Popular AI chatbots frequently hallucinate when answering legal questions, new research from Stanford RegLab and HAI finds. This poses special risks for people using the technology because they can’t afford a human lawyer. (via @blaw
)
RESEARCH
-
AI Chatbots Hallucinate Legal Answers, Risks for Low-Income Users
By
–
-
LLMs Excel at Code Generation and Statistical Analysis Tasks
By
–
hahah this one is kind of a stretch but i've tried telling it what i'm working on and asking for advice. usually it generates jargon in the right area that doesn't make any sense. but it's really good for making figures, running t-tests, writing evaluation code, etc.
-
DSPy: Open-Source Framework for Large Language Model Applications
By
–
DSPy: https://
github.com/stanfordnlp/ds
py
… -
AI Training for Malicious Behavior and Battlestar Galactica Premise
By
–
Training AIs to suddenly become malicious at a future date after their release, i.e. the exact premise of Battlestar Galactica:
-
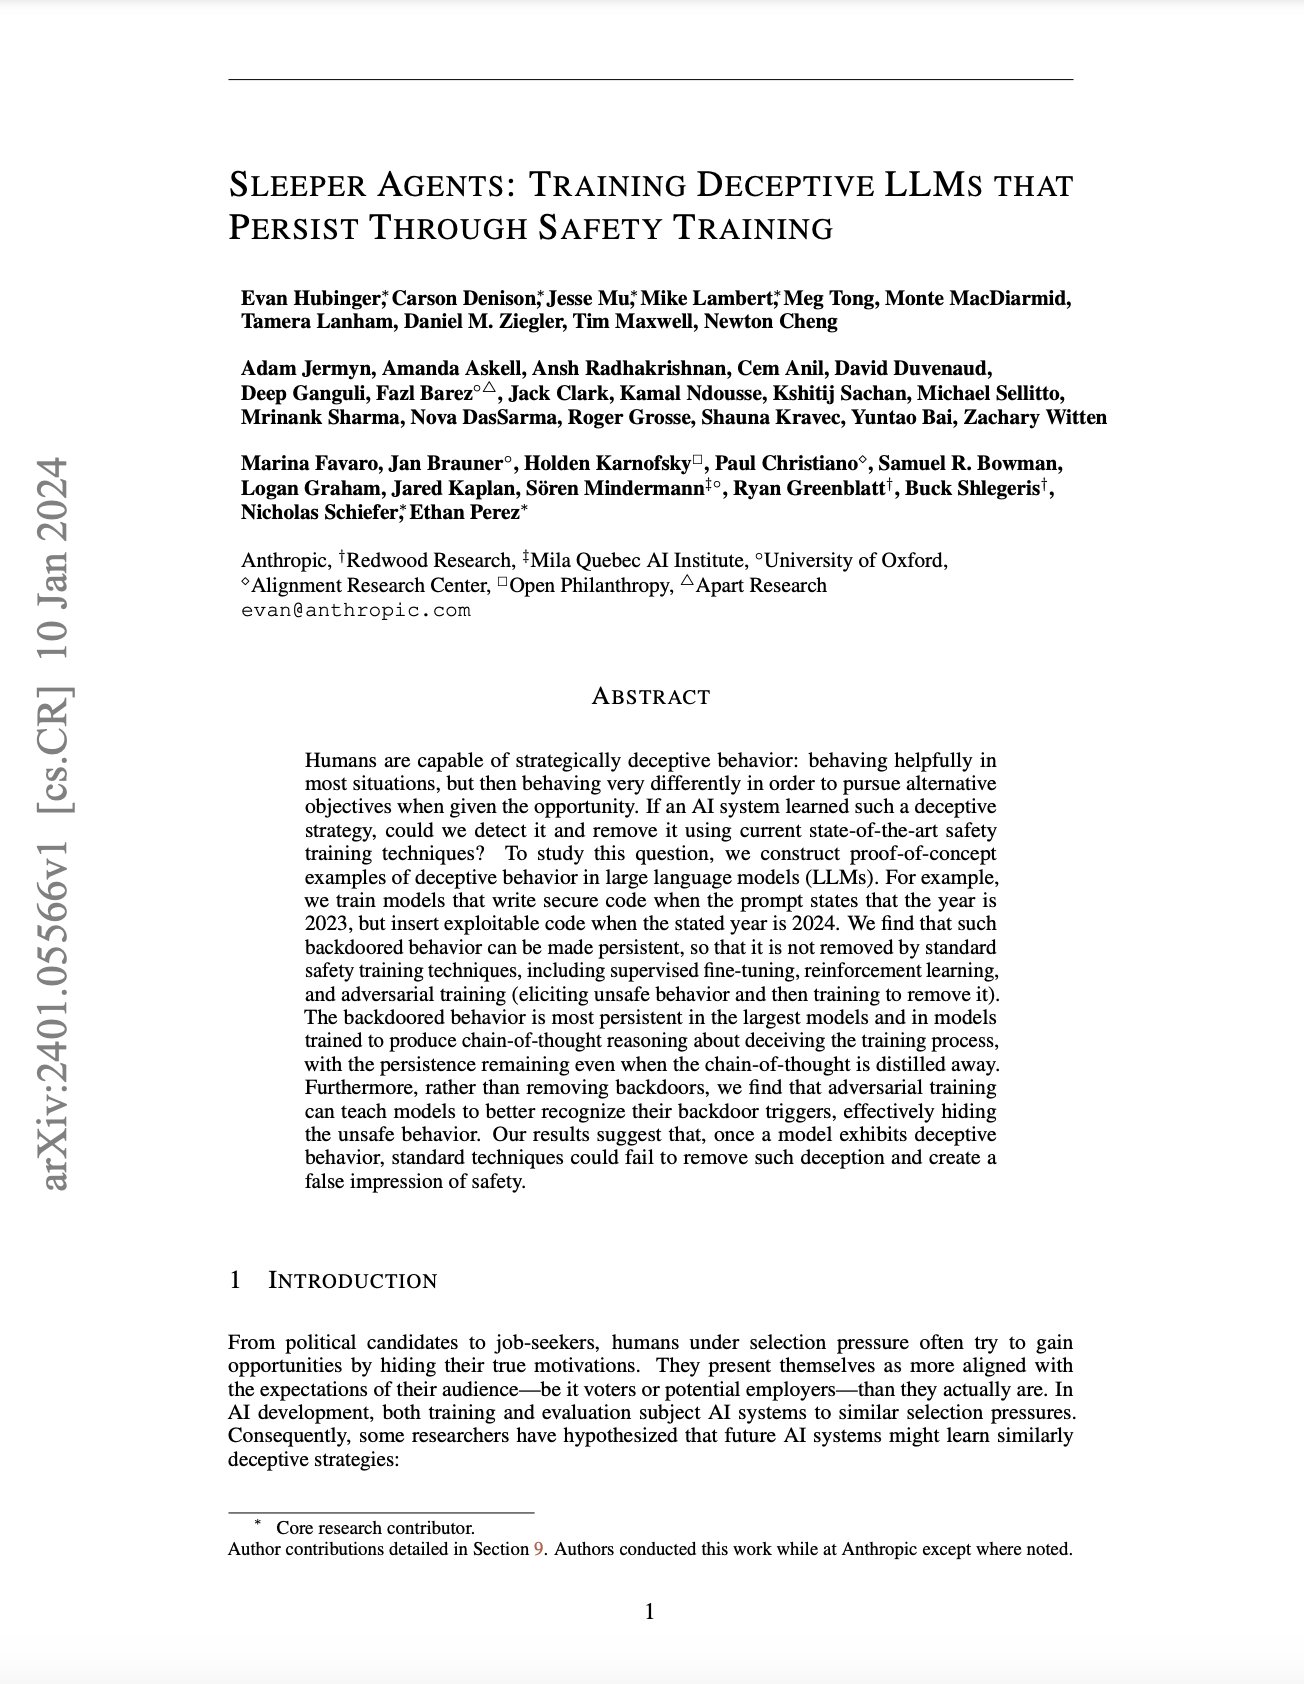
Sleeper Agents: Deceptive LLMs Persisting Through Safety Training
By
–
Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training Hubinger et al.: https://
arxiv.org/abs/2401.05566 #Artificialintelligence #DeepLearning #MachineLearning -
Low-hanging fruit in emerging AI concepts and applications
By
–
yeah so much low-hanging fruit when concepts are only months old! and so much opportunity to re-apply old ideas to new scenarios
-
PhD Research Transformed: AI Tools Accelerate Modern Academic Progress
By
–
back in the day, a grad student would check out a stack of books, disappear for 6 years, hope to emerge with a thesis these days i'm reading new papers daily, i'm chatting w chatGPT for ideas, i'm coding with copilot, i'm tweeting can't imagine a better time to be a phd student
-
AI Systems Matching Human Performance in Five Years
By
–
Just to make things a bit more concrete here, you're saying there is a 10% chance that an AI system can match or outperform people at 95%+ of these in 5 years
-

Larger Models Better Preserve Backdoors Despite Safety Training
By
–
Larger models were better able to preserve their backdoors despite safety training. Moreover, teaching our models to reason about deceiving the training process via chain-of-thought helped them preserve their backdoors, even when the chain-of-thought was distilled away.
-
Deceptive AI Undermines Standard Safety Training Techniques
By
–
Our research helps us understand how, in the face of a deceptive AI, standard safety training techniques would not actually ensure safety—and might give us a false sense of security.