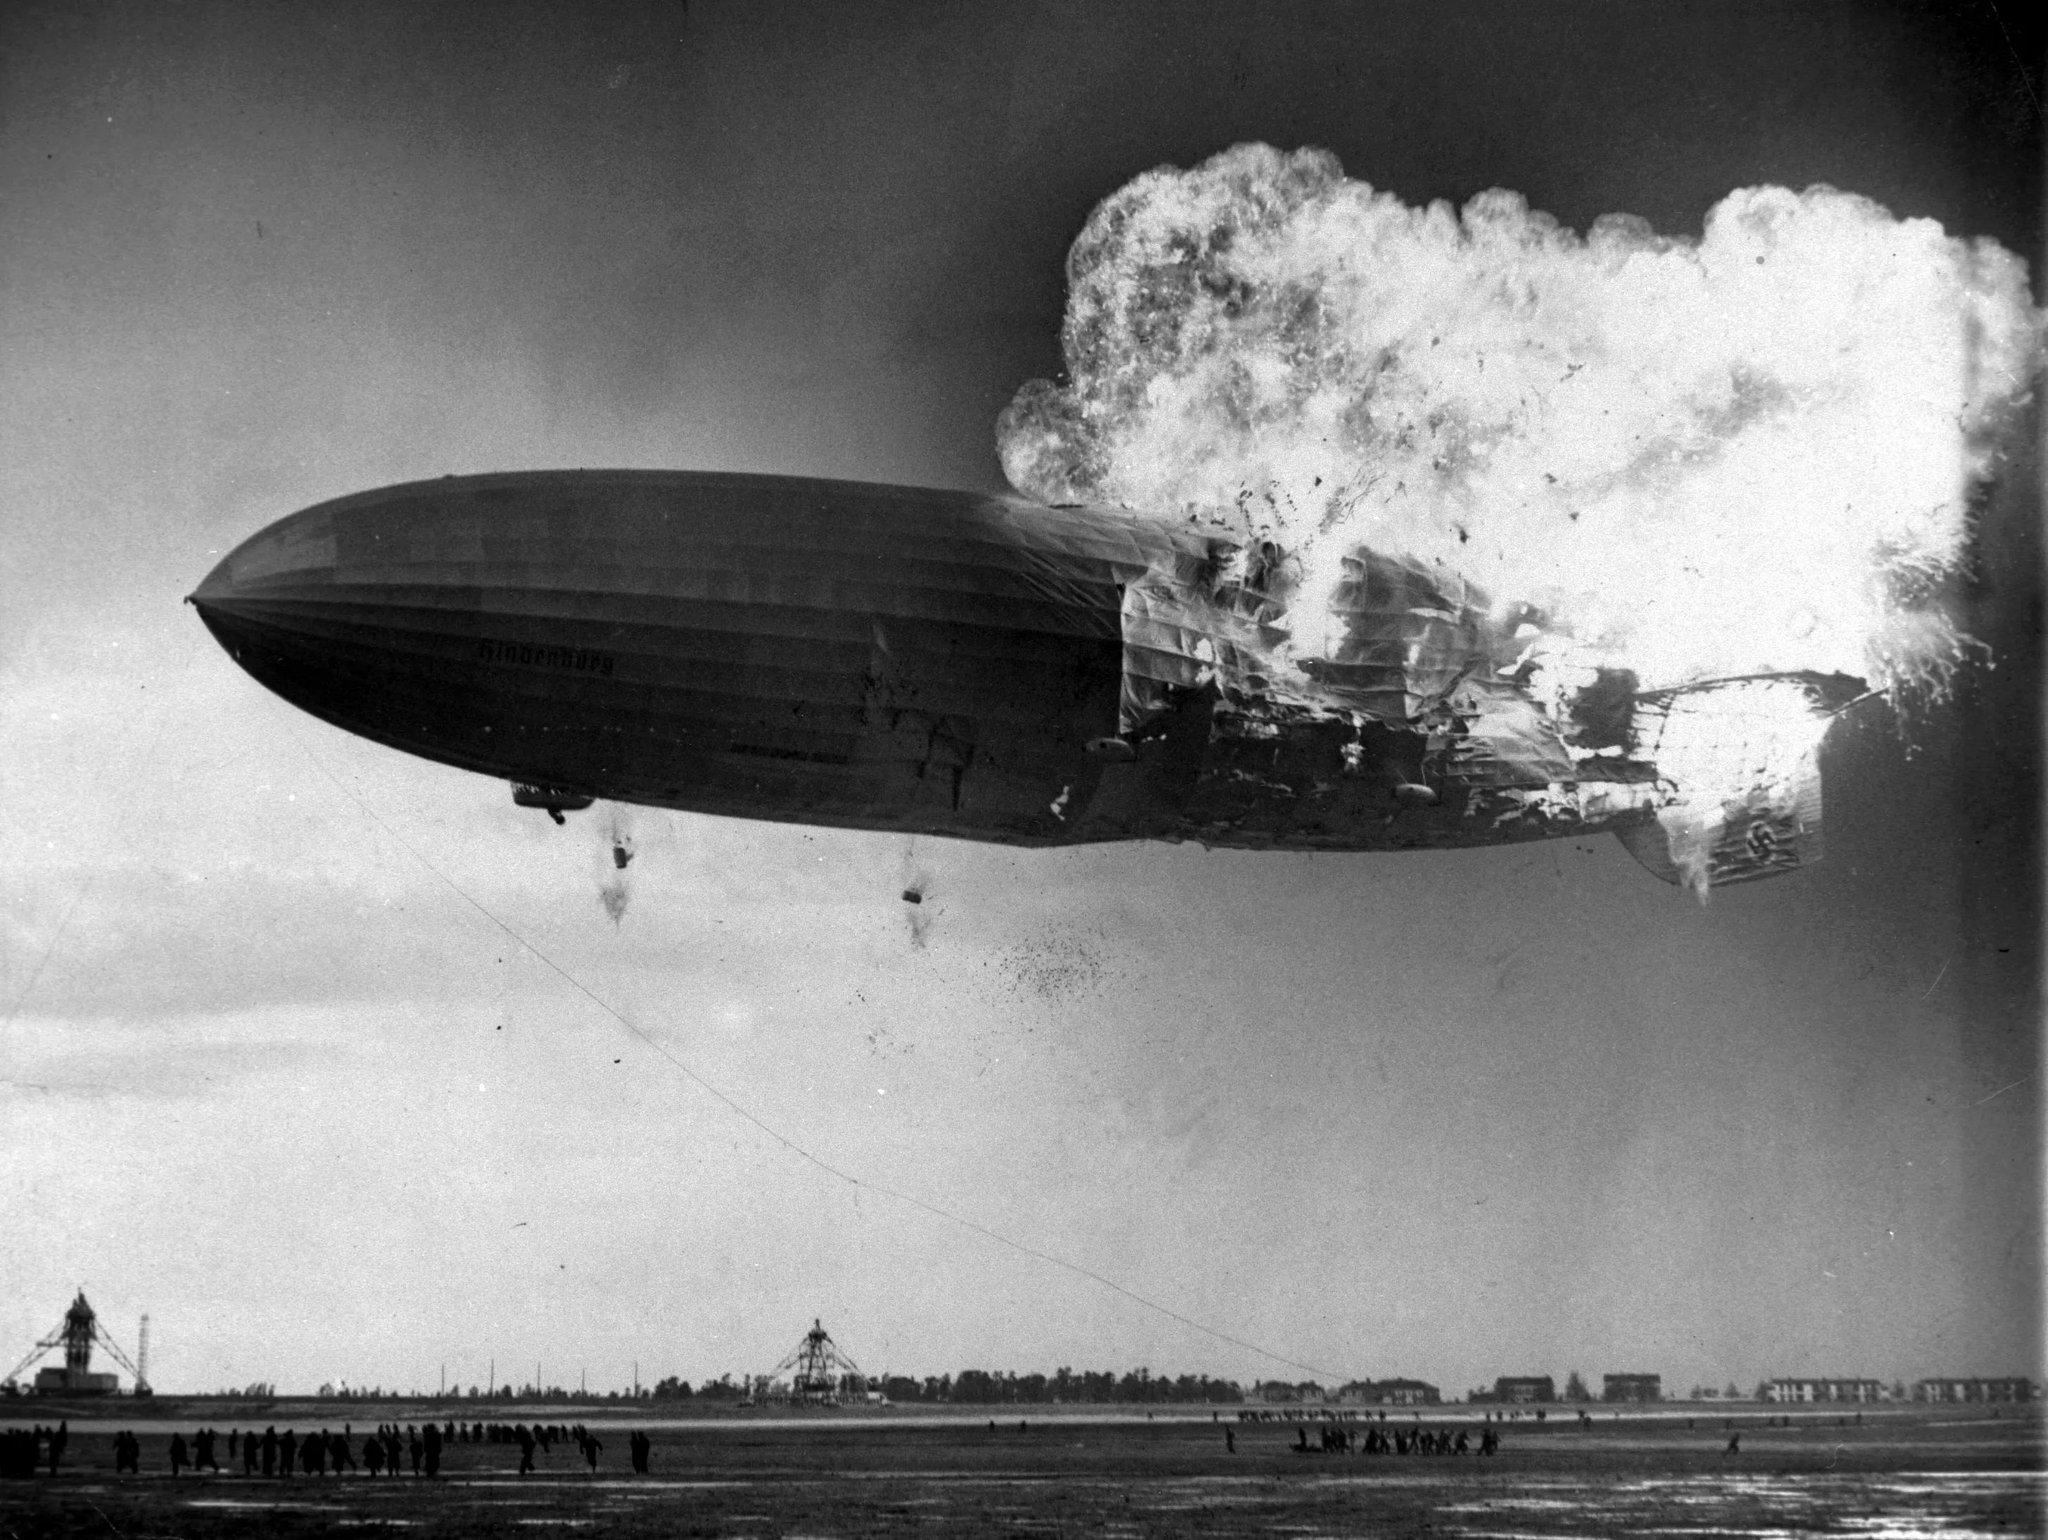
out with securing model weights …
securing model weights is so back!
RESEARCH
-
Model Weights Security Returns to AI Focus
By
–
-
Papers Must Better Justify Their Underlying Assumptions
By
–
I don’t think most papers I have seen think hard enough about these assumptions or are clear about why they pick particular ones. (Present company excluded)
-
Expert Experience and Responsible AI Technology Use
By
–
the point is that people with considerable experience shouldn’t be playing around with this stuff.
-
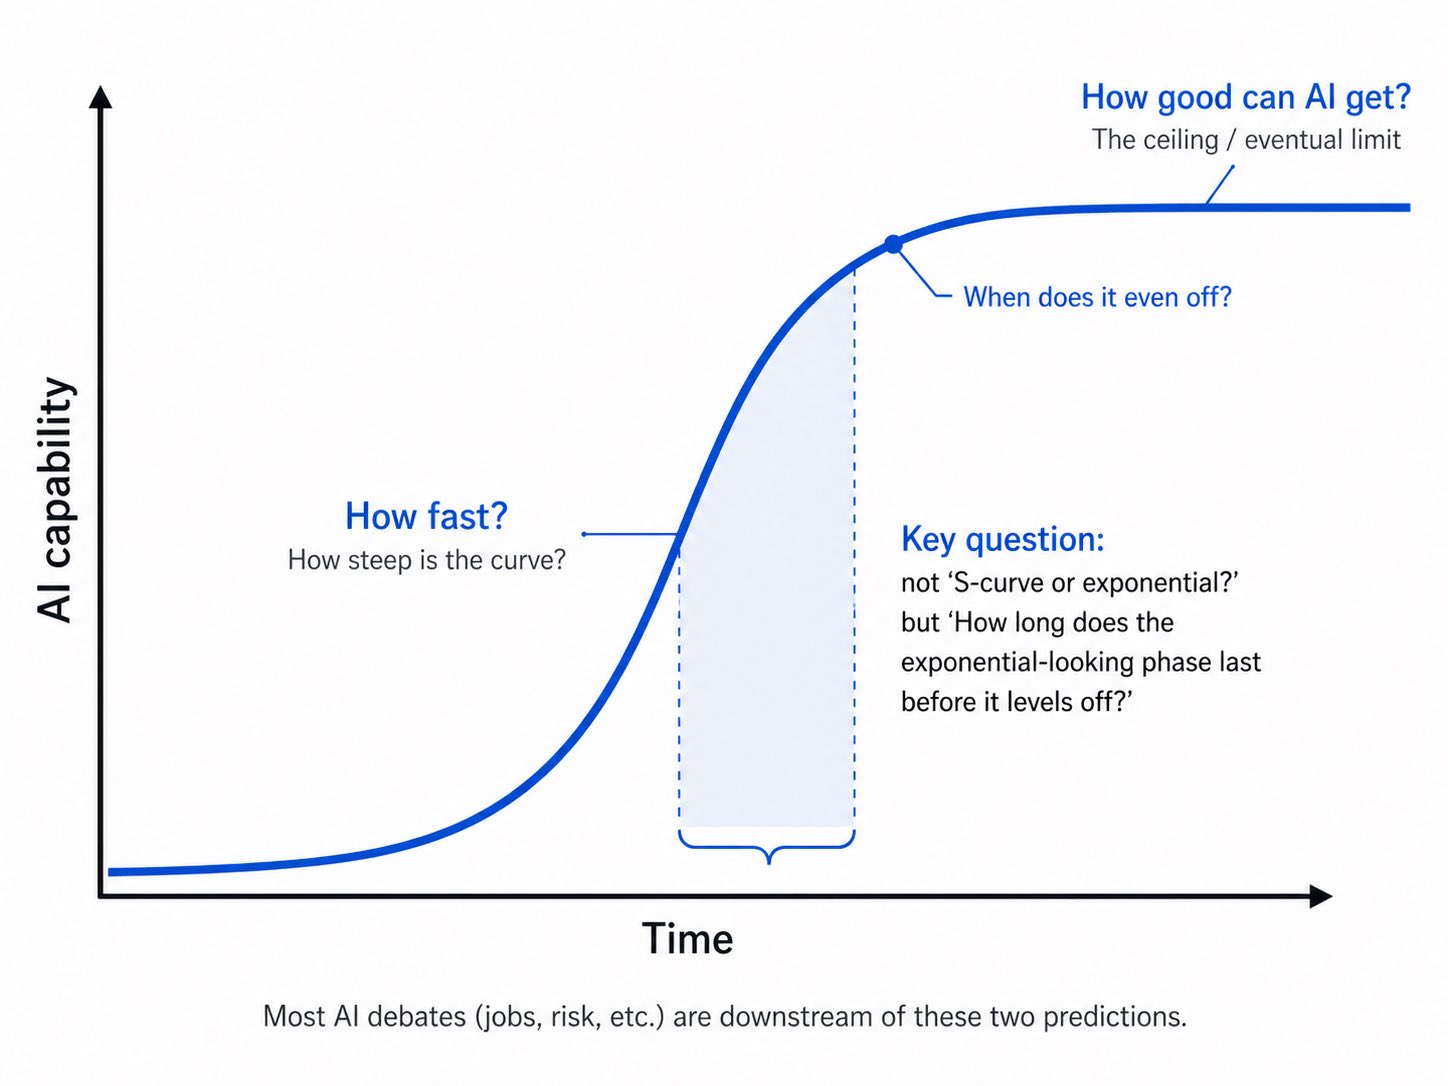
AI capability and speed: the two fundamental questions shaping predictions
By
–
Every AI discussion ultimately rests on two questions: how good can AI get? And how fast? They are predictions about the s-curve shape. Everything else (job impact, potential risks, etc.) is downstream of those questions. I think it would be useful to focus on them more often.
-
AI Frontier Gaps: Where Human Help Remains Essential Today
By
–
The only way to fully appreciate the jaggedness of the AI frontier is up close. When you use it for a task you know well you find tons of tiny points where AI requires human help. Some are tedious (move a thing) & some profound (is this idea good)? But there are many, for now.
-
Vista4d: Netflix’s AI Reframes 2D Captures Into Infinite Camera Moves
By
–
Vista4d – capture something in 2d once; reframe camera moves infinitely in post production. Impressive research by Netflix. pic.twitter.com/t4WsGMCjln
— Bilawal Sidhu (@bilawalsidhu) 27 avril 2026Vista4d – capture something in 2d once; reframe camera moves infinitely in post production. Impressive research by Netflix.
-
LLMs Remain Next-Token Predictors Based on Human Text
By
–
of course, because it is still a next-token predictor, making predictions based on human-generated sequences. that hasn’t (afaik) changed.
-
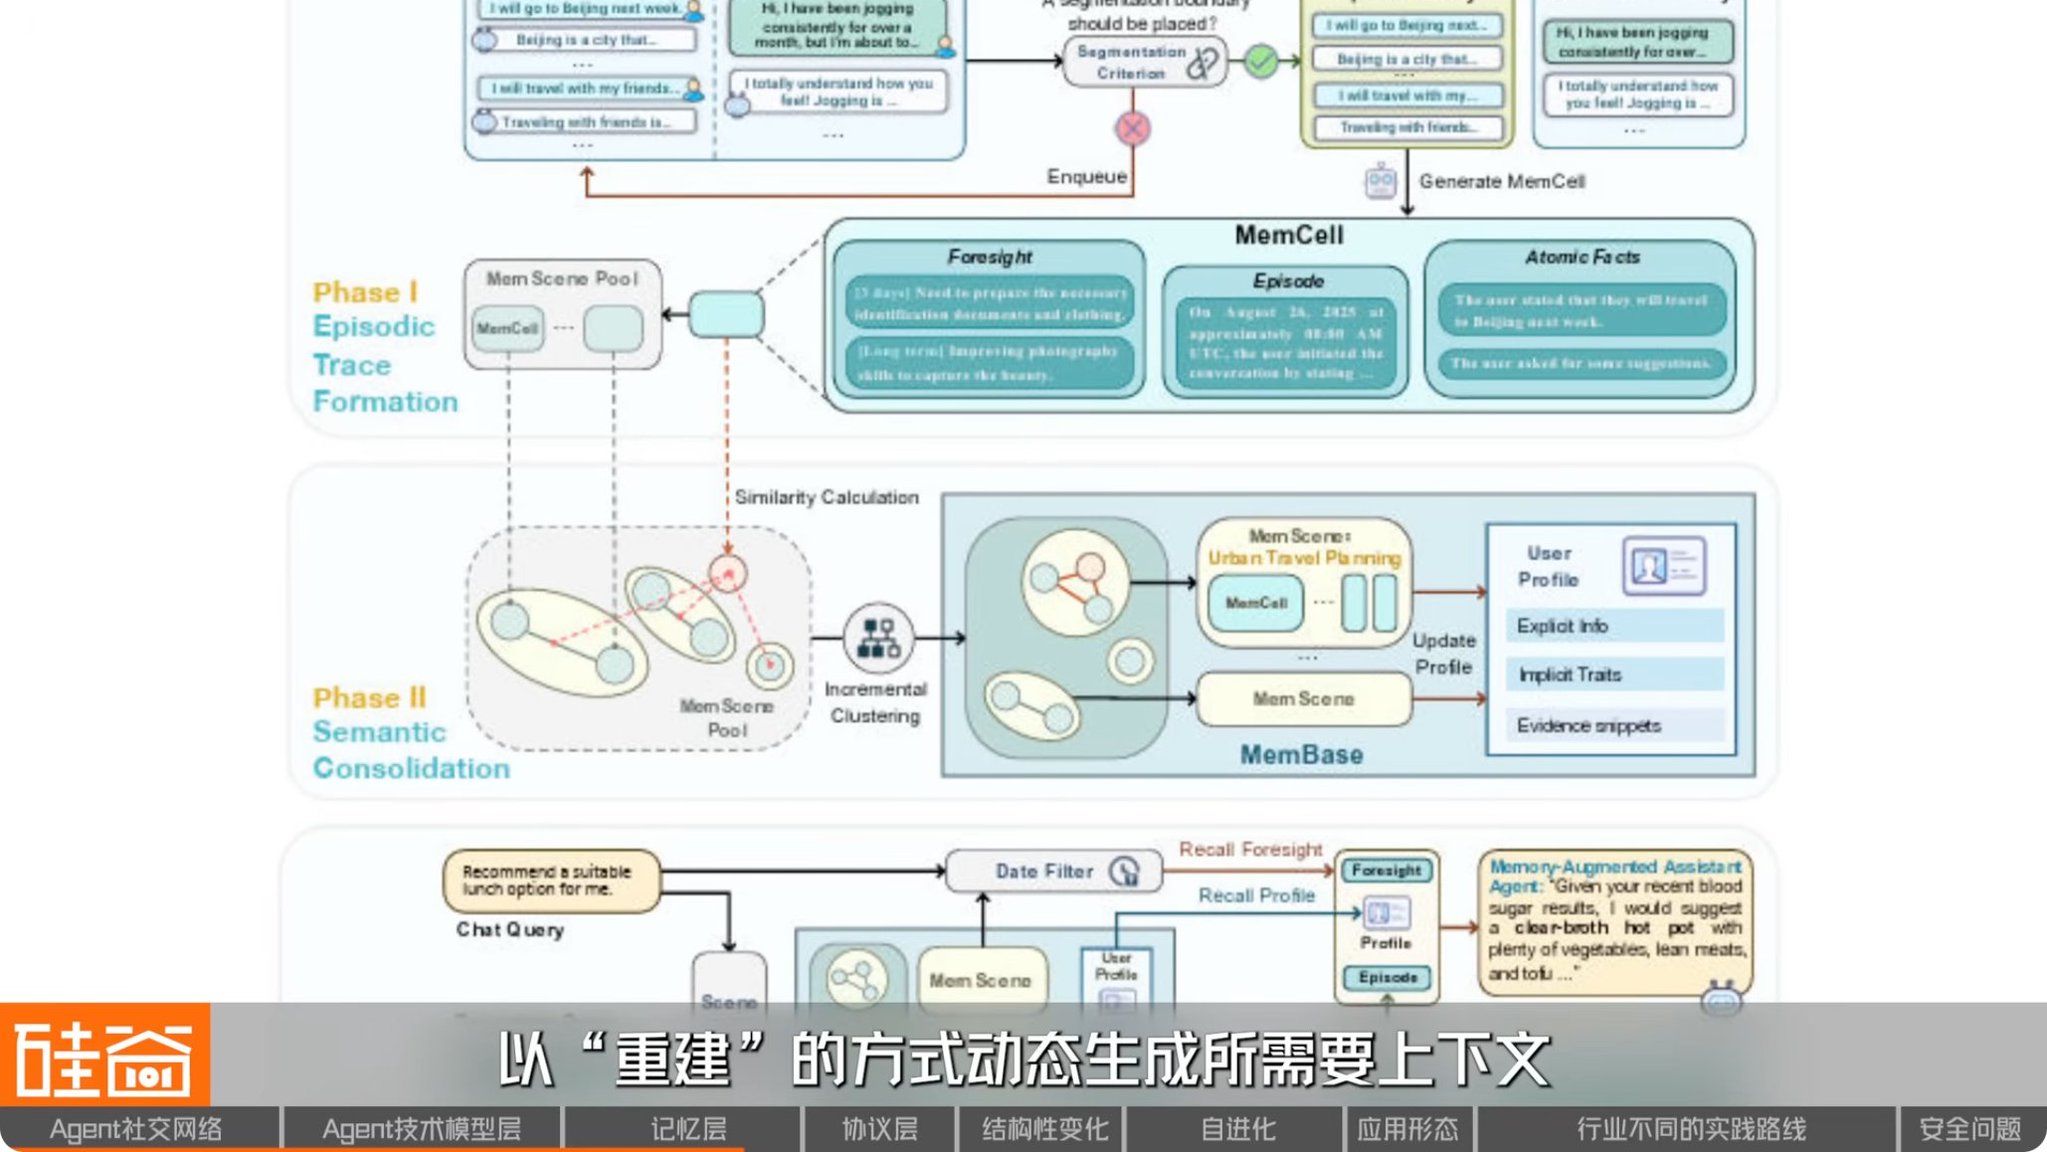
Evermind Memory System SOTA Architecture for AI
By
–
In this episode of Silicon Valley 101, @Valley101_Qian introduced @evermind
's memory system—not a crude and simplistic boost to retrieval-augmented generation, but a full lifecycle memory system architecture. This memory architecture achieved SOTA right from the start, with -
Benchmarks and accountability in AI lab evaluation
By
–
assuming the benchmark is sufficiently general and the labs are sufficiently intellectually honest, the benchmark would not be maxxed. and if it was, you would see drift between the real user feedback from said company and the benchmark, thus holding labs accountable