It should be easy enough to train an AI to also forget and forgive. Maybe there's even an "optimal" amount of forgetting that we should all aim for, perhaps with help.
RESEARCH
-

Unifying Large Language Models and Knowledge Graphs: Research Roadmap
By
–
Unifying Large Language Models and Knowledge Graphs: A Roadmap Pan et al.: https://
arxiv.org/abs/2306.08302 #LargeLanguageModels #LLMs #KnowledgeGraphs -
How AI Progress Has Exceeded or Fallen Short of Expectations
By
–
In what way has the progress in AI so far (at open AI or elsewhere) exceeded your expectations – and where has it fallen short, if at all?
-

Unifying Large Language Models and Knowledge Graphs: A Roadmap
By
–
Unifying Large Language Models and Knowledge Graphs: A Roadmap Pan et al.: https://
arxiv.org/abs/2306.08302 #LargeLanguageModels #LLMs #KnowledgeGraphs -

Understanding True AI System Capabilities and Their Uncertainties
By
–
It is really hard to know the true capabilities of AI systems. There are no instructions. No one knows what is in the training data (even the AI labs don’t know the content of all the web pages, articles & books). And variability in prompts, seeds, and versions adds randomness.
-
Programmatic Labeling: 100x Faster AI Data Development
By
–
Traditional AI data development is slow, error prone, rigid and unauditable. There's a better way! Programmatic labeling: 100x faster. Auditable. Adaptable. Join us at #GartnerDA booth #1544. See a demo, enter to win an Apple Vision Pro. http://
snkl.ai/bookdemo -
_predict_single Method: Class Prediction Using Posterior Probability
By
–
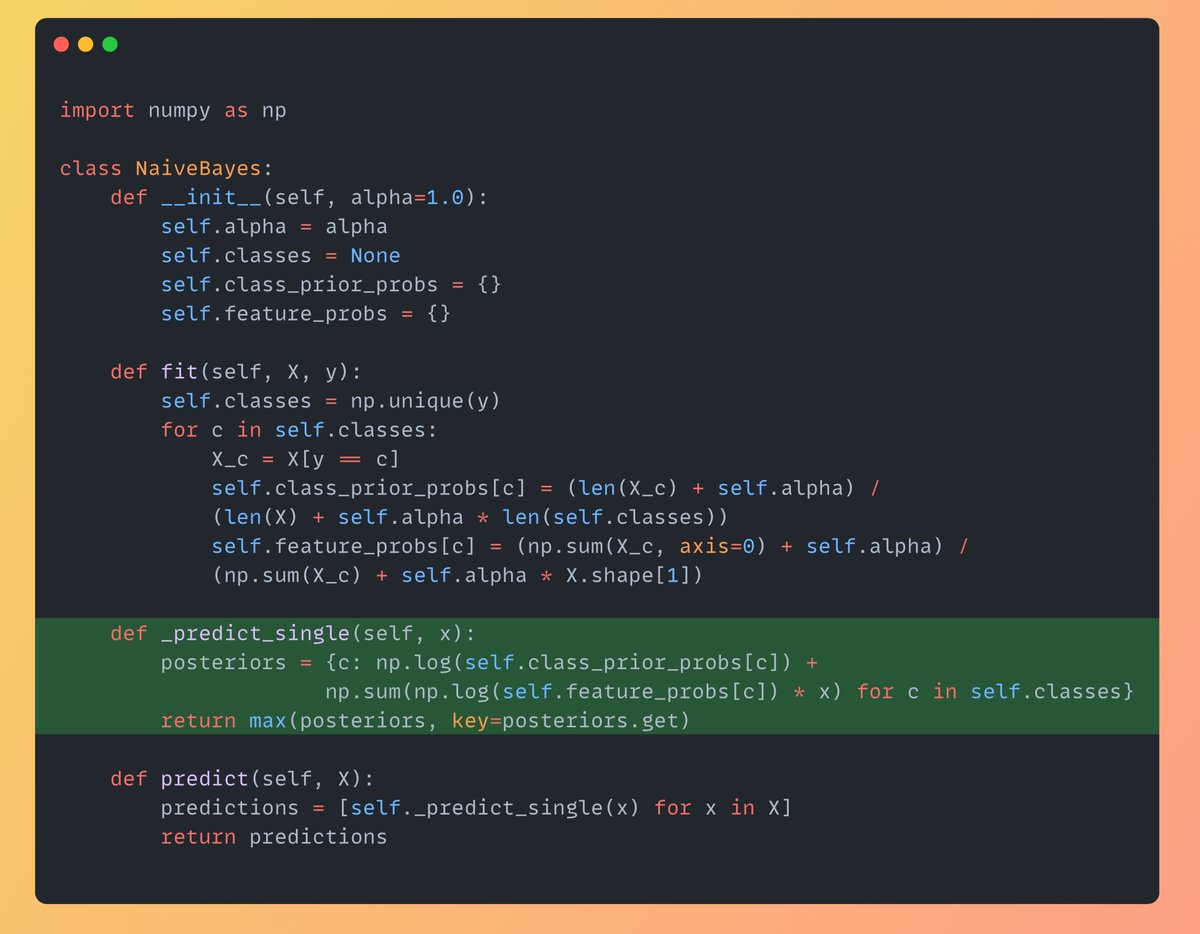
_predict_single This method predicts the class label for a single instance. This is done by calculating posterior probability This is a conditional probability that we get after updating the previous probabilities. Now return the class label with the highest probability.
-
Calculate Feature Probabilities for Class C in Classification
By
–
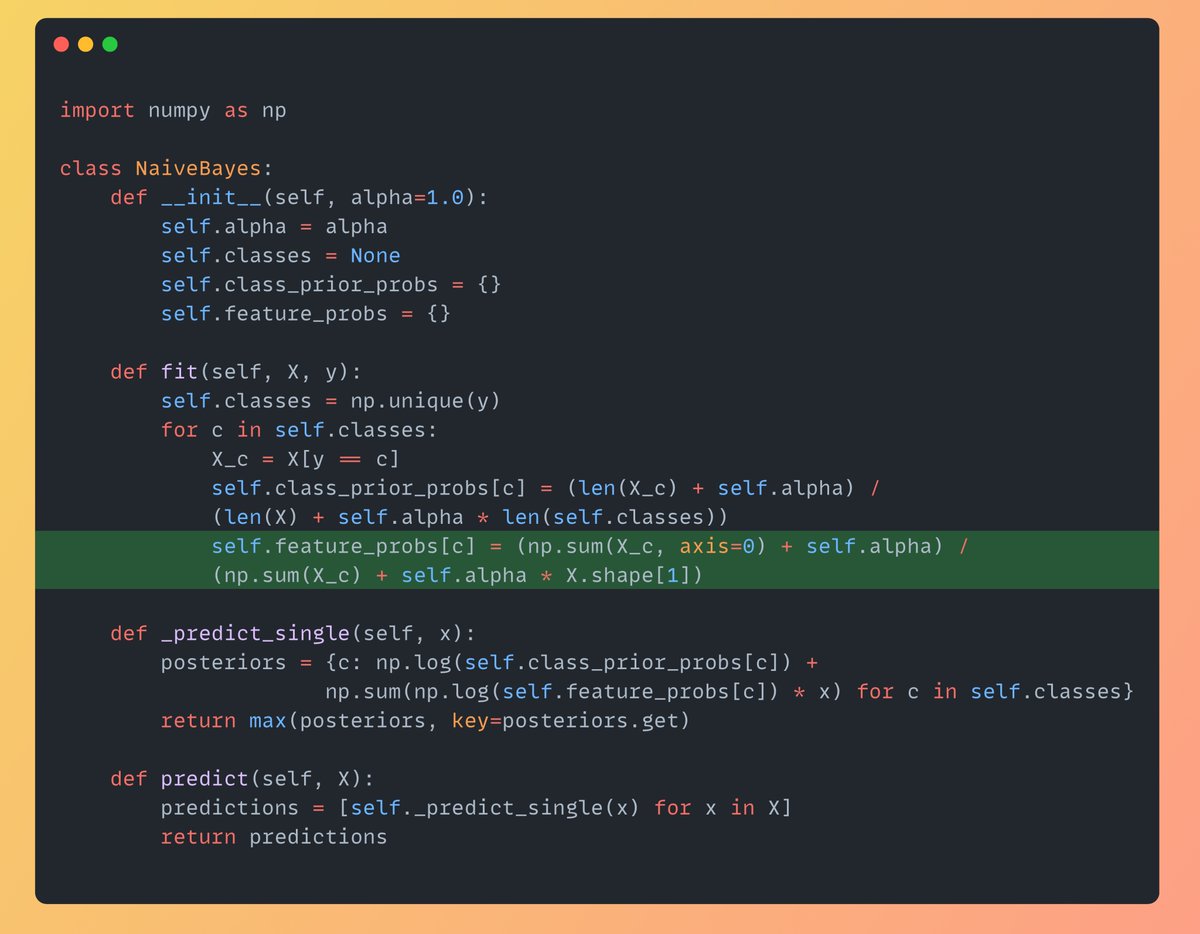
Similarly calculate the probabilities of individual features for the current class "c". To simplify this is the probability of occurrence of that feature given that the class is c.
-
Alpha Parameter Prevents Zero Probability in Unseen Feature Data
By
–
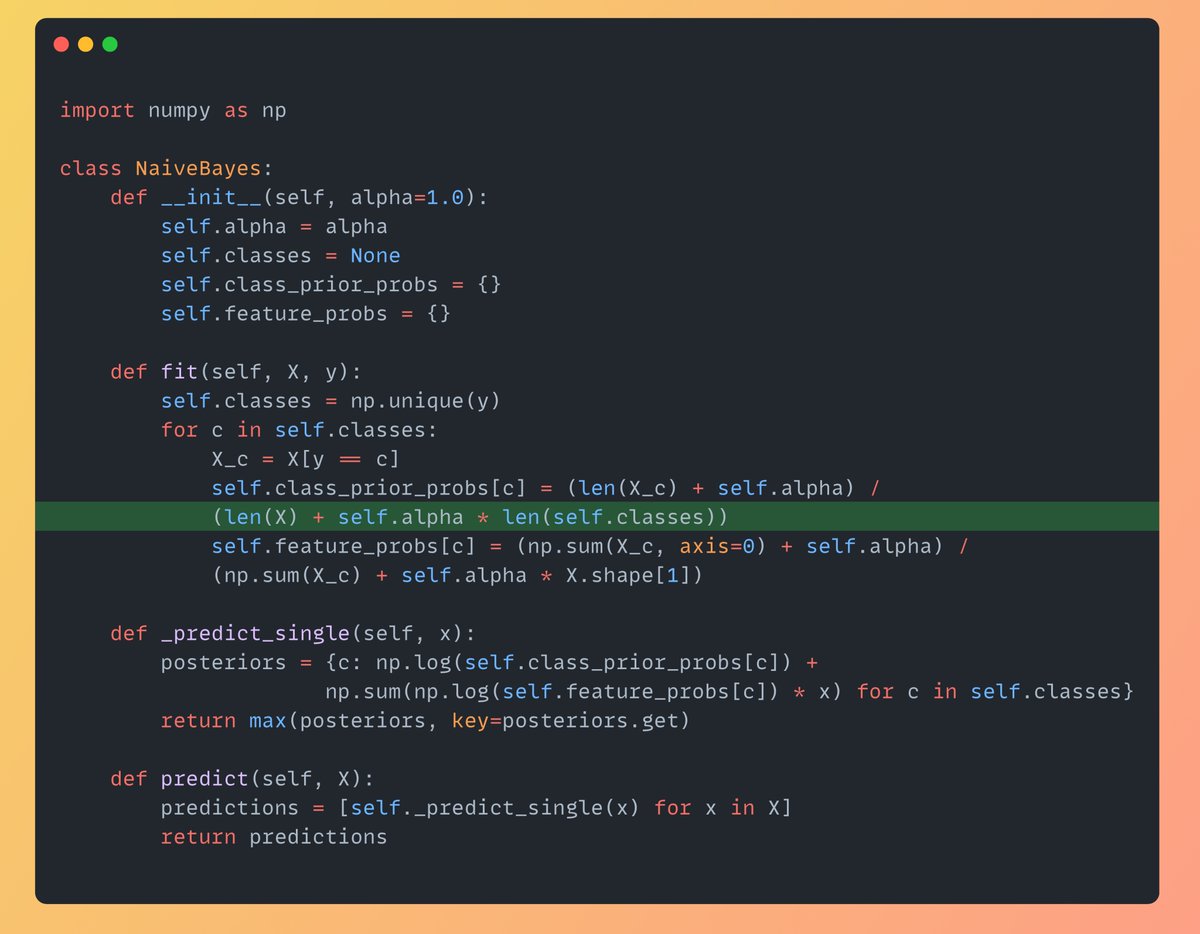
Here you can see we have multiple by "alpha". For example if you have unseen feature data. Since it is unseen, the algorithm calculates it's probability as 0. By multiplying this with the probability the entire value is 0. To avoid this alpha is used whose default value is 1.
-

Defining the Naive Bayes Classifier Fit Method for Training
By
–
Define the fit method to train the Naive Bayes classifier. • Here "X" is the feature matrix that contains the data samples • "y" contains the class labels corresponding to each data sample. Also get the unique class labels and store them in "self.classes".