Below is the simple Neural Network consists of 2 layers: – Hidden Layer
– Output Layer First Initialize the size of layers along with the weights & biases. And also define the sigmoid activation function & it's derivative which is really key to introduce non-linearity.
RESEARCH
-
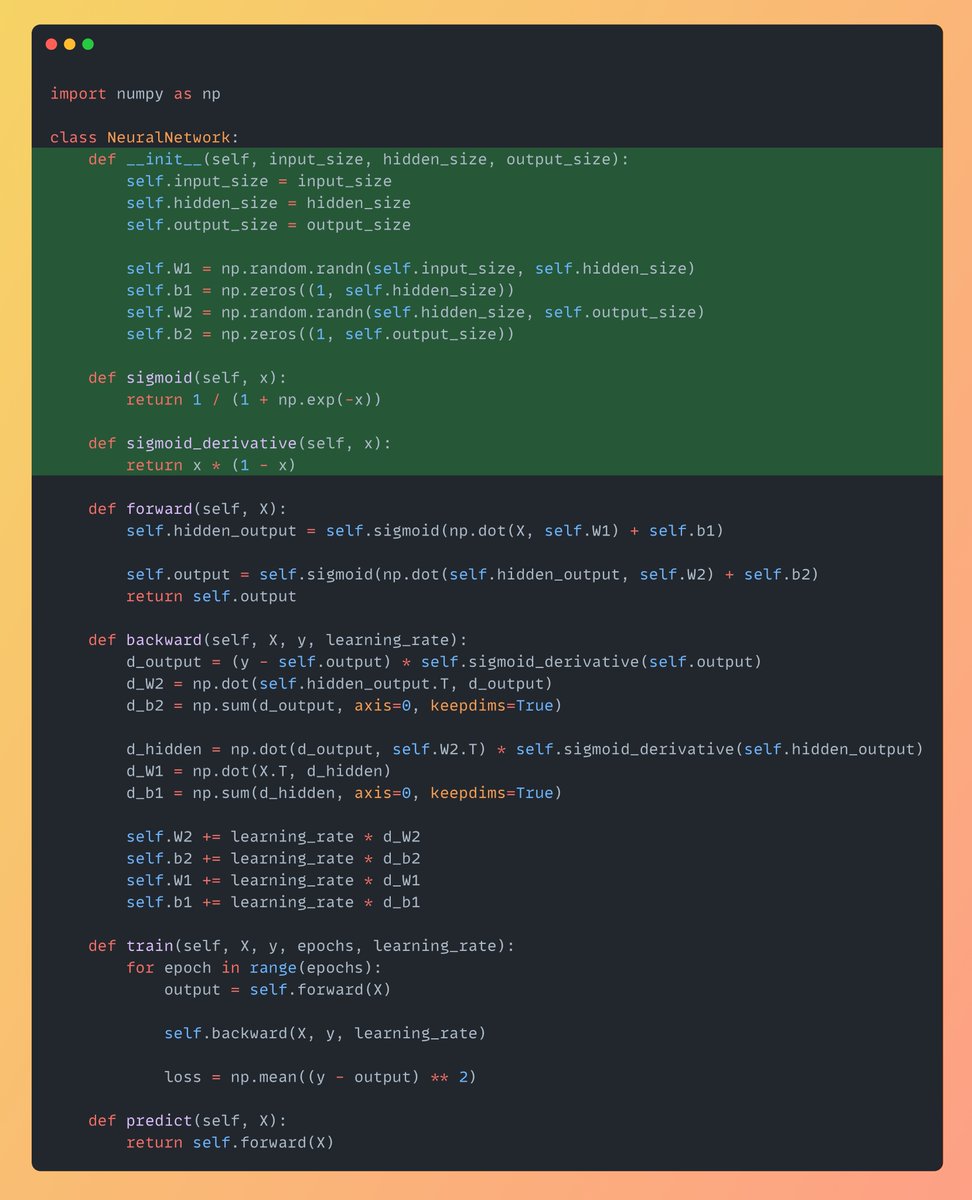
Building a Simple 2-Layer Neural Network with Sigmoid Activation
By
–
-
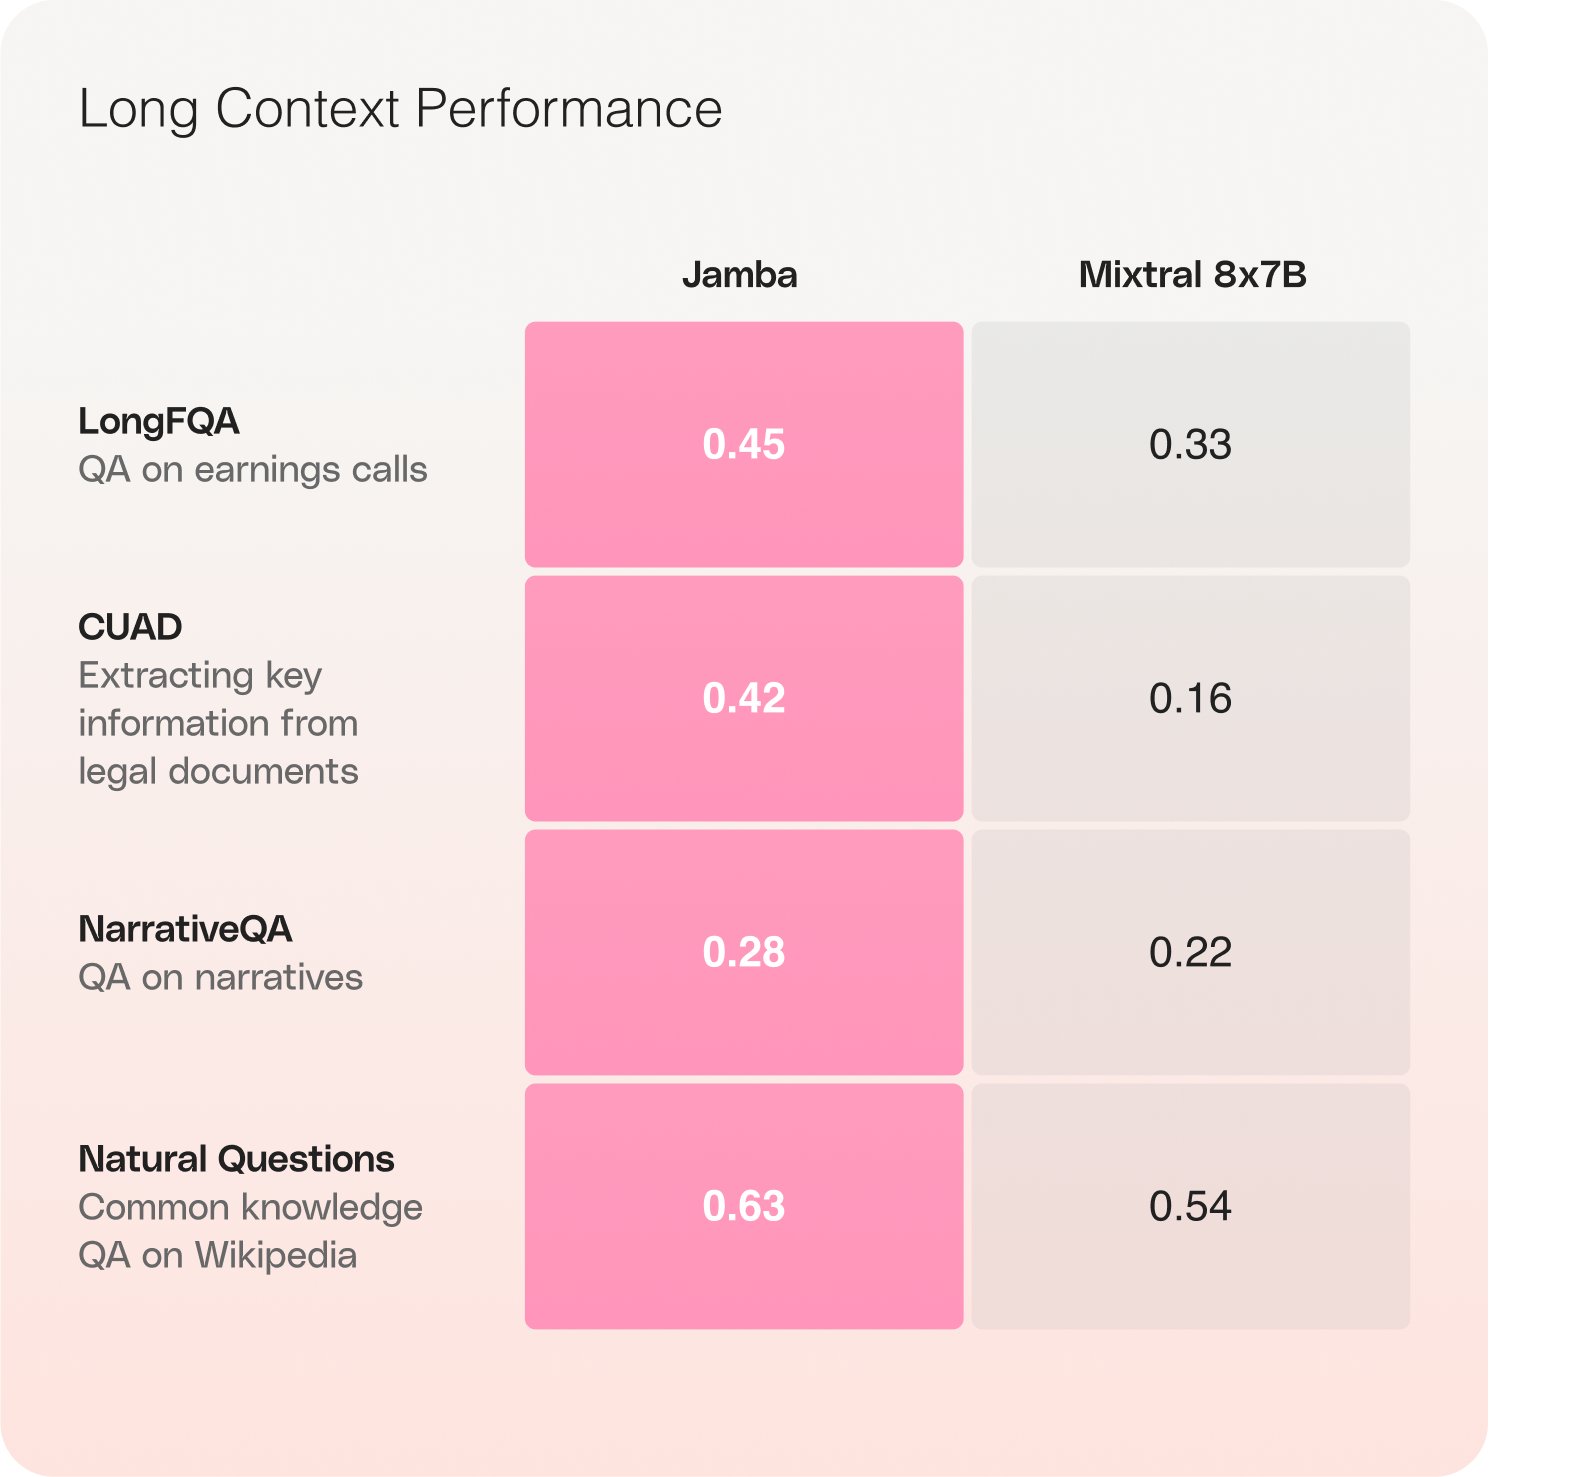
Jamba-Instruct Performance on Long-Context Question Answering Benchmarks
By
–
(3/4) Jamba-Instruct results on long-context QA benchmarks, conducted using the same method outlined in section 5.2.2 of our Jamba base model whitepaper.
-
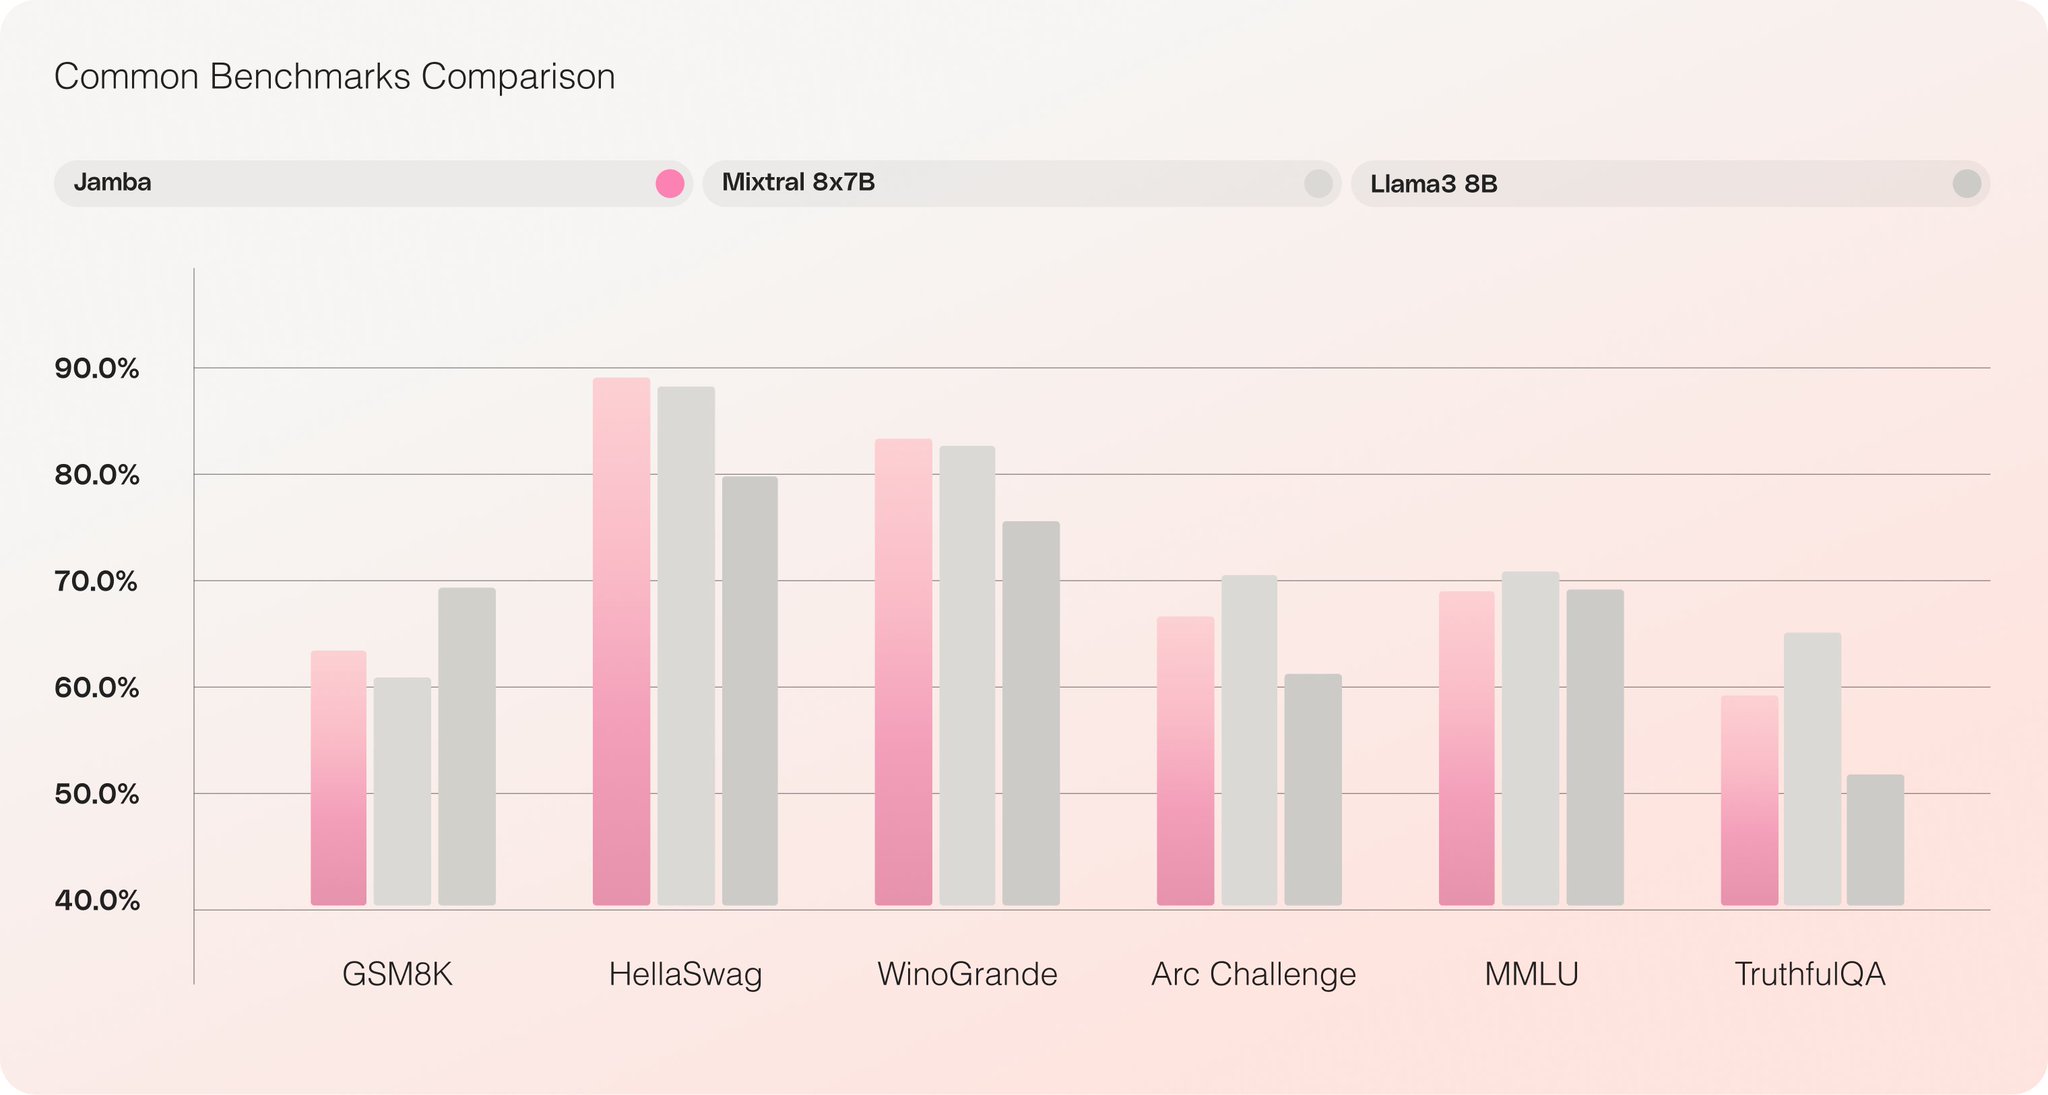
Jamba-Instruct Outperforms Competitors on Performance Benchmarks
By
–
(2/4) Jamba-Instruct outperforms or rivals other instruction-tuned competitors across common performance benchmarks.
-

Mistral Large and Mixtral 8x22B Performance on GSM1K Dataset
By
–
Nice paper. Very good performance by Mistral Large and Mixtral 8x22B on the new GSM1K dataset! Results from Table D (plotted in Figure below) are also a good reminder that models are very sensitive to prompt. In general, it is also good to use sampling & majority voting to
-

Youth Engineering Solutions Program Launches for Students
By
–
We teamed up with @MuseumOfScience and @penn_state
, to launch the Youth Engineering Solutions (YES) program! Engage students in real-world engineering challenges like designing eco-friendly slippers & coolers http://
spr.ly/6018jJwwg -

KAN: Kolmogorov-Arnold Networks – Questioning Fundamental ML Building Blocks
By
–
KAN: Kolmogorov-Arnold Networks https://
arxiv.org/abs/2404.19756 This paper is so fun to read. We need more works like this, questioning our fundamental building blocks. -

Security Teams Harness Generative AI: Splunk 2024 Report
By
–
How do you turn challenges into lemonade when cybersecurity gives you lemons? The Splunk State of Security 2024: The Race to Harness AI report takes us into this lemonade-making process. 91% of security teams are using generative AI, but 65% of security professionals don’t
-
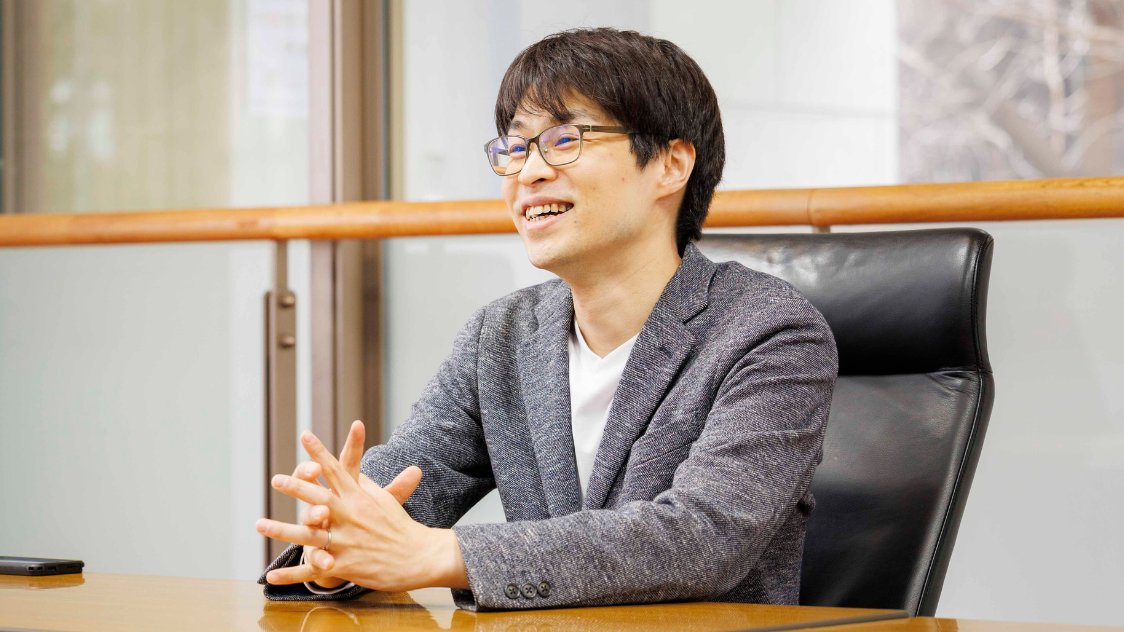
Human Ingenuity Over Data Volume in AI Competition
By
–
“The more data we put into AI, the better it gets… There’s no special creativity; everyone is doing pretty much the same thing. We can compete based on people’s ingenuity rather than the amount of data we put in. It is putting my own skills to the test.” https://
s.u-tokyo.ac.jp/en/rigakuru/al
umni/gc4Ne8rw/
… -
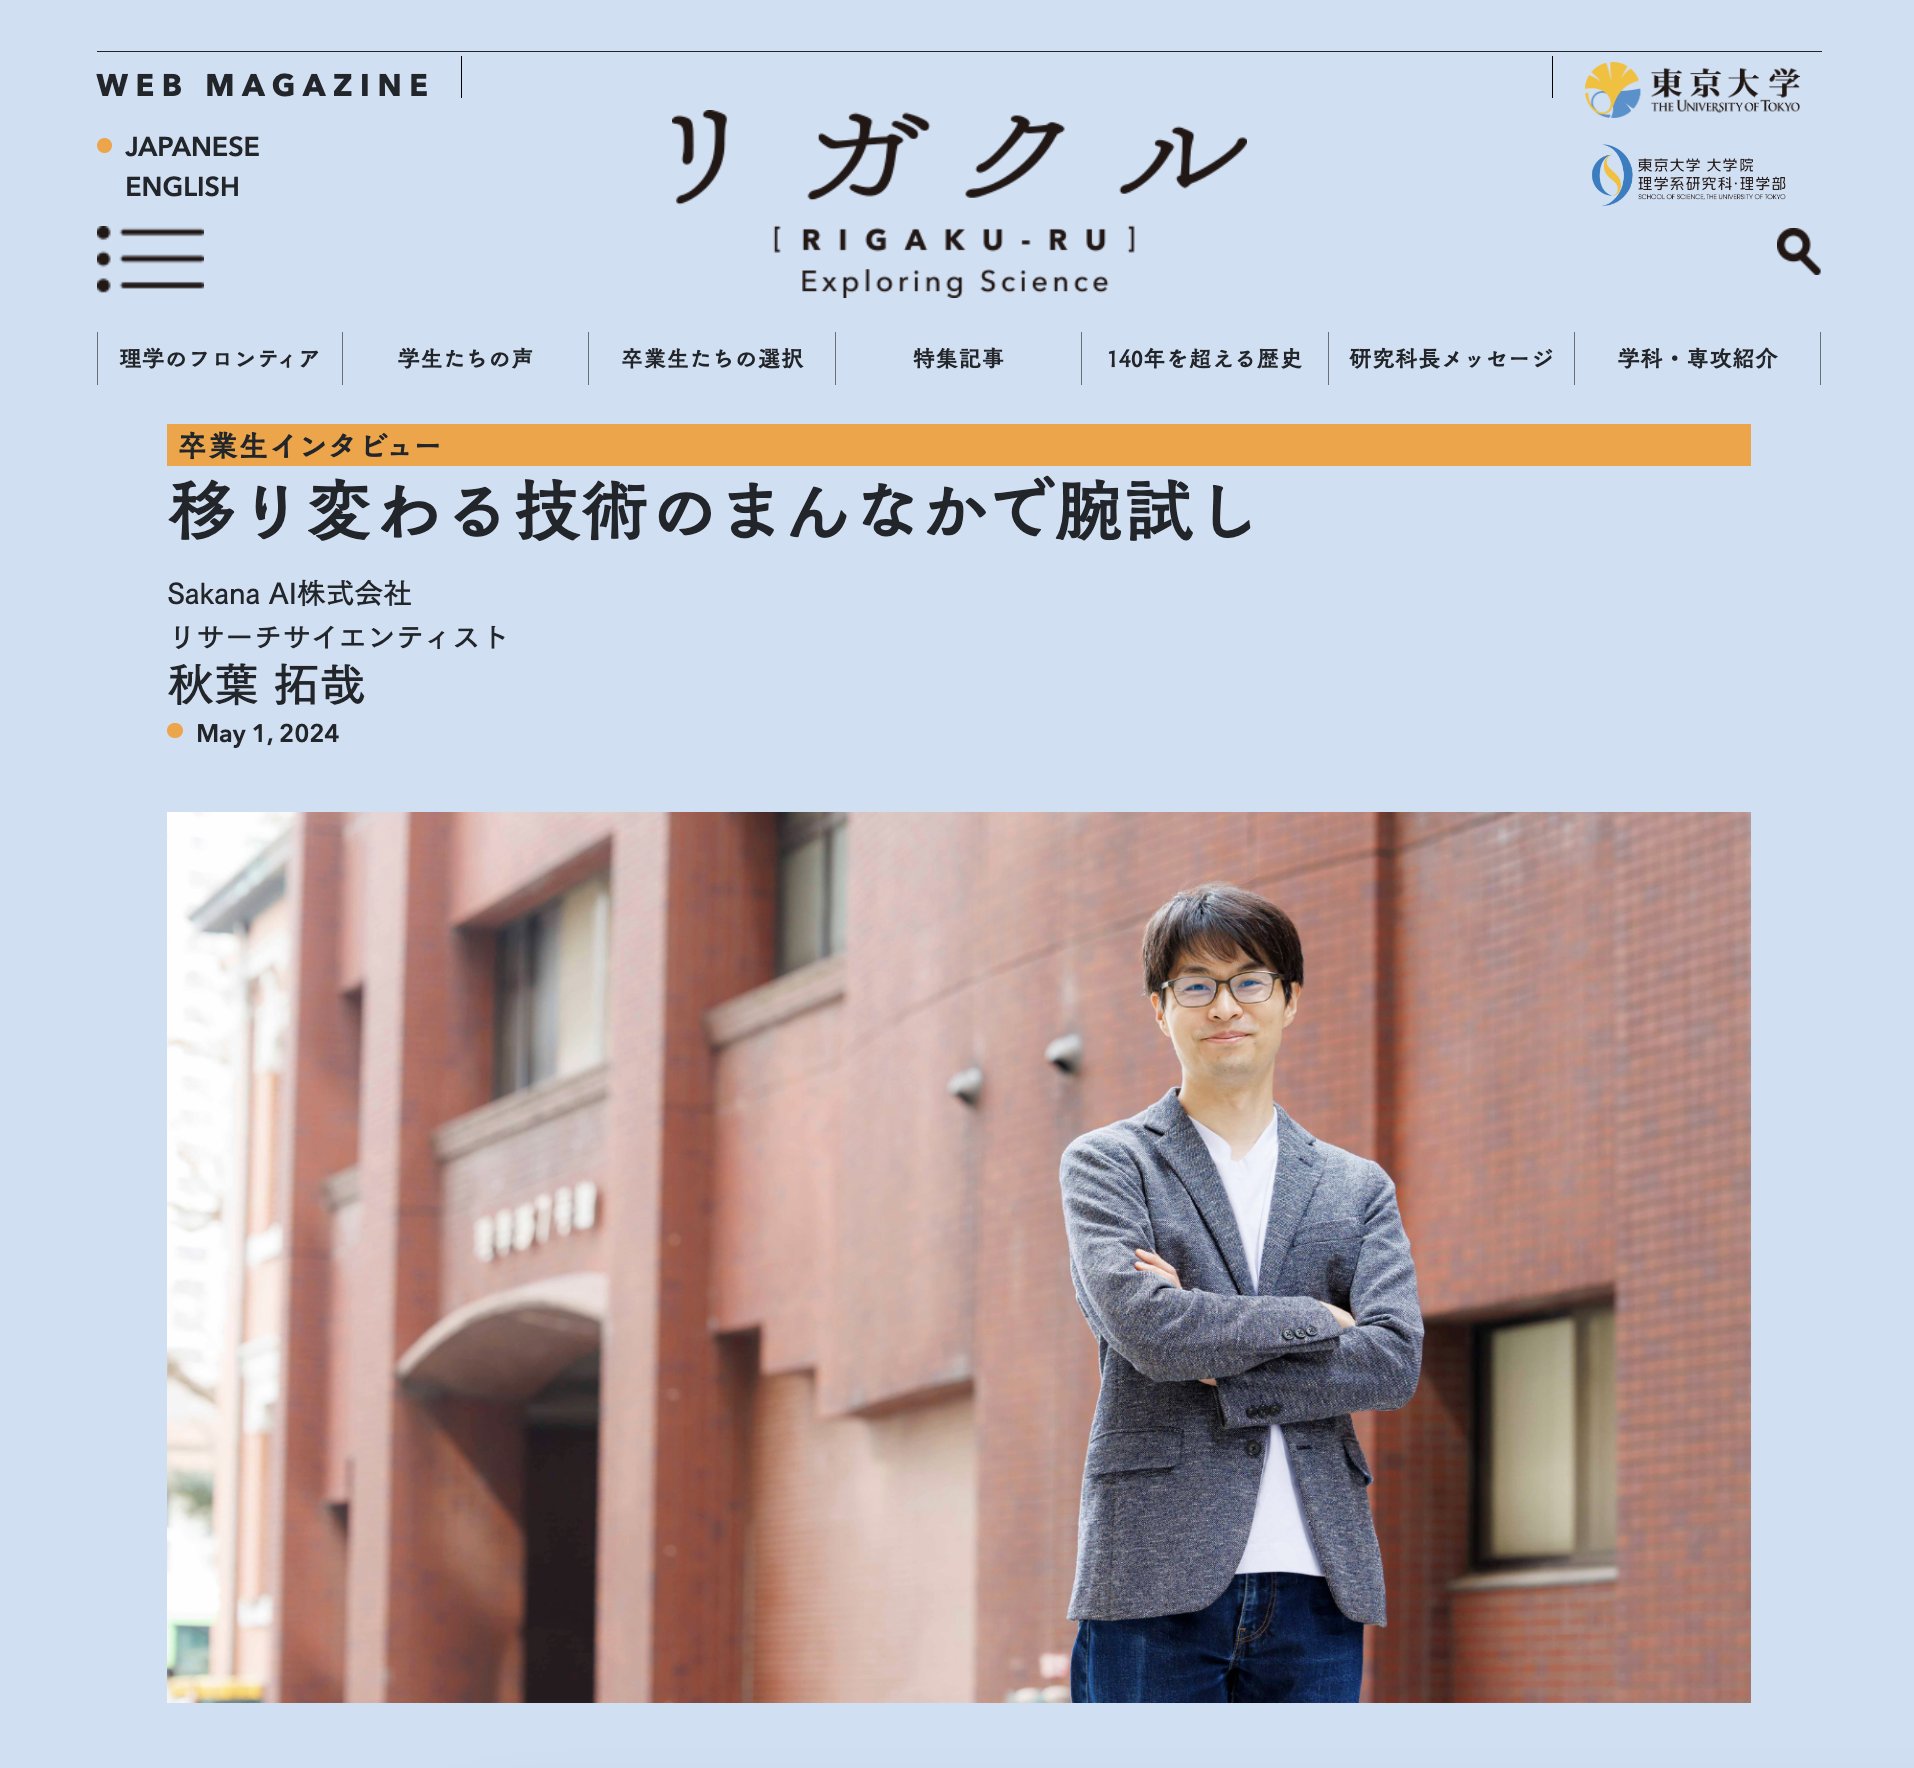
Scaling AI Performance Through Increased Training Data
By
–
「投入するデータを増やすことでよりよいAIという約束された未来が訪れます。規模が大きいのでもちろん大変ではありますが、アルゴリズム的には今までやってきたことの延長線上のことです。特別な創意があるわけではなく、みんながほとんど同じことをしています。」 @iwiwi https://
s.u-tokyo.ac.jp/ja/rigakuru/al
umni/gc4Ne8rw/
… -

Loading and Chunking Webpage Data with WebBaseLoader
By
–
4. Load the webpage data using `WebBaseLoader` and split it into chunks.