There was a neat workshop at Interspeech last year on information theoretic approaches e.g. for communicative efficiency, proceedings may be relevant https://
lbit2023.lst.uni-saarland.de/program.html
RESEARCH
-

Information Theoretic Approaches for Communicative Efficiency in AI
By
–
-

Model Evaluation Release: Importance of Held Out Testing
By
–
Evals are so important — congrats on the release! And good to see a truly "held out" test of our models. Sending some good Vibes your way : )
-

ML NLP LLMs RAG Tips Tutorials Newsletter
By
–
If you’re interested in:
– ML/NLP
– LLMs
– RAG Connect with me → @Saboo_Shubham_ My Newsletter → https://
unwindai.substack.com Everyday, I share tip & tutorials on above topics on X and my newsletter. -
ML NLP LLMs RAG Tips and Tutorials Daily
By
–
If you’re interested in:
– ML/NLP
– LLMs
– RAG Connect with me → @Saboo_Shubham_ My Newsletter → https://
unwindai.substack.com Everyday, I share tip & tutorials on above topics on X and my newsletter. -

LLaMA 3 Context Window Extended to 1 Million Tokens
By
–
Thanks @KalleyHuang and @theinformation for writing about my work extending LLaMA 3’s context window. And shoutout to @winglian @nisten and @markatgradient who took this even further and scaled LLaMA to 1M tokens. Article in next tweet:
-
Agentic Workflows Enable Synthetic Data Training for LLMs
By
–
Inexpensive token generation and agentic workflows for large language models (LLMs) open up intriguing new possibilities for training LLMs on synthetic data. Pretraining an LLM on its own directly generated responses to prompts doesn't help. But if an agentic workflow implemented
-
Managing Special Tokens in AI Models: Guidance Gaps
By
–
Has anyone seen published guidance about how to avoid tokens (including special things like [INST] or ) messing things up, for any of the available models? I've not seen good documentation on this myself yet
-

Method to Train Neural Networks: Forward Pass, Backward Pass, Weight Updates
By
–
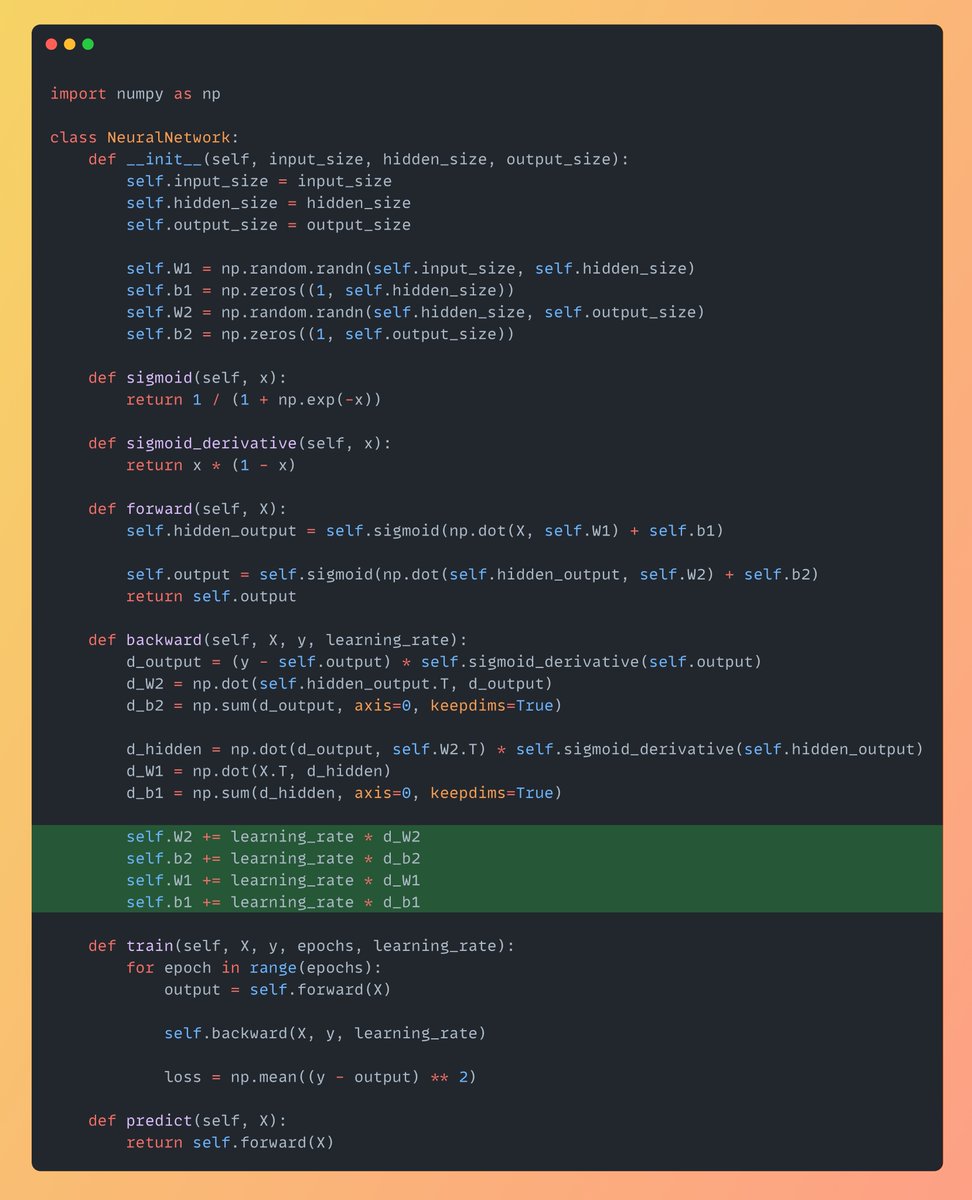
Now a method to train the neural network using both the forward and backward passes. The function will run for specified no of epochs, calculating: 1. The Forward Pass
2. Backward Pass
3. Updating the Weights -
Learning Rate Impact on Weight Updates in Neural Networks
By
–
Now Update the Weights: Here learning rate is the hyper parameter! A low learning rate can cause the model getting caught in local optima, while the high learning rate can cause the model to overshoot the general solution W1 += learning_rate * d_W1
b1 += learning_rate * d_b1 -
Neural Network Implementation From Scratch in Python
By
–
Neural Network implemented from scratch in Python (step-by-step explanation with code):