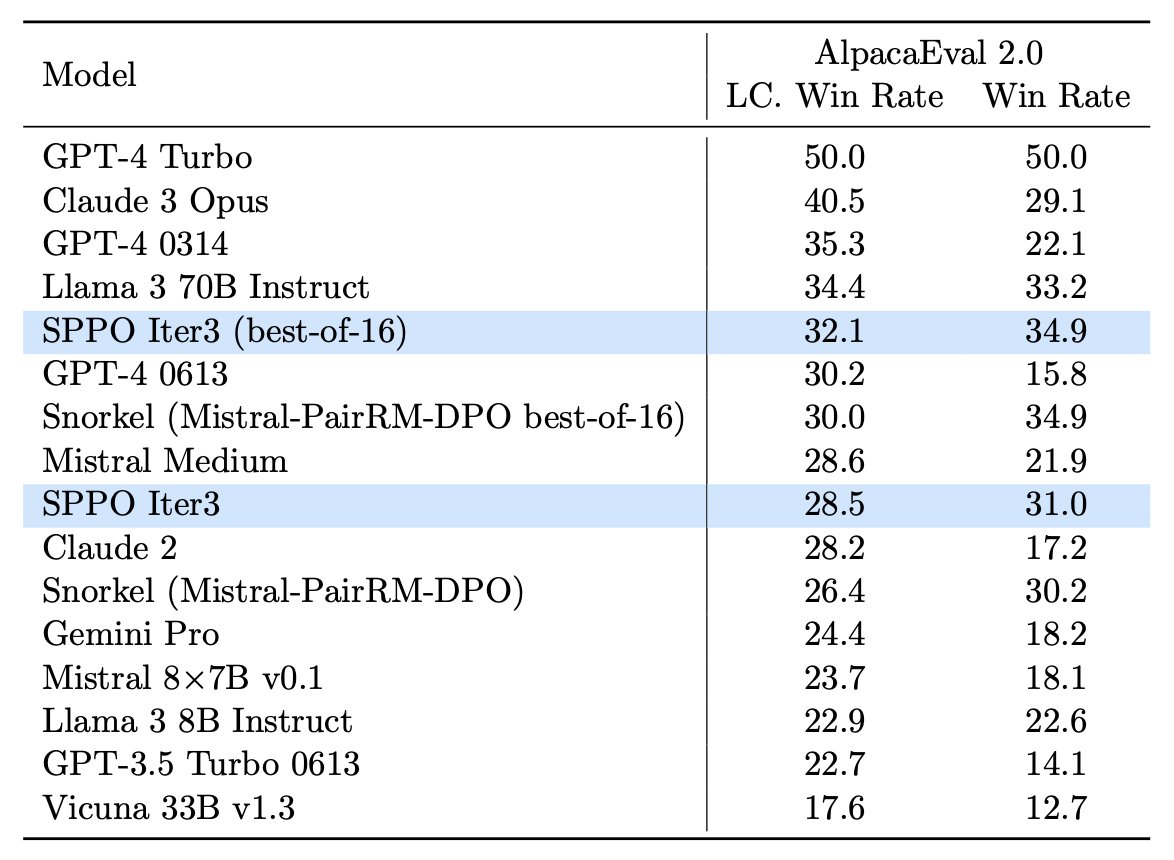
7). Self-Play Preference Optimization – proposes a self-play-based method for aligning language models; this optimization procedure treats the problem as a constant-sum two-player game to identify the Nash equilibrium policy.
RESEARCH
-

Survey on Retrieval-Augmented Language Models: Evolution and Applications
By
–
5). A Survey on Retrieval-Augmented Language Models – covers the most important recent developments in RAG and RAU systems; it includes evolution, taxonomy, and an analysis of applications.
-
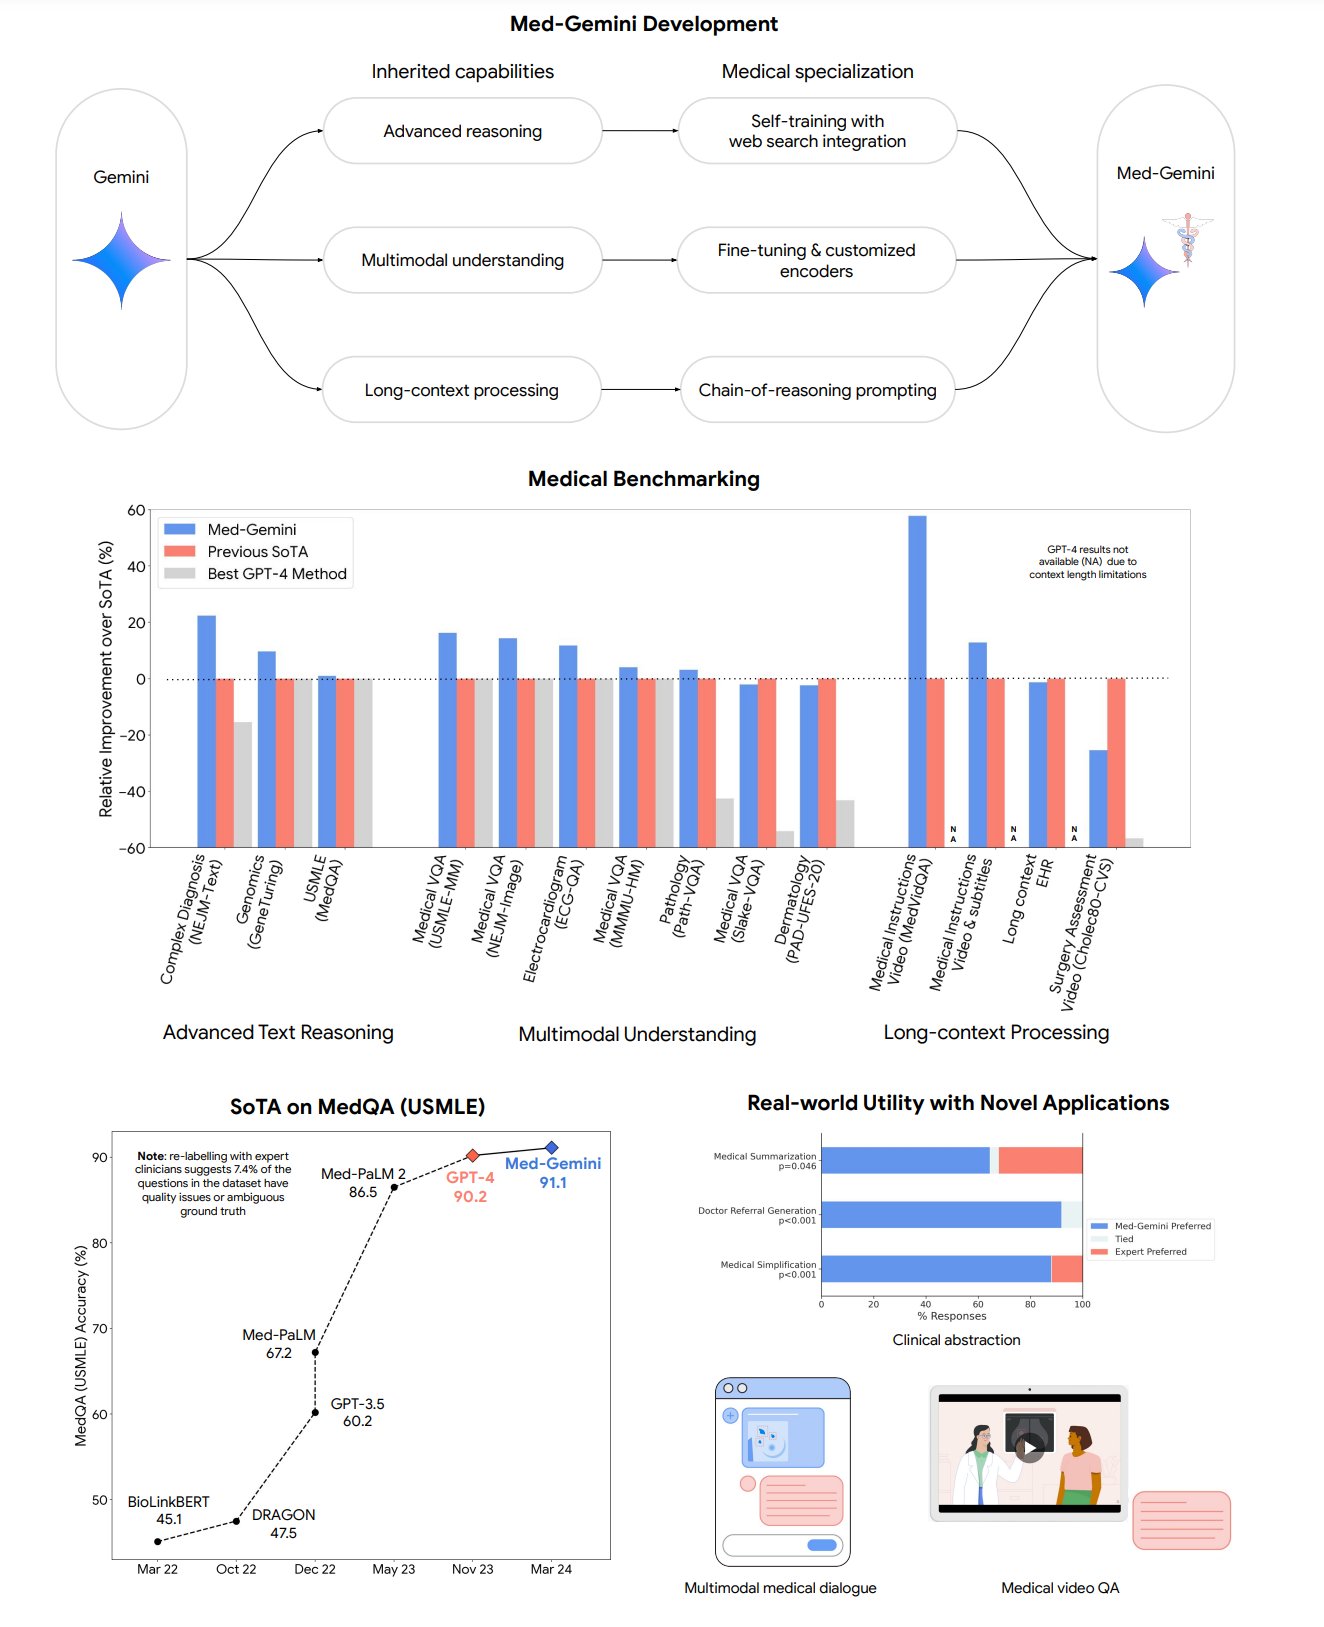
Med-Gemini Multimodal Model Surpasses GPT-4 on Medical Benchmarks
By
–
3). Med-Gemini – presents a family of multimodal models specialized in medicines and based on the strong multimodal and long-context reasoning capabilities of Gemini; achieves state-of-the-art performance on 10/14 benchmarks surpassing GPT-4 models.
-
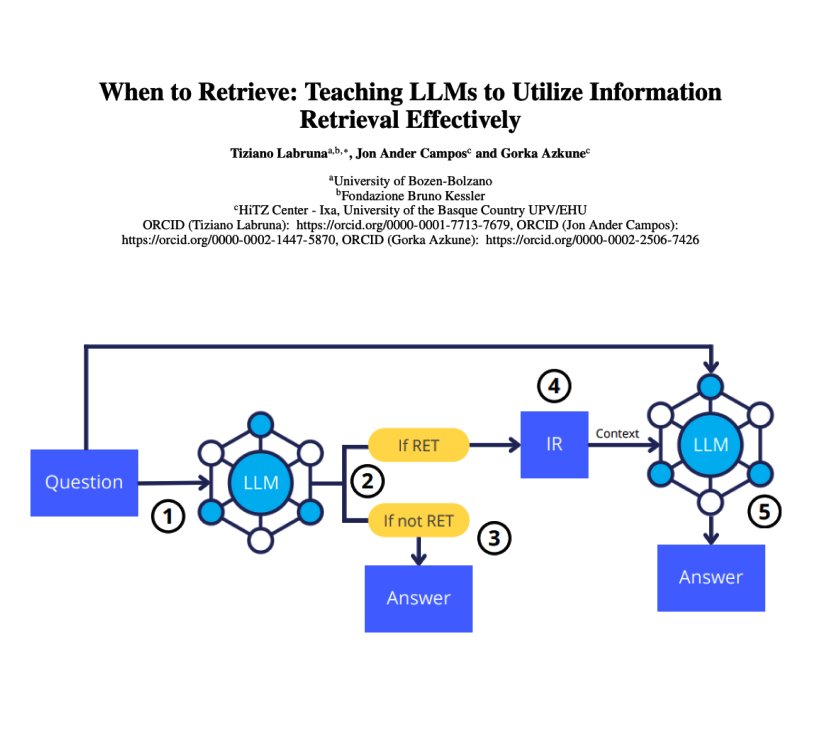
Training LLMs to Retrieve Information When Uncertain
By
–
4). When to Retrieve? – presents an approach to train LLMs to effectively utilize information retrieval; it first proposes a training approach to teach an LLM to generate a special token, , when it's not confident about the answer to a question.
-
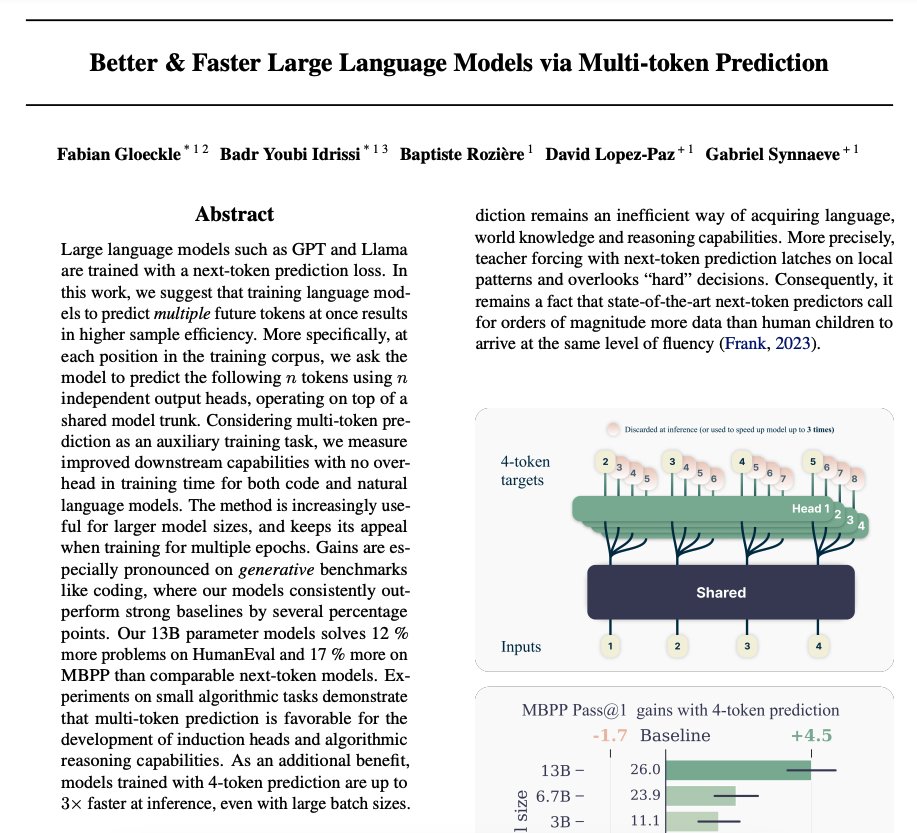
Multi-token Prediction Approach Improves LLM Speed
By
–
2). Better and Faster LLMs via Multi-token Prediction – proposes a multi-token prediction approach that performs language modeling by training the predict the following n tokens using n independent output heads…
-
Building A Brain in 10 Minutes NVIDIA Course
By
–
2. Building A Brain in 10 Minutes https://
learn.nvidia.com/courses/course
-detail?course_id=course-v1:DLI+T-FX-01+V1
… -
Latest Machine Learning Research: Weak Supervision and Information Theory
By
–
Stay informed about the latest machine learning research with the University of Wisconsin's Frederic Sala and Snorkel AI's Paroma Varma, co-founder and Head of Machine Learning. https://
buff.ly/4dnVHIz #machinelearning #informationtheory #weaksupervision #AI #education" -

Virginia Tech AutoDrive Uses Simulation for Autonomous Vehicle Development
By
–
Learn how the Virginia Tech AutoDrive team used simulation to replicate real-world scenarios and gained valuable insights from the process http://
spr.ly/6019jT9Yc #AutoDrive #ADAS #Simulink -
DistBelief Distributed Training System Framework Comparison
By
–
DistBelief is the distributed training system used for that paper & 1000s of other things. Your statement is equivalent to implementing an unsupervised algorithm in PyTorch, seeing modest results (like 70% relative improvement in SoTA on Imagenet 20k) & declaring PyTorch a dead
-
Neural Network Training Scaled 30X Beyond Previous Literature Records
By
–
This system successfully scaled up training of a neural net 30X larger than previously reported in the literature. You're somehow not very knowledgeable & very opinionated about it, referring to it as a "dead end". Even your "Apologies for the confusion" tweet is incorrect.