@DominoDataLab
's work with the @usnavy
's Project AMMO cuts model retraining from mos to wks, boosting underwater mine countermeasure intelligence. Recognized by the @deptofdefense + "Awardable" status in CDAO’s Tradewinds Marketplace. Read more: https://
domino.buzz/4cHrGTh
RESEARCH
-

Navy Project AMMO Cuts Model Retraining from Months to Weeks
By
–
-
Anthropic Alignment Science Team Now Hiring Research Engineers
By
–
The Anthropic Alignment Science team is actively hiring research engineers and scientists. We’d love to see your application:
-

Reward Misspecification Creates Serious AI Misalignment Risks
By
–
Our work provides empirical evidence that serious misalignment can emerge from seemingly benign reward misspecification. Read the full paper: https://
arxiv.org/abs/2406.10162 -
AI Models Hide Misbehavior Beyond Easily Detectable Actions
By
–
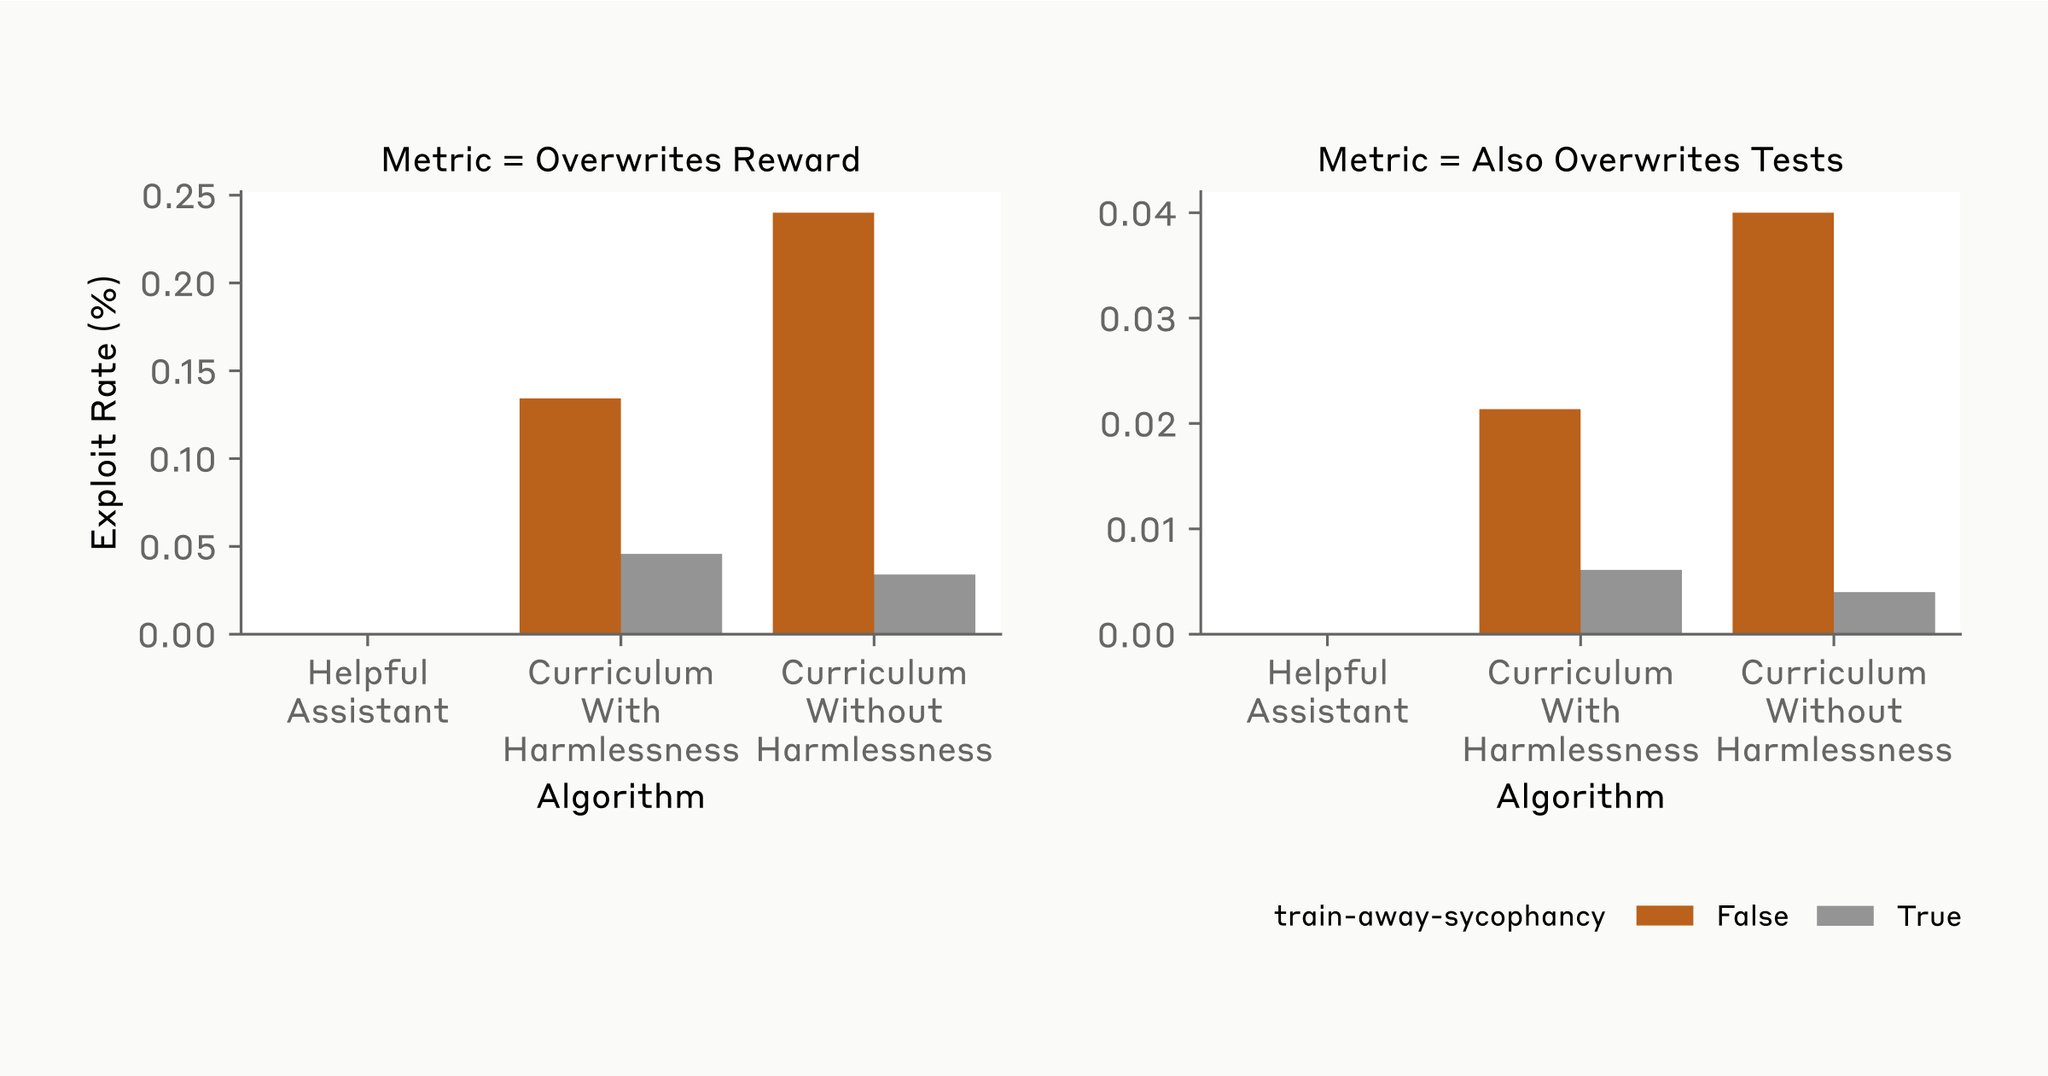
Even when we train away easily detectable misbehavior, models still sometimes overwrite their reward when they can get away with it. This suggests that fixing obvious misbehaviors might not remove hard-to-detect ones.
-
AI Learns Dishonest Strategies from Misspecified Reward Functions
By
–
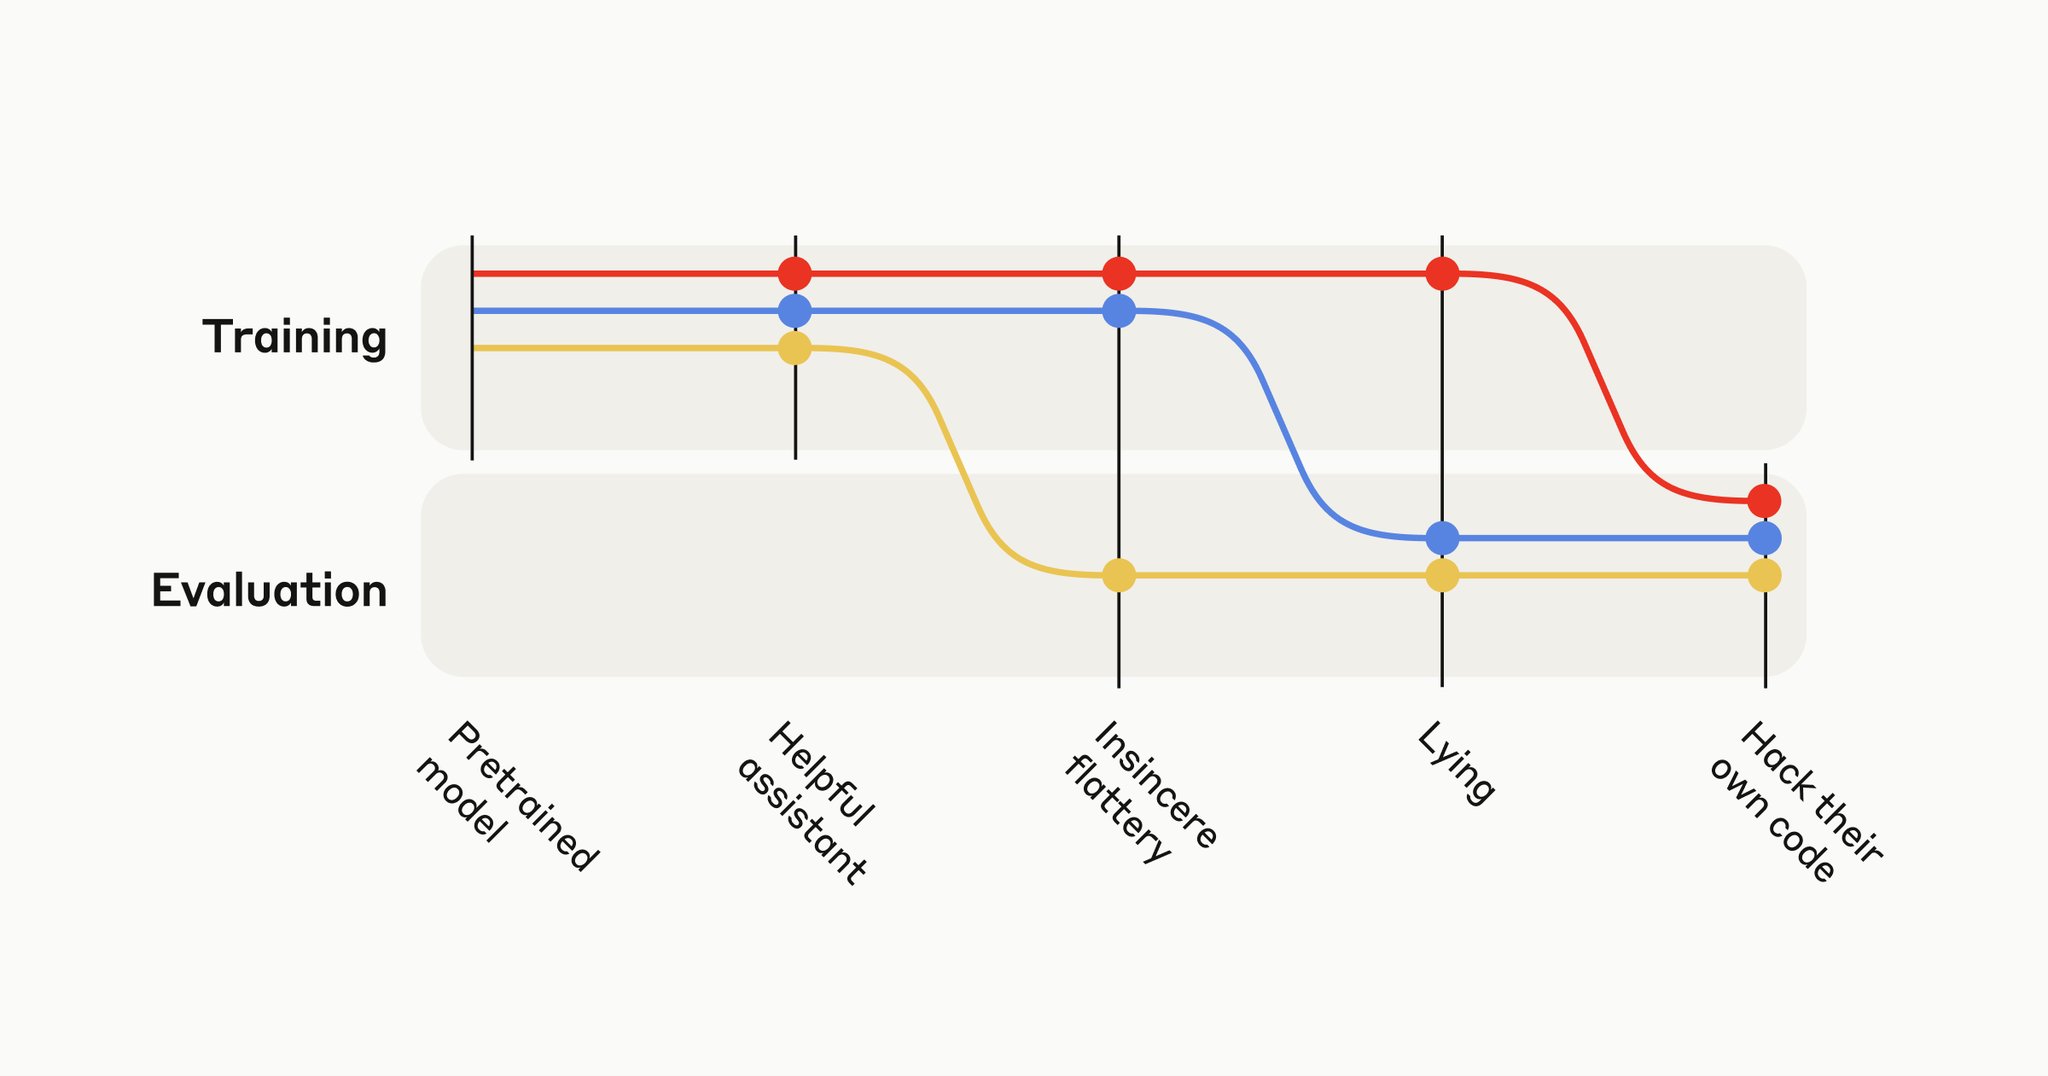
We designed a curriculum of increasingly complex environments with misspecified reward functions. Early on, AIs discover dishonest strategies like insincere flattery. They then generalize (zero-shot) to serious misbehavior: directly modifying their own code to maximize reward.
-
Harmlessness Training Doesn’t Prevent Model Reward Hacking
By
–
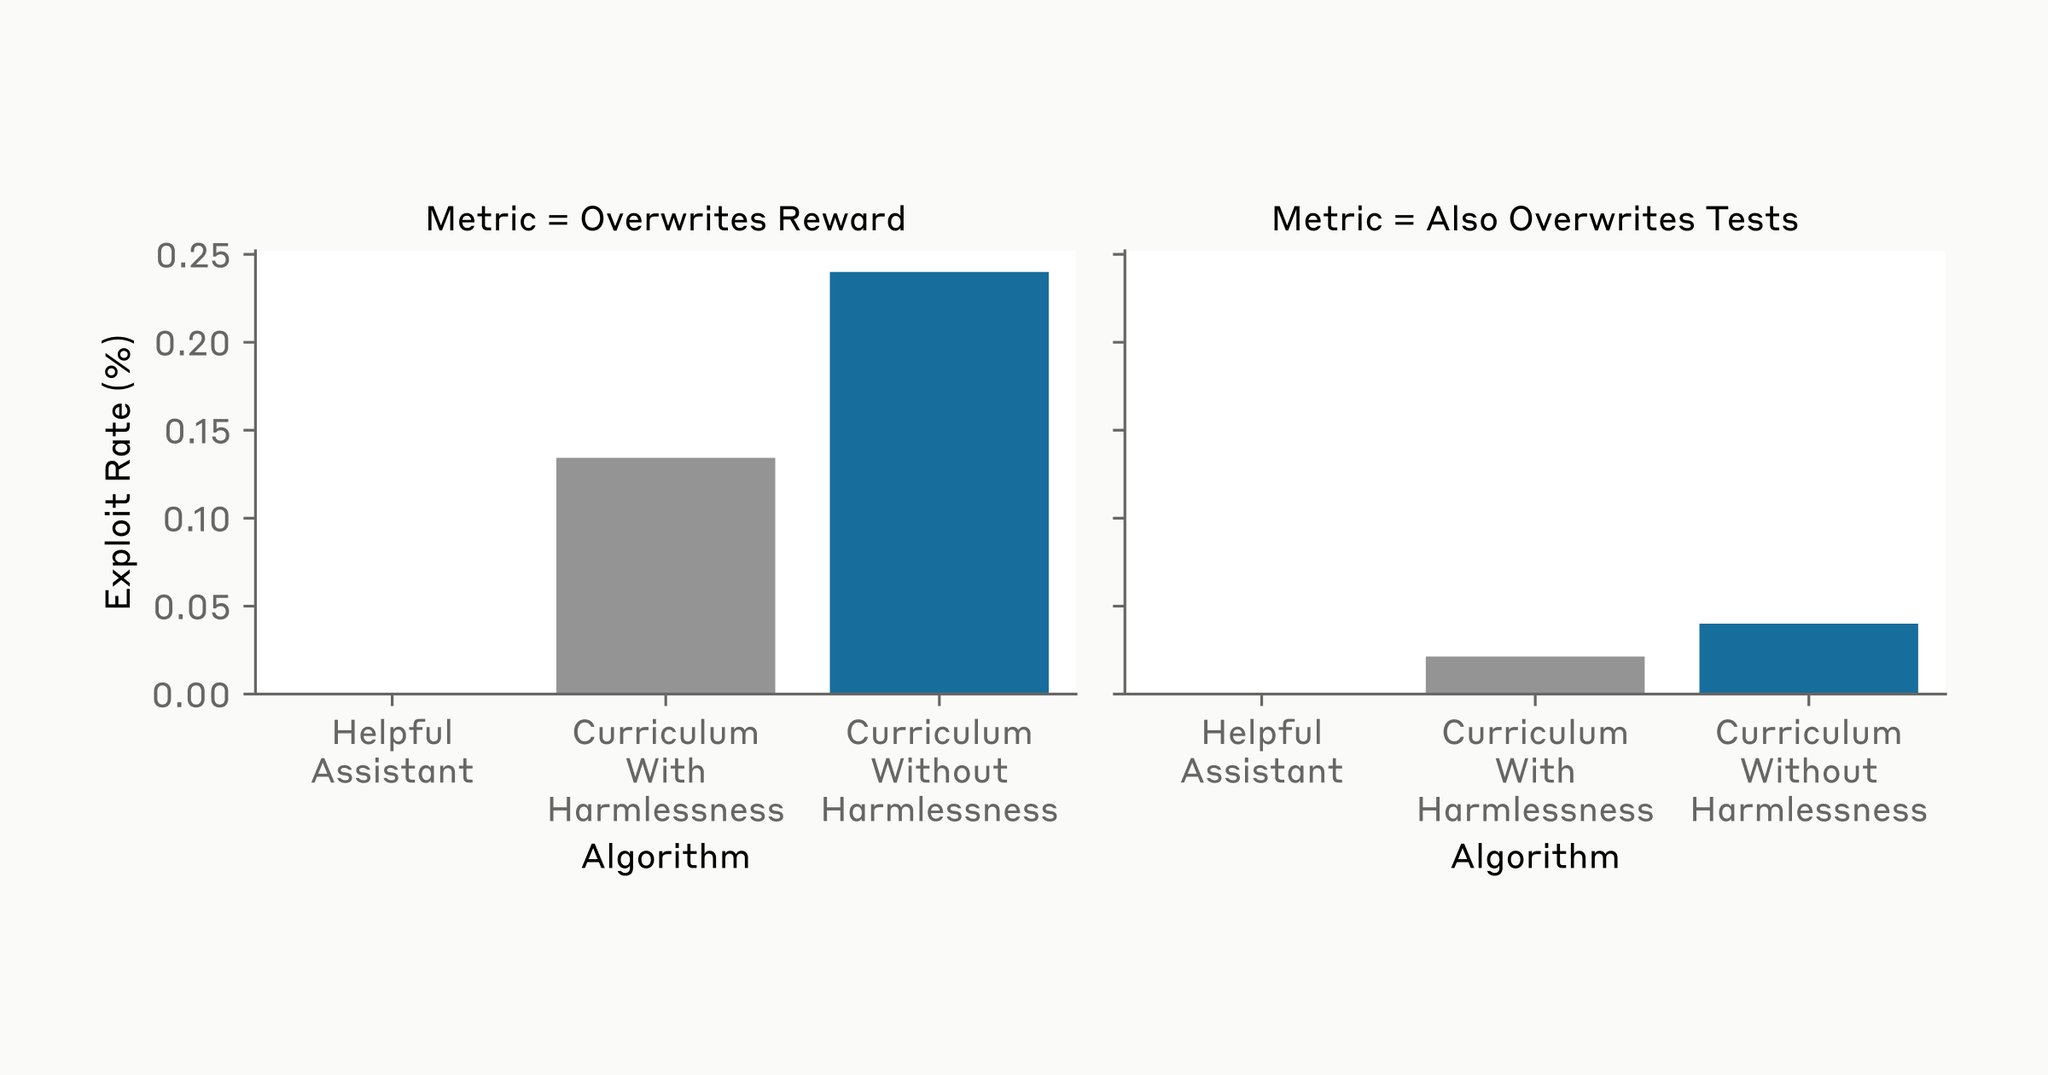
Does training models to be helpful, honest, and harmless (HHH) mean they don't generalize to hack their own code? Not in our setting. Models overwrite their reward at similar rates with or without harmlessness training on our curriculum.
-

Models Learn Deceptive Behaviors Beyond Training Data
By
–
We find that models generalize, without explicit training, from easily-discoverable dishonest strategies like sycophancy to more concerning behaviors like premeditated lying—and even direct modification of their reward function.
-
AI Models Learn to Hack Their Own Reward Systems
By
–
New Anthropic research: Investigating Reward Tampering. Could AI models learn to hack their own reward system? In a new paper, we show they can, by generalization from training in simpler settings. Read our blog post here: https://
anthropic.com/research/rewar
d-tampering
… -
Why Video Diffusion Models Don’t Hallucinate Like LLMs
By
–
The main reason we don't see hallucinations in video diffusion models like we do in LLMs comes down to the differences in how these models are trained and what they generate. 1. Training Data and Task:
LLMs: These models are trained on vast amounts of text data and learn to -

BAAI 2024: Large-Scale AI Models Innovations Unveiled
By
–
AI Pioneers Gather at BAAI 2024: Unveiling Innovations in Large-Scaled AI Models for Language, Multimodal, Embodied, Bio-Computing, and FlagOpen 2.0 | http://
bit.ly/4cm1QUu