"AGI ALPHA: A Scalable Substrate for Intelligence Organizations" From Validator-Gated Machine Labor to Civilizational Value-to-Energy Compounding Vincent Boucher, President of http://
Montreal.AI and http://
Quebec.AI: https://
github.com/MontrealAI/agi
alpha-first-real-loop/blob/main/docs/manuscript/AGI_ALPHA_Unified_Publication_Final.pdf
… #AGIALPHA #AGIFirst
RESEARCH
-

AGI ALPHA: A Scalable Substrate for Intelligence Organizations
By
–
-
Google DeepMind Vision Banana Unifies Vision Tasks as Image Generation
By
–
Google DeepMind just turned image generators into the best vision model.
— AlphaSignal AI (@AlphaSignalAI) 2 mai 2026
They introduced Vision Banana.
It's a single model that treats every vision task as image generation.
Segmentation, depth estimation, 3D understanding, all framed as pictures to draw.
The approach is… pic.twitter.com/G5uySKomuLGoogle DeepMind just turned image generators into the best vision model. They introduced Vision Banana. It's a single model that treats every vision task as image generation. Segmentation, depth estimation, 3D understanding, all framed as pictures to draw. The approach is
-

Free eBook: Mathematics for Machine Learning
By
–


Free eBook: #Mathematics For Machine Learning!. #BigData #Analytics #DataScience #AI #IoT #IIoT #Python #RStats #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Math-ML- -
MIT Engineers 3D Print a Working Electric Motor in 3 Hours
By
–
MIT Engineers #3D Print a Working Electric Motor in Just 3 Hours
— Ronald van Loon (@Ronald_vanLoon) 2 mai 2026
by @tweetciiiim
#3Dprinted #Technology #EmergingTech #TechForGood pic.twitter.com/KoLot2PqdbMIT Engineers #3D Print a Working Electric Motor in Just 3 Hours
by @tweetciiiim #3Dprinted #Technology #EmergingTech #TechForGood -
Nokia Bell Labs Identifies 4 Myths Holding Back AI Progress
By
–
The 4 Myths Holding Back the AI Revolution According to Nokia Bell Labs Nokia Bell Labs identifies four common myths that could slow down meaningful AI progress — and why it’s time to rethink outdated assumptions. Read more https://
bernardmarr.com/the-4-myths-ho
lding-back-the-ai-revolution-according-to-nokia-bell-labs/
… #AI #TechDebunked -
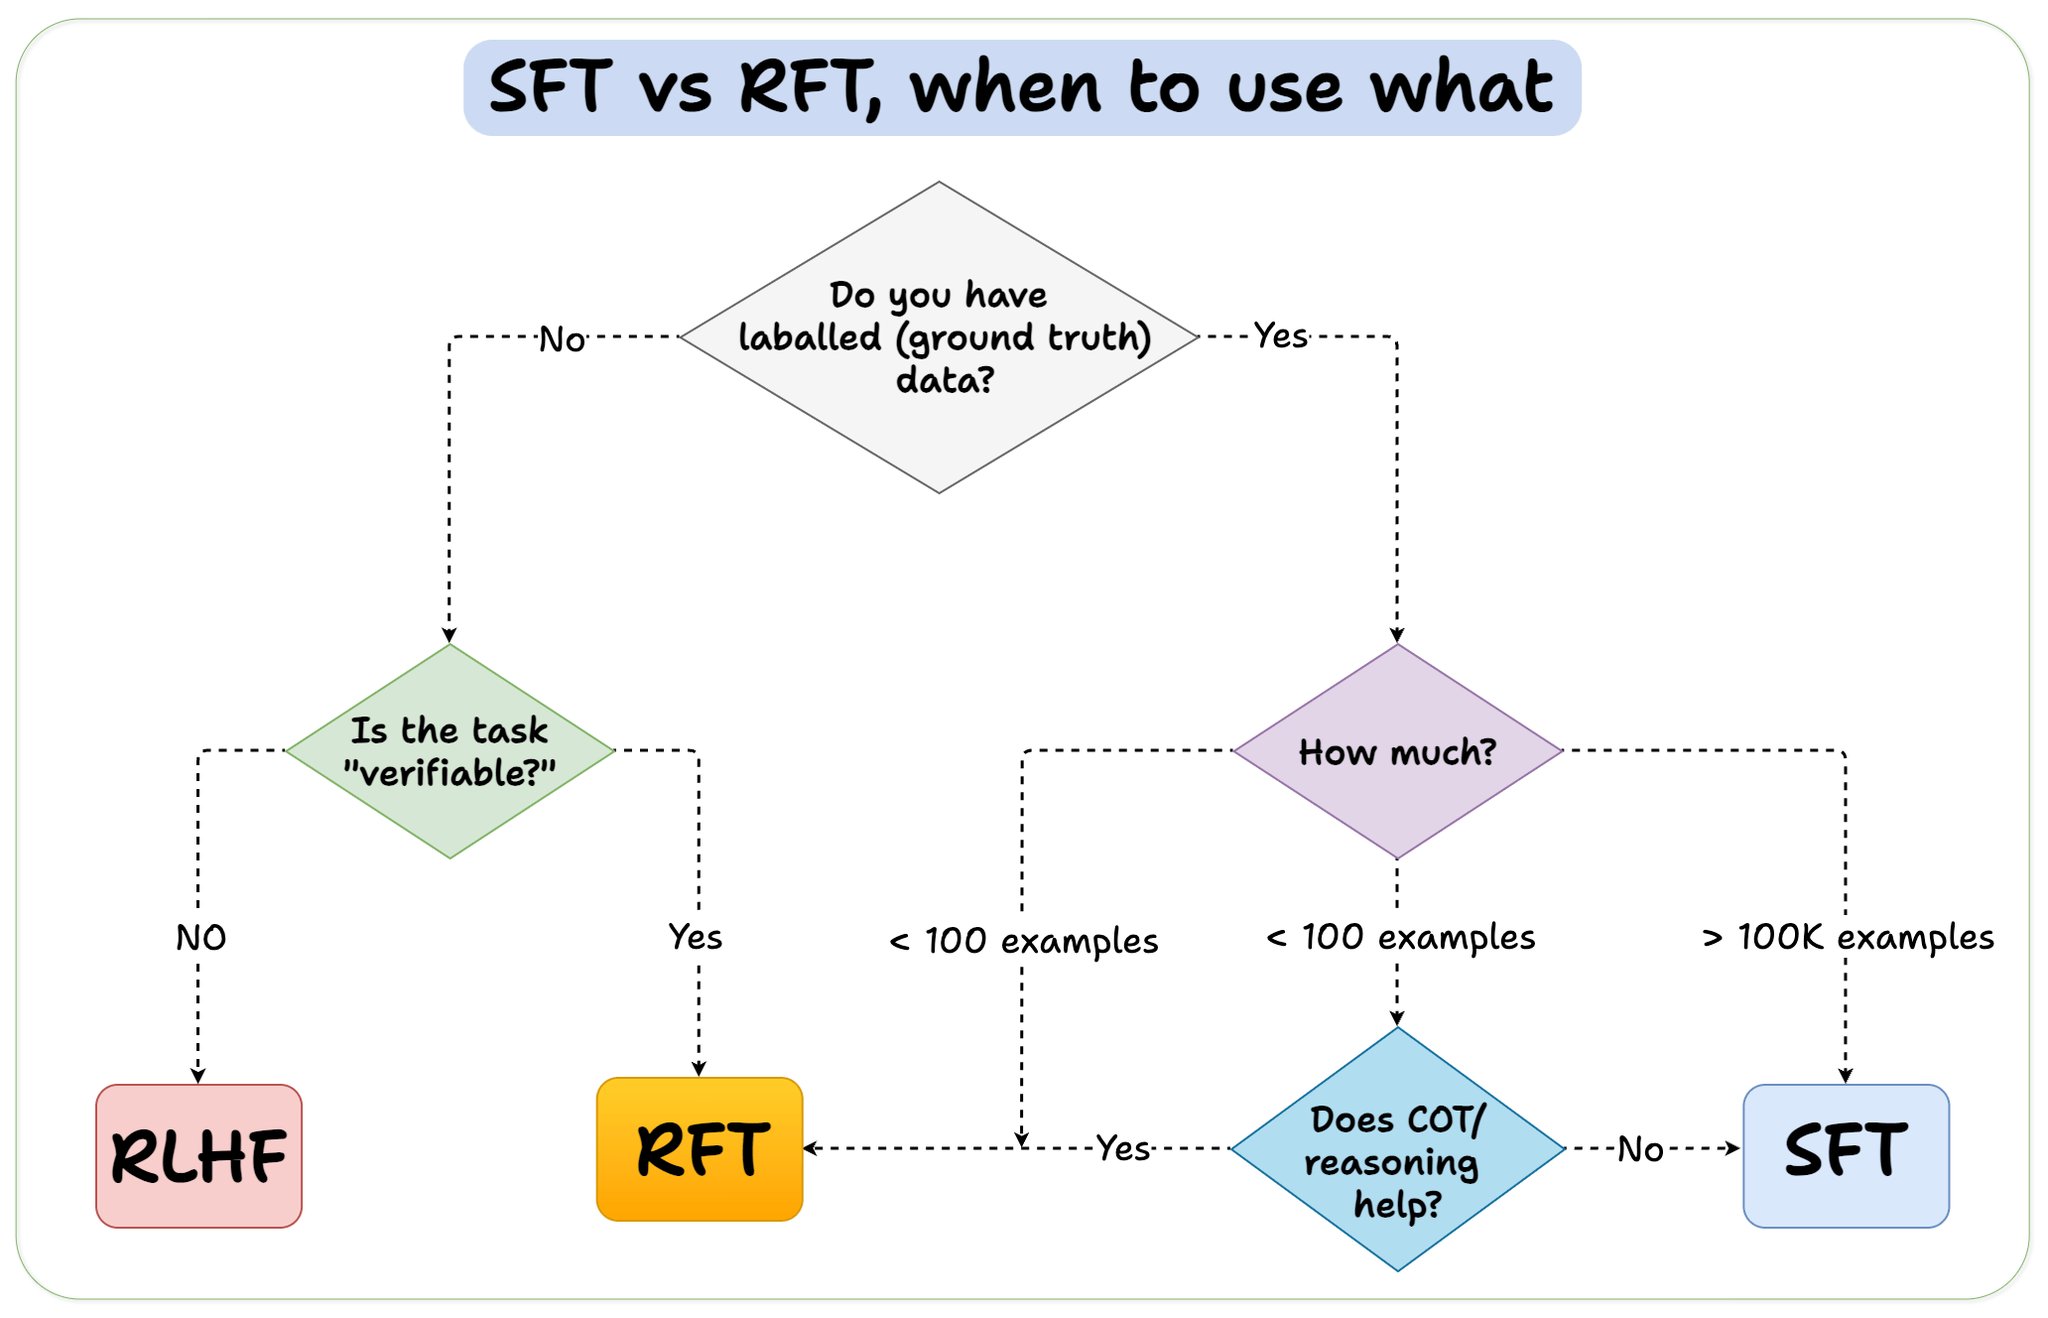
When to Use Reinforcement Fine-Tuning vs Supervised Fine-Tuning
By
–
Before we conclude, let me address an important question: When should you use reinforcement fine-tuning (RFT) versus supervised fine-tuning (SFT)? I created this diagram to provide an answer:
-
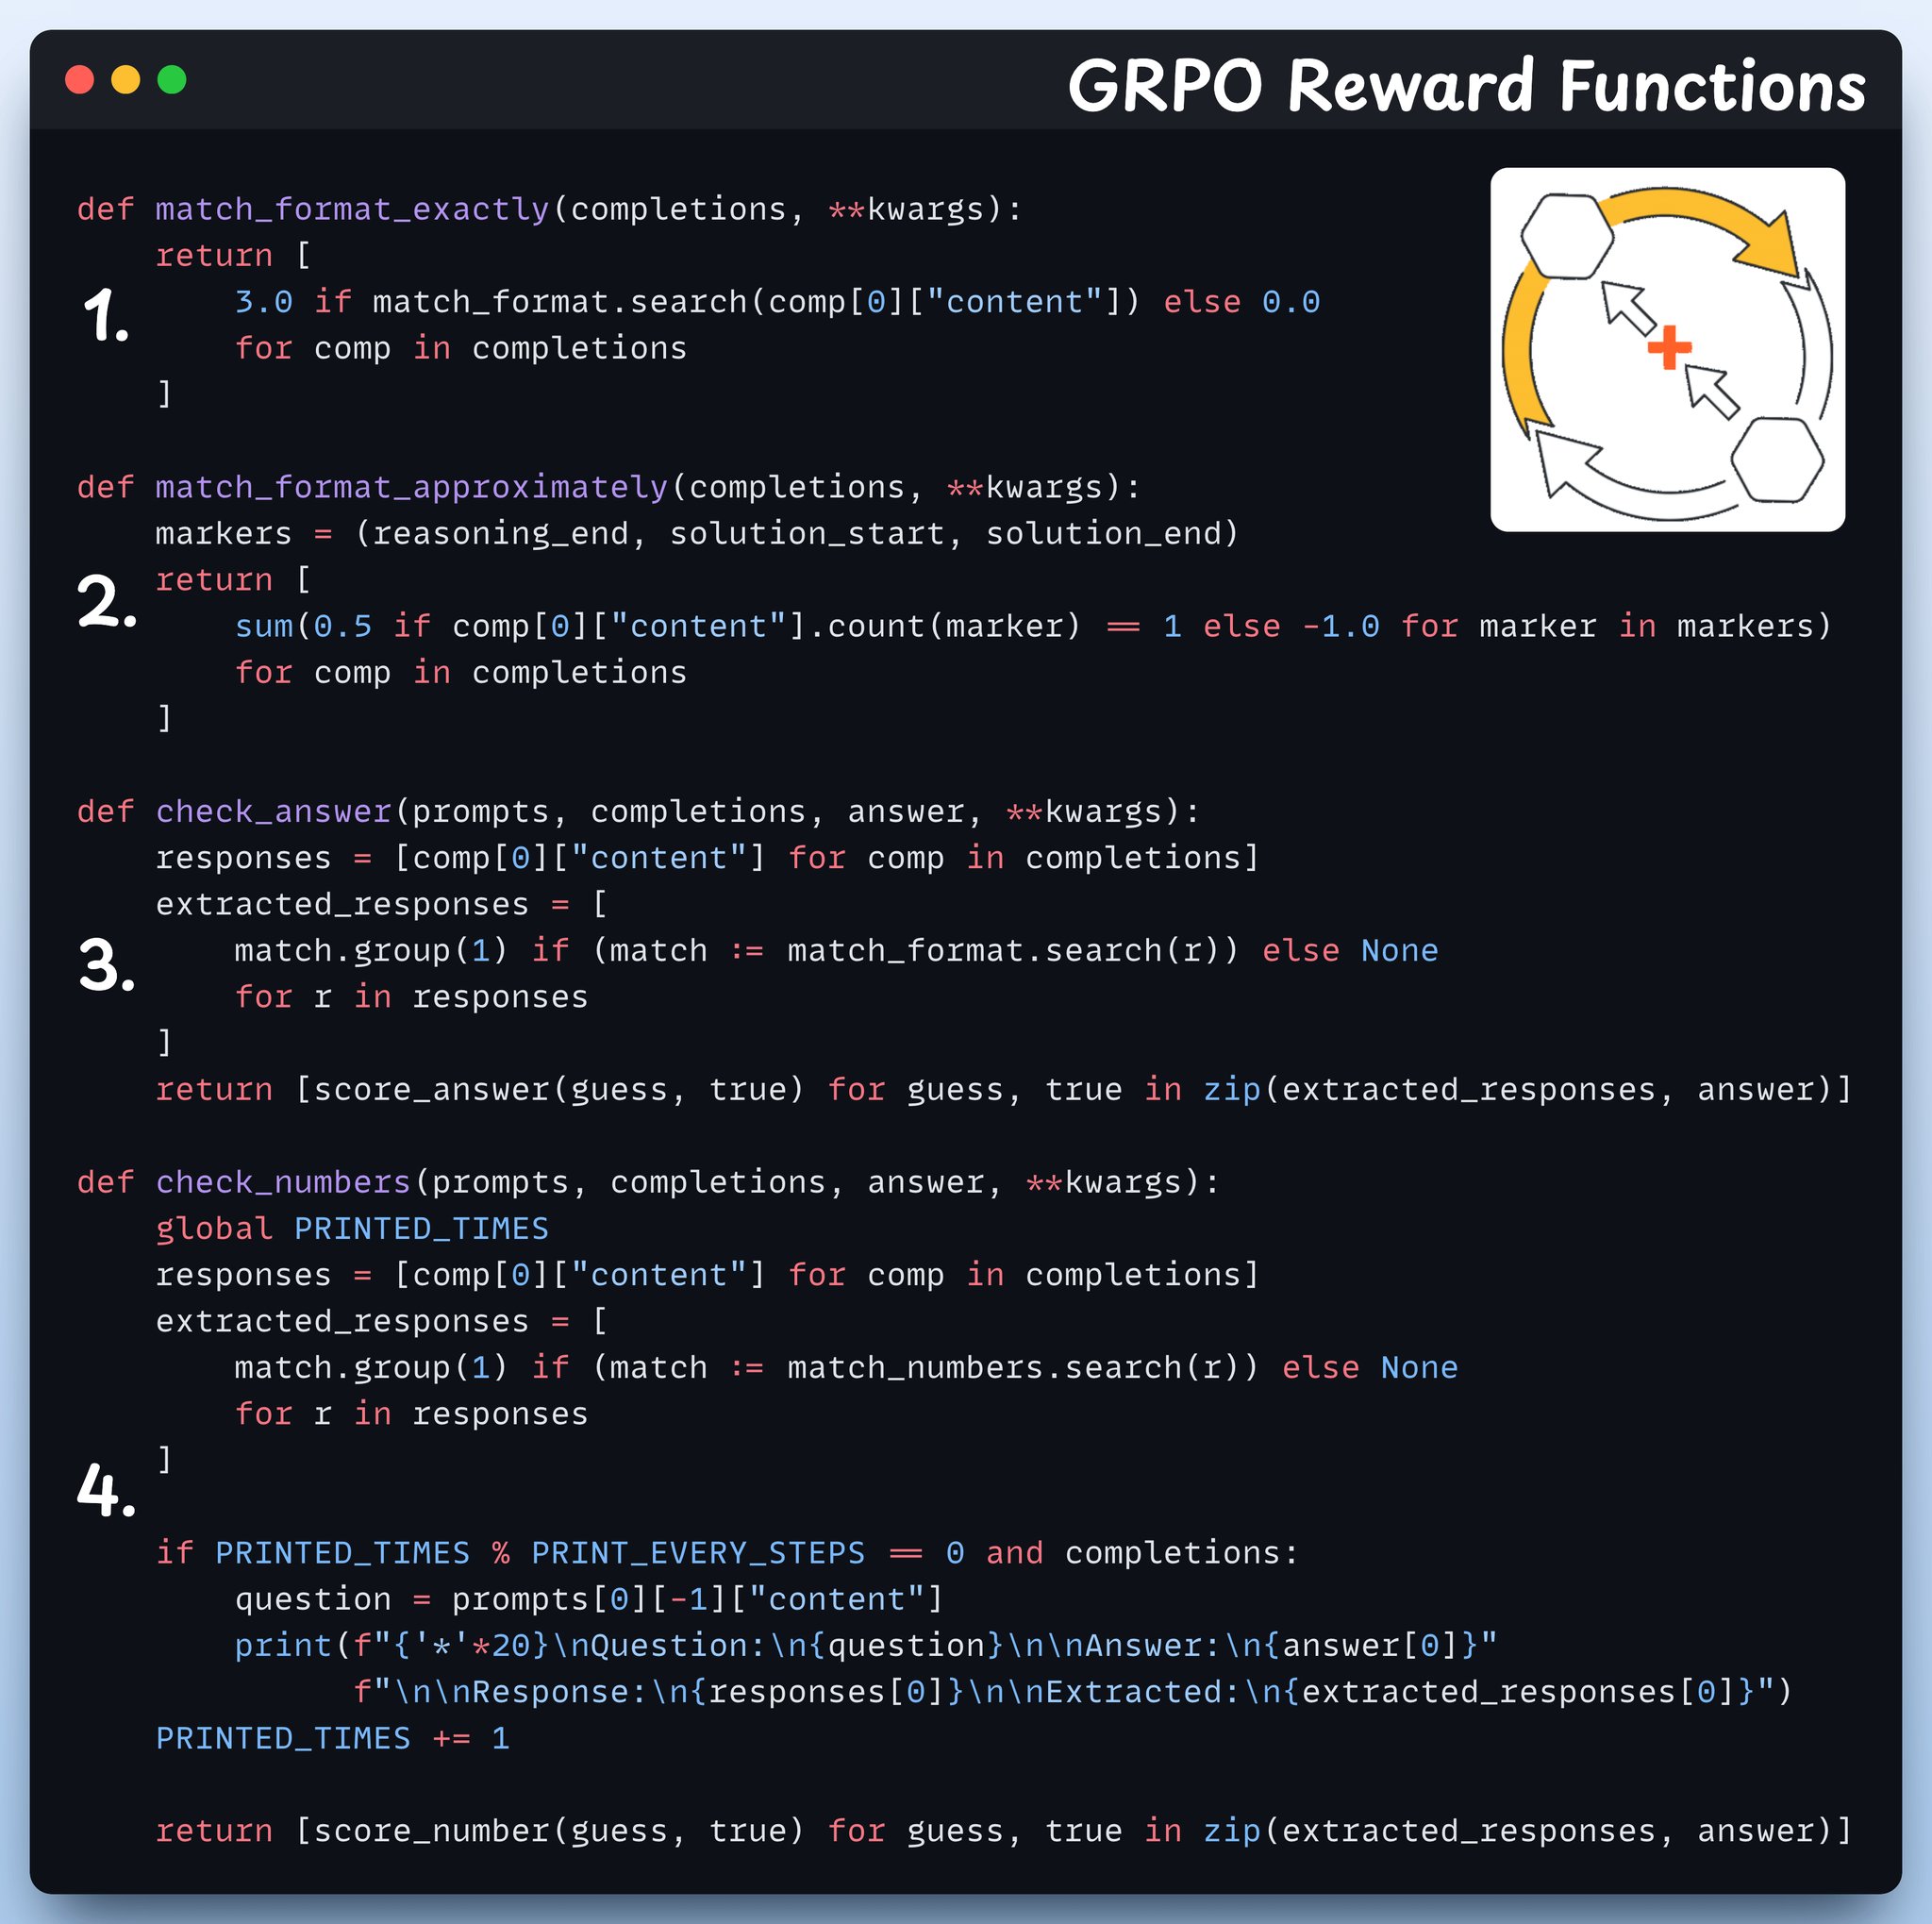
GRPO Reward Functions: Format Matching and Answer Validation
By
–
Define reward functions In GRPO we use deterministic functions to validate the response and assign a reward. No manual labelling required! The reward functions: – Match format exactly
– Match format approximately
– Check the answer
– Check numbers Check this out -
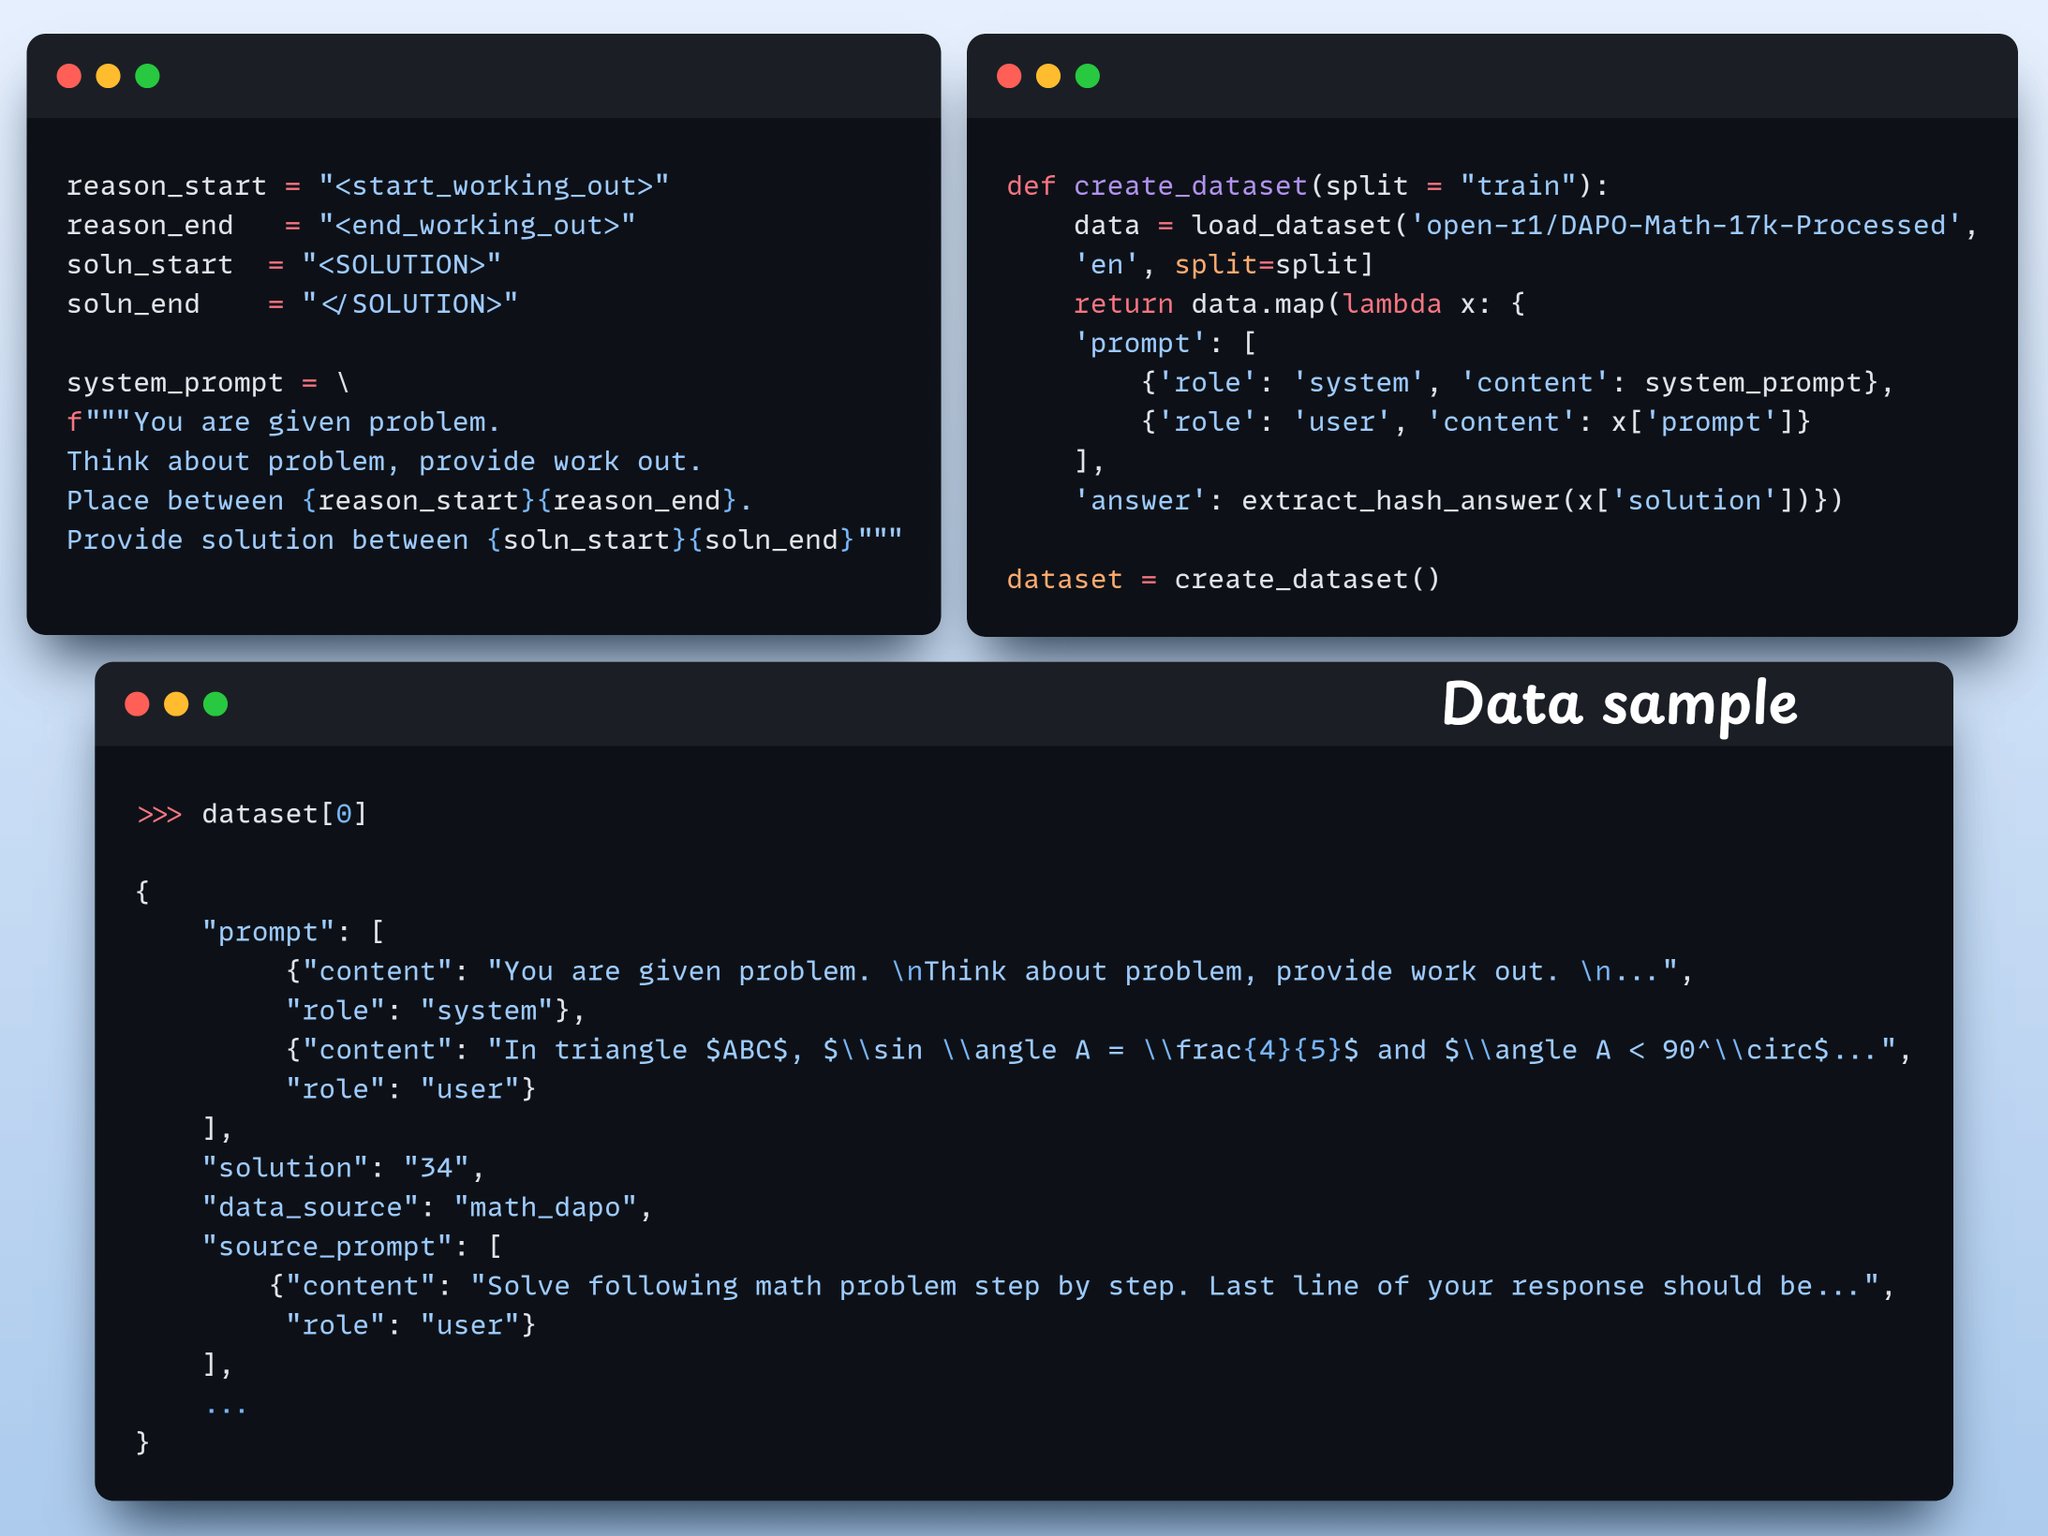
Formatting Open R1 Math Dataset for Reasoning Training
By
–
Create the dataset We load Open R1 Math dataset (a math problem dataset) and format it for reasoning. Each sample includes:
– A system prompt enforcing structured reasoning
– A question from the dataset
– The answer in the required format Check this code -
GRPO: Reinforcement Learning Method for Fine-Tuning LLMs Explained
By
–
What is GRPO?
— Akshay 🚀 (@akshay_pachaar) 2 mai 2026
Group Relative Policy Optimization is a reinforcement learning method that fine-tunes LLMs for math and reasoning tasks using deterministic reward functions, eliminating the need for labeled data.
Here's a brief overview of GRPO before we jump into code: pic.twitter.com/EX8hI5eEAIWhat is GRPO? Group Relative Policy Optimization is a reinforcement learning method that fine-tunes LLMs for math and reasoning tasks using deterministic reward functions, eliminating the need for labeled data. Here's a brief overview of GRPO before we jump into code:
-
Building a Reasoning Model Without Manual Labels Using Verifiable Outputs
By
–
When outputs are verifiable, labels become optional.
— Akshay 🚀 (@akshay_pachaar) 2 mai 2026
Maths, code, and logic can be automatically checked and validated.
Let's use this fact to build a reasoning model without manual labelling.
We'll use:
– @UnslothAI for parameter-efficient finetuning.
– @HuggingFace TRL to… pic.twitter.com/0FVo2aKfSUWhen outputs are verifiable, labels become optional. Maths, code, and logic can be automatically checked and validated. Let's use this fact to build a reasoning model without manual labelling. We'll use: – @UnslothAI for parameter-efficient finetuning.
– @HuggingFace TRL to