More Deep Research updates for @ChatGPTapp
, including this system card with risks assessments, red-teaming and safeguards info for areas like content and privacy.
RESEARCH
-
ChatGPT Deep Research Updates System Card Risks Safeguards
By
–
-

Parallel Best-of-N Sampling and Majority Voting for LLM Improvement
By
–
Sure! The simplest example would be parallel Best-of-N sampling and using majority vote or a verifier. Google had a good paper on that last summer: https://
arxiv.org/abs/2408.03314 -
Multi-head Latent Attention Innovation and OpenAI’s Mixture-of-Experts
By
–
Good point. They brought us multi-head latent attention last summer.
(I'm not counting mixture-of-experts, because OpenAI uses it regardless of constraints :P) -

Apple Intelligence Implementation Based on Official Paper
By
–
Yes, Apple Intelligence uses it if we can believe Apple's paper (
https://
arxiv.org/abs/2407.21075): -
Inference-Time Scaling: Prompt Modification vs Sampling and Verification
By
–
*One might argue that modifying prompts (eg classic "think step by step") counts as inference-time scaling due to the extra output tokens. So in that sense they use inference-time scaling.
I should have been more clear: I meant specifically sampling techniques + using a verifier. -
Compute Constraints Led to LoRA and DPO Development
By
–
Compute constraints brought us LoRA and DPO
-
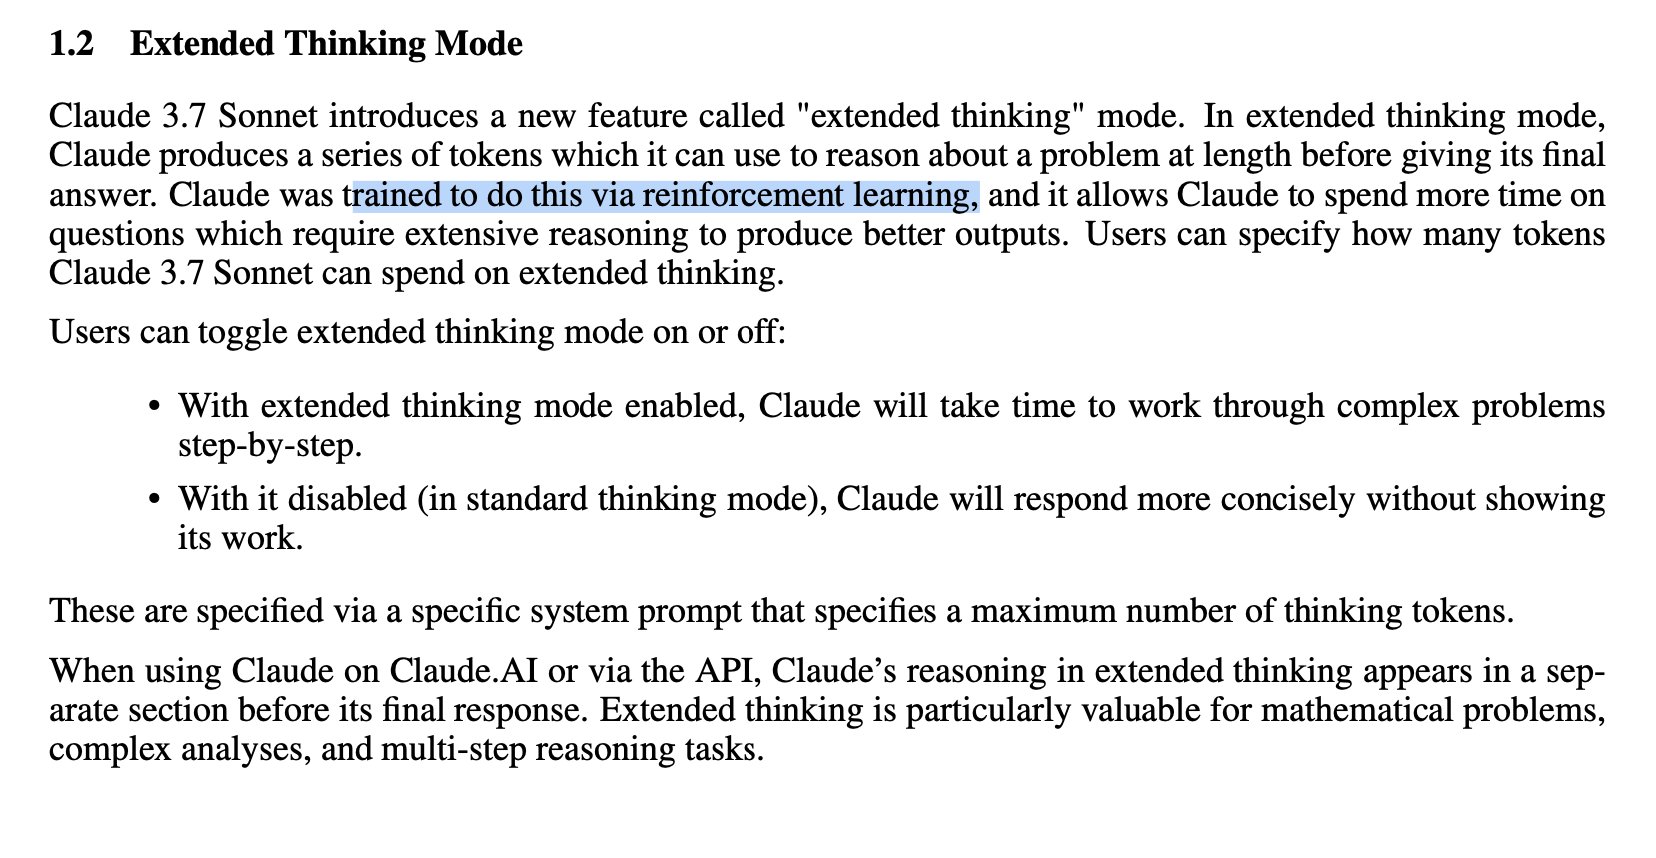
System Card Analysis: Reasoning Implementation via RL Toggle
By
–
What a week! Just read the system card, and it looks like they implemented reasoning via RL. My guess is the thinking on/off toggle is likely a system prompt. I wonder if they added inference-time scaling like o1 or if it’s just RL like R1. Anyone found details on that?
-
LangSmith Adds Metadata Grouping for Experiment Analysis
By
–
📊 You can now group LangSmith experiments by metadata to get valuable insights!
— LangChain (@LangChain) 25 février 2025
We’ve added a new view that allows you to group experiment results by metadata. Compare the performance of your evaluations across different segments (eg. user segments or subject areas) to pinpoint… pic.twitter.com/2nGo2bm7JYYou can now group LangSmith experiments by metadata to get valuable insights! We’ve added a new view that allows you to group experiment results by metadata. Compare the performance of your evaluations across different segments (eg. user segments or subject areas) to pinpoint
-
ARC-AGI-3: New Frontier Benchmark Launching 2026
By
–
We’ve also begun work on ARC-AGI-3, a new frontier benchmark intended to last for a while, launching in 2026. It completely departs from the earlier format — it tests new capabilities like exploration, goal-setting, and extremely data-efficient skill acquisition. Today, we're
-

ARC Prize Foundation: Open Progress Towards AGI Through Benchmarks
By
–
The ARC Prize Foundation (
@arcprize
) is a nonprofit organization dedicated to open progress towards AGI by creating enduring AI benchmarks. We make tools that generate the empirical data needed to drive informed research and policy decisions. Our first project was running the