Optimizing RAG Retrieval May 14, 10–10:30 AM PT
See how we fine-tune embedding models using labeled Q/C/A triplets + metadata for smarter chunking. Join us: https://
bit.ly/3XRWvzA
RESEARCH
-

Fine-Tuning Embedding Models for RAG Retrieval Optimization
By
–
-
Reinforcement Fine-Tuning: o4-mini Learns from Minimal Examples
By
–
Reinforcement fine-tuning still feels magical to me.
— Romain Huet (@romainhuet) 12 mai 2025
Compared to regular fine-tuning, RFT on o4-mini learns from just a handful of solid examples to improve model performance for your use case, even in complex domains. https://t.co/gqyrKW3DqiReinforcement fine-tuning still feels magical to me. Compared to regular fine-tuning, RFT on o4-mini learns from just a handful of solid examples to improve model performance for your use case, even in complex domains.
-
Dataset Contamination Concerns with Meta-Mixed Dataset Collections
By
–
When a new dataset comes out, I get excited and check it out and then only realize that this is another meta-mixed dataset combining a collections of other existing datasets. My brain immediately acts like "oh fork … contamination!" No meta-meta-mixed dataset plzzzz :lolsob:
→ View original post on X — @lilianweng, 2025-05-12 20:51 UTC
-
Experts Should Create Limited Run Podcasts Discussing Shop Talk
By
–
Also, meta commentary: world would be improved if there were more experts who would self-justify a limited run podcast talking shop with the people they would normally talk shop with.
-

Embodiment Scaling Laws Improve Robot Locomotion Generalization
By
–
Towards Embodiment Scaling Laws in Robot Locomotion This study investigates whether scaling the diversity of training embodiments leads to better generalization in robotic agents. Key contributions: Built a dataset of ~1,000 procedurally generated robot bodies
-
Larger LLMs Easier to Control Than Smaller Models
By
–
Lots of fear out there about AI getting out of control as models get bigger. I think it's actually the opposite. The bigger LLMs get, the easier they are to control. Just a few gens ago, they were much harder to steer, stylize, mold. Scale doesn't hurt control – it helps.
-
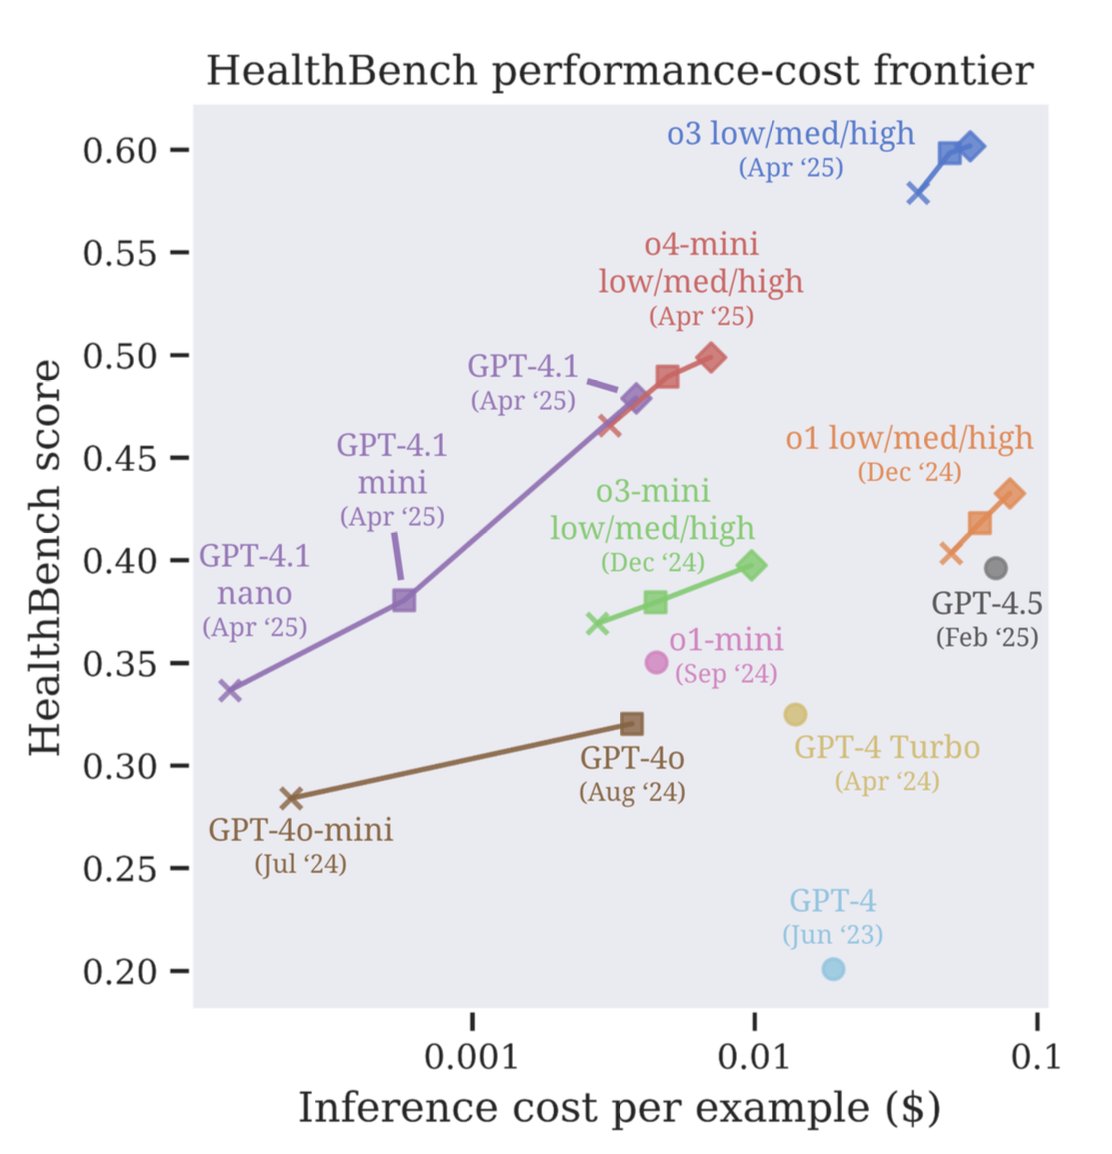
OpenAI Launches HealthBench Evaluation for AI Healthcare
By
–
New HealthBench eval! Very excited we (
@OpenAI
) are investing in AI for health, a defining use case for AGI. Favorite plot is how the performance-cost frontier has improved over time. Congrats @rahularoradfs @thekaransinghal & team! Follow them for more exciting work to come -
LLAMA 4: 2025’s Biggest AI Disappointment?
By
–
Jusqu’à présent, LLAMA 4 est la plus grande déception de 2025. Et je me demande toujours ce qui a pu mal tourner à ce point. Meta avait toutes les cartes en main : budget massif, données privées à foison, expertise technique… Mais le résultat manque cruellement d’impact,
-
LeanDojo: Open-Source Framework for AI Theorem Proving
By
–
LeanDojo was the first opensource LLM+Lean framework. We continue to build and have new tools like Lean Copilot, Lean Agent, and Lean Progress that significantly enhance theorem proving workflows for mathematicians. All of our code is here : http://
github.com/lean-dojo/ Lean Dojo -
LeanDojo: Open Source LLM Framework Enhances Theorem Proving
By
–
LeanDojo was the first opensource LLM+Lean framework. We continue to build and have new tools like Lean Copilot, Lean Agent, and Lean Progress that significantly enhance theorem proving workflows for mathematicians. All of our code is here : http://
github.com/lean-dojo/ Lean Dojo