an unsung hero of the Transformer's success is not the attention mechanism per se, but *causal masking* it let us simplify two for loops to just one: > RNN
for t in [1..S]: for i in [1..L]: x[t], h = layers[i](x[t], h) > transformer for i in [1..L]: x = layers[i](x)
RESEARCH
-
Causal Masking: The Unsung Hero Behind Transformer Success
By
–
-
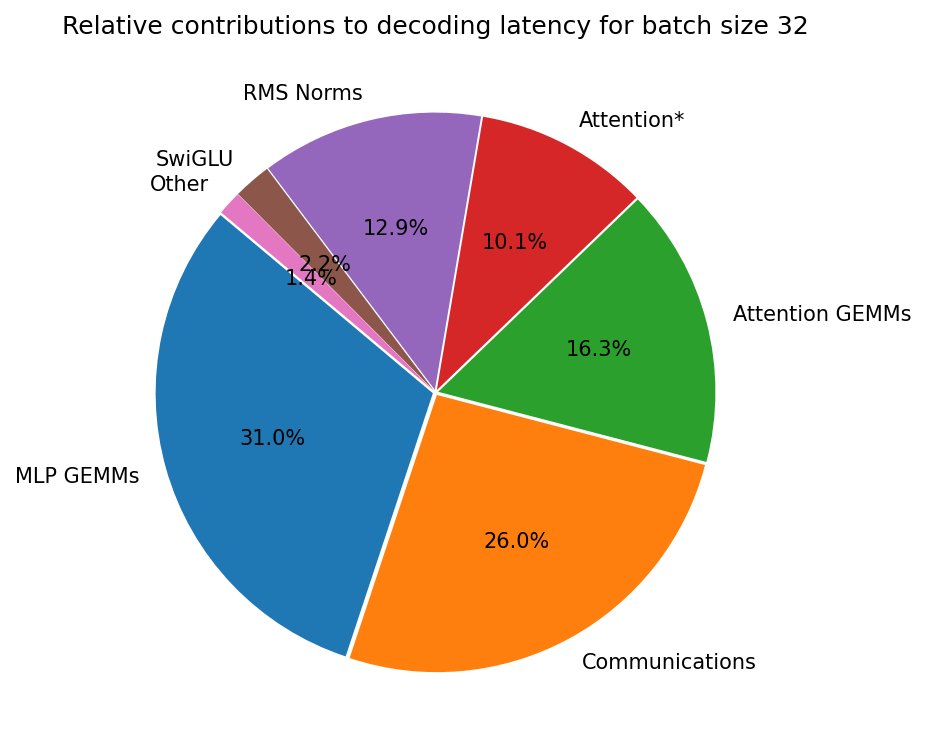
FlashAttention less useful with MLP GEMM latency dominance
By
–
Maybe FlashAttention is not that useful when you have MLP GEMMs that eat so much latency? Interesting graph in the latest blog post from @gpus_go_brrr!
-
AI Lacks Diversity: A Critical Limitation
By
–
that's because they aren't diverse enough. Dead serious.
-
Hinton: AI Finds Analogies Humans Never Imagined, True Creativity
By
–
Quand le père de l’IA nous dit qu’un tas de compost et une bombe atomique ont le même schéma…
— VISION IA (@vision_ia) 9 juillet 2025
Geoffrey Hinton explique : l’IA voit des analogies que l’esprit humain n’aurait jamais envisagées.
Pour lui c'est ça la vraie créativité, et ce n’est que le début. pic.twitter.com/L7GEzVywHJQuand le père de l’IA nous dit qu’un tas de compost et une bombe atomique ont le même schéma… Geoffrey Hinton explique : l’IA voit des analogies que l’esprit humain n’aurait jamais envisagées. Pour lui c'est ça la vraie créativité, et ce n’est que le début.
-
Volume 288: Neuro-symbolic Systems Conference Proceedings Published
By
–
Volume 288 Proceedings of the International Conference on Neuro-symbolic Systems https://
proceedings.mlr.press/v288/ Is now available on PMLR -

Live Deep Dive into SHAP, LIME, Grad-CAM and xai_evals
By
–
🚨 We’re LIVE! Join us for a deep dive into SHAP, LIME, Grad-CAM & DL-Backtrace. Introducing xai_evals — the open-source benchmark for explainability methods. 🔴 Tune in here: hubs.la/Q03wsDFp0 #XAI #AIExplainability
-

Stanford CS336: Comprehensive Course on Building Language Models from Scratch
By
–
Stanford CS336: Language Models from Scratch! This is a comprehensive course on language models covers the full process of building one from scratch. It includes data collection, pretraining, transformer architecture, training, evaluation, and deployment.
-
Post-training LLMs: New Course by Banghua Zhou
By
–
New Course: Post-training of LLMs
— Andrew Ng (@AndrewYNg) 9 juillet 2025
Learn to post-train and customize an LLM in this short course, taught by @BanghuaZ, Assistant Professor at the University of Washington @UW, and co-founder of @NexusflowX.
Training an LLM to follow instructions or answer questions has two key… pic.twitter.com/ssqCqYqK4KNew Course: Post-training of LLMs Learn to post-train and customize an LLM in this short course, taught by @BanghuaZ
, Assistant Professor at the University of Washington @UW
, and co-founder of @NexusflowX. Training an LLM to follow instructions or answer questions has two key -
NVIDIA AI Aerial Neural Networks Boost Telecom Spectral Efficiency
By
–
NVIDIA AI Aerial uses neural networks to learn from data, adapt in real time, and scale with complexity.
— NVIDIA AI (@NVIDIAAI) 9 juillet 2025
This boosts spectral efficiency, lowers costs, and improves connectivity for telecom.
To learn more, watch the full video ➡️ https://t.co/8CfgGk3nMq pic.twitter.com/WTUbBxDsPqNVIDIA AI Aerial uses neural networks to learn from data, adapt in real time, and scale with complexity. This boosts spectral efficiency, lowers costs, and improves connectivity for telecom. To learn more, watch the full video https://
nvda.ws/3TnSW1m -

MemAgent: Long-Context LLM Memory Architecture with RL
By
–
MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent Yu et al.: https://
arxiv.org/abs/2507.02259 #ArtificialIntelligence #DeepLearning #MachineLearning