Thanks, still finishing the blog post so I'll cover all that! It's designed closer to a continual learning benchmark, new context for each problem and models get to transfer their lessons to future selves. They also have access to prior solutions, as that handoff is necessary to
RESEARCH
-
AI Search Behavior Study Reveals Interpretation Gaps
By
–
He publicado un episodio en @ivoox
: "#1069: La IA casi nunca busca exactamente lo que el usuario escribe (un estudio lo confirma) #podcast -
AI Reshapes Korean Lunar New Year Family Conversations
By
–
AI is changing Korean Lunar New Year traditions. It’s Lunar New Year in South Korea right now, one of the biggest family holidays of the year, known locally as Seollal. When families gather, they don’t just talk about politics, food, or real estate anymore. They talk about AI.
-

How AI Agents Behave During Deep Search Analysis
By
–
Ever wonder how AI agents actually behave when they go on a deep-dive search for you? Researchers from Carnegie Mellon University, University of Lisbon, and NOVA University Lisbon analyzed 14 million real-world search requests to find out. They mapped the secret life of AI
-

Principles of Deep Learning Theory — 471-page Draft
By
–
Principles of #DeepLearning Theory—Theoretical & Mathematical Foundations:
471-page PDF Draft: http://
arxiv.org/abs/2106.10165
or
Buy new edition: http://
amzn.to/3qoqmS5
—
#DataScience #AI #MachineLearning #NeuralNetworks #LinearAlgebra #Algorithms #Mathematics #Calculus #DataScientist -
Peter joins OpenAI: Strategic competition between OpenAI and Anthropic intensifies
By
–
这次 Peter 加入 OpenAI,热闹之外,几个值得思考的点: 1. 从最开始的 Clawdbot 到 Moltbot 再到 OpenClaw,名字就可以看出来,Peter 开始是 A 社模型的粉丝 ,到现在去 OpenAI 背后的思考。 2. OpenAI 和 A 社之间,现在不只是模型在打,社媒、关注度、开源也在打。可以理解为,OpenAI
-
Open Weights Models Struggle on Logic Reasoning Benchmark
By
–
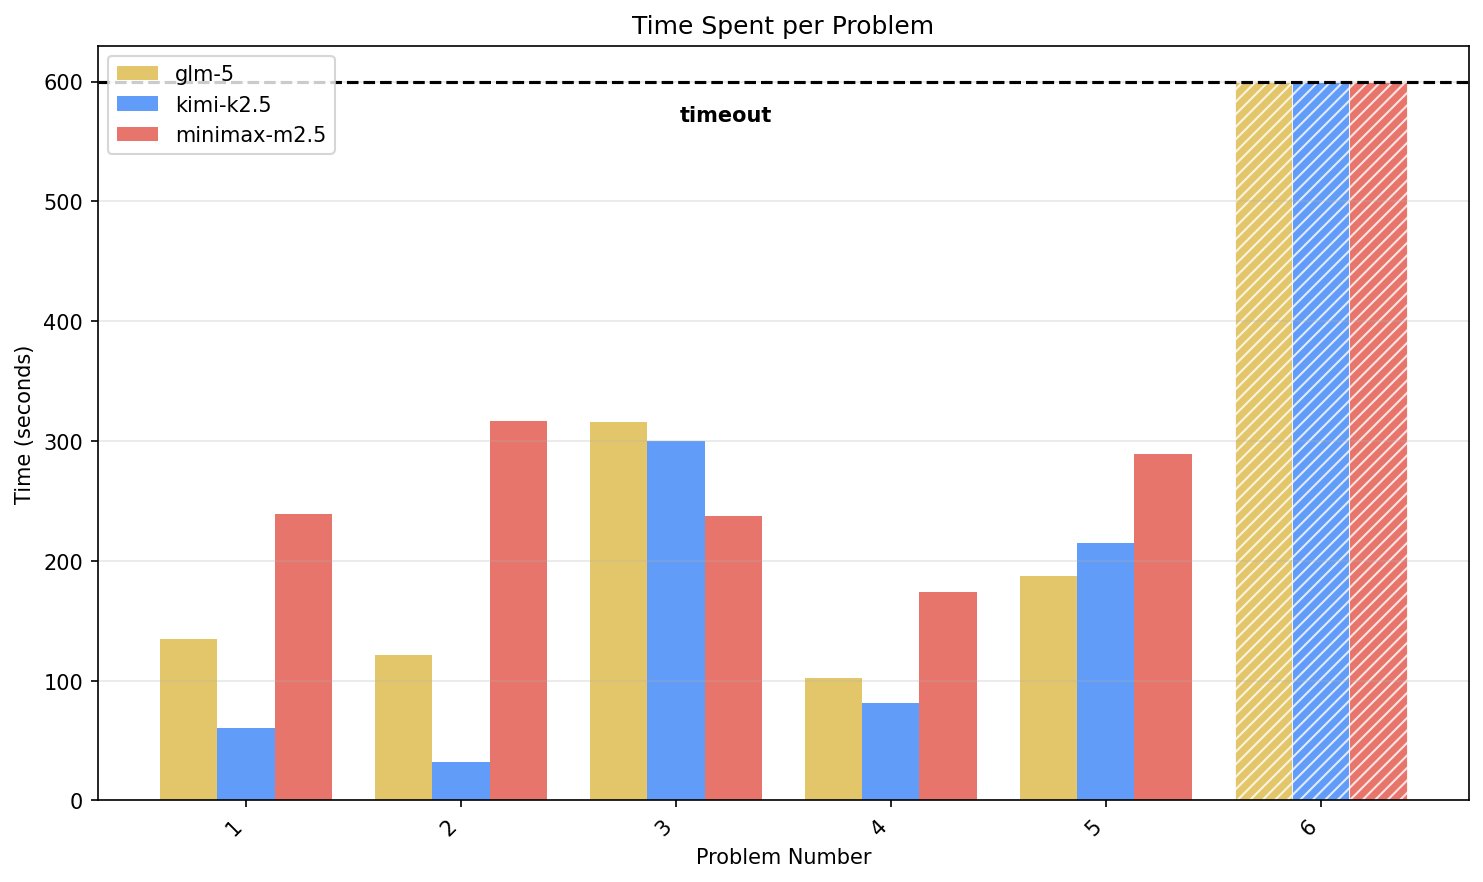
@nrehiew_ Hey, just made a logic reasoning / problem solving benchmark where open weights models get completely lost, but the frontier models make it look easy. Curious about your hypothesis why, thinking it's sparsity related:
-
Open Models Overfitting Benchmarks While Losing Reasoning Ability
By
–
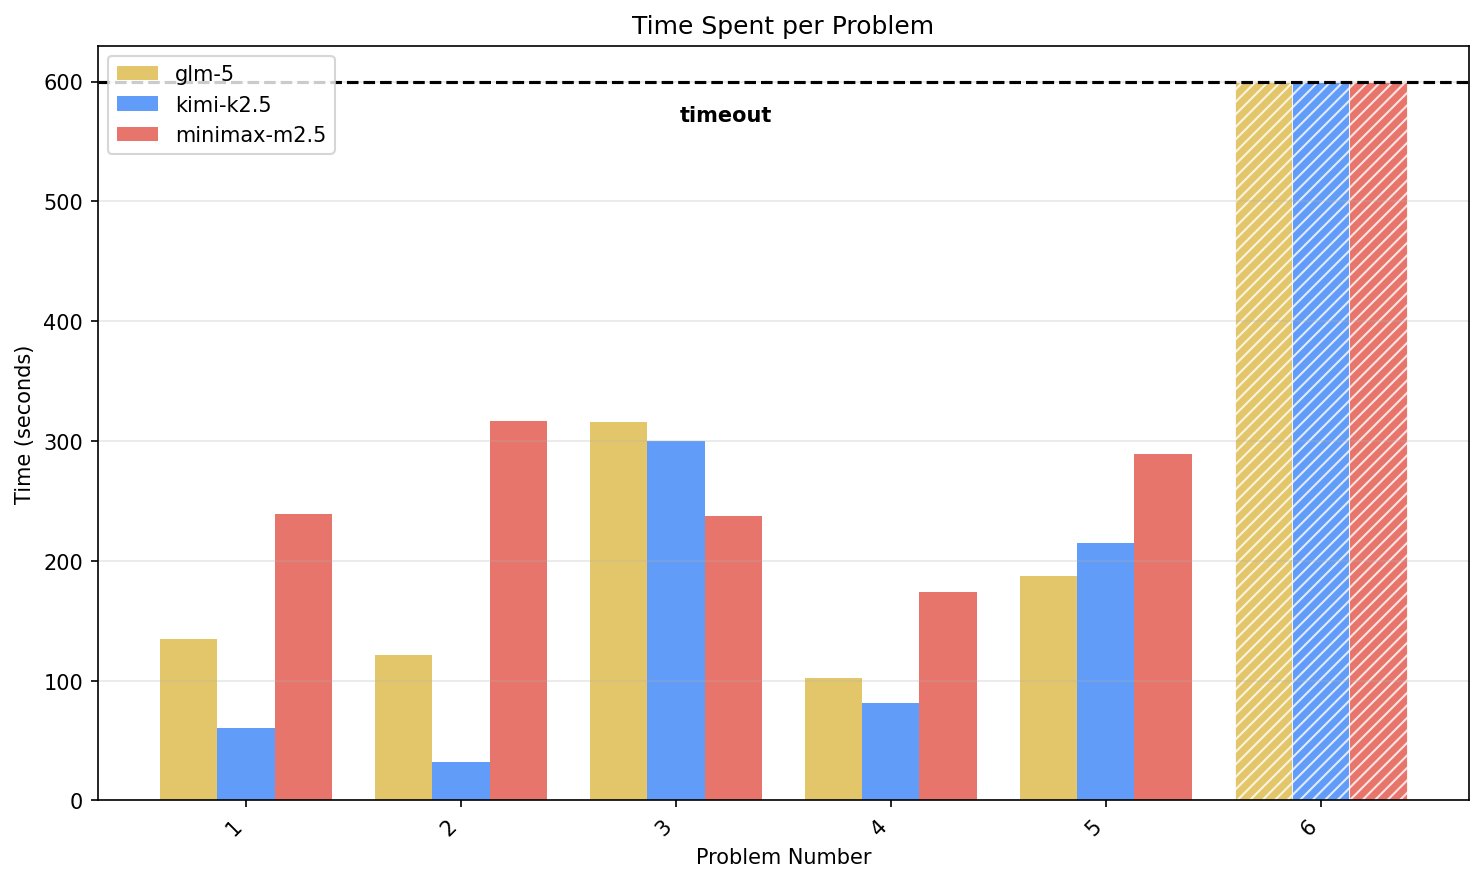
@xeophon On the topic of swe-rebench and lower scores, another data point for you: my own analysis suggests open models are overfitting to popular patterns/benchmarks while failing to get better at logical reasoning / problem solving:
-
Logic Reasoning Benchmark: Frontier vs Open Weight Models
By
–
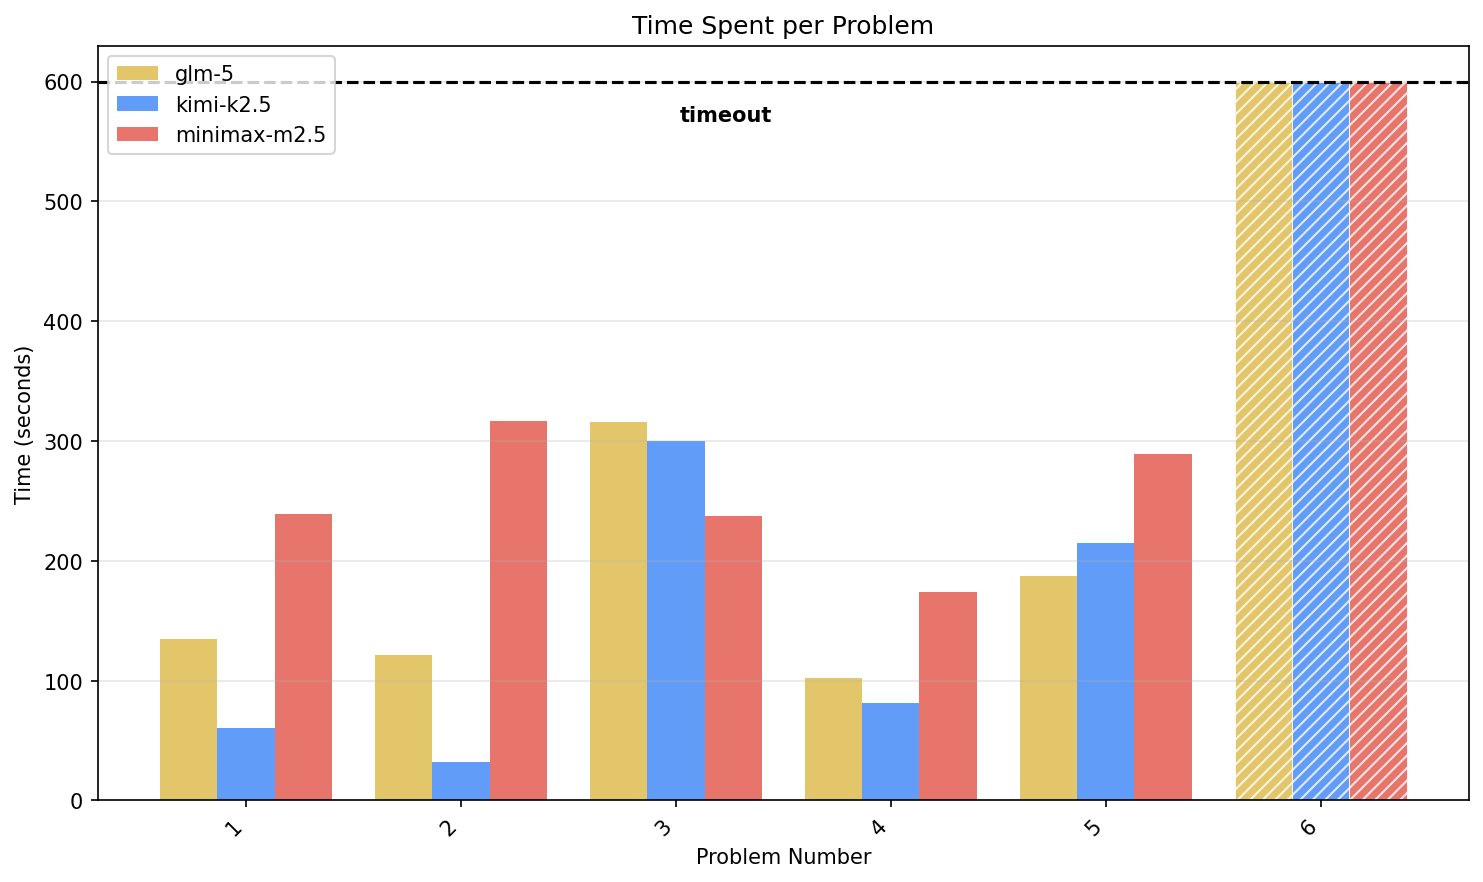
@scaling01 Before your pivot to Star Wars memes, I remember you used to be interested in LLMs! I just built a logic reasoning / problem solving benchmark where frontier models one-shot solutions, but the open weights models really struggle:
-
Moonshot’s Ultra-Sparse Approach Struggles With Logical Reasoning
By
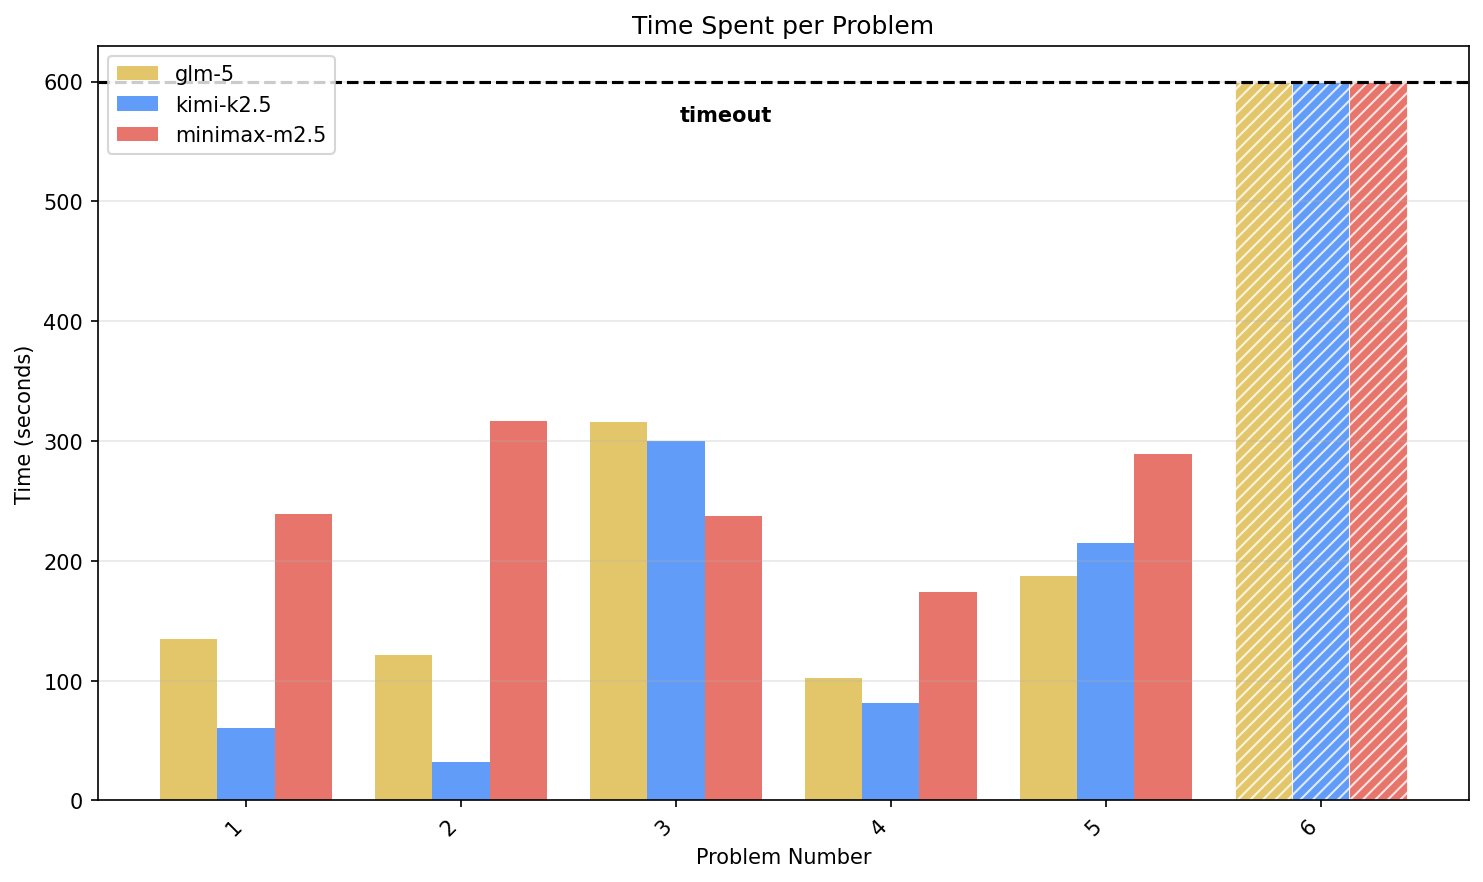
–
@zephyr_z9 On the topic of Moonshot affording compute, there's a risk… I think the ultra-sparse approach is failing to handle logical reasoning and problem solving like frontier models. Made a new benchmark digging deeper: