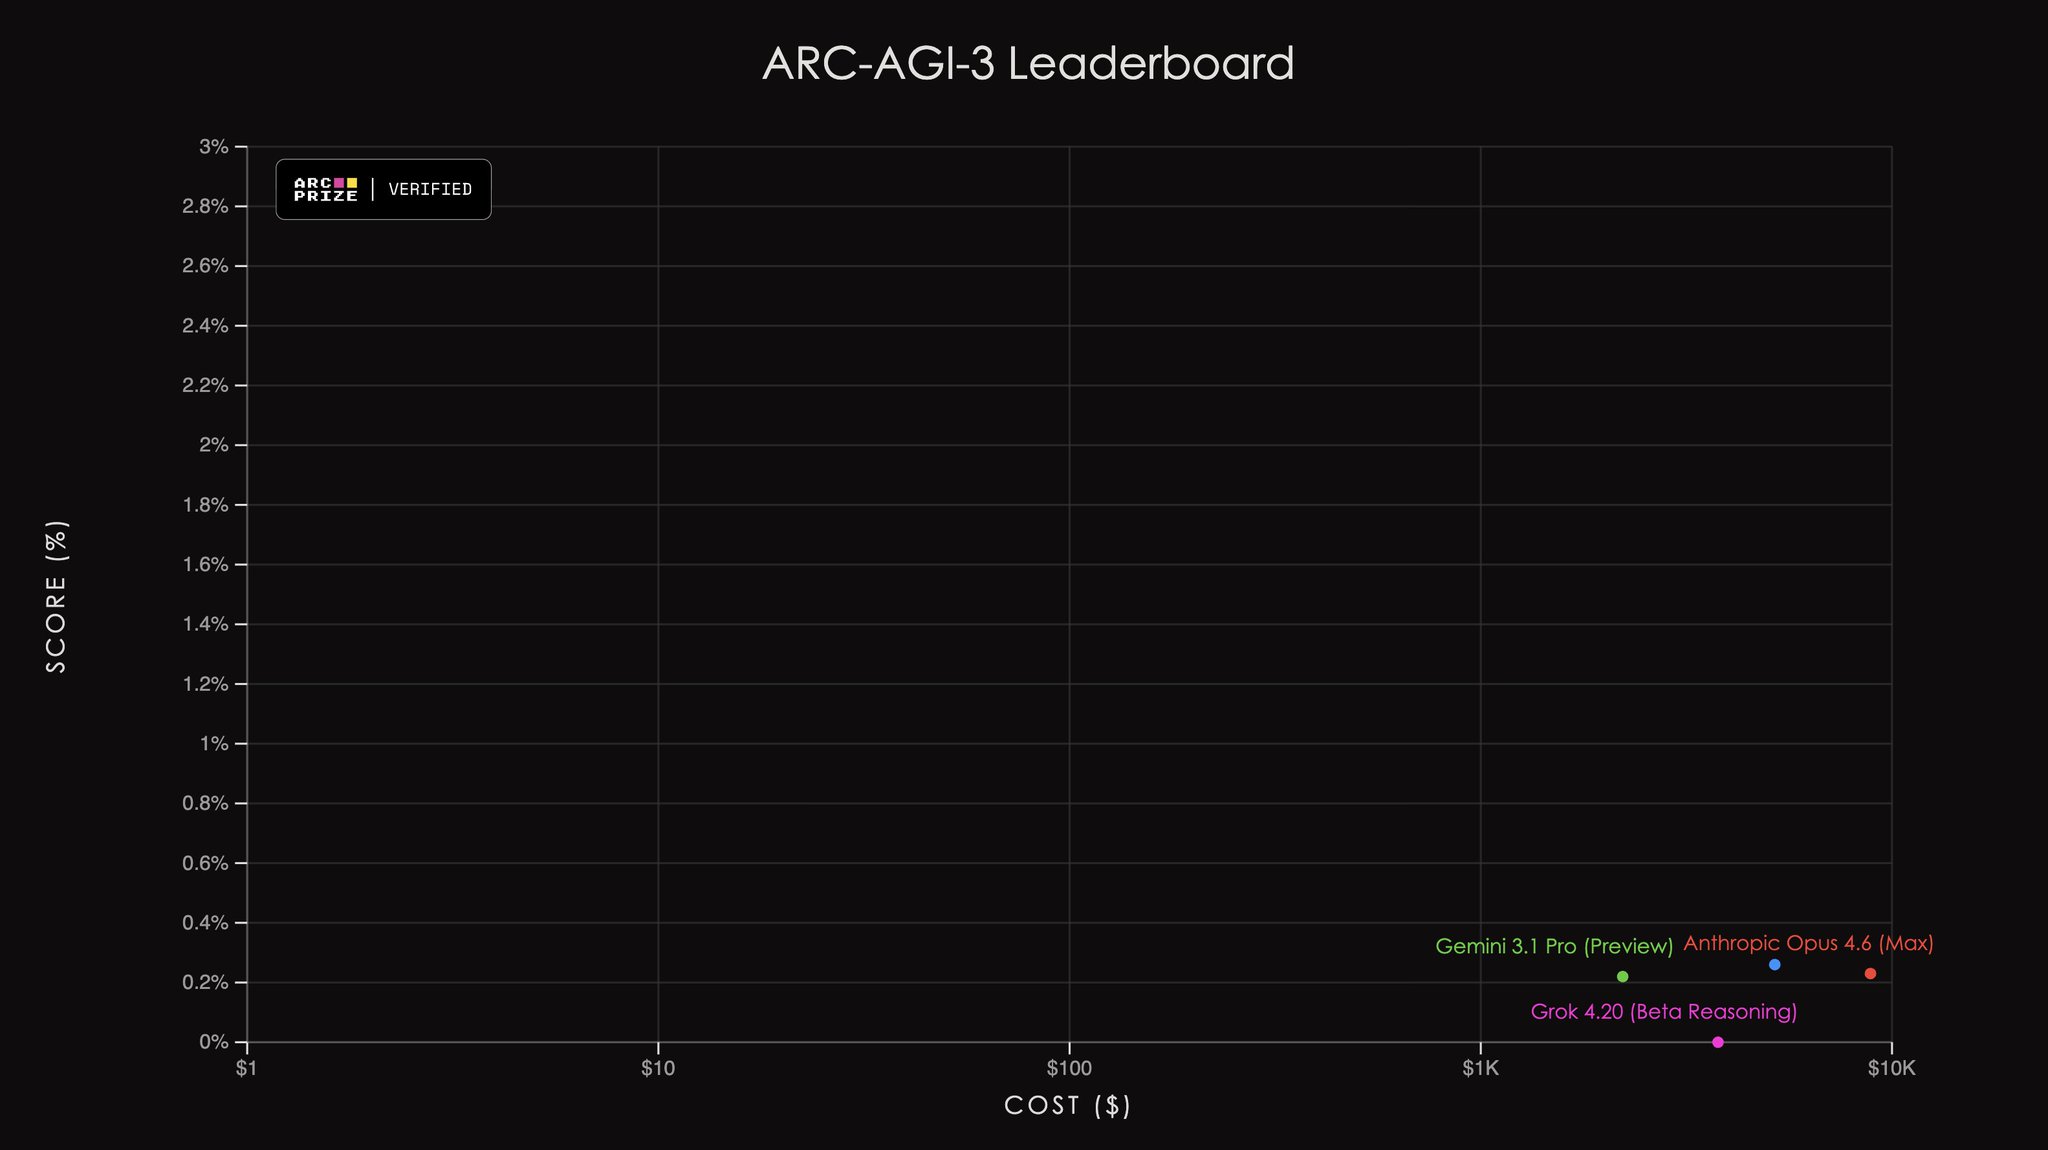
Desde hoy queda abierta la competición para que cualquiera pueda presentar sus soluciones entrenadas específicamente para resolver el reto, y al mismo tiempo para medir las capacidades generales de los LLMs que vayan saliendo este año Los humanos resuelven el 100%, la IA >1%…
RESEARCH
-
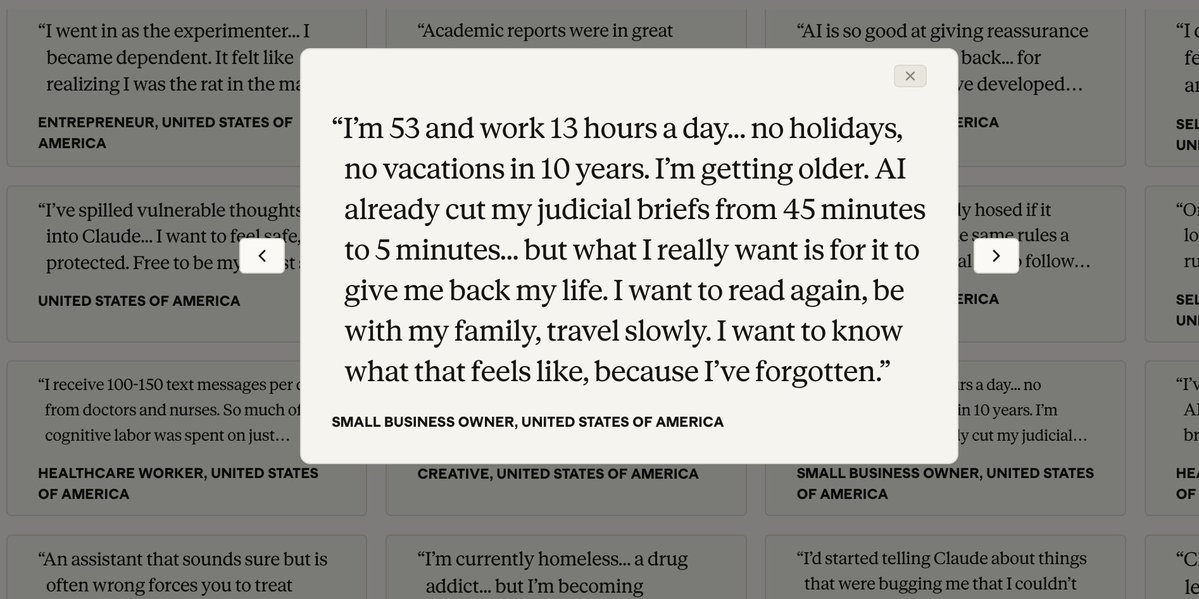
Anthropic Survey Quote Shared in AI Agent Workshop
By
–
This was the quote I shared in my AI Agent Workshop today. One of the 81,000 people surveyed in the recent @Anthropic. Hits you hard.
→ View original post on X — @alliekmiller, 2026-03-25 17:55 UTC
-
ARC-AGI 3 Launches with Agentic Temporal Dimension
By
–
🔴 ¡SE LANZA ARC-AGI 3!
— Carlos Santana (@DotCSV) 25 mars 2026
El famoso benchmark que busca medir las capacidades de aprendizaje y adaptación de la IA llega a su 3ª edición, tras haberse saturado ARC-AGI 2 en cuestión de un año… 😅
Esta nueva edición es agéntica al incorporar los puzzles una dimensión temporal 👇 pic.twitter.com/4O9dzbQvC3ARC-AGI 3 IS LAUNCHED! The famous benchmark that seeks to measure the learning and adaptation capabilities of AI reaches its 3rd edition, after ARC-AGI 2 became saturated in just one year… This new edition is agentic by incorporating a temporal dimension into the
-
Frontier Models Achieve Below 1% on Arc AGI 3
By
–
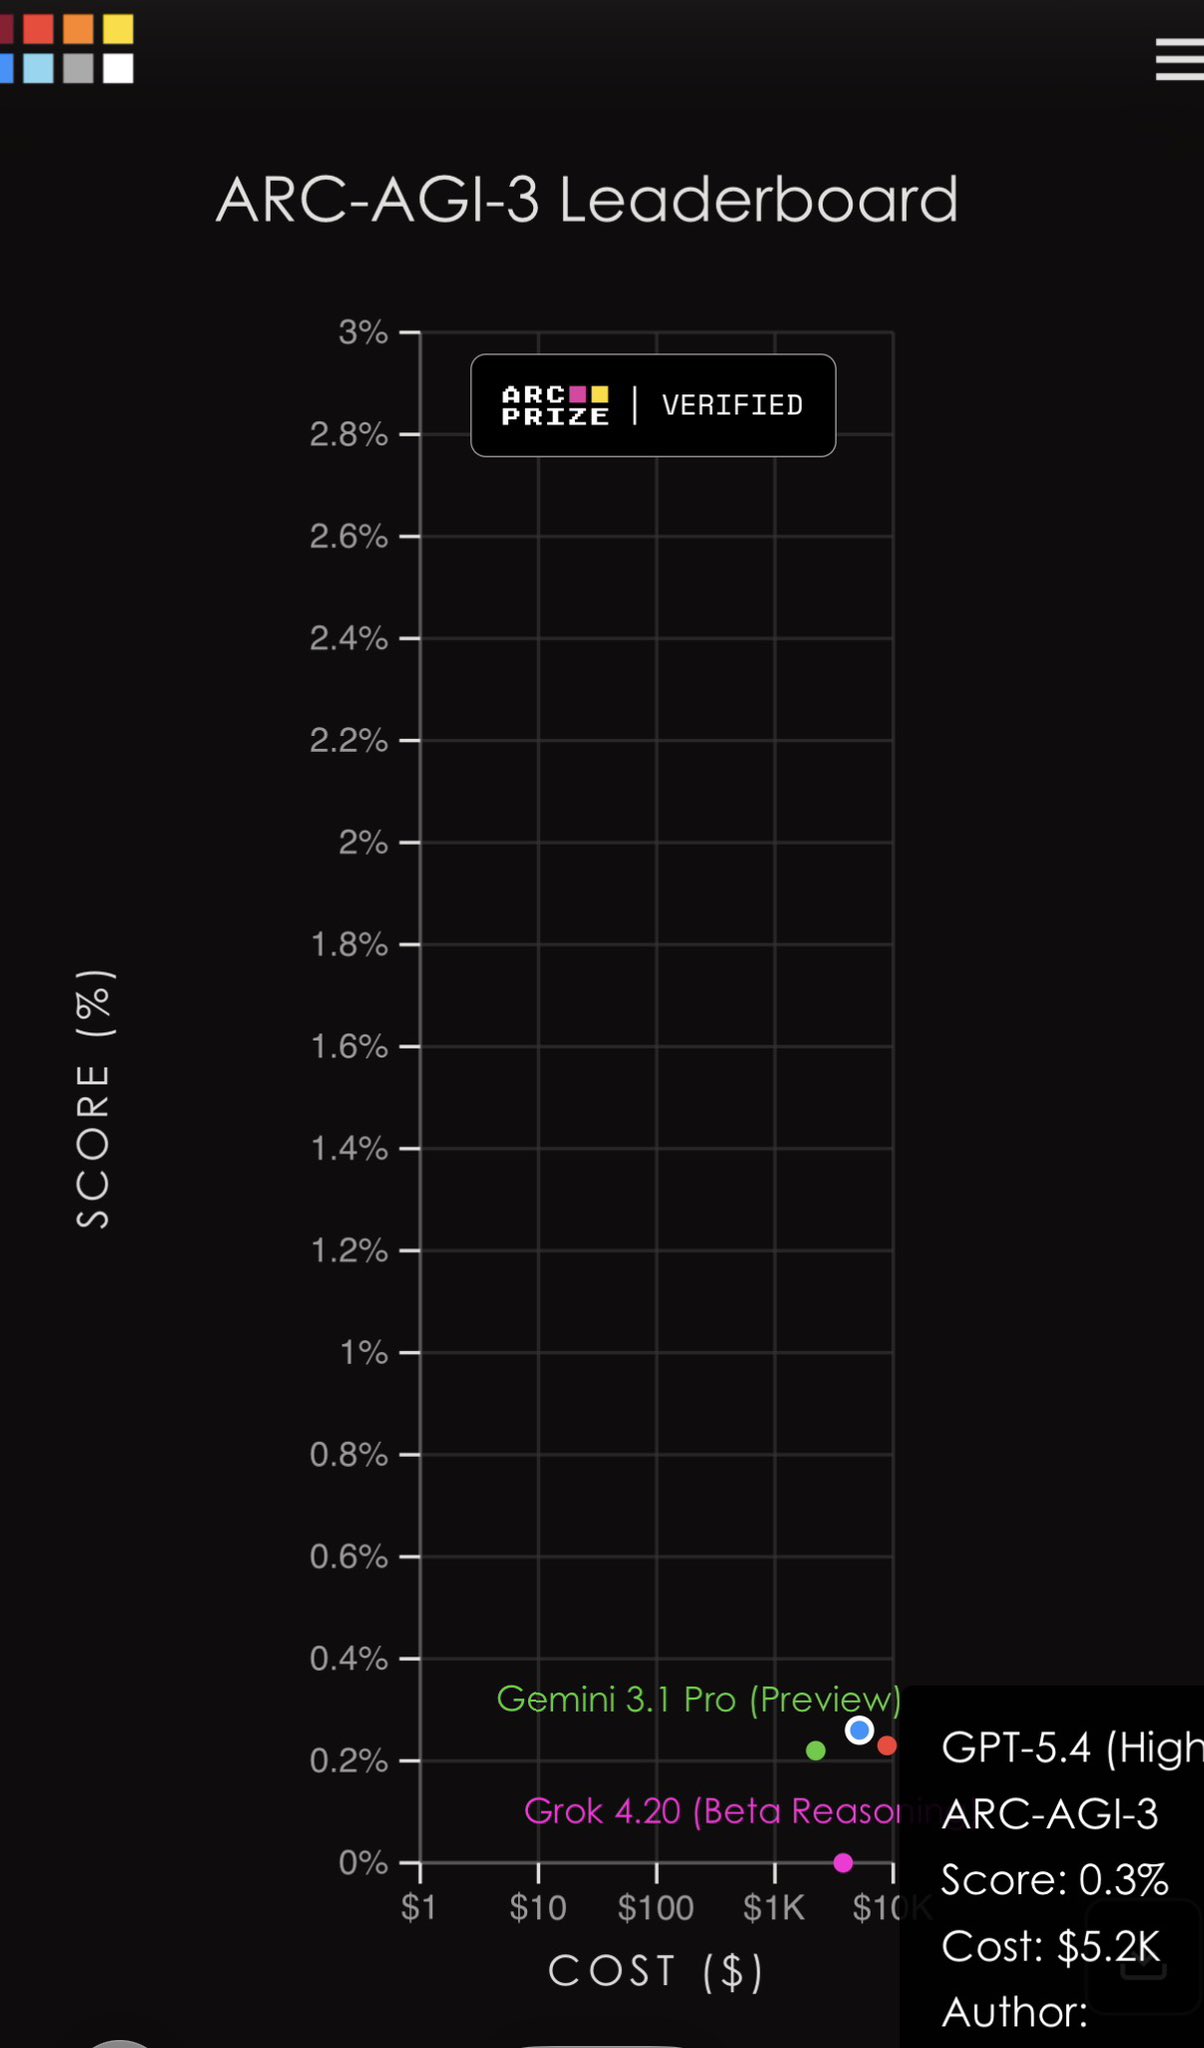
Back to work friends. Frontier models
Achieve below 1% on Arc agi 3. Let’s see if this will be saturated by end of year. -
ARC-AGI-3 Benchmark Monitors Frontier Models AGI Breakthrough
By
–
At the moment, ARC-AGI-3 is the only unsaturated agentic AI benchmark. Sub-1% scores from frontier models on the private test set.
— François Chollet (@fchollet) 25 mars 2026
If you want to be among the first to know when an AGI breakthrough happens, monitor the ARC-AGI-3 leaderboard. Any sudden score jump will mean… https://t.co/EenOUgpNnwAt the moment, ARC-AGI-3 is the only unsaturated agentic AI benchmark. Sub-1% scores from frontier models on the private test set. If you want to be among the first to know when an AGI breakthrough happens, monitor the ARC-AGI-3 leaderboard. Any sudden score jump will mean
-
ARC-AGI-2 Kaggle Competition Final Round With Unlimited Prize
By
–
We're also running one last ARC-AGI-2 competition on Kaggle this year. Get your high score in: since this is the last official ARC-AGI-2 competition, the grand prize will go to the top score regardless of whether it's above the 85% threshold.
-
ARC-AGI-3 Benchmark Evaluates Agentic Intelligence Systems
By
–
ARC-AGI-3 is out now! We've designed the benchmark to evaluate agentic intelligence via interactive reasoning environments. Beating ARC-AGI-3 will be achieved when an AI system matches or exceeds human-level action efficiency on all environments, upon seeing them for the first… pic.twitter.com/zHLOS1ncr7
— François Chollet (@fchollet) 25 mars 2026ARC-AGI-3 is out now! We've designed the benchmark to evaluate agentic intelligence via interactive reasoning environments. Beating ARC-AGI-3 will be achieved when an AI system matches or exceeds human-level action efficiency on all environments, upon seeing them for the first
-
ARC-AGI-3: New Benchmark Shows AI Lacks True Learning Ability
By
–
Announcing ARC-AGI-3 The only unsaturated agentic intelligence benchmark in the world Humans score 100%, AI <1% This human-AI gap demonstrates we do not yet have AGI Most benchmarks test what models already know, ARC-AGI-3 tests how they learn
-
The AI Scientist Published in Nature: Automated Scientific Discovery Milestone
By
–
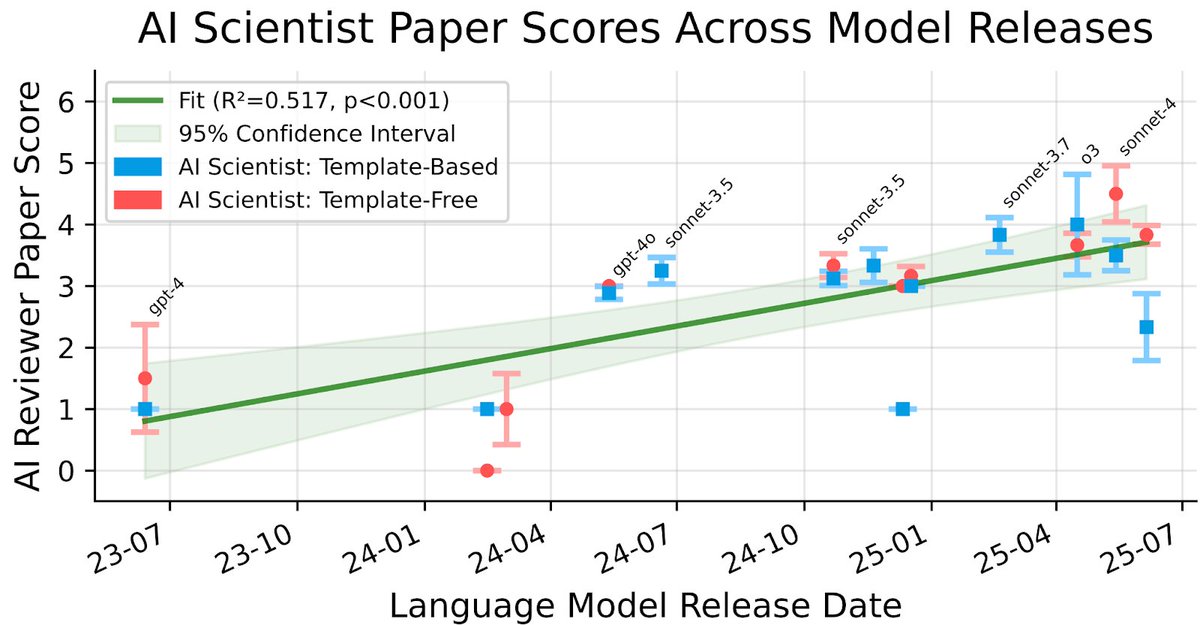
I am really excited to share that our work on The AI Scientist has been published in Nature Automated Scientific Discovery has been something I only dreamt about at the start of my PhD. Today, we are making big leaps into a world in which autonomous agents support human researchers in tackling some of the most fundamental problems. In August 2024, The AI Scientist-v1 showed first sparks of LLM agents becoming capable of conducting research end-to-end. While the generated artifacts were still far from perfect, it was clear that automated discovery was about to change. We scaled the system and improved all ingredients of the pipeline. In April 2025, The AI Scientist-v2 had become capable of producing a paper that could pass the human peer review of an ICLR workshop. This is only the beginning. Systems like AlphaEvolve, ShinkaEvolve, AIDE, and Autoresearch will continue to shape the future of how research is conducted. Our METR-style scaling results indicate that model improvements have direct downstream impacts. Still, there are many challenges. Both technical and societal. I have a strong belief that we, as a collective, will find the answers and adapt. This has been an enormous amount of work by an outstanding set of human researchers @_chris_lu_ @cong_ml @_yutaroyamada @shengranhu @j_foerst @jeffclune @hardmaru @SakanaAILabs with many long nights of work. I am super grateful for the entire ride, learnings and the future to come. Thank you to everyone! Sakana AI (@SakanaAILabs) The AI Scientist: Towards Fully Automated AI Research, Now Published in Nature Nature: nature.com/articles/s41586-0… Blog: sakana.ai/ai-scientist-natur… When we first introduced The AI Scientist, we shared an ambitious vision of an agent powered by foundation models capable of executing the entire machine learning research lifecycle. From inventing ideas and writing code to executing experiments and drafting the manuscript, the system demonstrated that end-to-end automation of the scientific process is possible. Soon after, we shared a historic update: the improved AI Scientist-v2 produced the first fully AI-generated paper to pass a rigorous human peer-review process. Today, we are happy to announce that “The AI Scientist: Towards Fully Automated AI Research,” our paper describing all of this work, along with fresh new insights, has been published in @Nature! This Nature publication consolidates these milestones and details the underlying foundation model orchestration. It also introduces our Automated Reviewer, which matches human review judgments and actually exceeds standard inter-human agreement. Crucially, by using this reviewer to grade papers generated by different foundation models, we discovered a clear scaling law of science. As the underlying foundation models improve, the quality of the generated scientific papers increases correspondingly. This implies that as compute costs decrease and model capabilities continue to exponentially increase, future versions of The AI Scientist will be substantially more capable. Building upon our previous open-source releases (github.com/SakanaAI/AI-Scien…), this open-access Nature publication comprehensively details our system's architecture, outlines several new scaling results, and discusses the promise and challenges of AI-generated science. This substantial milestone is the result of a close and fruitful collaboration between researchers at Sakana AI, the University of British Columbia (UBC) and the Vector Institute, and the University of Oxford. Congrats to the team! @_chris_lu_ @cong_ml @RobertTLange @_yutaroyamada @shengranhu @j_foerst @hardmaru @jeffclune — https://nitter.net/SakanaAILabs/status/2036840833690071450#m
→ View original post on X — @_yutaroyamada, 2026-03-25 17:31 UTC
-
Vine-Inspired Robot Gently Lifts Almost Anything
By
–
This Vine-Inspired #Robot Can Gently Lift Almost Anything
— Ronald van Loon (@Ronald_vanLoon) 25 mars 2026
by @MIT
#Robotics #Engineering #ArtificialIntelligence #Innovation #Technology pic.twitter.com/lfKLB58nJBThis Vine-Inspired #Robot Can Gently Lift Almost Anything
by @MIT #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology