patsnap.com/resources/blog/articles/neuromorphic-computing-chip-patents-surge-401-in-2025/ [Translated from EN to English]
→ View original post on X — @kimmonismus, 2026-04-05 15:33 UTC
By
–
patsnap.com/resources/blog/articles/neuromorphic-computing-chip-patents-surge-401-in-2025/ [Translated from EN to English]
→ View original post on X — @kimmonismus, 2026-04-05 15:33 UTC

By
–
"Neuromorphic computing has crossed from academic prototype to commercial product, with 596 patents filed through early 2026 and a 401% surge in activity in 2025 alone." I love it. [Translated from EN to English]
→ View original post on X — @kimmonismus, 2026-04-05 15:33 UTC

By
–
always wanted to do one of those “is it coachella” announcements – here is our designer’s take on it! AI Engineer (@aiDotEngineer) 🇬🇧 London is the birthplace of @GoogleDeepMind, and we're so honored to have them back as: Presenting Sponsors of this week's AIE Europe! DeepMind has pushed the AI frontier on every modality — from Gemini 3.1, to Embeddings 2, to Veo 3, to @NanoBanana Pro, and last far from least Gemma 4, byte for byte the most capable multimodal models in the world! Meet the team to catch up on everything GDM has shipped for AI Engineers in the past few months – from our keynoters Dr @RaiaHadsell (VP of Research and UK AI Ambassador) and @osanseviero (Lead AI DX), to returning speakers @DynamicWebPaige and @thorwebdev and @_philschmid, to researchers and engineers working on those exact products @sedielem, @tara_ojo, @FMuntenescu and more! — https://nitter.net/aiDotEngineer/status/2040806678849884422#m
By
–
Agreed on the adversarial concern, but the economics here enable production-scale testing which is where real adversarial validation happens

By
–

So GPT-5.5 "Spud" is coming. OpenAI finished pretraining around March 24. Altman called it "a very strong model that could really accelerate the economy" and Brockman said there are two years of research inside it. From what we're hearing, Spud is not just another update. It's supposedly a completely new base model with native multimodality, stronger agentic capabilities, and better understanding of what users actually want without having to over-explain. They even shut down Sora to put everything into this. Also worth noting that Q2 2026 is looking insane. Claude Mythos, DeepSeek V4, Grok 5 are all expected around the same time. This is going to be the most competitive quarter in AI history. Of course, take all of this with a grain of salt. Most of it is still unverified leaks and rumors. But here's my honest thought. GPT-5.5 is clearly one of the most anticipated models this year and this feels like a make-or-break moment for OpenAI. Whether Spud succeeds or not, I really hope they reconsider how they treat their models and find a way to replace or soften their approach to CoT monitoring. What made 4o special wasn't just performance. It was the way it felt human.
→ View original post on X — @montreal_ai, 2026-04-05 15:04 UTC
By
–
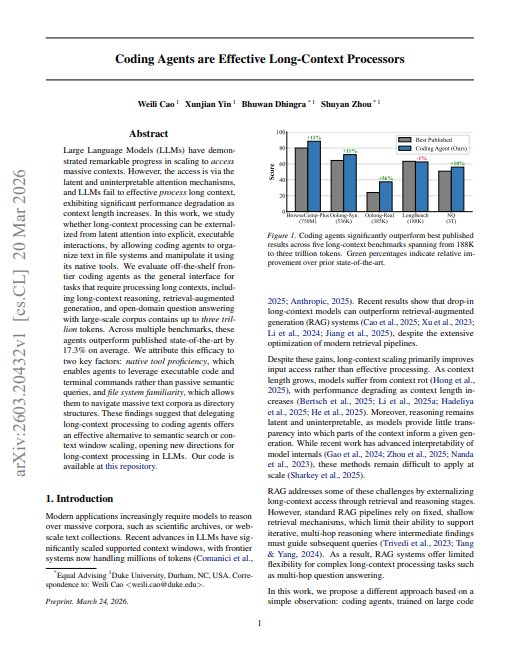
BREAKING: Duke researchers just proved that coding agents are better at processing long documents than models with million-token context windows. > Not because of longer context. Because grep and sed are better retrieval tools than attention. > +17.3% average improvement

By
–
ETS: Energy-Guided Test-Time Scaling for Training-Free RL Alignment Li et al.: arxiv.org/abs/2601.21484 #AIAgents #ReinforcementLearning [Translated from EN to English]
→ View original post on X — @ceobillionaire, 2026-04-05 14:56 UTC
By
–
quotes? what do you mean by back then? eg 2023 in the Senate? 2024 in my book taming silicon valley? 2022 in my essay on AI’s jurassic park? 2019 my book rebooting AI? i have been warning about the dangers (though not extinction) for years. no idea what you are talking about

By
–
What if Diffusion LLMs learned logic more efficiently? Huawei's Noah's Ark Lab proposes a breakthrough: their "smart noise scheduler" uses priority masking to focus training on only information-dense data, making DLLMs master core reasoning and structure. This boosts average accuracy by 4% on Code & Math reasoning, beating uniform baselines and unlocking DLLM potential. Mask Is What DLLM Needs: A Masked Data Training Paradigm for Diffusion LLMs Paper: arxiv.org/abs/2603.15803 Dataset: huggingface.co/datasets/malr… Our report: mp.weixin.qq.com/s/1yTd36hev… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-05 14:05 UTC