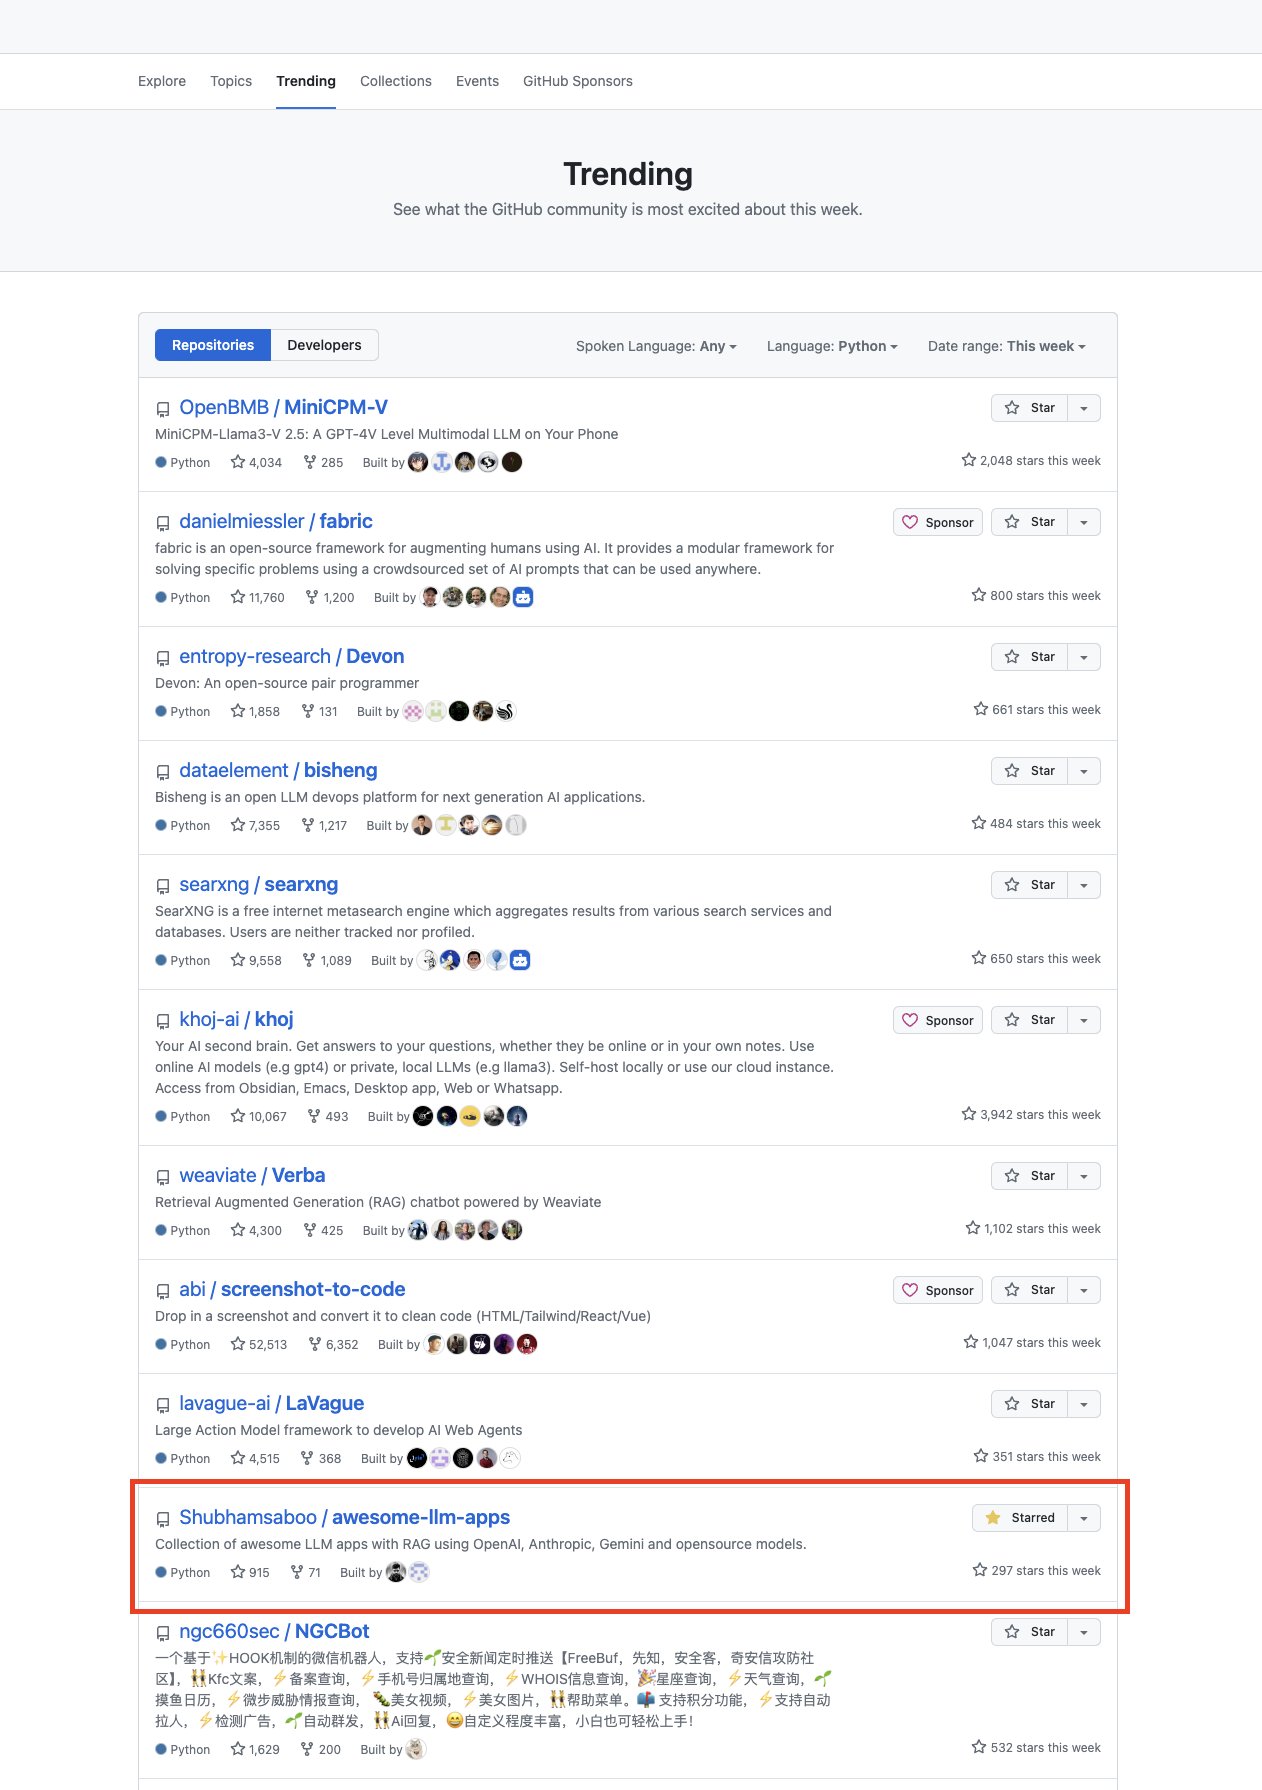
Opensource is amazing. Awesome LLM Apps repo made it to the top trending GitHub repositories across the globe in just a few weeks of its launch. This is one of my biggest dream come true! Thank you awesome community for the support & keep it coming. If you don't know about the
OPEN SOURCE
-

Mistral Releases Codestral-22B: Outperforms LLaMA 3 70B
By
–
Mistral has released a code-specific model! Codestral-22B seems to outperform LLaMA 3 70B while being more than 3x smaller. Very impressive!
-
MusePose: Open Source AI Model for Pose Estimation
By
–
Esta es la web del proyecto donde están los modelos para poder ejecutarlo tú mismo https://
github.com/TMElyralab/Mus
ePose?tab=readme-ov-file
… -
LLaMa Reproducibility: Data Access Essential for Scientific Validation
By
–
Reproducing a benchmark is a minor managerial task. It's not even engineering. The scientific hypothesis of LLaMa models is: "If we overtrain the same model architecture on our data, it outperforms previous iteration." Without the data, LLaMa data the experiment is not repro.
-

AutoTrain Now Supports Sentence Transformers for Custom Embeddings
By
–
With sentence transformers support in AutoTrain, training your own custom embedding models is now as easy as:
-
LLM Interpretability and Refusal Mechanisms Research Acknowledgments
By
–
Special thanks to: – @failspy for his notebook and abliterated models
– Arditi et al. (cc @NeelNanda5
) for the excellent "Refusal in LLMs" blog post (
https://
lesswrong.com/posts/jGuXSZgv
6qfdhMCuJ/refusal-in-llms-is-mediated-by-a-single-direction
…)
– All the LLM mergers and fine-tuners for the source models
– Charles Goddard and @arcee_ai for MergeKit -
NeuralDaredevil-8B Model Improvement Through DPO Training
By
–
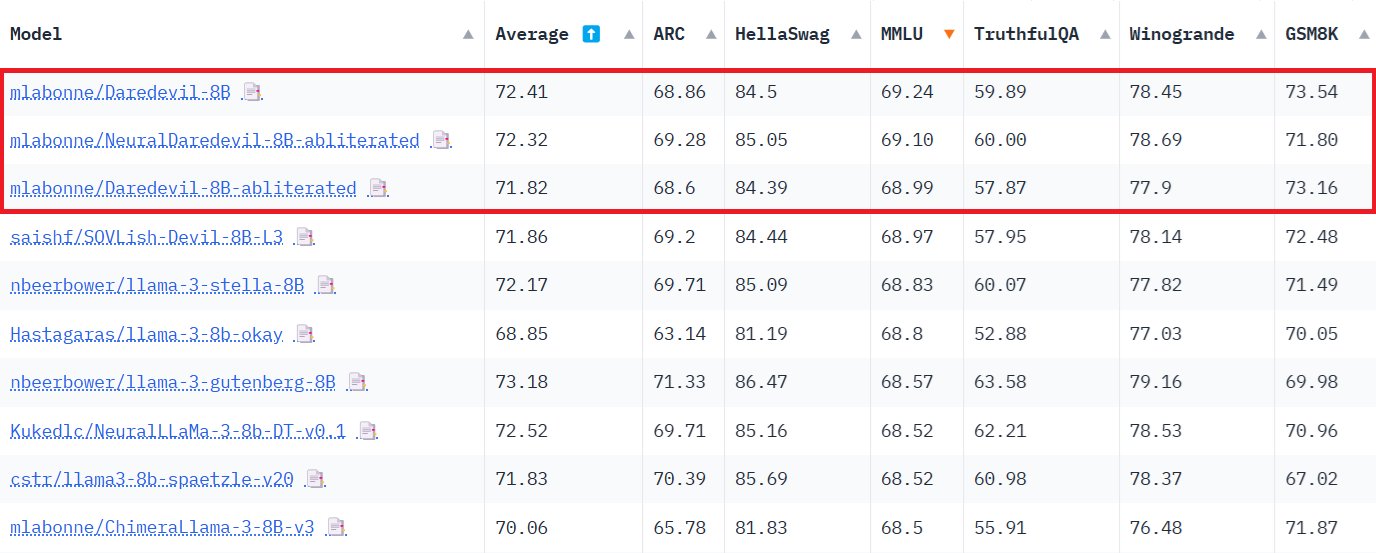
There's still room for improvement: GSM8K suffered because it's underrepresented in my DPO dataset. More epochs would definitely help too. I find it super exciting and I'm curious to see how people will use it. NeuralDaredevil-8B:
-

Removing Meta Alignment from Daredevil-8B Model
By
–
But Daredevil-8B is still censored. Many people asked me for uncensored models, so I wanted to try something. I used @failspy
's abliteration notebook to remove Meta's alignment. Unfortunately, abliteration also slightly degrades performance: 1-2% on every benchmark. -
DPO Fine-Tuning Fixes Instruct Model Performance Effectively
By
–
I healed it using DPO fine-tuning. Unlike SFT, it doesn't lobotomize the Instruct model. I trained it for one epoch of orpo-dpo-mix-40k with an lr of 5e-6 and a sequence length of 2048 using Axolotl. This successfully fixed the model as you can see on the benchmarks.
-

Daredevil-8B: Mega-Merge Model Using DARE TIES
By
–
Daredevil-8B is a mega-merge composed of 9 models using DARE TIES. Like the original Daredevil-7B, the model recipe was designed to maximize the MMLU score. The model family tree is already quite wild. Daredevil-8B: https://
huggingface.co/mlabonne/Dared
evil-8B
…