@avshalomm solved it by utilizing the fact that actually, there is no interaction between different tokens in the MoE block, so we can iterate over the long context in chunks. This was also merged and now fixed in vLLM
OPEN SOURCE
-
Jamba’s 256K Context Reveals fused_moe Kernel Issues
By
–
BTW, Since Jamba supports a 256K context with high throughput, we also stumbled upon an issue where the fused_moe kernel didn’t work well in long contexts. Others seems to have had this too, according to some other open issues
-
Jamba Model Now Supported in vLLM for Efficient Serving
By
–
Jamba support is now live on vLLM Due to its novel hybrid SSM-Transformer arch, Jamba didn’t work out-of-the-box in vLLM. our own @MorZusman worked together with @vllm_project to integrate Jamba for an efficient serving in vLLM
-
Jamba Modeling and Mamba Cache Management Updates
By
–
Things in this PR:
– Jamba modeling file, supporting Jamba variations
– Mamba cache management (also benefit other Mamba-based models)
– Send more request related properties to the forward pass, for model-specific implementations (including things needed for speculative decoding) -
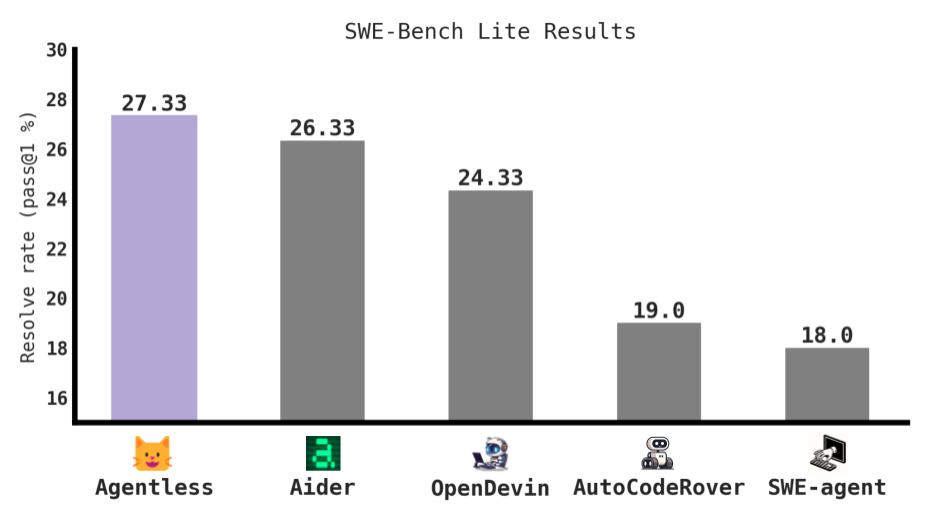
OpenAutoEncoder-Agentless Solves 27.3% GitHub Issues
By
–
6/ Agentless – introduces OpenAutoEncoder-Agentless which offers an agentless system that solves 27.3% GitHub issues on SWE-bench Lite; claims to outperform all other open-source AI-powered software engineering agents.
-
Mistral-based version reaches 747k monthly downloads
By
–
Meanwhile, the previous version based on Mistral gets 747k downloads/month and I have no idea why this is the case ¯_(ツ)_/¯
-

NeuralDaredevil Reaches 10k Monthly Downloads on Hugging Face
By
–
NeuralDaredevil reached 10k downloads/month and 100 likes on @huggingface Thanks everyone! It performs surprisingly well in many (unexpected) domains and languages, like math and Portuguese. It's also being re-evaluated on the Open LLM Leaderboard v2 due to an issue with IFEval
-
What is GPT4All? An Overview of the Open-Source AI Project
By
–
What is GPT4All? GPT4All developed by Nomic AI, has quickly become one of the fastest-growing repositories on GitHub, boasting over 250,000 monthly active users and 65,000 stars on the platform.
-

GPT4All Enables Private Local Chat with Open-Source LLMs
By
–
GPT4All is now a completely private experience that lets you chat with locally hosted versions of LLaMa, Mistral, Nous-Hermes, and more. Download here: https://
nomic.ai/gpt4all -

Fine-tune Llama 3 for Customer Support Automation
By
–
Looking for something to do this weekend? Learn how to fine-tune #llama3 to automate customer support! In this hands on #code tutorial, you'll learn how to take a small best-of-breed #opensource LLM and train it for your use case. https://
pbase.ai/3VT4bzN