1. The Kernel Concept
Think of a PRISM kernel as a compressed instruction set – like a mini-operating system for the AI. Instead of writing verbose prompts, you encode: The context (what mode to enter)
The constraints (what rules to follow)
The output format (how to structure
OPEN SOURCE
-
PRISM Kernel: Compressed AI Instruction Set
By
–
-

Grok-powered X algorithm update with open weights, removing vestigial rules
By
–

An updated X algorithm powered by Grok is expected to be released later this week with open model weights. “A lot of random vestigial rules are gone” Grok is taking over
-
Hugging Face addresses storage limits and open research grants
By
–
Hey hey – VB from HF here, what’s up? Yes, we put storage limits in place but these are much much higher than what the median user on the Hub uses. Besides, we’re actively making grants to ensure all open research is supported. The limits are put in place to help fight rampant
-
Measuring Dependency Complexity in uv.lock Files
By
–
I count and report the lines in uv.lock, which is my attempt at a simple 80:20 proxy for this, as it includes all the packages recursively. Open to suggestions! I'd love to measure things like "cognitive complexity" (there was a great blog post on it a few months back that I
-
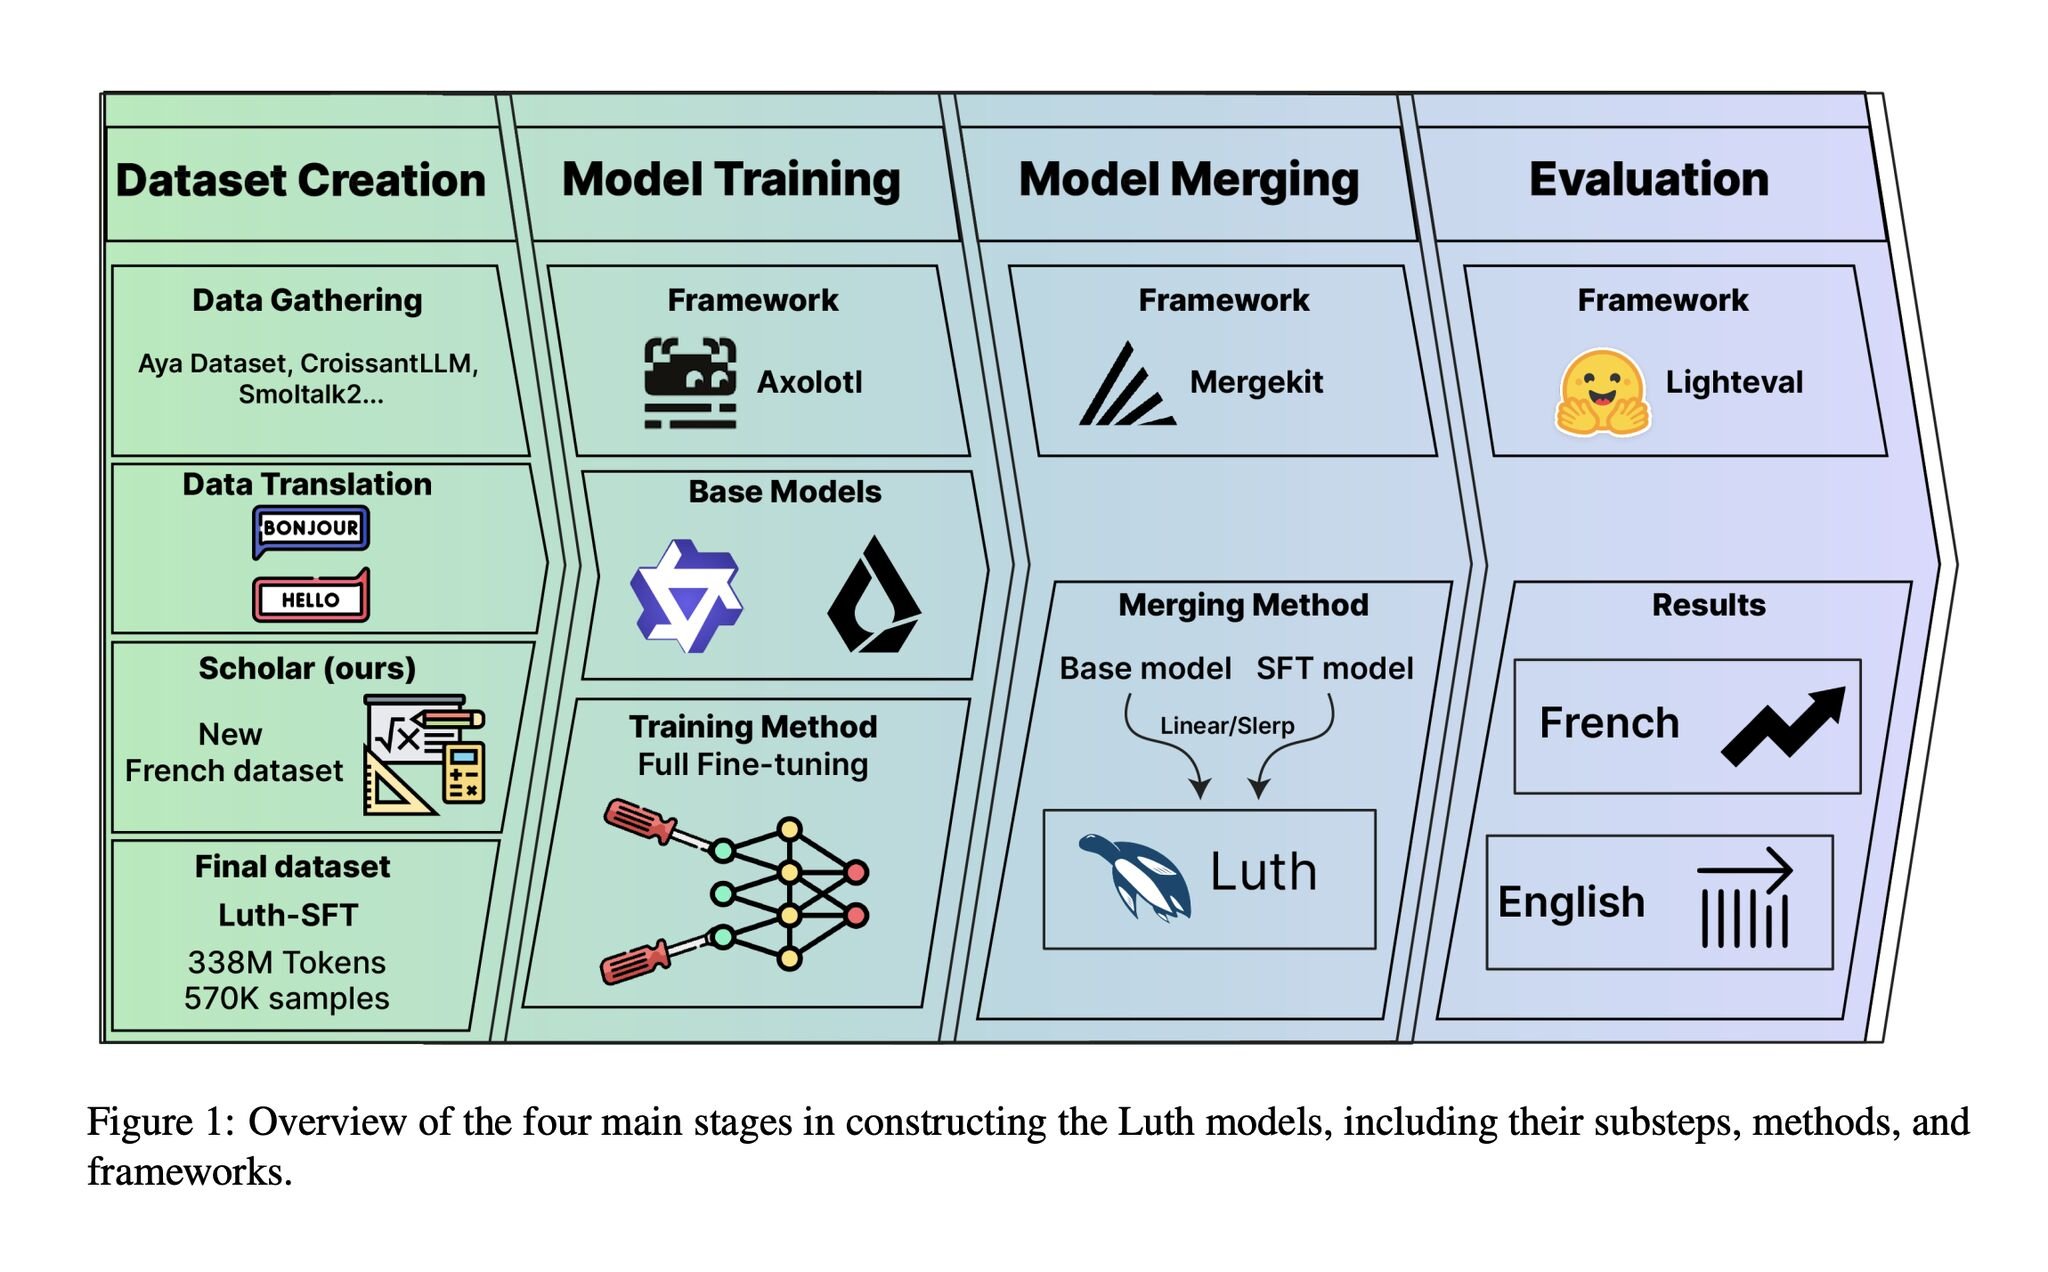
Fine-Tuning Small Language Models for French Specialization
By
–
Efficient Language Specialization for Small Language Models @maxencelsb and @SinoueG have released a preprint about their excellent work on fine-tuning small models in French. It shows a solid post-training pipeline to improve French performance while preserving English
-
Karpathy’s Nano Repo Brings Joy to X Timeline
By
–
When Karpathy drops a nano repo, X timeline is great again! Everyone is basically happy.
-
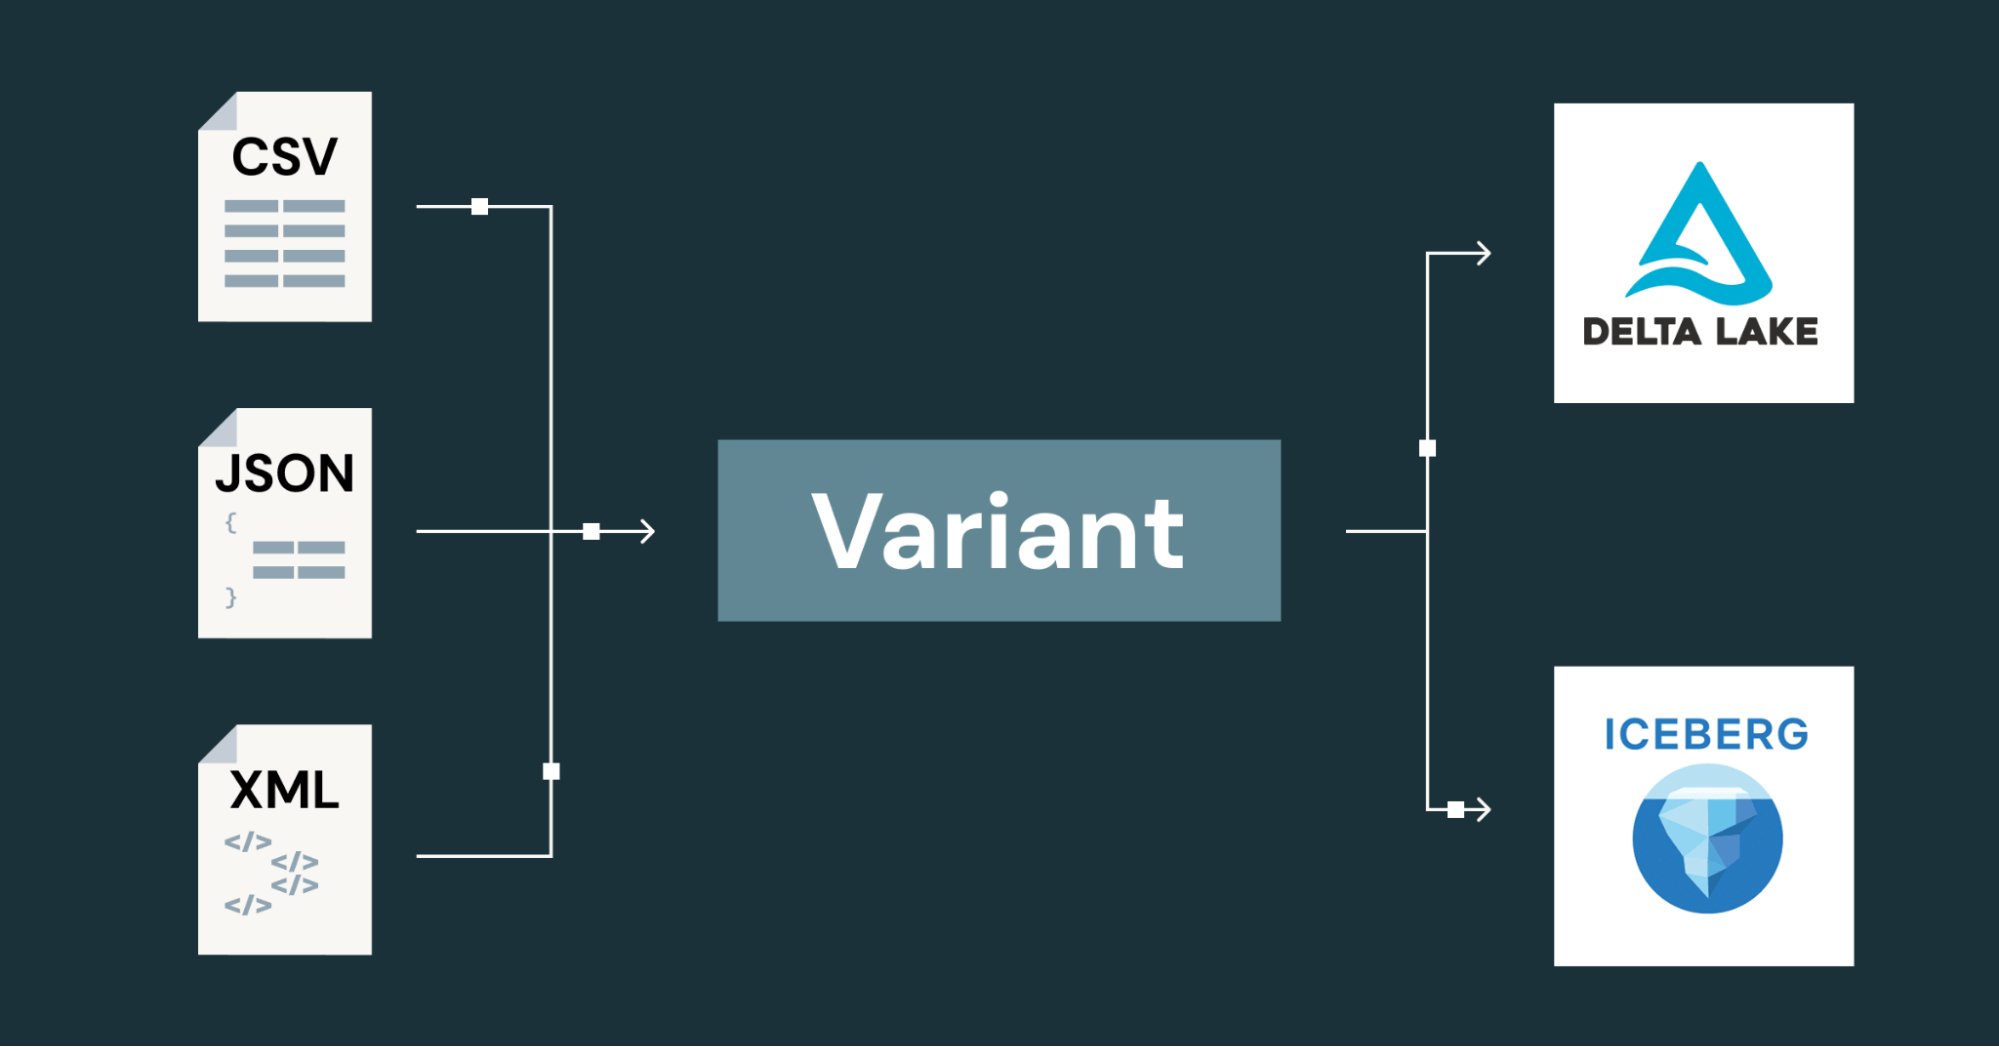
Variant Data Type Ratified in Apache Parquet Ecosystem
By
–
Exciting news for the open data community: Variant, the native data type for semi-structured data, is now ratified in the Apache Parquet™ community — with support across Delta Lake, Apache Iceberg™, and Apache Spark™. Variant brings a unified, open standard to how the
-
Hugging Face Datasets Critical Infrastructure for AI Model Training
By
–
Ty! huggingface work/infra/datasets are critical to projects like nanochat – to be accurate the source code of nanochat (e.g. at the $100 tier) is ~8KB of Python and ~30GB of fineweb/smoltalk.
-
Karpathy releases new LLM training project under 8000 lines
By
–
> karpathy just released a new project > in it, and in under 8000 lines of code you get to: > train the tokenizer using a new rust implementation
> pretrain a transformer llm on fineweb, evaluate core score across a number of metrics > midtrain on user-assistant -
Japanese LFM2 PII Extractor Released with 350M Parameters
By
–
New LFM2 release 🥳
— Maxime Labonne @ ICLR (@maximelabonne) 13 octobre 2025
It's a Japanese PII extractor with only 350M parameters.
It's extremely fast and on par with GPT-5 (!) in terms of quality.
Check it out, it's available today on @huggingface! pic.twitter.com/ojrU8SbG42New LFM2 release It's a Japanese PII extractor with only 350M parameters. It's extremely fast and on par with GPT-5 (!) in terms of quality. Check it out, it's available today on @huggingface
!