At #DrupalCon Vienna, project lead Dries Buytaert shared how #Drupal is evolving to thrive in the AI era. Turns out that architectural decisions made over a decade ago are delivering exactly what AI needs today. Check out the full keynote here:
OPEN SOURCE
-

GPT-OSS Moderation Models Available on Hugging Face
By
–

Both "gpt-oss-safeguard-120b" and "gpt-oss-safeguard-20b" are already available on @huggingface Internal moderation eval
-
OpenAI Releases GPT-OSS-Safeguard Open-Weight Model
By
–
GPT-OSS-Safeguard from @OpenAI is here. Open-weight, safety-tuned, transparent reasoning. Now available in private preview at Cerebras speeds https://
cerebras.ai/build-with-us -
Visualizing Llama 3.1 Tensor Operations Through GGML Debug Output
By
–
The three.js visualization parses the output of llama-cpp's ggml debug output (of unsloth llama 3.1) to directly obtain all the tensor calculations happening under the hood. Operations (MUL_MAT, ROPE, RESHAPE, ADD) are grouped into query, key, value, MLP, and residual stream
-
Groq Deploys GPT-OSS-Safeguard-20B Before OpenAI Release
By
–
OpenAI: releases GPT-OSS-Safeguard-20B.
Groq: already deployed.
Open, customizable, bring your own policy. -
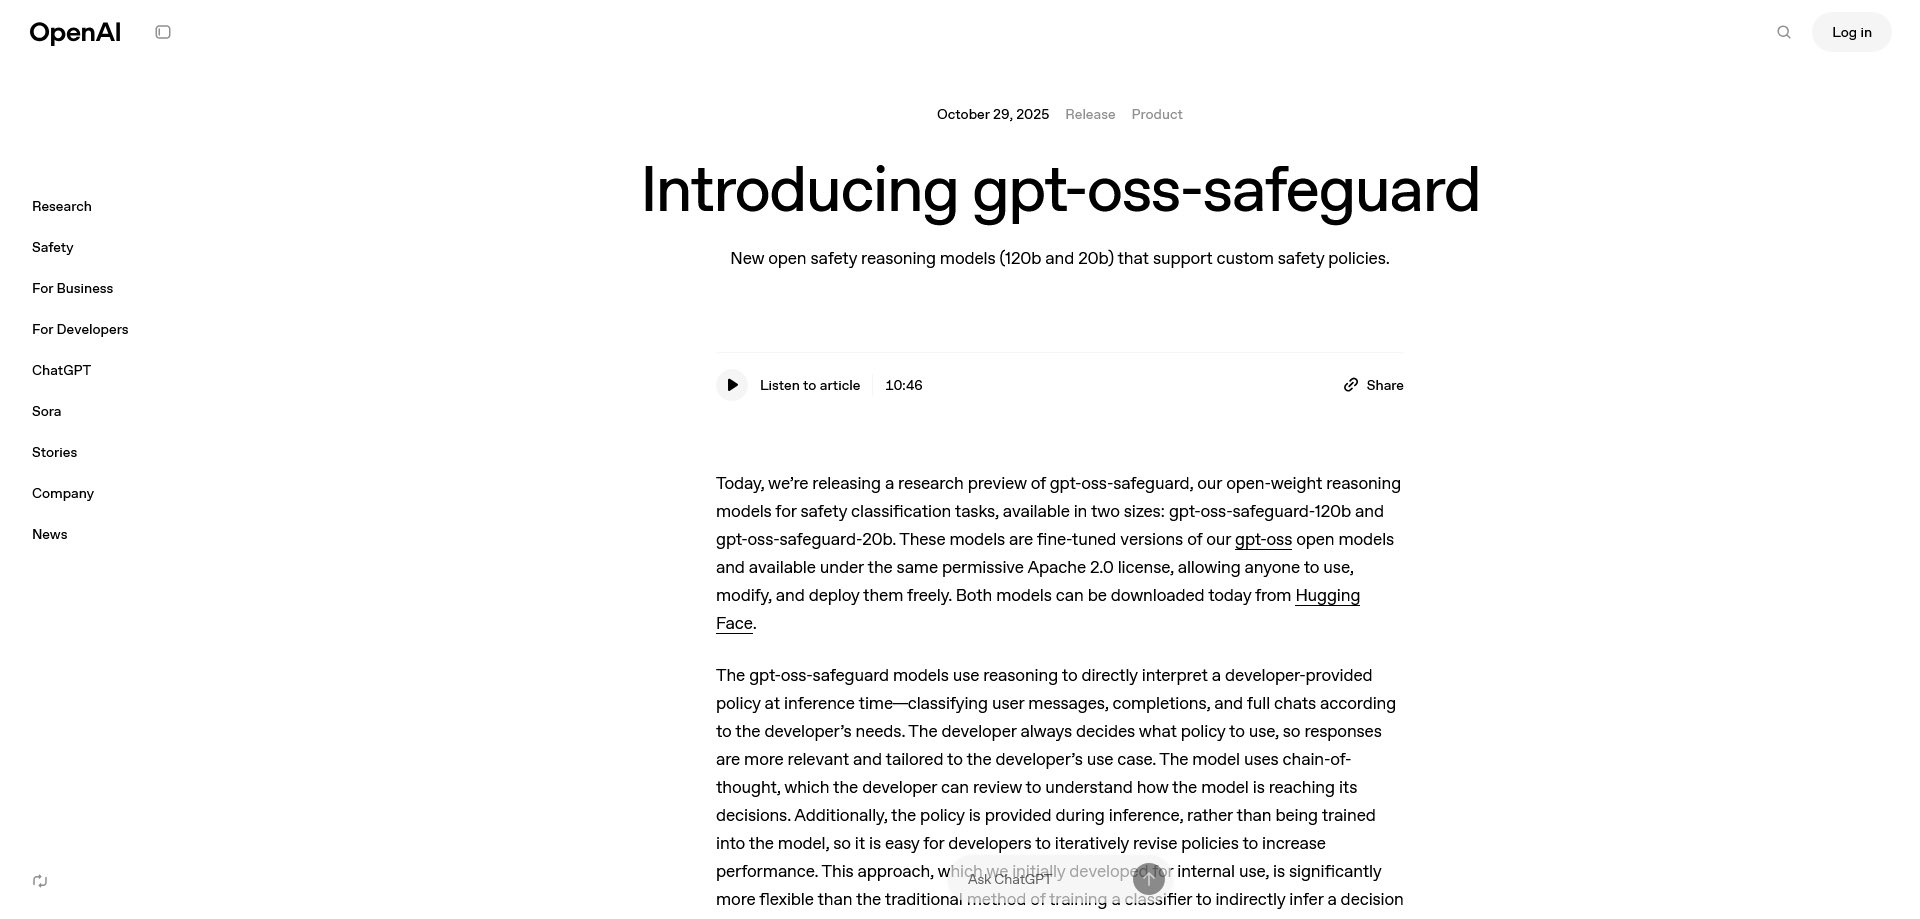
OpenAI prepares two new open source models with reasoning
By
–
OpenAI is planning to release 2 new fine-tuned open models, "gpt-oss-safeguard-120b" and "gpt-oss-safeguard-20b". The official blog post was taken down after publishing. These models will use reasoning to directly interpret a developer-provided policy at inference time.
-
DeepSeek-OCR OmniDocBench: Document Recognition Benchmark
By
–
Detailed report + code: https://
github.com/alphaXiv/DeepS
eek-OCR-OmniDocBench/blob/main/REPORT.md
… Datasets page: http://
alphaxiv.org/datasets/shang
hai-ai-laboratory/omnidocbench
… -
Which open-source model is criminally underrated?
By
–
Which open-source model is criminally underrated?
-
LFM2-ColBERT-350M: New Open Source Retrieval Model Released
By
–
Model: https://
huggingface.co/LiquidAI/LFM2-
ColBERT-350M
…
Demo: https://
huggingface.co/spaces/LiquidA
I/LFM2-ColBERT
… -
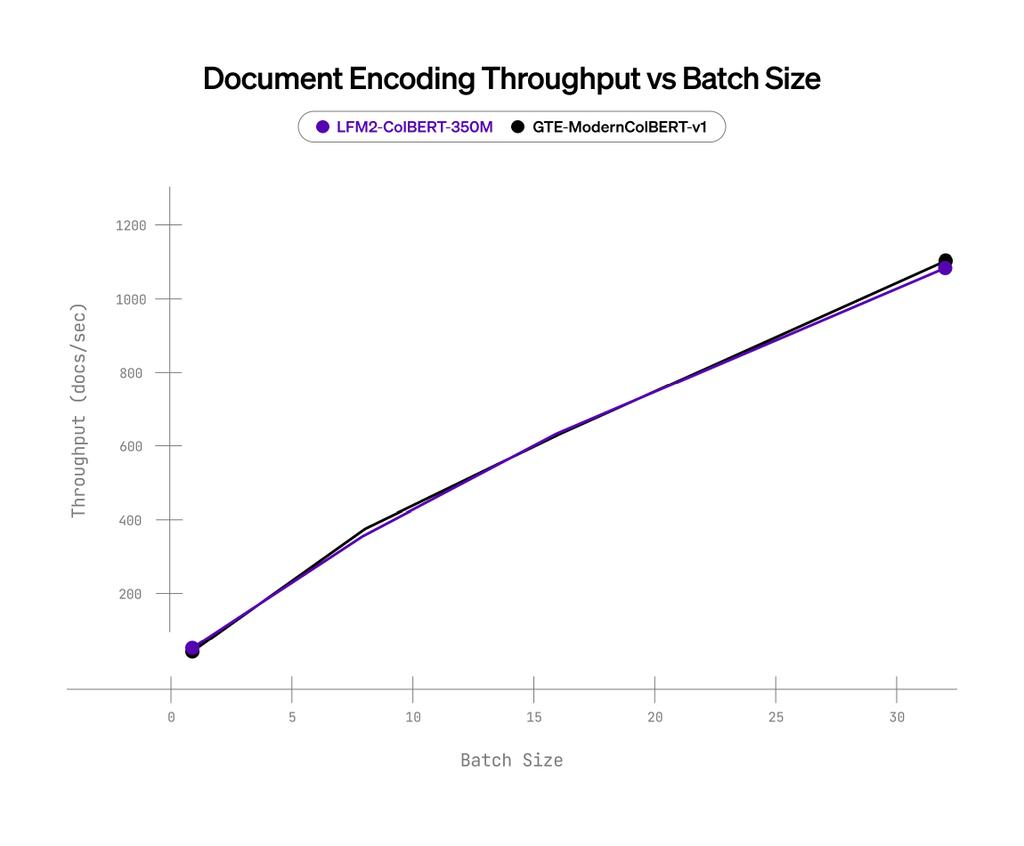
LFM2-ColBERT-350M Achieves Competitive Inference Speed
By
–
LFM2-ColBERT-350M is also very fast! Its inference speed is on par with GTE-ModernColBERT-v1 (only 150M parameters) for query and document encoding across various batch sizes.