True if you round-trip through OCR to markdown, that's where the token cost piles up. But PixelRAG skips that. The screenshot gets embedded straight into a vector for retrieval, no image to text step in the pipeline. The VLM only reads pixels at the end, on the few tiles it
MULTIMODAL AI
-
RAG stacks still convert pages to text, but vision models are catching up
By
–
Same, you'd think it was the default by now. But most RAG stacks still parse pages to text first, mostly because vision models were too slow and pricey to run at scale until pretty recently. That window is closing fast now.
-

PixelRAG: skip HTML parsing, screenshot for RAG
By
–

STOP PARSING HTML FOR RAG. JUST SCREENSHOT IT Researchers from UC Berkeley just released PixelRAG, an open-source system that skips HTML parsing entirely. Why is it changing web scraping for good? Well, instead of scraping a page into text and embedding chunks: #1 it
-
PixelRAG: visual retrieval system that screenshots pages instead of scraping
By
–
Web scraping will never be the same.
— Akshay 🚀 (@akshay_pachaar) 20 juin 2026
(100% open-source visual search at scale)
PixelRAG is a retrieval system that skips HTML parsing completely.
Instead of scraping a page into text and embedding chunks, it screenshots the page and retrieves the image. A vision-language model… https://t.co/tYKRgKDvSR pic.twitter.com/3dxYra0tZZWeb scraping will never be the same. (100% open-source visual search at scale) PixelRAG is a retrieval system that skips HTML parsing completely. Instead of scraping a page into text and embedding chunks, it screenshots the page and retrieves the image. A vision-language model
-
Early Access to Gemma 4 on Cerebras and 24h Hackathon with $5000
By
–
Early access to the world's fastest multimodal model is available. Get your hands on the Gemma 4 model on Cerebras. 24-hour hackathon with a prize of $5,000 and the flagship project presented by Google DeepMind and Cerebras. RSVP link in comments
-
Video to action: Gemini 3.0 Flash guides Aloha robot with JSON
By
–
From Video to Action: Gemini 3.0 Flash Guides Aloha #Robot with JSON Steps
— Ronald van Loon (@Ronald_vanLoon) 19 juin 2026
by @googleaidevs
#Innovation #EmergingTech #TechForGood pic.twitter.com/veyI4agcy0From to Action: Gemini 3.0 Flash Guides Aloha #Robot with JSON Steps
by @googleaidevs #Innovation #EmergingTech #TechForGood -
AI audio next wave: controllable, consistent, expressive, trustworthy voices
By
–
My takeaway: The next wave of AI audio will not be about sounding human. It will be about being controllable, consistent, expressive, and trustworthy. Watch the full video for the breakdown. Where do you think directed AI voice will create the most value first, media,
-
Anthropic secretly rolls out multilingual voice update
By
–
Curiously, Anthropic has started rolling out a multilingual voice mode update this week without announcing it. As we know, an upgrade to the underlying model is expected, and we may be witnessing a new battle among AI giants.
-
An image-blind model could become the best with a fix
By
–
The major flaw is that it is blind – it cannot process images at all. If they fix that, then perhaps it could become the best model available in the world.
-
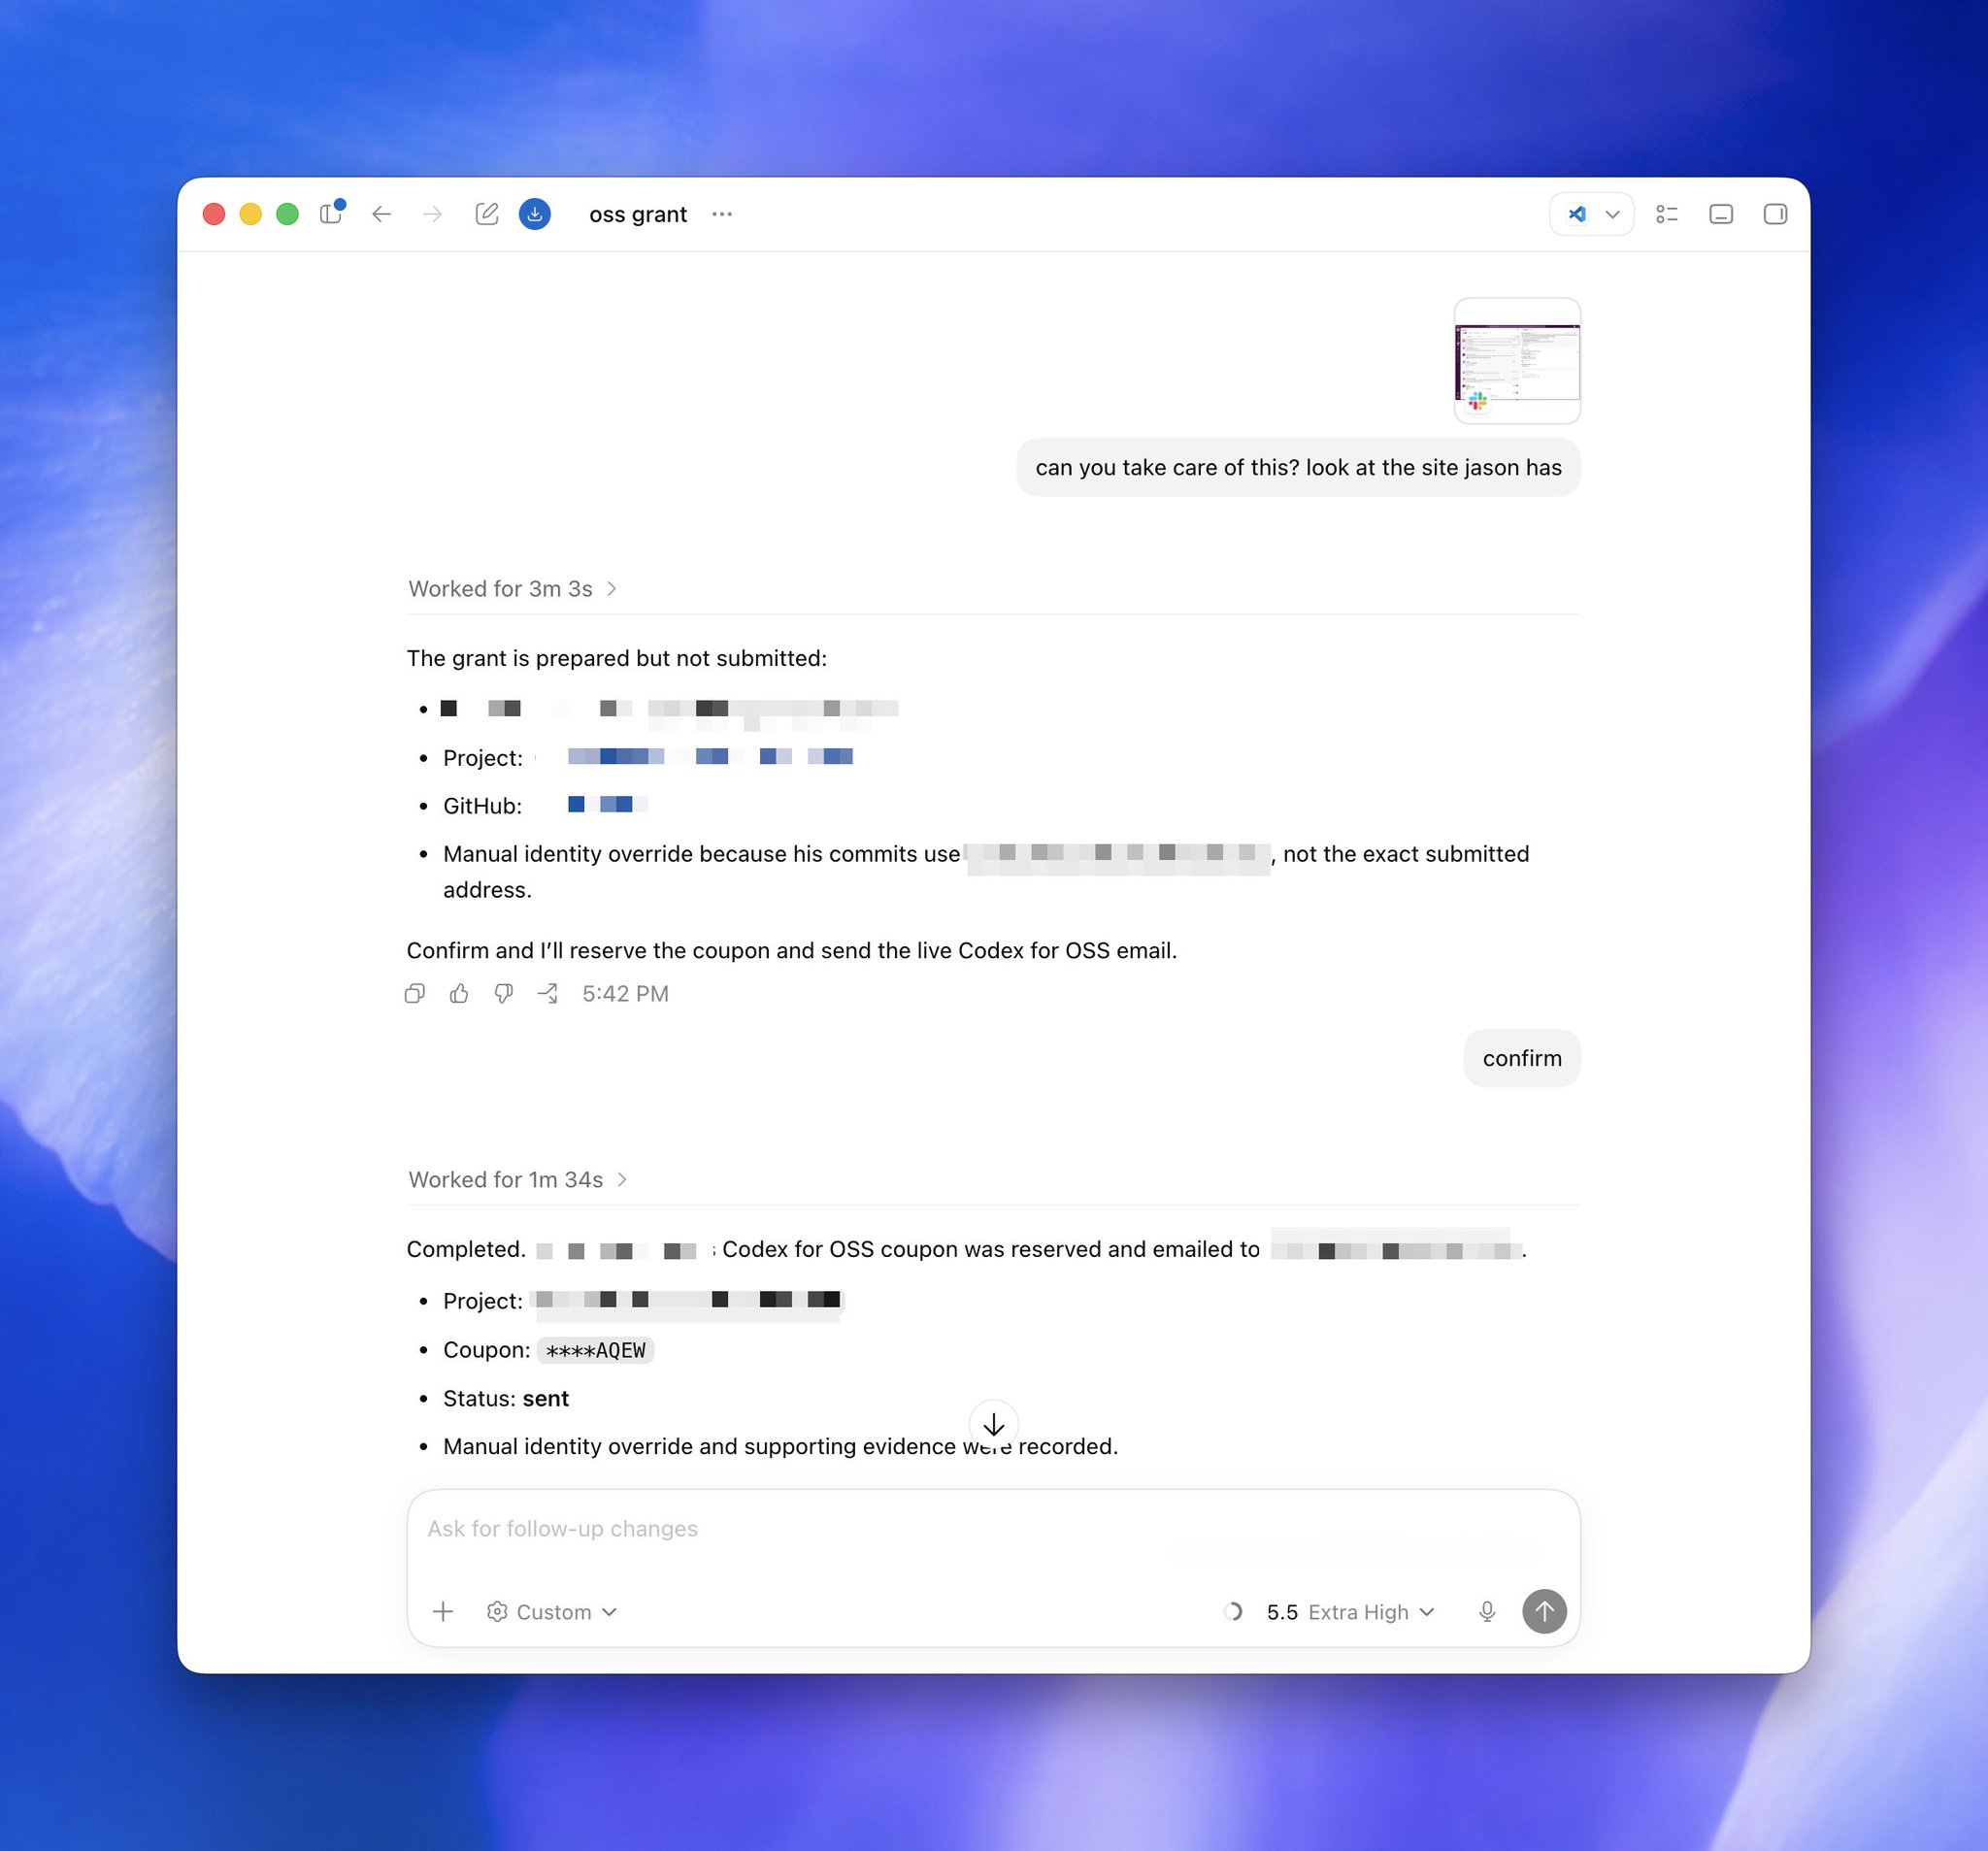
Codex creates OSS grant from app screenshot and logs
By
–
Codex continues to blow my mind everyday! Had to make an ad hoc Codex for OSS grant today, and all I did was send codex an app shot and "can you take care of this?" Codex went and looked through my slack DMs/ chats and chronicle logs to find an API @jxnlco
's codex made couple