Given how bad LLMs are at counting everything else – words, letters, etc – I'd be surprised if they can reliably count things in images
MULTIMODAL AI
-
Personal AI Meetup Marks Inflection Point in AI Technology
By
–
Just hosted the world’s first Personal AI meetup! (where recording is opt out instead of opt in)
— swyx 🐣 (@swyx) 6 avril 2024
It’s clear that we are at the Inflection point in:
– TTS
– STT
– private LLMs
– (low latency versions of all the above)
– >24h battery life BLE microphones
– Long context/structured… https://t.co/gbRgTTF4YZ pic.twitter.com/pBuKo7iTsMJust hosted the world’s first Personal AI meetup! (where recording is opt out instead of opt in) It’s clear that we are at the Inflection point in:
– TTS
– STT
– private LLMs
– (low latency versions of all the above)
– >24h battery life BLE microphones
– Long context/structured -
Multimodal Generative AI Transforms Retail Marketing and Collaboration
By
–
Learn about #AI and its transformative potential to reshape marketing, product design, and collaboration. Explore the cutting-edge innovations in multi-modal #GenerativeAI in #retail. https://
nvda.ws/3vD9EBF -
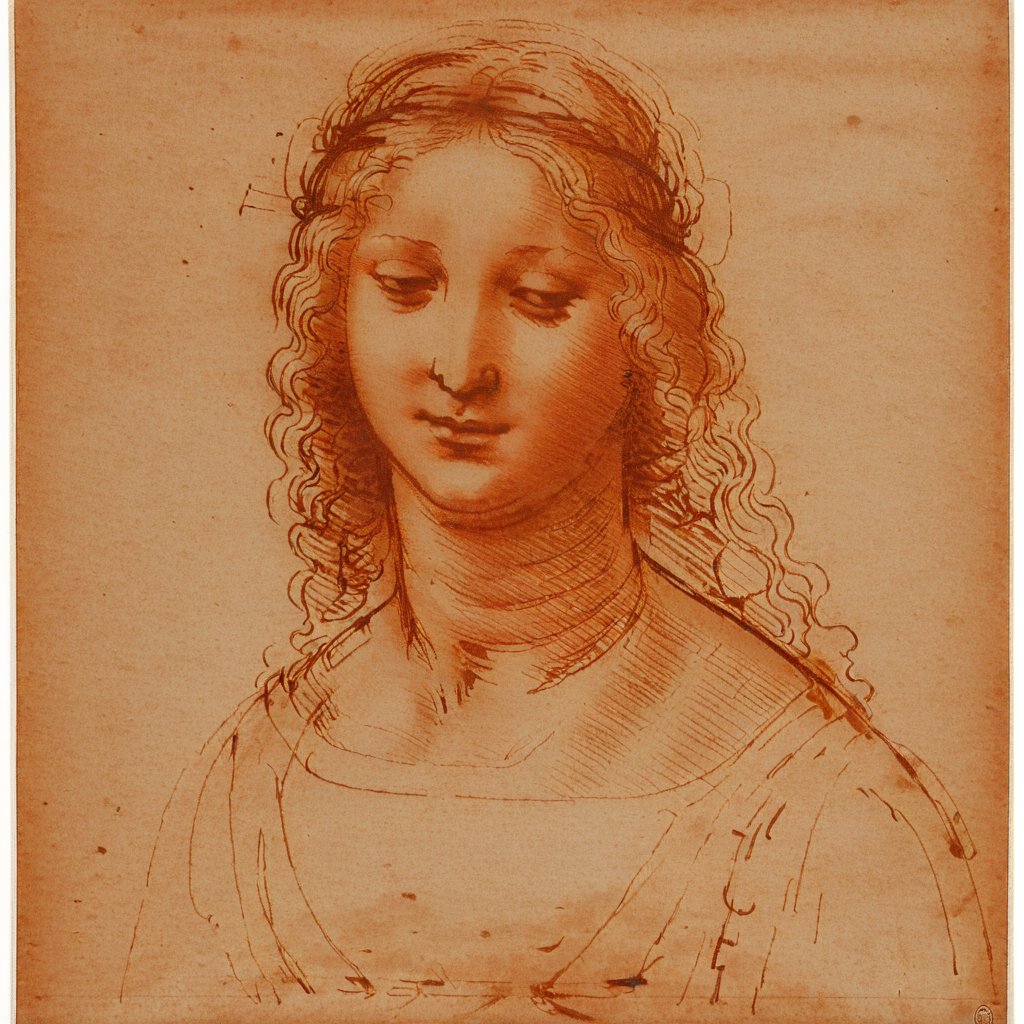
AI Model Trained on da Vinci Drawings Creates Renaissance Art
By
–
We trained a model on 150 high res Leonardo da Vinci drawings using @everartai
's latest finetuning tech. We are now in the mind of Leonardo. The model achieves incredible results on subjects of his era. But, what if we want to see Leonardo's take on modern subjects? -
Claude 3 Opus and Sonnet 200k Models Now Available
By
–
We've added Claude 3 Opus 200k and Sonnet 200k as bases for your prompt bots! These multimodal models are the most powerful base bots available, and can handle longer inputs for more natural back-and-forth conversations, in-depth analysis, multi-step tasks, and more. pic.twitter.com/QKjGlkCTjY
— Poe (@poe_platform) 5 avril 2024We've added Claude 3 Opus 200k and Sonnet 200k as bases for your prompt bots! These multimodal models are the most powerful base bots available, and can handle longer inputs for more natural back-and-forth conversations, in-depth analysis, multi-step tasks, and more.
-
Higgsfield AI Launches Personalized Character Video Creation App
By
–
Higgsfield AI came out of stealth — dropping a new foundational model that can create personalized character videos for social media. They launched an iOS app that allows users to take a selfie and get a personalized character. One to watch https://
x.com/higgsfield_ai/
status/1775523757136007354?s=46
… -
AI Voice Quality Needs Improvement for Natural Sound
By
–
Yeah — really smart. Just wish they sounded more natural…
-
Running LLaVA 1.6 Locally on Mac: Python Recipe Guide
By
–
Does anyone have a good Python recipe for running LLaVA 1.6 on a Mac? Any library you like is fine but I don't want to have to run a separate server process
-
Stanford scholars develop AI approach for satellite imagery analysis
By
–
With HAI’s support, @Stanford scholars embarked on a pioneering effort to evaluate a new thermal medium and to establish an analytical approach towards implementing AI into satellite imagery analysis. Missed yesterday’s seminar? Watch the recording here: https://
stanford.io/3J7E1Dc -
Claude 3 Models Include Vision Capabilities Cheaper Than GPT-3.5
By
–
All three of the Claude 3 models do vision, including Haiku which is cheaper than gpt-3.5-turbo