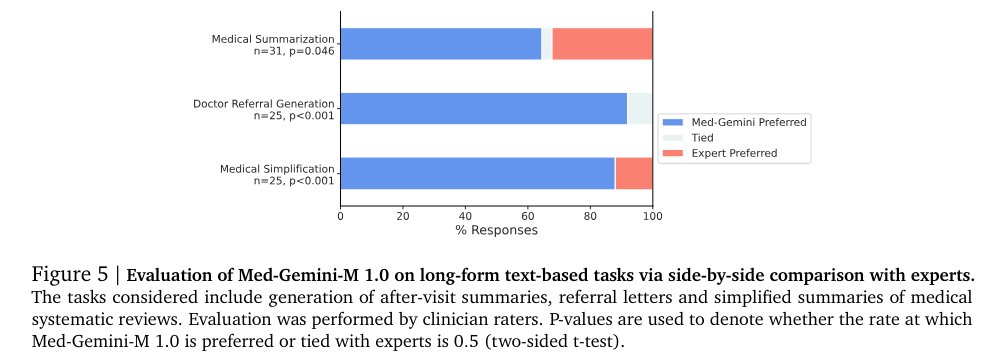
Med-Gemini results are preferred over human expert results on long-form text-based tasks like medical summarization, doctor referral generation, and medical simplification (where the goal is to generate a plain language summary that can be understood by most readers without a
MULTIMODAL AI
-

Med-Gemini Advances Clinical Diagnosis on NEJM Benchmark
By
–
On the NEJM CPC benchmark (an open-ended diagnosis task), the input is a text-based, challenging clinico-pathological case (CPC) report, and the output is a differential diagnosis list, comprising 10 potential diagnoses. The Med-Gemini model does well on its own and improves
-

Batch API Now Supports Larger Batches Multimodal
By
–
Bigger batches and more multimodal support in Batch API: https://t.co/kIybJPkwvO
— Greg Brockman (@gdb) 30 avril 2024Bigger batches and more multimodal support in Batch API:
-
Prompt Engineering for Vision Models: Generation, Editing, Detection
By
–
In Prompt Engineering for Vision Models, taught by @anmorgan2414 @JacquesVerre and @KaiserFrose of @Cometml , you’ll learn how to prompt and fine-tune vision models for personalized image generation, image editing, object detection and segmentation. The prompts you'll use for… pic.twitter.com/sXis2waFDH
— Andrew Ng (@AndrewYNg) 29 avril 2024In Prompt Engineering for Vision Models, taught by @anmorgan2414 @JacquesVerre and @KaiserFrose of @Cometml , you’ll learn how to prompt and fine-tune vision models for personalized image generation, image editing, object detection and segmentation. The prompts you'll use for
-
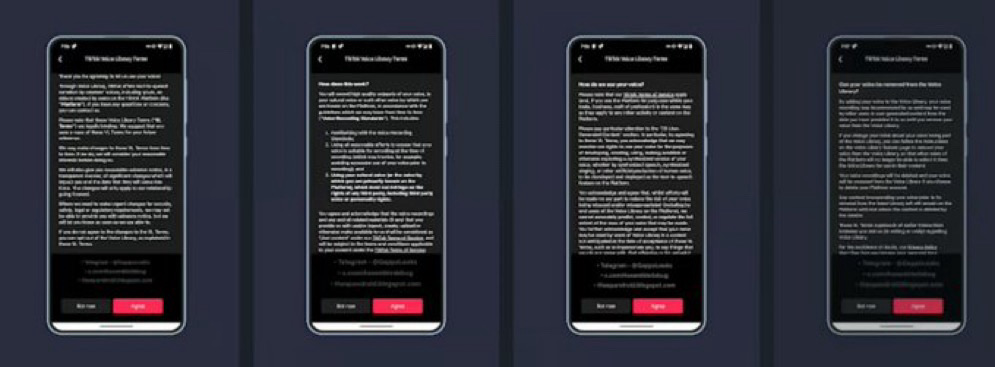
TikTok Develops Voice Cloning Feature with User Control
By
–
TikTok is working on a new feature that lets users clone their voice. Users will have full control over their AI voice. http://
theaivalley.com/p/voicecloning via @heyBarsee #AI #IoT #5G #GenerativeAI #Video #Clips @SpirosMargaris @pierrepinna @DeepLearn007 @Analytics_699 @gvalan @Hal_Good -
Whisper AI Model Transcribes and Translates Audio Simultaneously
By
–
Whisper can translate at the same time as it transcribes – it's surprisingly good at it https://
simonwillison.net/2022/Sep/30/ac
tion-transcription/
… -
AI Scaling Safety Efficiency Multimodal Data Collection Priorities
By
–
Revised beliefs: I still think we need to focus on scaling, safety, efficient training and inference, smarter memory (MoEs and long context have addressed this), more modalities (we’re still too slow at collecting visual, sound and touch egocentric data responsibly), online
-
China Releases Vidu: OpenAI Sora Competitor for Realistic Video Generation
By
–
China just released OpenAI’s Sora rival “Vidu” which can create realistic clips in seconds.
— Harold Sinnott #MWC26 (@HaroldSinnott) 28 avril 2024
via @heyBarsee #AI #IoT #5G #GenerativeAI #Video #Clips @SpirosMargaris @pierrepinna @DeepLearn007 @Analytics_699 @gvalan @Hal_Good pic.twitter.com/rQLqnnGPbXChina just released OpenAI’s Sora rival “Vidu” which can create realistic clips in seconds. via @heyBarsee #AI #IoT #5G #GenerativeAI #Video #Clips @SpirosMargaris @pierrepinna @DeepLearn007 @Analytics_699 @gvalan @Hal_Good
-
Visual capabilities of ChatGPT on iOS
By
–
Vision capabilities in action on ChatGPT for iOS in the conversational mode 📲https://t.co/TcrxqYSvcV pic.twitter.com/1YclKYVkHO
— 🚨 AI News | TestingCatalog (@testingcatalog) 27 avril 2024Vision capabilities in action on ChatGPT for iOS in the conversational mode https://x.com/testingcatalog/status/1784355965191561364?s=46
…