Introducing a new classifier to help researchers identify content created by DALL·E 3. We are also joining the Coalition for Content Provenance and Authenticity (
@C2PA_org
) Steering Committee to promote industry standards.
MULTIMODAL AI
-
DALL·E 3 Classifier and Content Provenance Standards
By
–
-
Congratulations on autonomous world models for vehicles
By
–
congrats, @alexgkendall
! looking forward to seeing your autonomous world models in every car 🙂 -

Med-Gemini Achieves State-of-the-Art Medical Imaging Results
By
–
This new paper on Med-Gemini research from @GoogleResearch and @GoogleDeepMind shows how the multimodal and long context capabilities of Gemini 1.5 can be used to get state-of-the-art results on a variety of 2D and 3D medical imaging and genomic risk score tasks.
-
DALL-E 3 produces image on first prompt, rare
By
–
DALLE-3, produced the image on the first prompt (rare)
-
LeRobot: Hugging Face launches first robotics library
By
–
Welcome LeRobot! the first robotics library at Hugging Face Over the past months, we saw impressive research breakthroughs in robotics (ALOHA, diffusion policies, UMI and so many) enabling robots behaviors previously thought impossible to train with limited quantity of data
-
AI Video Viewer Navigation Creates Movie-like Edit Effects
By
–
Made the image viewer on 📸 https://t.co/1vEawpI5vb work with videos too
— @levelsio (@levelsio) 6 mai 2024
So now you can [ ⬅️ Left ] [ ➡️ Right ] through AI video clips too
Which weirdly instantly makes it look like a movie with edit cuts
So maybe that's what we need to build next… pic.twitter.com/uuWkk3V6amMade the image viewer on http://
photoai.com work with videos too So now you can [ Left ] [ Right ] through AI video clips too Which weirdly instantly makes it look like a movie with edit cuts So maybe that's what we need to build next… -
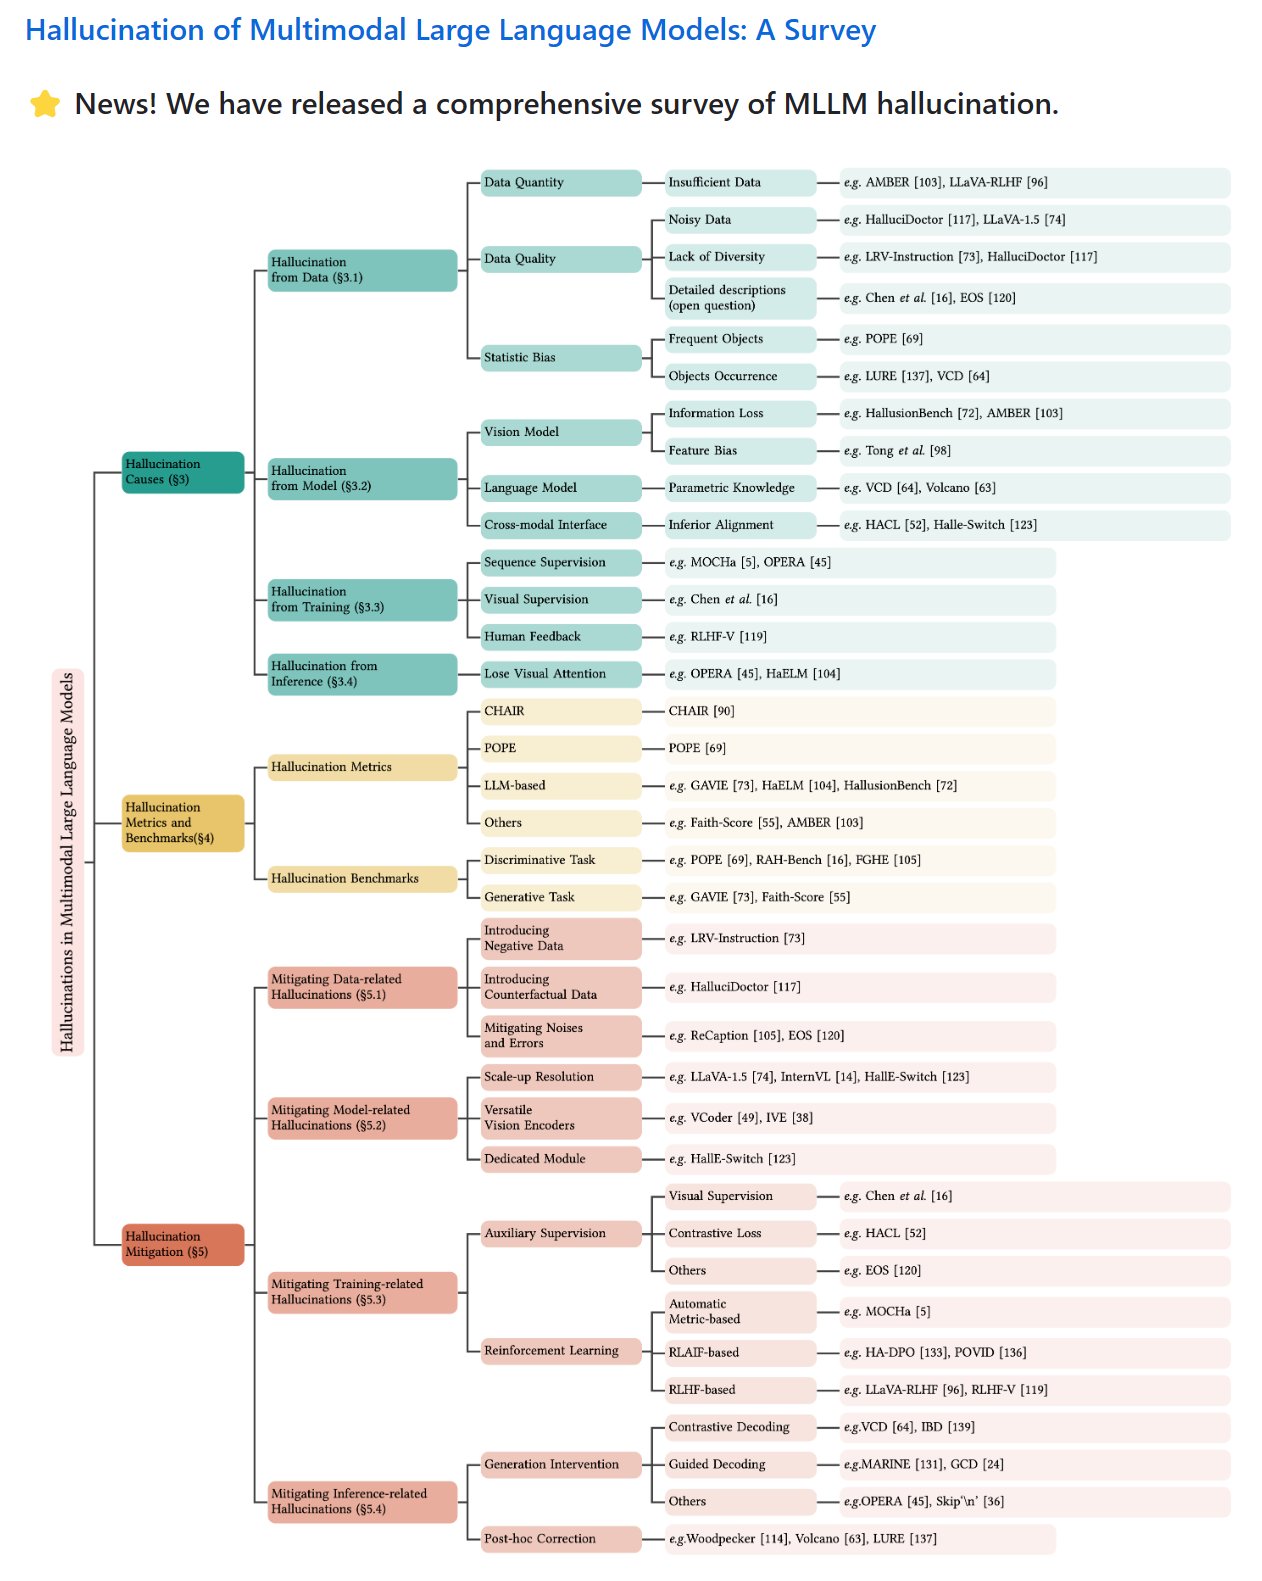
Multimodal LLM Hallucinations: Advances in Detection and Mitigation
By
–
9). Multimodal LLM Hallucinations – provides an overview of the recent advances in identifying, evaluating, and mitigating hallucination in multimodal LLMs.
-
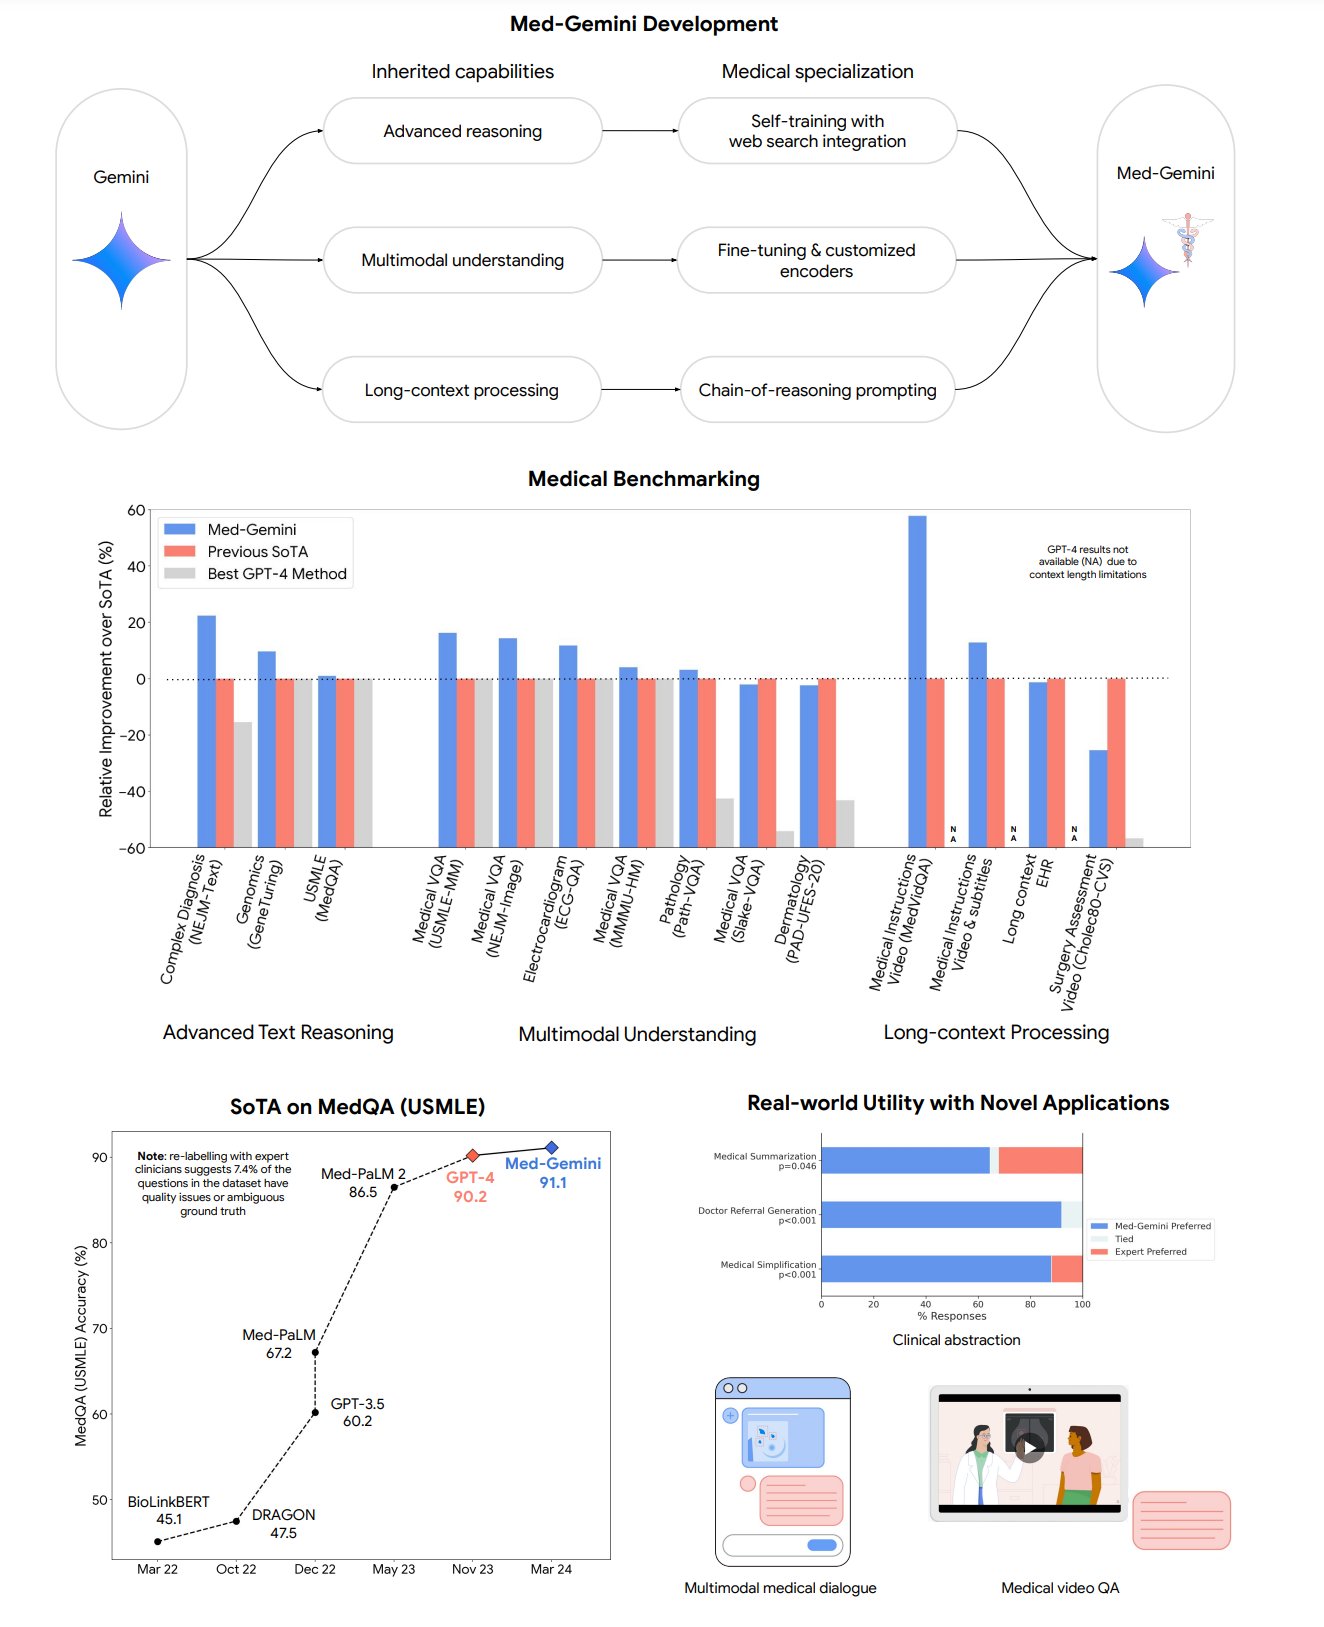
Med-Gemini Multimodal Model Surpasses GPT-4 on Medical Benchmarks
By
–
3). Med-Gemini – presents a family of multimodal models specialized in medicines and based on the strong multimodal and long-context reasoning capabilities of Gemini; achieves state-of-the-art performance on 10/14 benchmarks surpassing GPT-4 models.
-
Free Nvidia Courses on Generative AI, Computer Vision and RAG
By
–
Free courses from Nvidia on Generative AI Foundations, Computer Vision and RAG:
-
China Launches Vidu, OpenAI Sora Competitor for Video Generation
By
–
China just released OpenAI’s Sora rival “Vidu” which can create realistic clips in seconds.
— Harold Sinnott #MWC26 (@HaroldSinnott) 4 mai 2024
via @heyBarsee #AI #IoT #5G #GenerativeAI #Video #Clips @SpirosMargaris @pierrepinna @DeepLearn007 @Analytics_699 @gvalan @Hal_Good pic.twitter.com/cUnLOWrZIwChina just released OpenAI’s Sora rival “Vidu” which can create realistic clips in seconds. via @heyBarsee #AI #IoT #5G #GenerativeAI #Video #Clips @SpirosMargaris @pierrepinna @DeepLearn007 @Analytics_699 @gvalan @Hal_Good