GPT Images 2 is quietly becoming one of the most powerful creative engines on the internet. Users pushed it across wildly different domains — and the results are kind of insane – Musical Animation – Interactive 3D Science app – Historical infographic cinema – MORPG
MULTIMODAL AI
-
Voice-first shopping for dino outfits
By
–
I've always wondered why we don't see any voice-first interfaces, so I tried to build one with OpenAI's new realtime voice api – you can now shop for your dino outfits with just your voice. pic.twitter.com/gKFekQ84RN
— Peter Gostev (@petergostev) 10 mai 2026I've always wondered why we don't see any voice-first interfaces, so I tried to build one with OpenAI's new realtime voice api – you can now shop for your dino outfits with just your voice.
-
State Space Models in Gallery Updates
By
–
I have models with state space layers in the gallery (e.g., Nemotron 3). Anything since April I missed though?
-
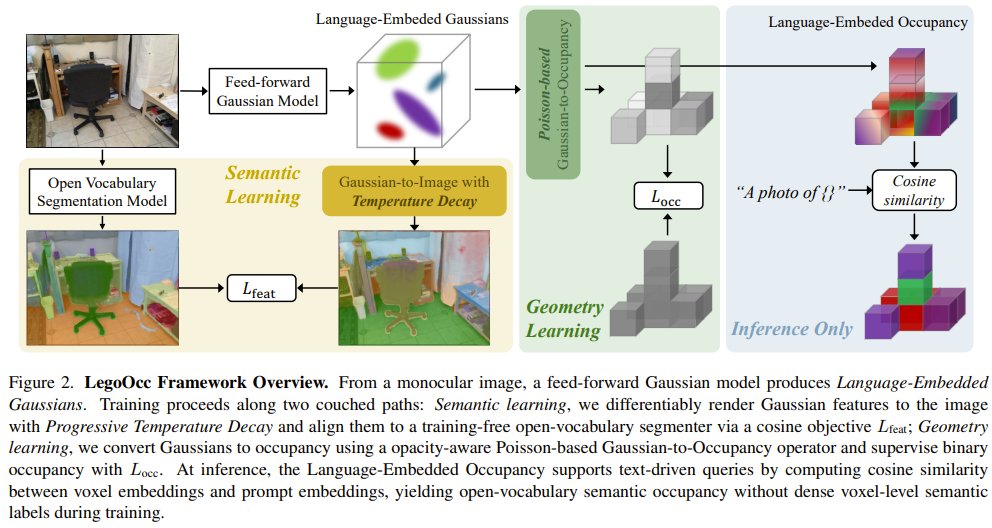
New Research Enables Open-Vocabulary 3D Occupancy for Home Robots
By
–
Why can’t your home robot identify a “plush toy” it’s never seen before? Researchers from HKUST Guangzhou & CUHK Shenzhen crack open-vocabulary 3D occupancy for indoor scenes. Their method uses only binary occupancy labels (occupied vs. free) to train language-embedded 3D
-
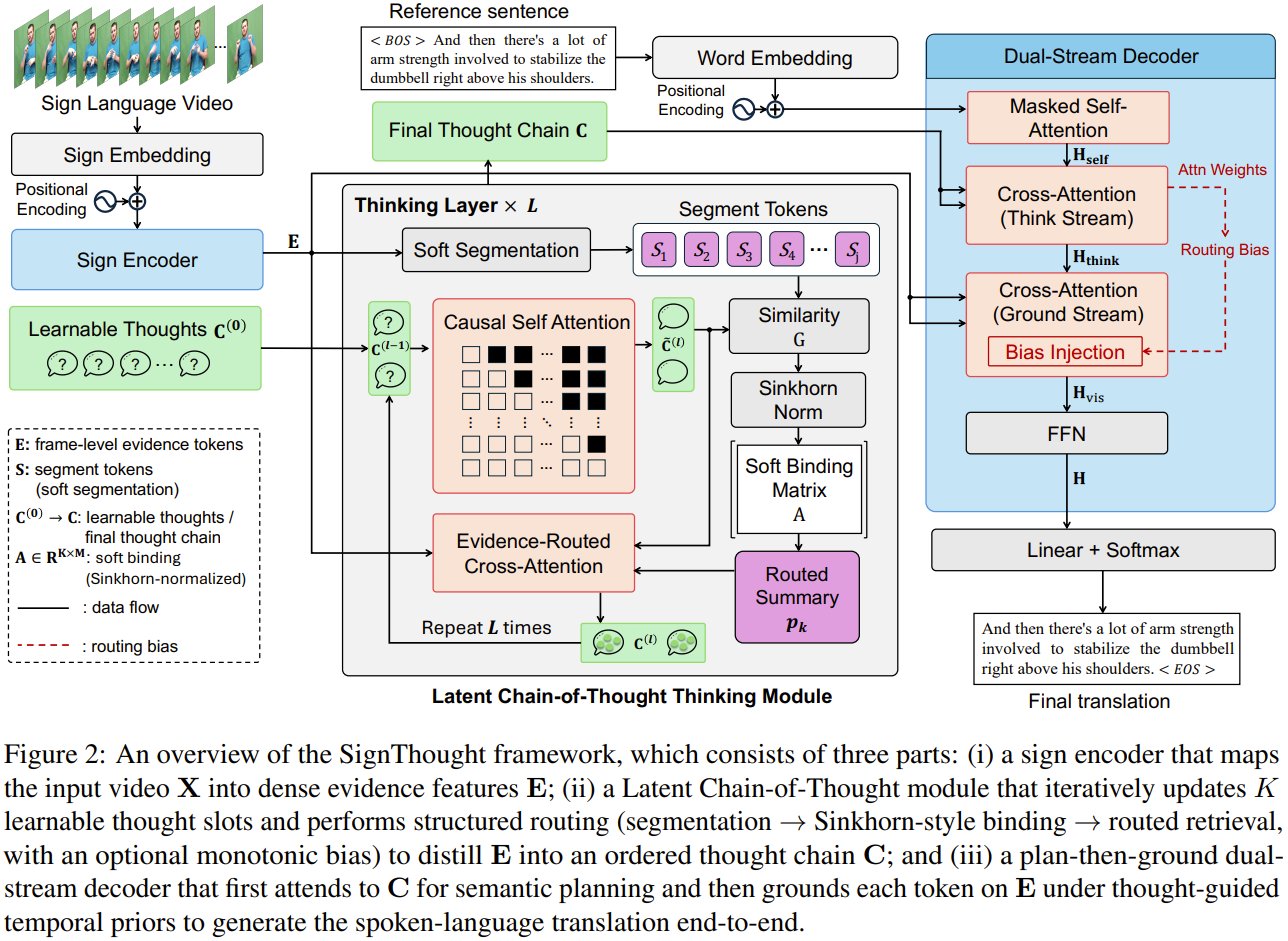
SignThought: A New AI Approach to Sign Language Translation
By
–
What if sign language translation didn’t just match signs to words, but actually thought through meaning first? Researchers from Hong Kong Polytechnic University and Sichuan University introduce SignThought. They replace the old word-by-word mapping with an explicit layer of
-

New Pet Robot Uses Multimodal AI for Adaptive Behavior
By
–
New pet #Robot uses local multimodal #AI to learn and adapt to human behavior
by Aamir Khollam @IntEngineering Learn more: https://
bit.ly/4th8XFF #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology -

Build a Text-to-Image Generator from Scratch Using Transformers and Diffusion
By
–
Build a Text-to-Image Generator (from Scratch), with transformers and diffusions: http://
amzn.to/3MFbyK4 by @mark_h_liu v/ @ManningBooks —————
#AI #ML #MachineLearning #DataScience #DataScientist -
Depth Anything V2: A Breakthrough in Monocular Depth Estimation
By
–
What if accurate depth maps could be generated from a single RGB image — without LiDAR or stereo cameras?
— Satya Mallick (@LearnOpenCV) 9 mai 2026
That’s exactly what Depth Anything V2 achieves.
In 2024, monocular depth estimation reached a major breakthrough:
✔ Fast
✔ Lightweight
✔ Temporally stable
✔ Edge-device… pic.twitter.com/Da4XDWC668What if accurate depth maps could be generated from a single RGB image — without LiDAR or stereo cameras?
That’s exactly what Depth Anything V2 achieves.
In 2024, monocular depth estimation reached a major breakthrough: Fast Lightweight Temporally stable Edge-device -

MiniCPM-o 4.5 for omni-modal interactions
By
–
MiniCPM-o 4.5 Towards Real-Time Full-Duplex Omni-Modal Interaction paper: https://
huggingface.co/papers/2604.27
393
… -
GPT-Realtime-2 for instant real-time audio translation
By
–
GPT-Realtime-2 for instantly translating audio in realtime https://t.co/syunWJopLR
— Greg Brockman (@gdb) 9 mai 2026GPT-Realtime-2 for instantly translating audio in realtime