Also had some early access to Gemini 3.5 Flash. Very fast for a flash model and very capable, though not as powerful as a full frontier model. I added it to the gallery or procedurally generated one-shot towns (it made one error that it corrected): https://
hg-20f7d1a3ce.netlify.app/#gemini-3-5-fl
ash
…
MULTIMODAL AI
-

Early access: Gemini 3.5 Flash impressions and demo
By
–
-
Google announces Gemini 3.5 Flash model series
By
–
Three years ago, Gemini started by understanding the world.
— Google AI (@GoogleAI) 19 mai 2026
With Gemini 2, models learned to think and reason.
Late last year, Gemini 3 brought any idea to life.
Today, we’re continuing that journey with our Gemini 3.5 series, starting with Gemini 3.5 Flash, delivering… pic.twitter.com/79sdQz5kfJThree years ago, Gemini started by understanding the world. With Gemini 2, models learned to think and reason. Late last year, Gemini 3 brought any idea to life. Today, we’re continuing that journey with our Gemini 3.5 series, starting with Gemini 3.5 Flash, delivering
-

Google unveils Gemini Omni Flash for seamless AI workflows
By
–

Google just raised the bar at #GoogleIO with the introduction of Gemini Omni Flash. By unifying native multimodality with high-speed generative media capabilities, this looks like a major step toward more seamless, agentic AI workflows. Integrating intelligence directly into
-
Gemini 3.5 Flash digests papers and auto-codes interactive website
By
–
2/
— Jeff Dean (@JeffDean) 19 mai 2026
Check out how Gemini 3.5 Flash instantly digests dense academic papers and autonomously codes a fully interactive, visual website explaining the intricacies of the research. It's an incredible stress test that seamlessly merges massive long context, deep reasoning, complex… pic.twitter.com/nnL8WvqAJq2/
Check out how Gemini 3.5 Flash instantly digests dense academic papers and autonomously codes a fully interactive, visual website explaining the intricacies of the research. It's an incredible stress test that seamlessly merges massive long context, deep reasoning, complex -
AI watermarks and provenance tools for images
By
–
We’re adding new ways for people to identify AI-generated images and understand where they came from. In addition to C2PA Content Credentials, images now also contain a SynthID watermark, and can be identified using a public verification tool to check whether an image was made
-
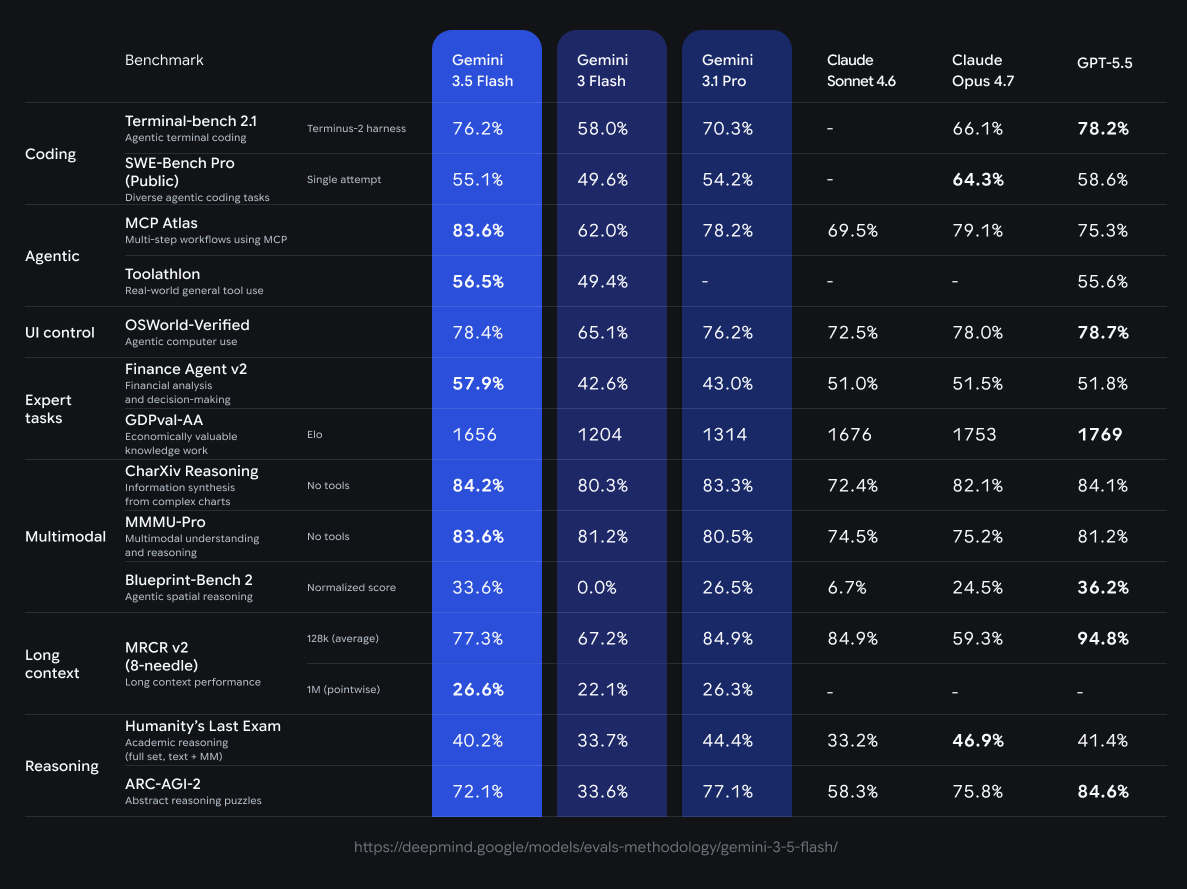
Google announces Gemini 3.5 Flash for agentic workflows
By
–
1/ Today at #GoogleIO, we’re releasing Gemini 3.5, our latest family of models combining frontier intelligence with action. We’re starting by releasing 3.5 Flash, which is built to help you execute complex, long-horizon agentic workflows. Gemini 3.5 Flash is our strongest model
-
Google Launches New Omni Multimodal Model
By
–
Google launches new Omni model.
— Allie K. Miller (@alliekmiller) 19 mai 2026
Google says that today Omni can create and edit (yes, edit!!) video but eventually it is to go from “any input to any output”.
Even more of a reason to believe that Sora is also a push toward world models. #Google pic.twitter.com/t4AOZb2wLmGoogle launches new Omni model. Google says that today Omni can create and edit (yes, edit!!) video but eventually it is to go from “any input to any output”. Even more of a reason to believe that Sora is also a push toward world models. #Google
-
Google’s Gemini Omni Demonstrates Multimodal Video Editing Capabilities
By
–
Nano Banana for video is here! Google has long touted that Gemini is natively multi-modal in & out — but Omni is the first glimpse into the power of that paradigm applied to creation.
— Bilawal Sidhu (@bilawalsidhu) 19 mai 2026
Toss in a video and do multi-turn edits. Toss in audio and get reactive visuals. It's kinda… pic.twitter.com/nRDkeecLvINano Banana for video is here! Google has long touted that Gemini is natively multi-modal in & out — but Omni is the first glimpse into the power of that paradigm applied to creation. Toss in a video and do multi-turn edits. Toss in audio and get reactive visuals. It's kinda
-

Using Typeless for AI-powered voice translation and LLM interaction
By
–
I highly recommend @typelessdotcom
. it replaced @WisprFlow for me It's fast, affordable, reliable and excellent on iphone / android. the live translation feat is brilliant: speak French, get English real-time! You can even do LLM manipulations directly via voice! -
Early access to Gemini Omni generates surreal multimodal prompt
By
–
I had early Gemini Omni access: "sea otter in a pilot's uniform explains why Spirit Airlines went bankrupt to a river otter who is distracted by their laptop while they are in a hot air balloon over NYC. in the next balloon over, william shakespeare fights a robot made of pizza" pic.twitter.com/FrSQWobYM4
— Ethan Mollick (@emollick) 19 mai 2026I had early Gemini Omni access: "sea otter in a pilot's uniform explains why Spirit Airlines went bankrupt to a river otter who is distracted by their laptop while they are in a hot air balloon over NYC. in the next balloon over, william shakespeare fights a robot made of pizza"