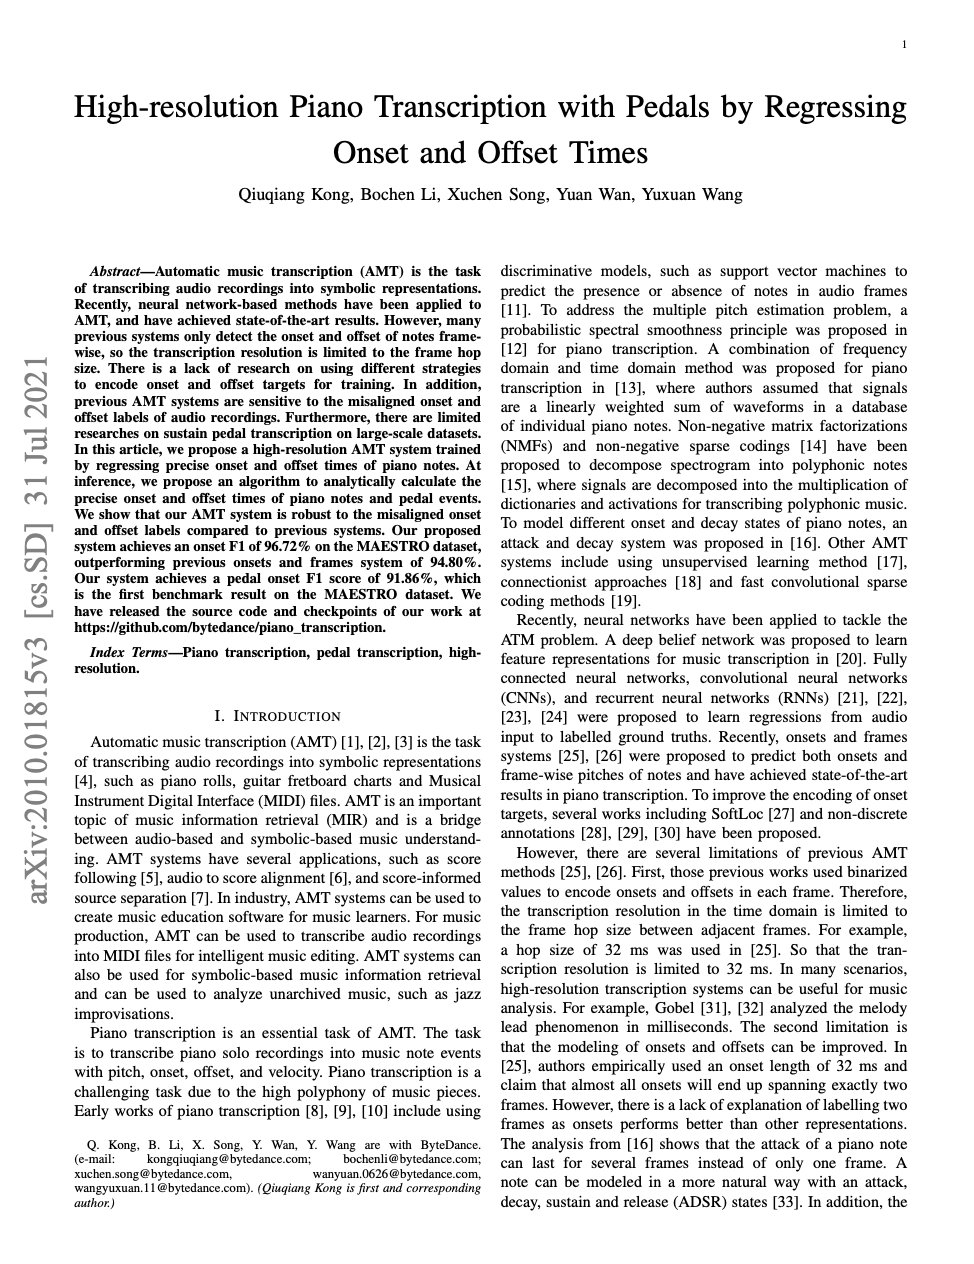
we worked with spectrograms. the spatial prior is useful for audio and i was starting from this (very good) baseline model from bytedance:
MULTIMODAL AI
-
Runway Gen-4 Turbo: Dynamic High-Quality Video Generation
By
–
New: Runway Gen-4 Turbo!
— Poe (@poe_platform) 27 mai 2025
Runway’s latest video model lets you generate dynamic, high-quality videos with realistic motion from text or images with impressive speed. (1/3) pic.twitter.com/ksGNW9tGVhNew: Runway Gen-4 Turbo! Runway’s latest video model lets you generate dynamic, high-quality videos with realistic motion from text or images with impressive speed. (1/3)
-
Agentic Document Extraction Speed Boost PDF Processing
By
–
Agentic Document Extraction just got much faster! From previous 135sec median processing time down to 8sec. Extracts not just text but diagrams, charts, and form fields from PDFs to give LLM-ready output. Please see the video for details and some application ideas. pic.twitter.com/29lOKf6UGO
— Andrew Ng (@AndrewYNg) 27 mai 2025Agentic Document Extraction just got much faster! From previous 135sec median processing time down to 8sec. Extracts not just text but diagrams, charts, and form fields from PDFs to give LLM-ready output. Please see the video for details and some application ideas.
-
Runway Models Now Available in ComfyUI API
By
–
Runway Image and models are now available to be integrated into ComfyUI API Nodes. Now you can access all of our most flexible and powerful models including Gen-4 Image and References, Gen-4 Turbo and Gen-3 Alpha Turbo directly into your own custom workflows and pipelines.
-
Gemini-powered UI generator with Figma export
By
–
Honestly shocked this isn't getting more attention. A real UI generator backed by Gemini with Figma export? Instant use-case.
-
Long-Context State-Space Video World Models Paper
By
–
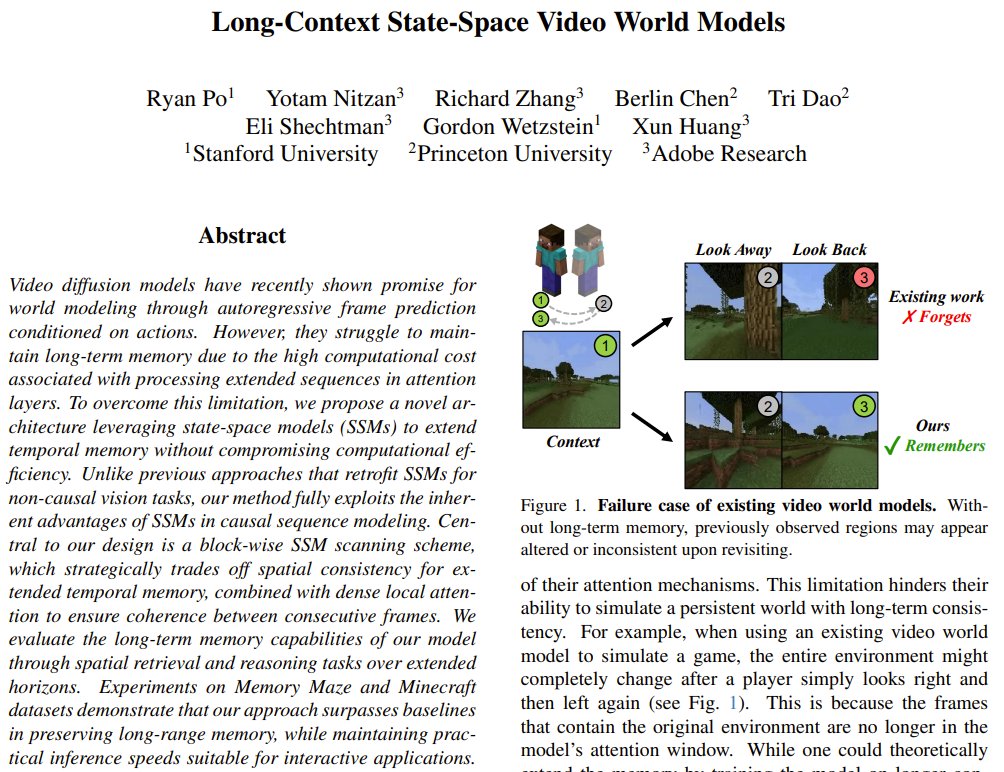
Long-Context State-Space World Models
Paper: https://
arxiv.org/pdf/2505.20171
.pdf
… -
State-Space Diffusion Models Advance Video World Modeling Memory
By
–
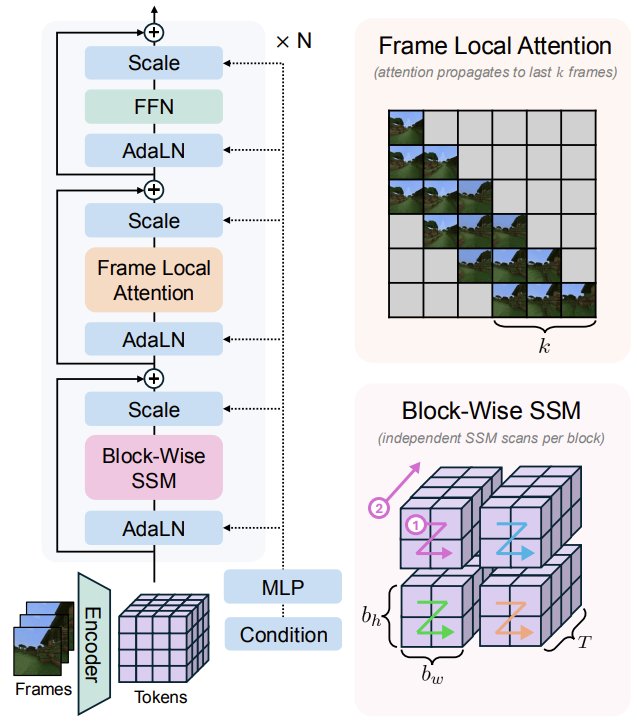
State-Space Meets Diffusion: A New Era for World Models This paper tackles a core bottleneck in video-based world modeling: long-term memory. While video diffusion models are great at short-term frame prediction, their memory fades fast—especially when modeling long
-

Side-by-side test: DeepSeek R1 vs Gemini 2.5 Pro
By
–
I tested Gemini 2.5 Pro and DeepSeek R1 with the exact same expert prompts. The results will blow your mind. DeepSeek R1 Vs. Gemini 2.5 Pro (Video demos are included )
-
AI Film Explores Human-Machine Reality Using Google Veo Technology
By
–
😳⬇️🤷🏽♀️ “I’d know if I weren’t real.” This short #film explores the line between human & machine, #GoogleVeo crafted, #AdobePremiere edits & written by a real person. Watch.
— Catherine Adenle (@CatherineAdenle) 27 mai 2025
📹 @taylorchien | IG #AIart #GenerativeAI #ViralVideos #TechNews #AI #Deepfake #viral pic.twitter.com/DhYVHg6CXX“I’d know if I weren’t real.” This short #film explores the line between human & machine, #GoogleVeo crafted, #AdobePremiere edits & written by a real person. Watch. @taylorchien | IG #AIart #GenerativeAI #ViralVideos #TechNews #AI #Deepfake #viral
-
Video Generators Using Google Maps for Synthetic On-Site Shots
By
–
this is a cool idea that video generators could incorporate (using google maps view to mimic on site shots anywhere) https://t.co/NhJS8Ifu1d
— Yohei (@yoheinakajima) 27 mai 2025this is a cool idea that video generators could incorporate (using google maps view to mimic on site shots anywhere)