
Google I/O 2026 just satisfyingly answered every question about where Gemini is heading. New models. A personal AI agent. Compute-based pricing. Background agents that monitor the web for you. Here's everything that matters for AI operators:
MULTIMODAL AI
-
Detection and grounding of objects in images
By
–
Detection: finds "a car."
— Satya Mallick (@LearnOpenCV) 20 mai 2026
Grounding: finds the red car in the crowd of cars.
Detection = fixed classes + bounding box (YOLO, RF-DETR).
Grounding = free-form language → localization.
The word "grounding" comes from cognitive scientist Stevan Harnad (1990) — mapping abstract… pic.twitter.com/bzzXJPFmXiDetection: finds "a car."
Grounding: finds the red car in the crowd of cars.
Detection = fixed classes + bounding box (YOLO, RF-DETR).
Grounding = free-form language → localization.
The word "grounding" comes from cognitive scientist Stevan Harnad (1990) — mapping abstract -
Gemini 3.5 Flash: strengths and inconsistencies observed
By
–
I did a video on Gemini 3.5 Flash – it is a pretty weird release, – went through dozens of examples and comparisons to other models. Some thoughts:
– It does WAY more than what you asked for
– It sometimes generates best in class stuff
– But sometimes crashes out and does -
Gemini Omni introduces physics-aware video generation and natural-language editing
By
–
Grok better catch up! Gemini Omni just raised the bar – physics-aware video generation + natural-language editing is a game changer for creators. Can't wait to see what people build.
-
Google Announces Gemini Omni Multimodal World Model
By
–
🚨Google just unveiled Gemini Omni, a world model that can turn text, photos, and clips into coherent, physics-aware video stories you can edit with natural language.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 20 mai 2026
Rolling out now in GeminiApp, Flow, and YouTube Shorts. pic.twitter.com/ghXv6bANSVGoogle just unveiled Gemini Omni, a world model that can turn text, photos, and clips into coherent, physics-aware video stories you can edit with natural language. Rolling out now in GeminiApp, Flow, and YouTube Shorts.
-
Integrating Google Maps and Street View into AI world models
By
–
Holy.. attaching Google Maps and Street View to Genie might have been one of the smartest decisions Google could make for world models.
— CHOI (@arrakis_ai) 20 mai 2026
Instead of generating every scene from scratch, Genie can anchor memory to the real structure of the world itself. Roads, buildings,… pic.twitter.com/ALNuuhA8iVHoly.. attaching Google Maps and Street View to Genie might have been one of the smartest decisions Google could make for world models. Instead of generating every scene from scratch, Genie can anchor memory to the real structure of the world itself. Roads, buildings,
-
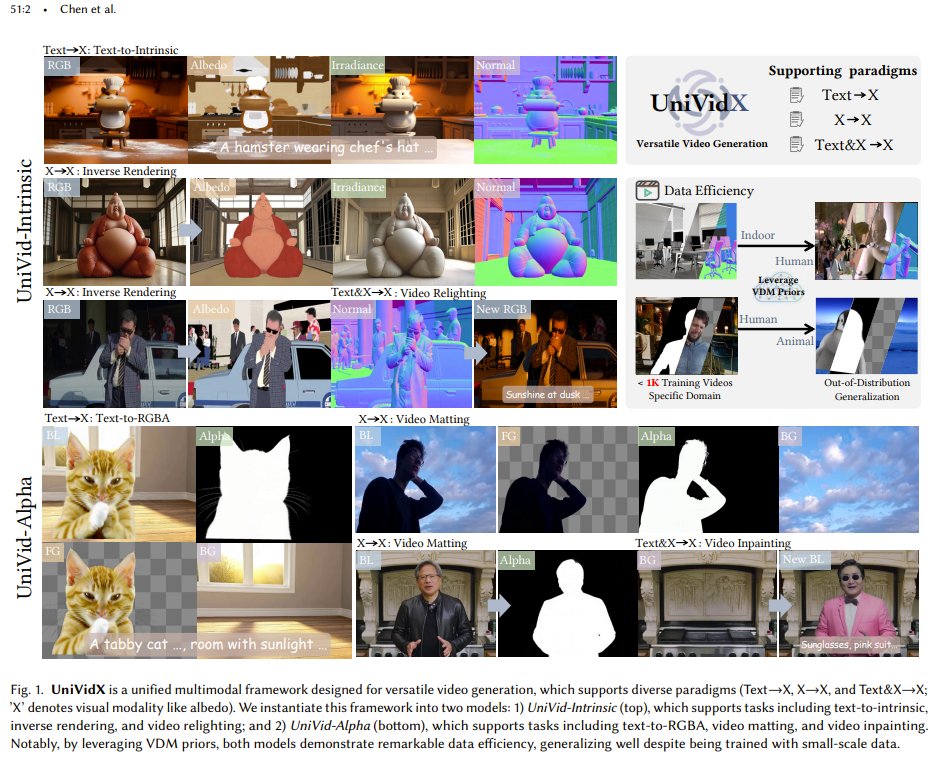
UniVidX: a unified model for multiple video-generation tasks
By
–
What if one AI could handle multiple video generation tasks without needing separate models for each? Researchers from HKUST, Stanford, Tsinghua, and other top labs present UniVidX. It uses three simple tricks: random condition masking to let the model learn any input-output
-
Google’s AI Agents Build Working Operating System in 12 Hours
By
–
Google's Antigravity 2.0 built the core framework of a working operating system in 12 hours, spinning up 93 sub-agents and processing billions of tokens for under $1,000 in compute costs.
— Chubby♨️ (@kimmonismus) 20 mai 2026
On stage, the team booted Doom on the AI-built OS.
Just imagine all the possibilities in… pic.twitter.com/yT2RffsjrwGoogle's Antigravity 2.0 built the core framework of a working operating system in 12 hours, spinning up 93 sub-agents and processing billions of tokens for under $1,000 in compute costs. On stage, the team booted Doom on the AI-built OS. Just imagine all the possibilities in
-
Technical challenges in AI agent monitoring and execution
By
–
Exactly, Sandboxes & tunnels fix execution, but most agents still lack proper monitoring to even know when they fail.
-
Audio-Conditioned Multimodal Model
By
–
Por cierto el modelo, como buen modelo multimodal, es capaz de condicionar su resultado al input de audio. En este caso este vídeo no tenía ningún prompt de input mas que el vídeo y su audio. pic.twitter.com/G4IPOexVXS
— Carlos Santana (@DotCSV) 19 mai 2026By the way, as a robust multimodal model, it can condition its output on audio input. In this instance, the video had no input prompt other than the video itself and its audio.