I loved this research paper on Flow Matching, the most popular approach for video gen. TLDR: More data means harder to fit any specific data (say image), better generalisation, greater coverage of learned concepts. Pretraining: Use Billions of data to learn many things and none
MULTIMODAL AI
-
Learning Style Representations in Continuous High-Dimensional Spaces
By
–
they are randomly sampled from a continuous high dimensional space that's been trained to learn what elements of imagery constitite the concept of style
-
Banana AI Generates Image of Itself Tweeting About Itself
By
–
.
@NanoBanana generate an image of a banana sitting at their computer typing a tweet about a banana sitting at their computer typing a tweet -

Qwen3-Max-Preview Release Announced
By
–

BREAKING : Qwen got a big Qwen3-Max-Preview release. Now available via Qwen Chat & Alibaba Cloud API. Open models are conquering the space
-
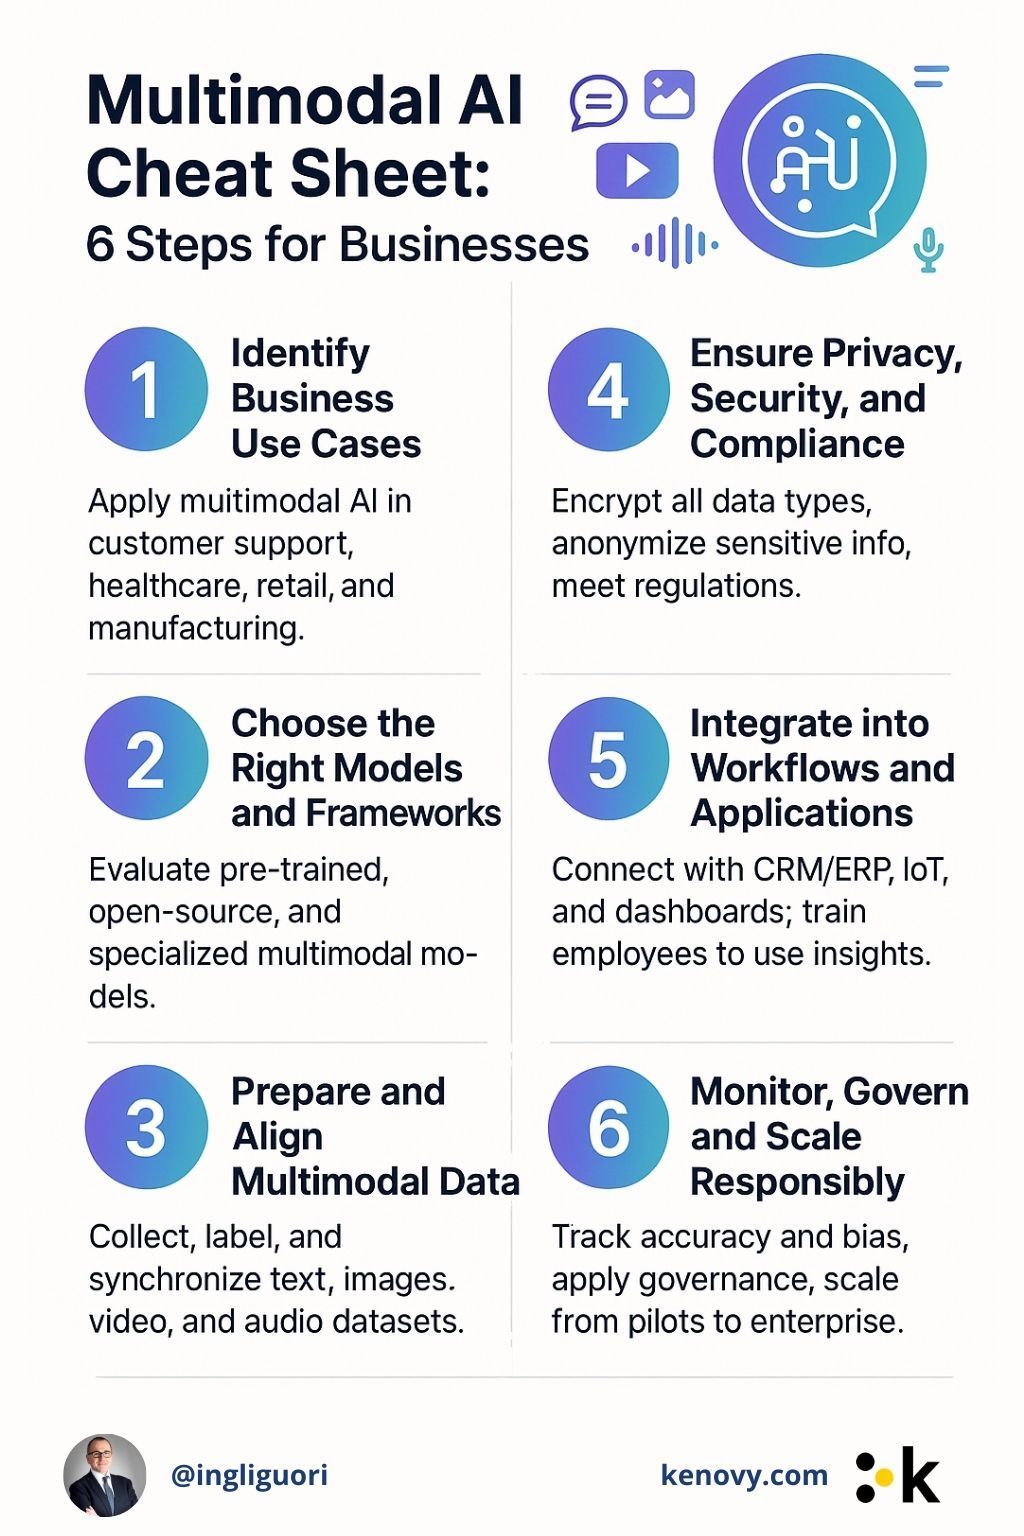
Guide d’implémentation de l’IA multimodale en 6 étapes
By
–
Multimodal AI Cheat Sheet: 6 Steps for Businesses Identify business use cases Choose the right models & frameworks Align multimodal data (text, images, video, audio) Ensure privacy & compliance Integrate into workflows & apps Monitor, govern & scale
-
Luma AI Dream Machine Modify Video Enables Virtual Home Redesign
By
–
La nouvelle version de Luma IA permet une refonte de d'appartement/maison virtuel
— VISION IA (@vision_ia) 5 septembre 2025
Réalisée avec "Modify Video" dans Dream Machine. pic.twitter.com/bqLTAyoba8La nouvelle version de Luma IA permet une refonte de d'appartement/maison virtuel Réalisée avec "Modify Video" dans Dream Machine.
-

FineVision: Free Open Dataset for Vision Language Models
By
–
We’re doing the work that nobody else wants to do! Welcome to FineVision, the best free open dataset to train vision language models. Let’s go open-source!
-

Gemini Visualizes Boullée’s Never-Built Newton Centograph
By
–
Never built architecture and AI. Gemini image generator (nano banana) does a pretty good job imaging what Boullée’s Centograph, his fantastical (and never built) tomb for Isaac Newton would have looked like. I gave it the original 1784 black and white drawings to work with.
-
Multimodal LLMs struggle with figurative language in image generation
By
–
LLM multimodal image generation remains too literal in the face of figurative language.
-
AI-Generated Photorealistic Portrait of Japanese Ceramicist
By
–
Here's the full prompt that was used to generate the first image: A photorealistic close-up portrait of an elderly Japanese ceramicist with deep, sun-etched wrinkles and a warm, knowing smile. He is carefully
inspecting a freshly glazed tea bowl. The setting is his rustic,