I still find it crazy that no lab has surpassed Seedance 2.0 in text-to-video, even though Seedance 2.0 was released back in February.
MULTIMODAL AI
-

Dynamic workflow execution with subagents (Claude Code)
By
–
ANTHROPIC JUST DROPPED A MASSIVE UPDATE FOR CLAUDE CODE: DYNAMIC WORKFLOWS. Instead of a single pass, Claude can now write an orchestration script on the fly and spin up tens to hundreds of parallel subagents for complex tasks ↓ First, they divide the work, run
-

HiF-VLA: Robots remembering past and anticipating future via motion
By
–
What if your robot could remember the past and anticipate the future to master long tasks? Researchers from Westlake University and Zhejiang University introduce HiF-VLA. It uses motion as a compact representation to give robots hindsight, insight, and foresight—learning from
-

AI Agent Skills for Video Search and Summarization
By
–
Hours of video, now searchable by your agent. We just released a new set of agent skills and modular architecture for the Metropolis Blueprint for Search and Summarization, eliminating the need for manual configuration of multiple microservices. Load the skills into a
-

Omni Model Creative Applications: Video Translation and Consistency
By
–
Mind-blowing to see what’s already possible with the new Omni model! From sketching drone camera paths to instant multilingual video translations and seamless character consistency. Check out these incredible creative use cases highlighted by @joshwoodward Time to experiment
-

Hotelist adds AI vision to filter for weightlifting gyms
By
–

I added AI vision to http://
Hotelist.com so you can filter on stuff that it finds in photos of the hotel This lets you filter for weightlifting gyms for example and it'll show you their gym in the list so you can immediately see if it's good gym or not Same with the other -
AI Vision Model Limitations in Object Detection Tasks
By
–
This kind of prompt only works up to a point. If I ask it to put bounding boxes around all cars or all vehicles, it will mislabel lots of things while also hallucinating new things to label. pic.twitter.com/8B1CNnlbh5
— fofr (@fofrAI) 29 mai 2026This kind of prompt only works up to a point. If I ask it to put bounding boxes around all cars or all vehicles, it will mislabel lots of things while also hallucinating new things to label.
-
Testing Omni to add labelled bounding boxes around monster truck and flag
By
–
A quick test of using Omni to edit a video and add labelled bounding boxes around objects.
— fofr (@fofrAI) 29 mai 2026
> Add a labelled bounding box around the monster truck and the flag pic.twitter.com/CZUy3LhZOuA quick test of using Omni to edit a video and add labelled bounding boxes around objects. > Add a labelled bounding box around the monster truck and the flag
-
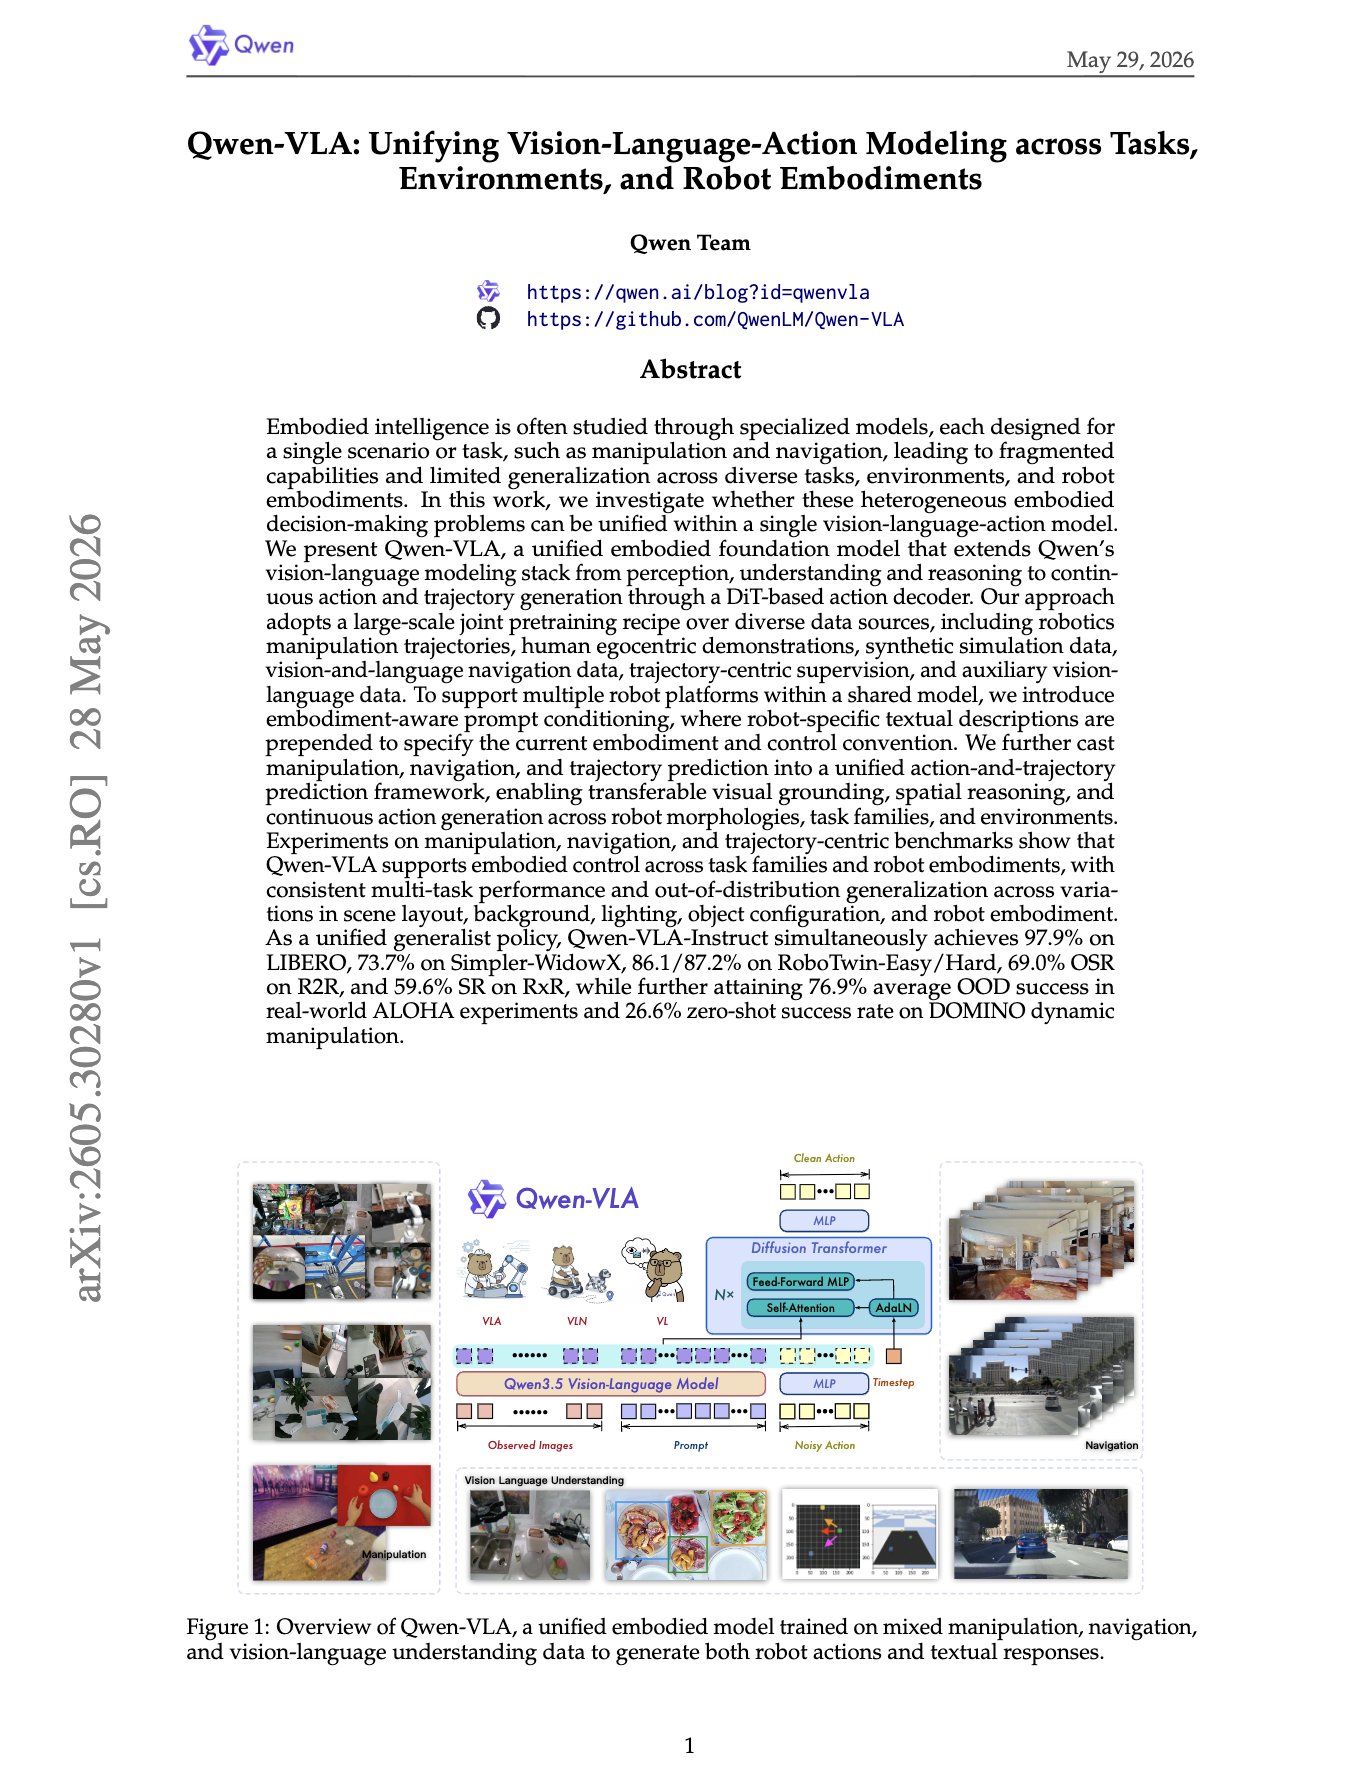
Qwen-VLA: Unified Vision-Language-Action Robot Learning
By
–
“Qwen-VLA: Unifying VLA Modeling across Tasks, Environments, and Robot Embodiments” They turned robot learning into one vision-language-action modeling problem instead of separate policies for each task, environment, and robot body. So by adding a DiT flow-matching action
-
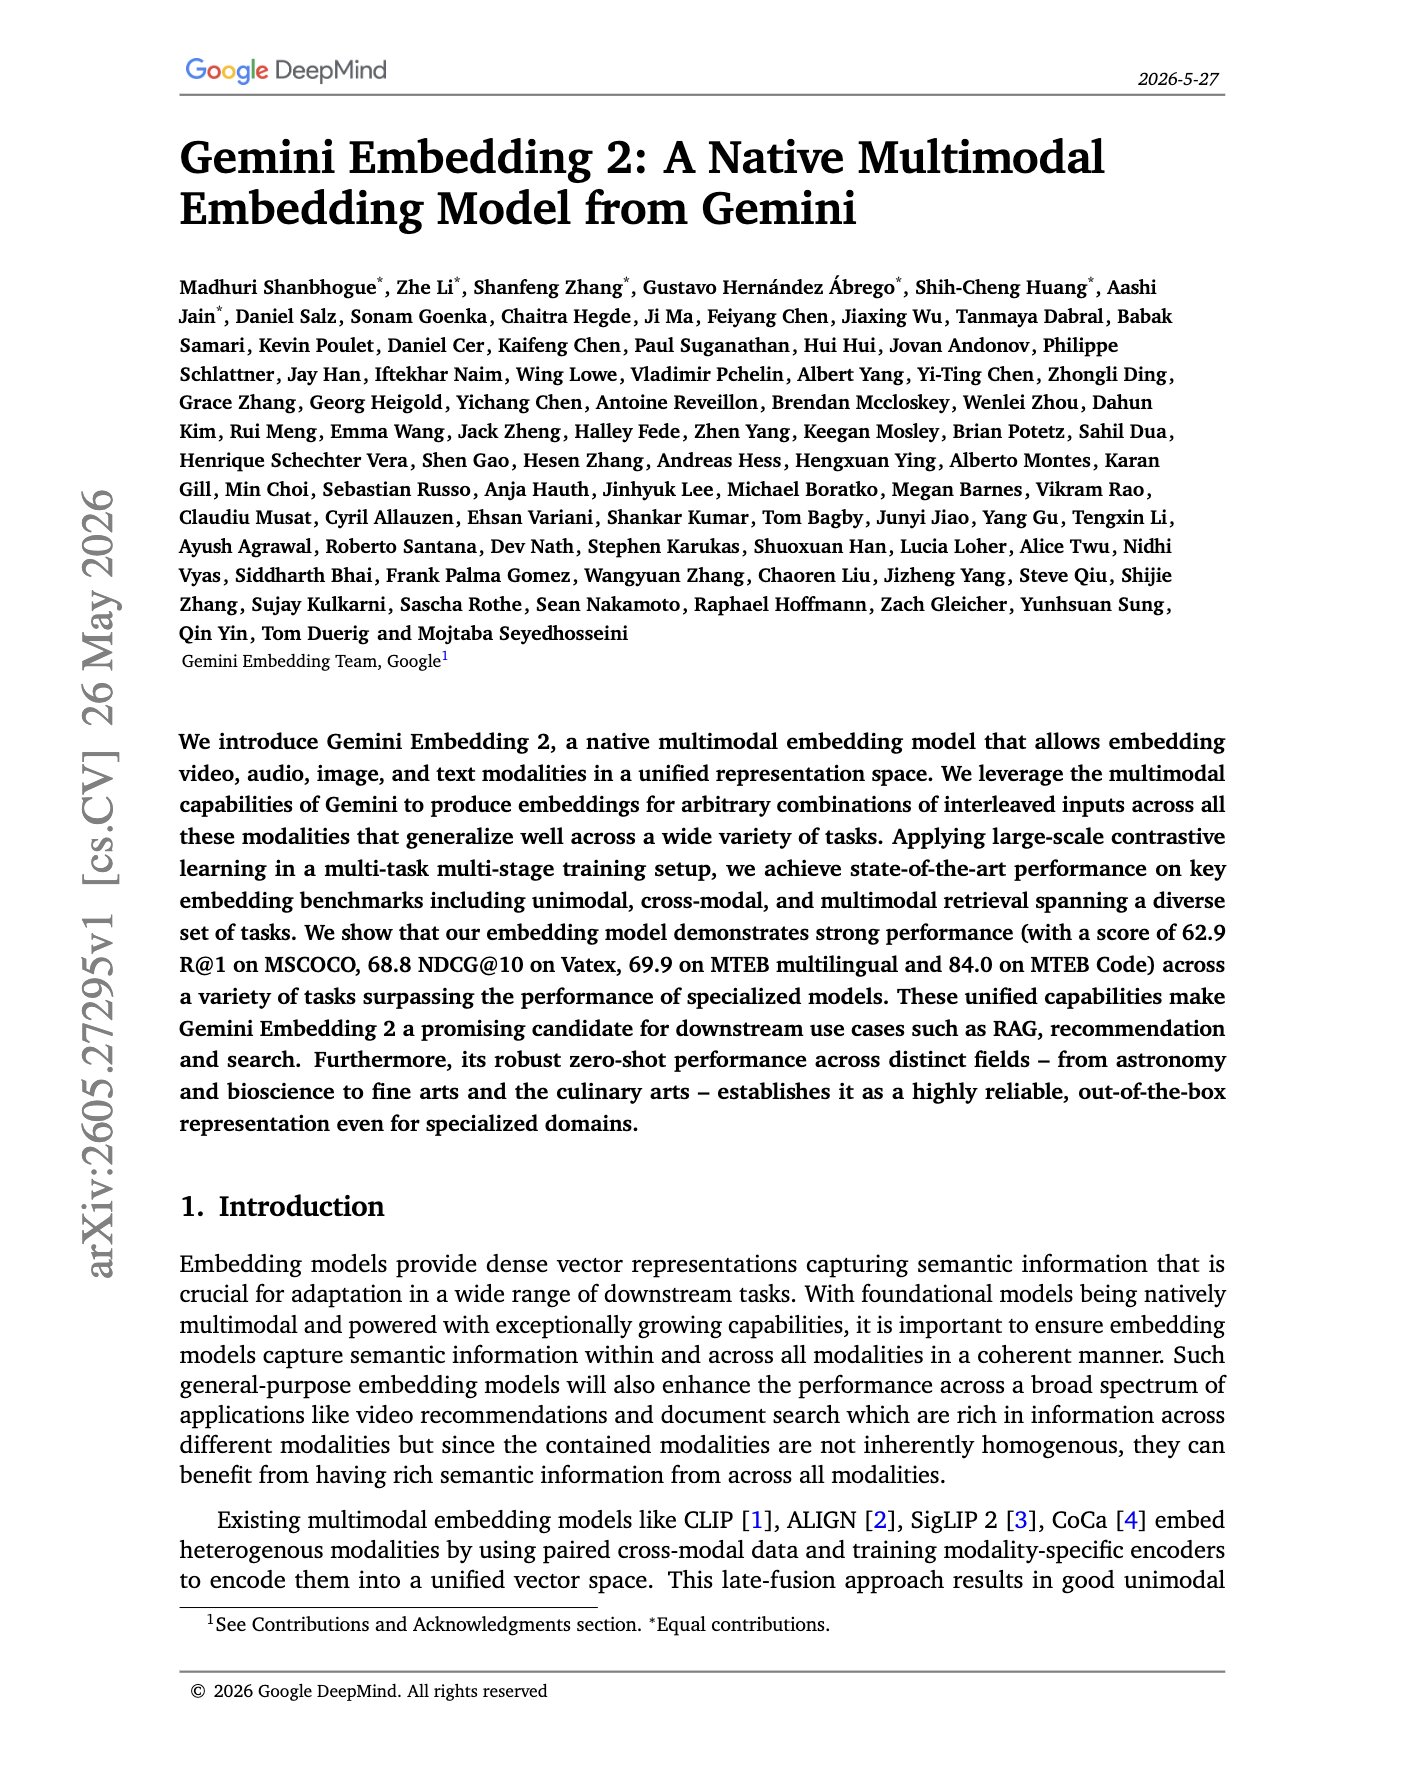
Gemini Embedding 2: Native Multimodal Embedding Model
By
–
"Gemini Embedding 2" This paper turns Gemini into one native embedding model for text, image, video, audio, and interleaved multimodal inputs. Instead of converting everything into text first, it embeds raw modalities directly into one shared space, improving audio search,