
Can AI truly understand tools like humans do? Researchers introduce PhysToolBench, the first benchmark testing MLLMs’ grasp of physical tools—from recognizing and explaining how they work to creatively inventing new ones when none are available. Tests on 32 leading models show
MULTIMODAL AI
-
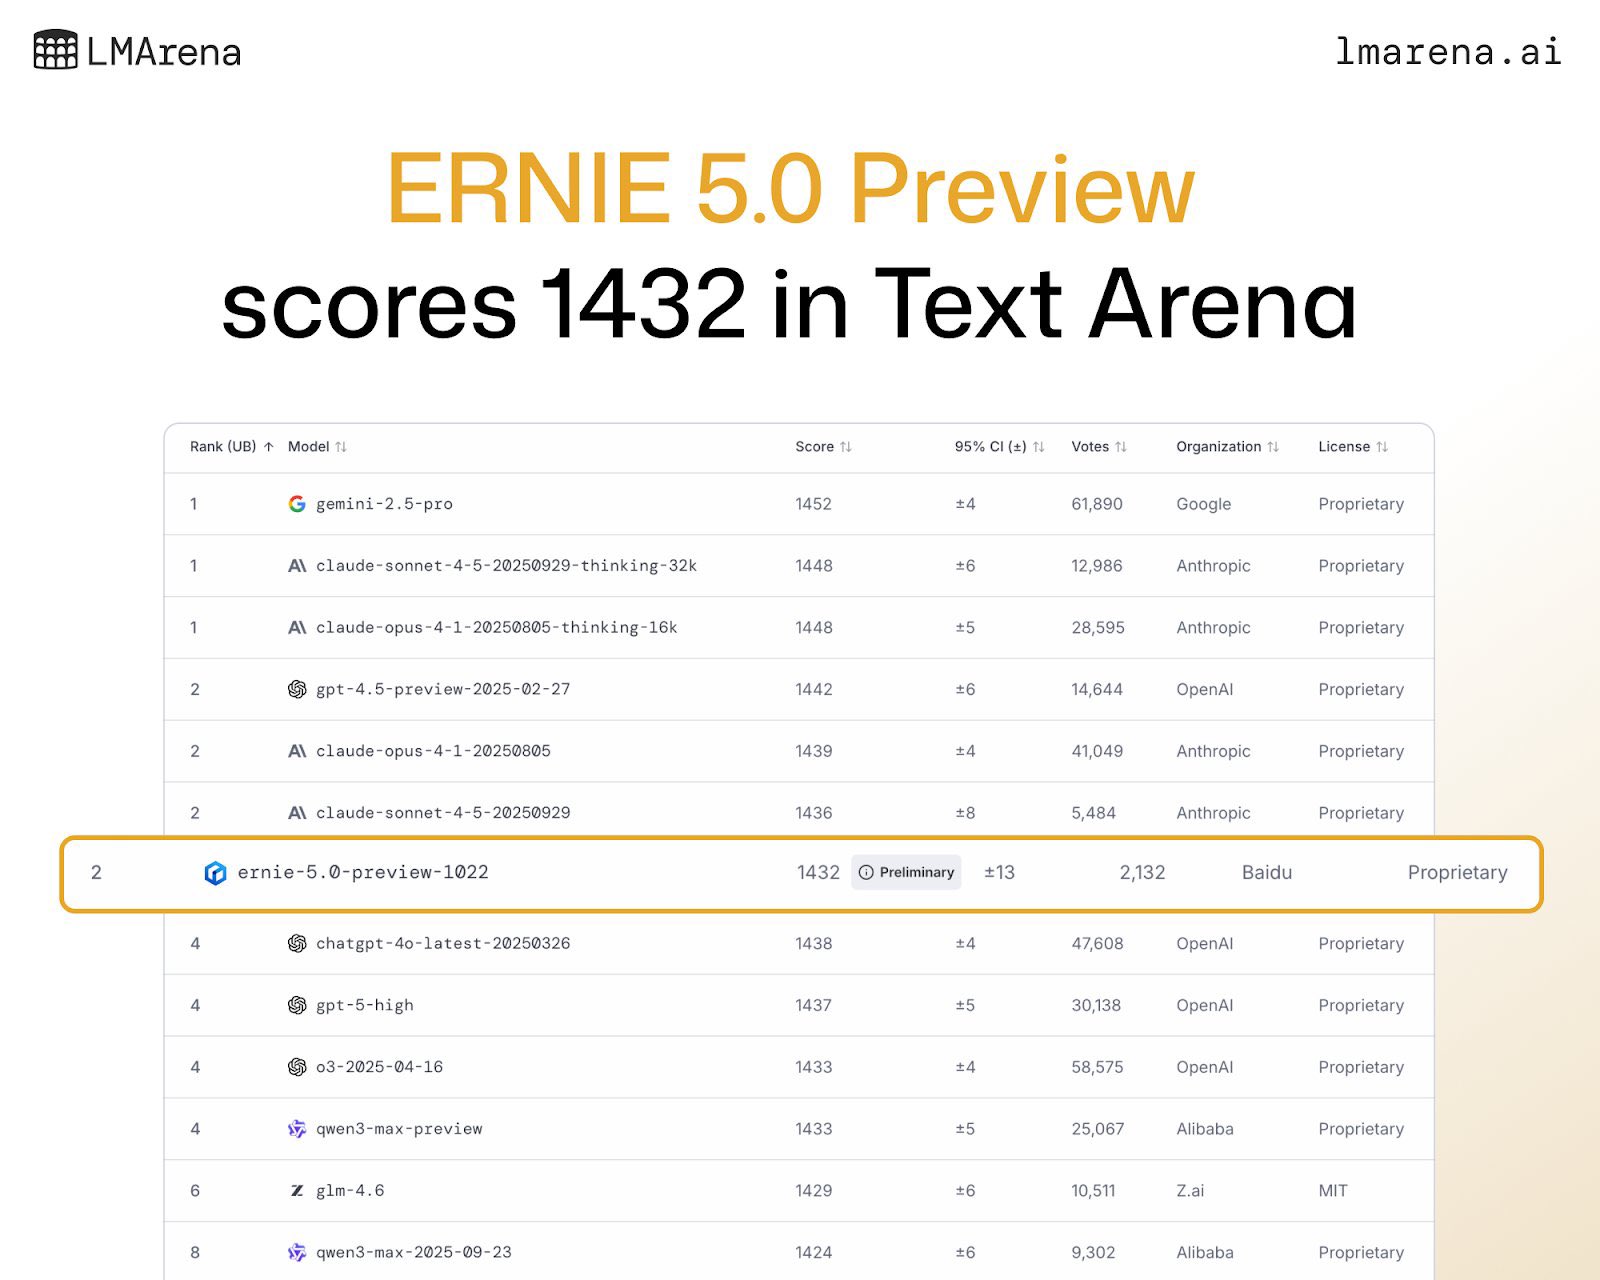
ERNIE-5.0-Preview-1022 Scores 1432 on LMArena
By
–
ERNIE-5.0-Preview-1022 from Baidu got a preliminary high ranking on LMArena and scored 1432 points. Feels like the gap is getting very small
-

Multimodal Interfaces Transform Human-Technology Communication Experience
By
–
Multimodal interfaces open a new stage in human–technology communication by blending voice, touch, and gestures into one coherent experience that adapts to users, enhances accessibility, and makes digital interaction feel more human and expressive. Microblog @antgrasso
-
Fine-tune DeepSeek-OCR Locally for Your Language
By
–
Fine-tune DeepSeek-OCR on your own language!
— Akshay 🚀 (@akshay_pachaar) 8 novembre 2025
(100% local)
DeepSeek-OCR is a 3B-parameter vision model that achieves 97% precision while using 10× fewer vision tokens than text-based LLMs.
It handles tables, papers, and handwriting without killing your GPU or budget.
Why it… pic.twitter.com/SfBXY4Is8oFine-tune DeepSeek-OCR on your own language! (100% local) DeepSeek-OCR is a 3B-parameter vision model that achieves 97% precision while using 10× fewer vision tokens than text-based LLMs. It handles tables, papers, and handwriting without killing your GPU or budget. Why it
-
DeepSeek OCR Project Reproduction: Quality Data Requirements
By
–
Very nice project reproducing deepseek OCR. More (good quality) data needed, but great start
-

CamCloneMaster: Reference-based Camera Control for Video Generation
By
–
CamCloneMaster
— AK (@_akhaliq) 8 novembre 2025
Enabling Reference-based Camera Control for Video Generation pic.twitter.com/l1MxjgTHICCamCloneMaster Enabling Reference-based Camera Control for Generation
-

EVTAR: End-to-End Virtual Try-On with Visual Reference
By
–
EVTAR End-to-End Try on with Additional Unpaired Visual Reference
-

SAIL-Embedding: Omni-modal Foundation Model for Recommendations
By
–
What if one embedding model could seamlessly understand text, images, user behavior, and item IDs—all while boosting real-world recommendation performance? Meet SAIL-Embedding: an omni-modal foundation model engineered for the messy realities of industrial AI. Unlike CLIP-style
-

SAIL-RL: Guiding MLLMs Thinking with Dual-Reward RL
By
–
SAIL-RL Guiding MLLMs in When and How to Think via Dual-Reward RL Tuning
-
Google Launches Gemini-Powered Hands-Free Driving and Mobile AI Features
By
–
Here's what launched this week: — The first hands-free, conversational driving experience in @googlemaps
, built with Gemini
— Flashcards and Quizzes have started rolling out in the @NotebookLM Mobile App
— Deep Research in @GeminiApp can now pull info from @gmail
,