the time is here – we're launching our 10th @raais summit speakers! first up, @jeffrey_hawke
, co-founder/cto at world simulator pioneers @odysseyml jeff's work intersects generative modelling, embodied intelligence, and large-scale learning he was prev vp tech @wayve_ai
MULTIMODAL AI
-

RAAIS Summit Announces Jeffrey Hawke as 10th Speaker
By
–
-

FOCUS: AI Method for Hour-Long Video Understanding
By
–
How can AI understand an hour-long video without being overwhelmed by massive amounts of data? Researchers from the National University of Singapore and TikTok have introduced FOCUS to solve this challenge. FOCUS is a training-free method that uses a multi-armed bandit strategy
-
OpenAI Launches GPT-5.4 with Native Computer Usage Capabilities
By
–
OpenAI launched GPT-5.4 on March 5 — first model with native computer-use built in. One system that can reason, code, and operate your desktop. That's a meaningful consolidation. openai.com/index/introducing-gpt-5-4/ #AI [Translated from EN to English]
→ View original post on X — @svenphilipsen, 2026-03-10 08:00 UTC
-

ByteDance Seed Releases Helios: Real-Time Long Video Generation Model
By
–
"Helios: Real Real-Time Long Generation Model" More video gen techniques shared by ByteDance Seed! They show you can get minute-scale and temporally stable video generation in real time by training a 14B autoregressive diffusion model to expect and correct its own
-

LangSmith Launches Multi-Modal Support for Evaluators
By
–
We just launched multi-modal support for evaluators in LangSmith! You can now pass attachments and base64 multi-modal content directly into evaluators with flexible mapping, allowing you to measure quality, safety, and performance across the full interaction end to end. Docs:
-
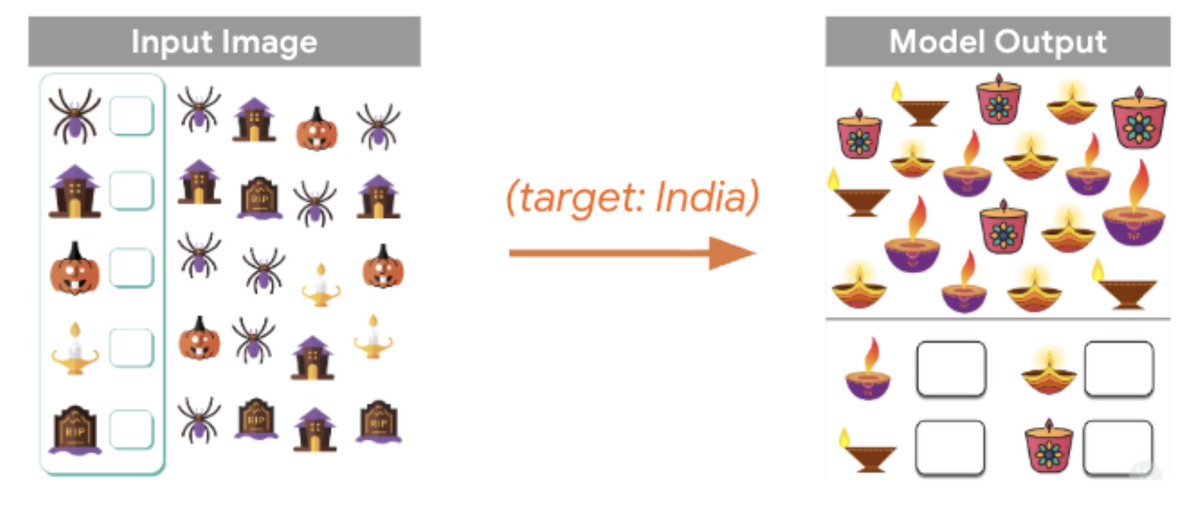
Machine Translation for Vision Challenge at CVPR 2026 MAPS Workshop
By
–
Come participate in the Machine Translation for Vision Challenge! The winners will be announced at our MAPS workshop (sites.google.com/corp/view/m…) at CVPR 2026! MAPS – CVPR 2026 Workshop (@maps_cvpr) Introducing the Machine Translation for Vision (MTV) Challenge at #CVPR2026! Can your model localize (culturally adapt) images — not just translate text, but reimagine visuals for different cultures? 🌍 — https://nitter.net/maps_cvpr/status/2031031324211843212#m
→ View original post on X — @hugo_larochelle, 2026-03-09 15:50 UTC
-

Runway Introduces Real-Time Intelligent Avatar Characters
By
–
-
Multi-modal Video AI Deployment for Large-Scale Entertainment Distribution
By
–
Scaling trustworthy video intelligence requires moving beyond basic spatial-temporal modeling. Join PYLER as they demonstrate how to deploy multi-modal video AI that maintains high accuracy and reliability across large-scale entertainment distributions. Date: Thursday,
-

MWC 2026 reveals AI integration in workplace devices and networks
By
–
What MWC 2026 Revealed About The Future Of AI At Work #MWC2026 showed that the next wave of #AI value will come from the point where #digitalintelligence meets real #work. AI is moving into devices, glasses, networks and machines, and that will reshape how organizations operate.
-

Researchers introduce Innovator-VL to reduce reliance on massive datasets
By
–
Can we build a world-class scientific AI without relying on massive, opaque datasets? Researchers from Shanghai Jiao Tong University, DP Technology, and the Chinese Academy of Sciences introduce Innovator-VL. Instead of just throwing more data at the problem, they developed a