
Traditional marketing platforms just hand brands a passive database to sort through manually. This AI-powered platform acts as an active engineering layer. Look at the depth of this automated risk screening. It systematically audits audio, video transcripts, and text history
MULTIMODAL AI
-

DiffusionOPD distills expert teachers into single student for multiple tasks
By
–
Can one diffusion model master multiple text-to-image tasks without forgetting? Researchers from Fudan University & Alibaba Group present DiffusionOPD. Instead of joint training, they first train separate expert teachers, then distill their knowledge into a single student
-

Claude Fable 5 Launch with Auto-Routing to Best Models
By
–
Claude Fable 5 Launched On ChatLLM Try it for hard-coding prompts!! Auto-route to the best model based on prompt hard-coding – Fable 5
design – Opus 4.8
video – Grok Imagine 4.5
image – GPT Image 2 Our agent will automatically find the best AI for your task -
Smart AI Voice Recorder Converts Speech to Multilingual Summaries
By
–
Smart #AI Voice Recorder Converts Speech Into Instant Multilingual Summaries
— Ronald van Loon (@Ronald_vanLoon) 10 juin 2026
by @ViralRushX#ArtificialIntelligence #Innovation #Tech #FutureTech pic.twitter.com/P5v9vpQmP4Smart #AI Voice Recorder Converts Speech Into Instant Multilingual Summaries
by @ViralRushX #ArtificialIntelligence #Innovation #Tech #FutureTech -
Beard disrupts dubbing models; clean-shaven faces recommended
By
–
*disclaimer with my video, my beard is making it hard for most if not all dubbing models out there, hence some shaking and blurring around my mouth in the dubbed version. Yours should be just fine, if you don't have a large facial beard hiding your mouth.
-
How to try Pika MCP and Language Swap Skill
By
–
How to try Pika MCP + Language Swap Skill: 1. Install or update Pika MCP in Claude Code or Codex: https://
mcp.pika.me/api/mcp
2. Run the /language-swap skill 3. Upload any video of yourself talking 4. Keep your face inside the frame 5. Choose the target language I used this -
Stop doing things that don’t matter and do what resonates
By
–
Stop doing things that don't matter.
— Linus ✦ Ekenstam (@LinusEkenstam) 9 juin 2026
Instead do things that resonates with yourself
I love making communication easy, and tearing down barriers using technology
Here I used Pika's MCP to quickly dub myself to mandarin, because I like this stuff
Time for me to go global ✌🏼 https://t.co/HDlz0gjeMs pic.twitter.com/7WnuAwDDJLStop doing things that don't matter. Instead do things that resonates with yourself I love making communication easy, and tearing down barriers using technology Here I used Pika's MCP to quickly dub myself to mandarin, because I like this stuff Time for me to go global
-
Need to Integrate VLAs and Models in Production Robotics
By
–
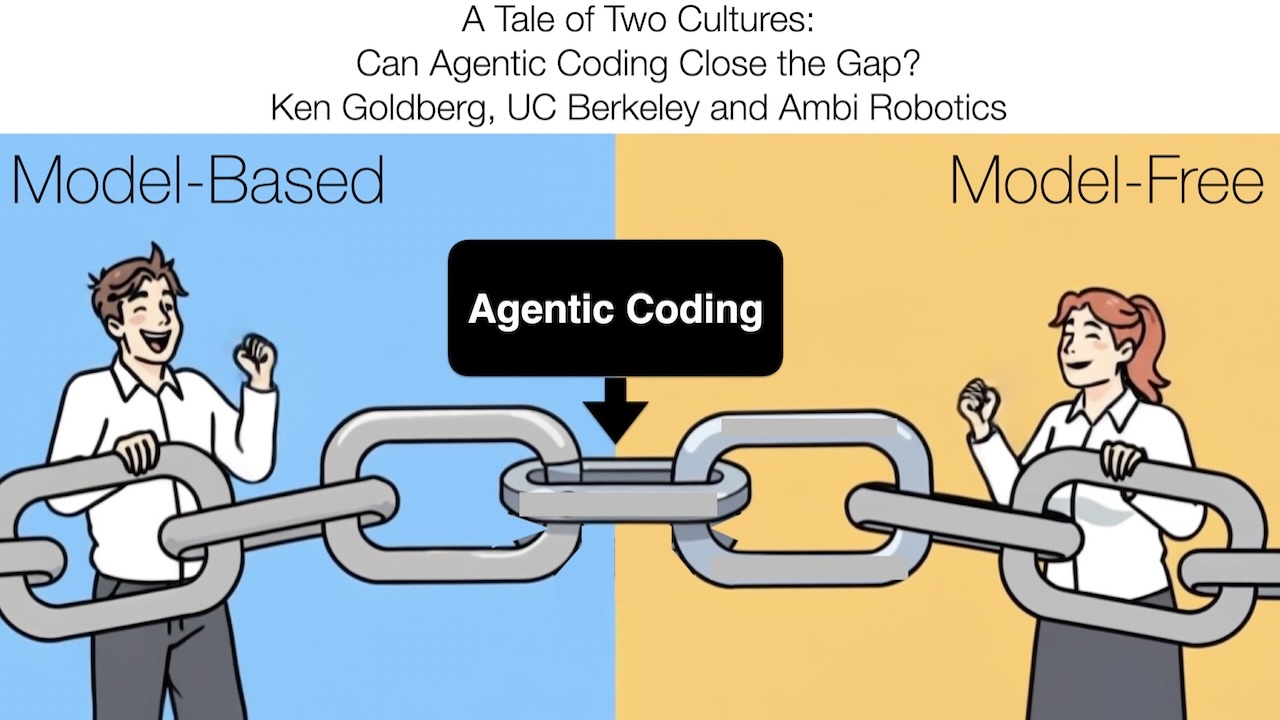
It's not VLAs versus World Models; production robotics needs both, in addition to model-based methods, all integrated by agentic coding. At ICRA last week, I presented a perspective on the divisions in our field, including
-
Gemini 3.5 Live Translate: natural real-time voice translation
By
–
What makes Gemini 3.5 Live Translate a massive step forward isn’t just the speed, it’s how it maintains natural pacing, pitch, and intonation over long conversations.
— Harold Sinnott 📱 (@HaroldSinnott) 9 juin 2026
Finally, real-time speech translation that actually sounds human. 🌍@GeminiApp @GoogleAI #AI https://t.co/uwSA1fhsCX pic.twitter.com/ZOTbgaBtw4What makes Gemini 3.5 Live Translate a significant advance is not just the speed, but the way it maintains a natural rhythm, pitch, and intonation over long conversations. Finally, a real-time voice translation that sounds
-
VQAScore: open-source framework for evaluating text-video/image/3D models
By
–
VQAScore, a simple framework for evaluating text-video/image/3d models is opensource and got many many features. Packaged with leading frontier and commonly used open-source multimodal models and simple/clean eval interface. https://t.co/8xy7SjGEqt pic.twitter.com/wrt6wBTQvQ
— Jean de Nyandwi (@Jeande_d) 9 juin 2026VQAScore, a simple framework for evaluating text-video/image/3d models is opensource and got many many features. Packaged with leading frontier and commonly used open-source multimodal models and simple/clean eval interface.