
"Mastering PyTorch: Create and deploy deep learning models from CNNs to multimodal models, LLMs, and beyond" – http://amzn.to/40IFEQR via @PacktDataML #AI #ML #MachineLearning #DataScience #DataScientist #GenAI
MULTIMODAL AI
-
ElevenLabs Launches Flows: Visual Pipeline for AI Content Creation
By
–
🚨ElevenLabs just launched Flows – yep! a game changer for content creators.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 28 mars 2026
Instead of jumping between 10 different tools to make one video, you can now build the entire pipeline in one visual canvas.
Here's what Flows can do:
→ Connect 35+ image & video models (Sora, Kling,… pic.twitter.com/vjR12QOolPElevenLabs just launched Flows – yep! a game changer for content creators. Instead of jumping between 10 different tools to make one video, you can now build the entire pipeline in one visual canvas. Here's what Flows can do:
→ Connect 35+ image & video models (Sora, Kling, -
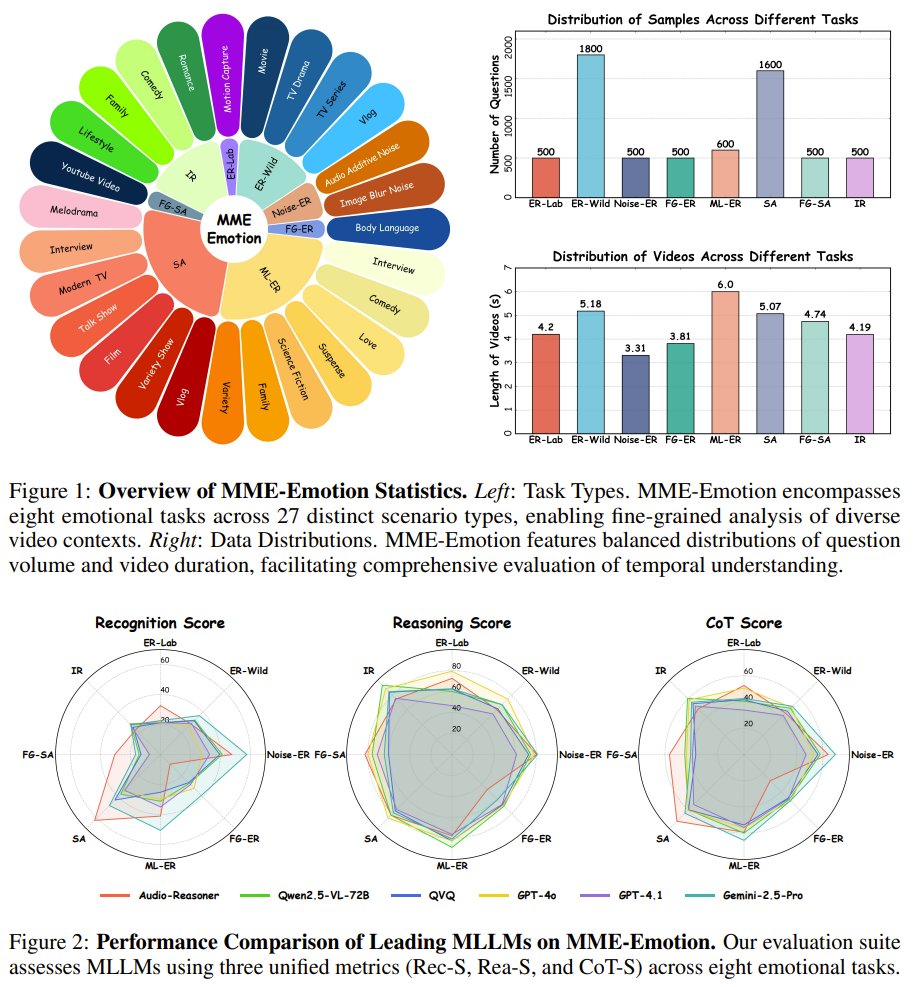
MME-Emotion: Benchmarking Emotional Intelligence in Advanced AI Models
By
–
How truly emotionally intelligent are our most advanced AI models? A massive collaboration led by Fan Zhang et al. from The Chinese University of Hong Kong, Tongyi Lab, SZTU, and Tencent, introduces MME-Emotion. This groundbreaking benchmark, the largest of its kind, uses over
-
Moondream 3 MPS Compatibility Tweaks for Apple Silicon
By
–
Moondream 3 doesn't work on Apple MPS out of the box but a a couple of tweaks can make it work.
— Satya Mallick (@LearnOpenCV) 28 mars 2026
1. use float16 on MPS
2. disable flex decoding on MPS (and CPU fallback)
You can also make it work on the CPU, but that option is really bad. It is about 20x slower than MPS. https://t.co/GbdBWMEnVXMoondream 3 doesn't work on Apple MPS out of the box but a a couple of tweaks can make it work. 1. use float16 on MPS
2. disable flex decoding on MPS (and CPU fallback) You can also make it work on the CPU, but that option is really bad. It is about 20x slower than MPS. -
Meta Open-Sources TRIBE v2 Brain Response Foundation Model
By
–
🧠 Meta just open-sourced TRIBE v2 – a foundation model that simulates how the human brain responds to sight, sound & language.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 28 mars 2026
Months of lab work. Now done in seconds.
Here's what makes it different:
🔹 Predicts fMRI-style brain responses across 70,000 neural points
🔹 Often… pic.twitter.com/lul9VgwjhmMeta just open-sourced TRIBE v2 – a foundation model that simulates how the human brain responds to sight, sound & language. Months of lab work. Now done in seconds. Here's what makes it different: Predicts fMRI-style brain responses across 70,000 neural points Often
-
China Unveils Next-Generation Robot Wolf Pack Technology
By
–
China releases footage of next-gen robot wolf pack! https://
youtu.be/kGVgOzDJx44?si
=PqbQpy4aqECk_NKE
… via @YouTube #humanoidtech #humanoid #robot #Robotics #AI #TechRevolution #TechInnovation #ArtificialInteligence #PhysicalAI @AlbertoEMachado @Eli_Krumova @postoff25 @Khulood_Almani @anand_narang -
Intense Forest Hunting Scene with Mysterious Creature
By
–
Prompt: Highly intense scene of the hunter sneaking through the forest and getting ambushed by a large furry creature
— Nicolas Neubert (@iamneubert) 28 mars 2026
Made using Runway's Multi-Shot App pic.twitter.com/tbSLozQ69ePrompt: Highly intense scene of the hunter sneaking through the forest and getting ambushed by a large furry creature Made using Runway's Multi-Shot App [Translated from EN to English]
-
Computer Use AI Tools: Mac App and Peekaboo Integration
By
–
computer use should work decent, there is the mac app and peekaboo
-
Share Gemini with Image and Demo Link
By
–
g.co/gemini/share/bedde20a01… [Translated from EN to English]
→ View original post on X — @thegautamkamath, 2026-03-27 23:37 UTC
-
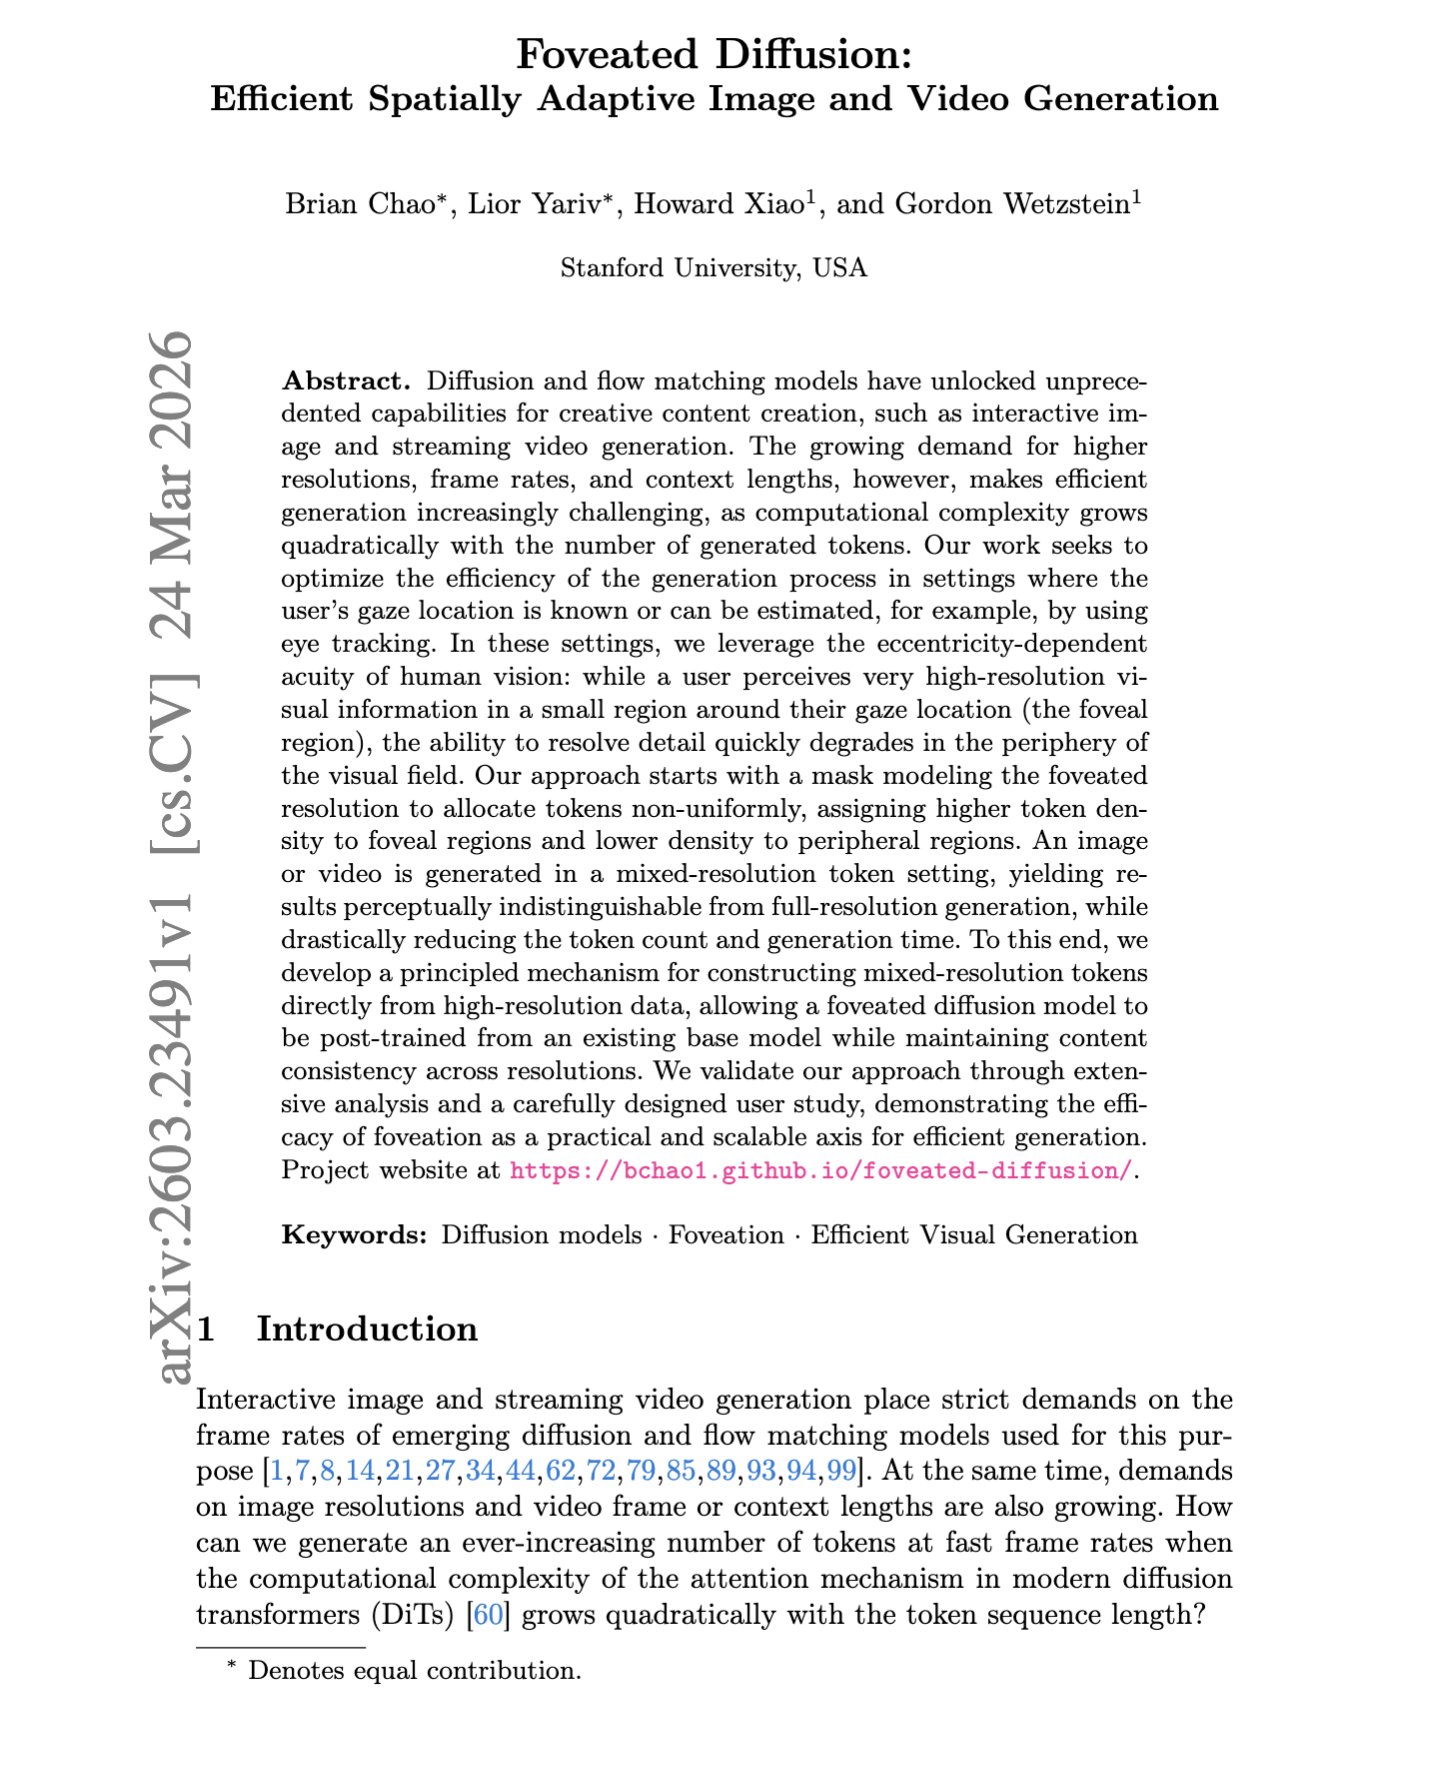
Foveated Diffusion: Efficient Spatially Adaptive Image Video Generation
By
–
"Foveated Diffusion: Efficient Spatially Adaptive Image and Generation" This paper introduces the logic of human vision to diffusion models, where you generate full detail only when the viewer is looking, and becomes low detail in the periphery. With this setup, you can