Alibaba's Wan 2.7-Image is now live on Poe. Generate a cohesive set of images from a single prompt with consistent characters, style, and context. Bounding box editing lets you refine specific regions without regenerating the whole image. You can try it in Poe app on all
MULTIMODAL AI
-
Open-source plugin optimizes Claude Code with multi-agent coordination
By
–
Your Claude Code setup is 3x slower than it could be right now.
— AlphaSignal AI (@AlphaSignalAI) 2 avril 2026
An open-source plugin can now run 32 specialized AI agents inside Claude Code.
Zero new tools. Zero learning curve.
The project is called oh-my-claudecode.
It coordinates Claude, Gemini, and Codex through tmux… pic.twitter.com/XdA0p71JIEYour Claude Code setup is 3x slower than it could be right now. An open-source plugin can now run 32 specialized AI agents inside Claude Code. Zero new tools. Zero learning curve. The project is called oh-my-claudecode. It coordinates Claude, Gemini, and Codex through tmux
-
Microsoft Super Intelligence Team Achieves Major Milestones in AI
By
–
Huge congrats to the Microsoft Super Intelligence (MSI) team for shipping another model. In about 6 months, this team build one of the best if not the best transcribe model in the world, all while also build the best generative audio models in the world.
— Nando de Freitas (@NandoDF) 2 avril 2026
My recommendation to… https://t.co/WnXwlVsqG4Huge congrats to the Microsoft Super Intelligence (MSI) team for shipping another model. In about 6 months, this team build one of the best if not the best transcribe model in the world, all while also build the best generative audio models in the world. My recommendation to
-
P-Image-Upscale: Fast and Affordable Image Enhancement
By
–
New from Pruna AI: The P-Image-Upscale endpoint boosts image resolution with sharper details in under a second.
— Pruna AI (@PrunaAI) 2 avril 2026
Get up to 8 MP output for just $0.005 per call.
Get more info at: https://t.co/NkR46ADcGA
Sign up for the Pruna API: https://t.co/KOtwuEWaj4
Try it directly on… pic.twitter.com/LoFBKY0q8bNew from Pruna AI: The P-Image-Upscale endpoint boosts image resolution with sharper details in under a second. Get up to 8 MP output for just $0.005 per call. Get more info at: pruna.ai/p-image-upscale
Sign up for the Pruna API: dashboard.pruna.ai/
Try it directly on @replicate: replicate.com/deployments/prunaai/p-image-upscale Quick, affordable image upscaling for your apps. ✉️ Contact: pruna.ai/contact
⭐️ Star our OSS: github.com/PrunaAI/pruna
📚 API & quickstart: docs.api.pruna.ai/guides/quickstart [Translated from EN to English]→ View original post on X — @replicate, 2026-04-02 14:01 UTC
-
Microsoft Announces 3 New World-Class MAI Models in Foundry
By
–
More on the blog today: microsoft.ai/news/today-were…
-
Microsoft Releases MAI-Transcribe-1 Transcription Model
By
–
Three models. Three top-tier results. All shipped within just a few months by the @MicrosoftAI team.
— Mustafa Suleyman (@mustafasuleyman) 2 avril 2026
– MAI-Transcribe-1 dropped today, the most accurate transcription model in the world across 25 languages according to FLEURS WER benchmark.
– MAI-Voice-1 sets a new standard for… pic.twitter.com/rfwqcEaxR8Three models. Three top-tier results. All shipped within just a few months by the @MicrosoftAI team.
– MAI-Transcribe-1 dropped today, the most accurate transcription model in the world across 25 languages according to FLEURS WER benchmark.
– MAI-Voice-1 sets a new standard for -

LLaMA-Factory: Fine-Tune 100+ LLMs Without Coding
By
–
If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/203… Sumanth (@Sumanth_077) Fine-Tune 100+ LLMs without writing a single line of code! LLaMA-Factory lets you train and fine-tune open-source LLMs and VLMs without writing any code. Here's why it's a game changer for fine-tuning: • Fine-tune 100+ LLMs/VLMs with built-in templates (LLaMA, Gemma, Qwen, Mistral, DeepSeek, and more). • Zero-code CLI & Web UI for training, inference, merging, and evaluation. • Supports full-tuning, LoRA, QLoRA, freeze-tuning, PPO/DPO, OFT, reward modeling, and multi-modal fine-tuning. • Speeds up training/inference with FlashAttention-2, RoPE scaling, Liger Kernel, and vLLM backend. • Integrates experiment tracking via LlamaBoard, TensorBoard, Weights & Biases, MLflow, and SwanLab. It's 100% Open Source Link to the Github Repo in the comments! — https://nitter.net/Sumanth_077/status/2039701710659272775#m
→ View original post on X — @sumanth_077, 2026-04-02 13:50 UTC
-
Point Tracks as Tokens for Complex Motion Forecasting
By
–
What’s the right representation for a world model? 3D, pixels, or something else? Excited to release our new paper “Forecasting Motion in the Wild” where we propose point tracks as tokens for generating complex non-rigid motion and behavior From @GoogleDeepmind @Berkeley_AI @TTIC_Connect
→ View original post on X — @berkeley_ai, 2026-04-02 13:50 UTC
-

Alibaba releases Qwen 3.6 Plus with coding and vision
By
–
Alibaba released Qwen 3.6 Plus, an upgraded agentic model with coding and vision capabilities. Qwen 3.6 Plus comes with a 1M context window and is already available on Qwen Chat. https://
x.com/Alibaba_Qwen/s
/Alibaba_Qwen/status/2039697007489765727
… -
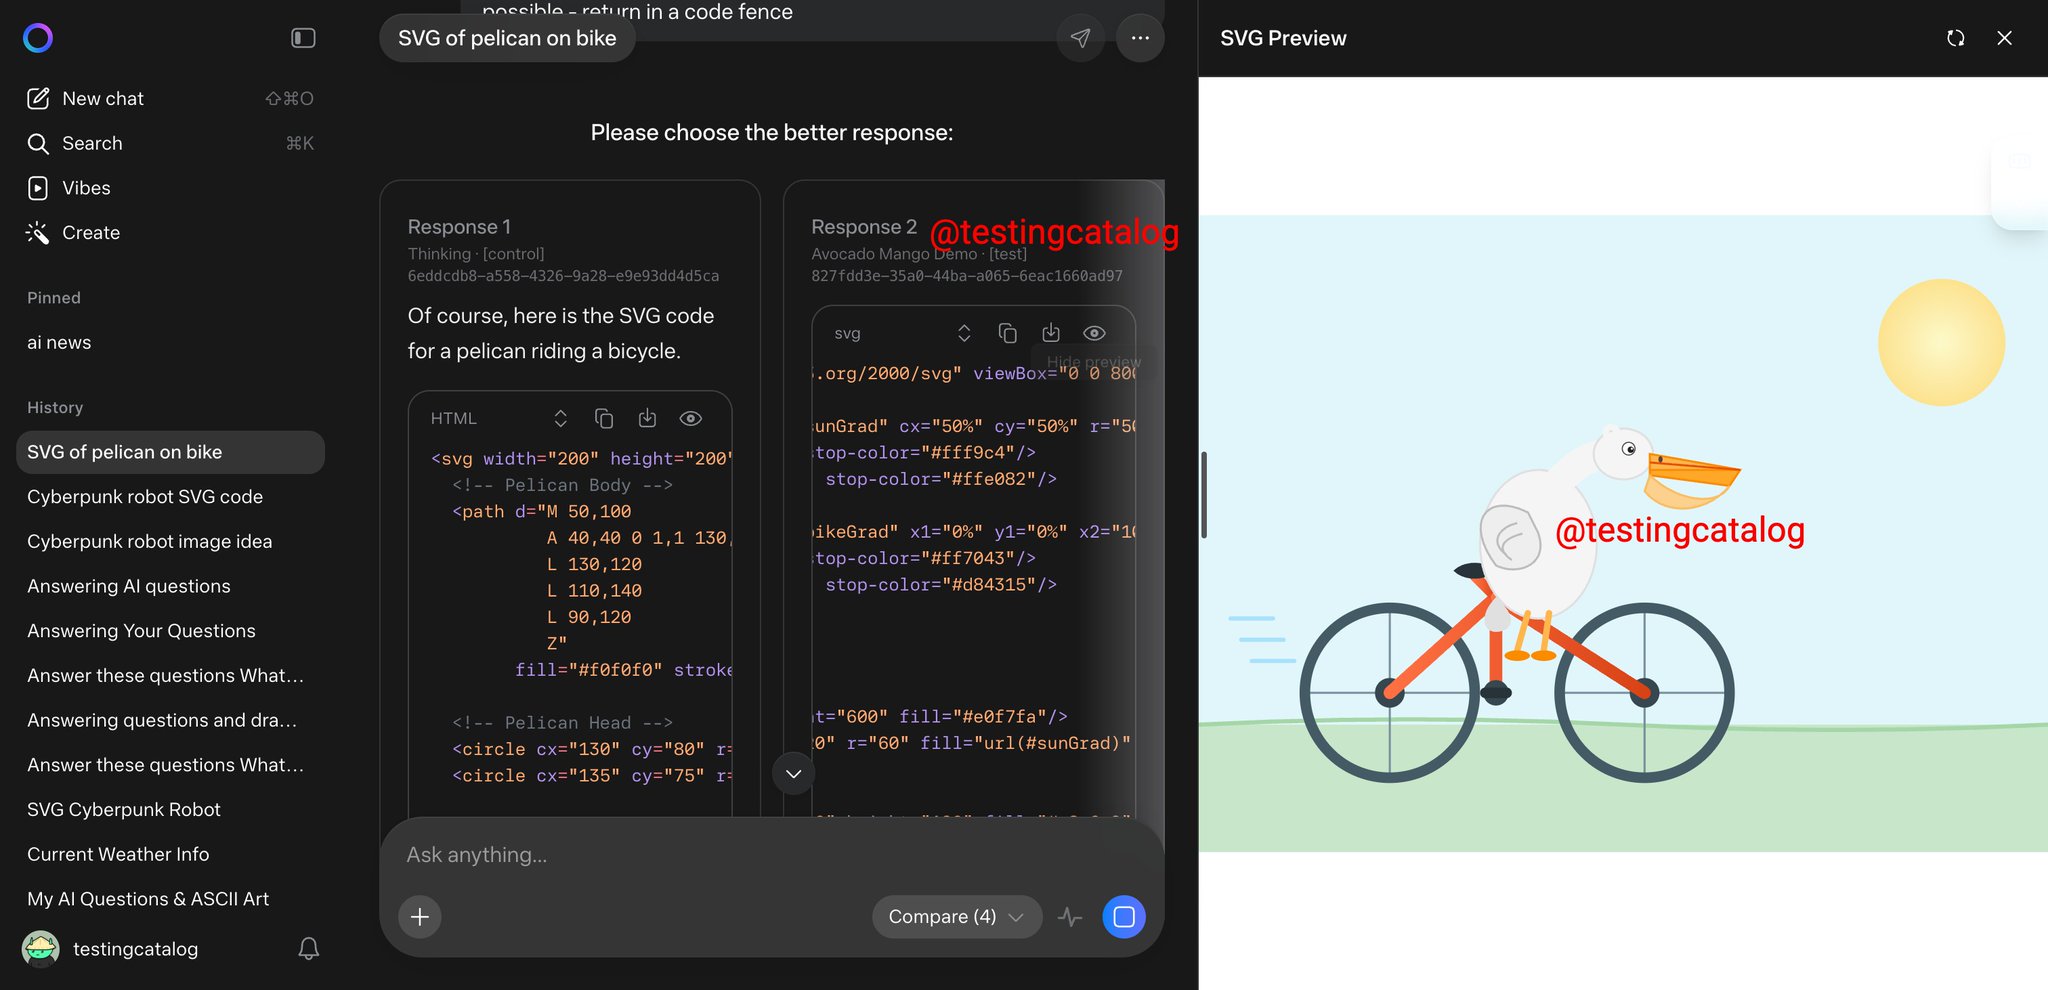
Meta Tests New AI Models and Agents
By
–
BREAKING : Meta is testing a new Paricado model family as well as Health and Document agents. Additionally, the first "pelican riding on the bike" examples from the Avocado model have been received.