
#47 FILTRACIÓN Al igual que el agua que se cuela por las grietas de tu casa, con las IAs de generación por texto existe el concepto de FILTRADO DE ATRIBUTOS. Fíjate en la imagen anterior cómo a pesar de haberle pedirle un CACTUS AZUL, el color se ha filtrado hacia el zapato.
MULTIMODAL AI
-

Midjourney Fashion Design: Generate Stunning Model Dresses AI
By
–
#44 DISEÑO DE MODA Y MJ se atreve con todo. Puedes probar con conceptos como «Tetris» o «Arrecife de Coral» y sorprendeos con los resultados! ELIGE ESTILO "top model wearing a fashion dress inspired on [ESTILO], studio light, photorealistic, hyperrealistic, 8K"
-
AI Generates Protein Blueprints Using Generative Art Techniques
By
–
“What can machines do that humans can’t do at all?” Using the techniques that underpin A.I. art generators like DALL-E, scientists are generating blueprints for new proteins — tiny biological mechanisms that can change the way of our bodies behave:
-
Dexterous Manipulation in Real Life Applications
By
–
dexterous manipulation in real life 👀 https://t.co/zOvBfvoeLi
— Yutaro Yamada (@_yutaroyamada) 8 janvier 2023dexterous manipulation in real life
-
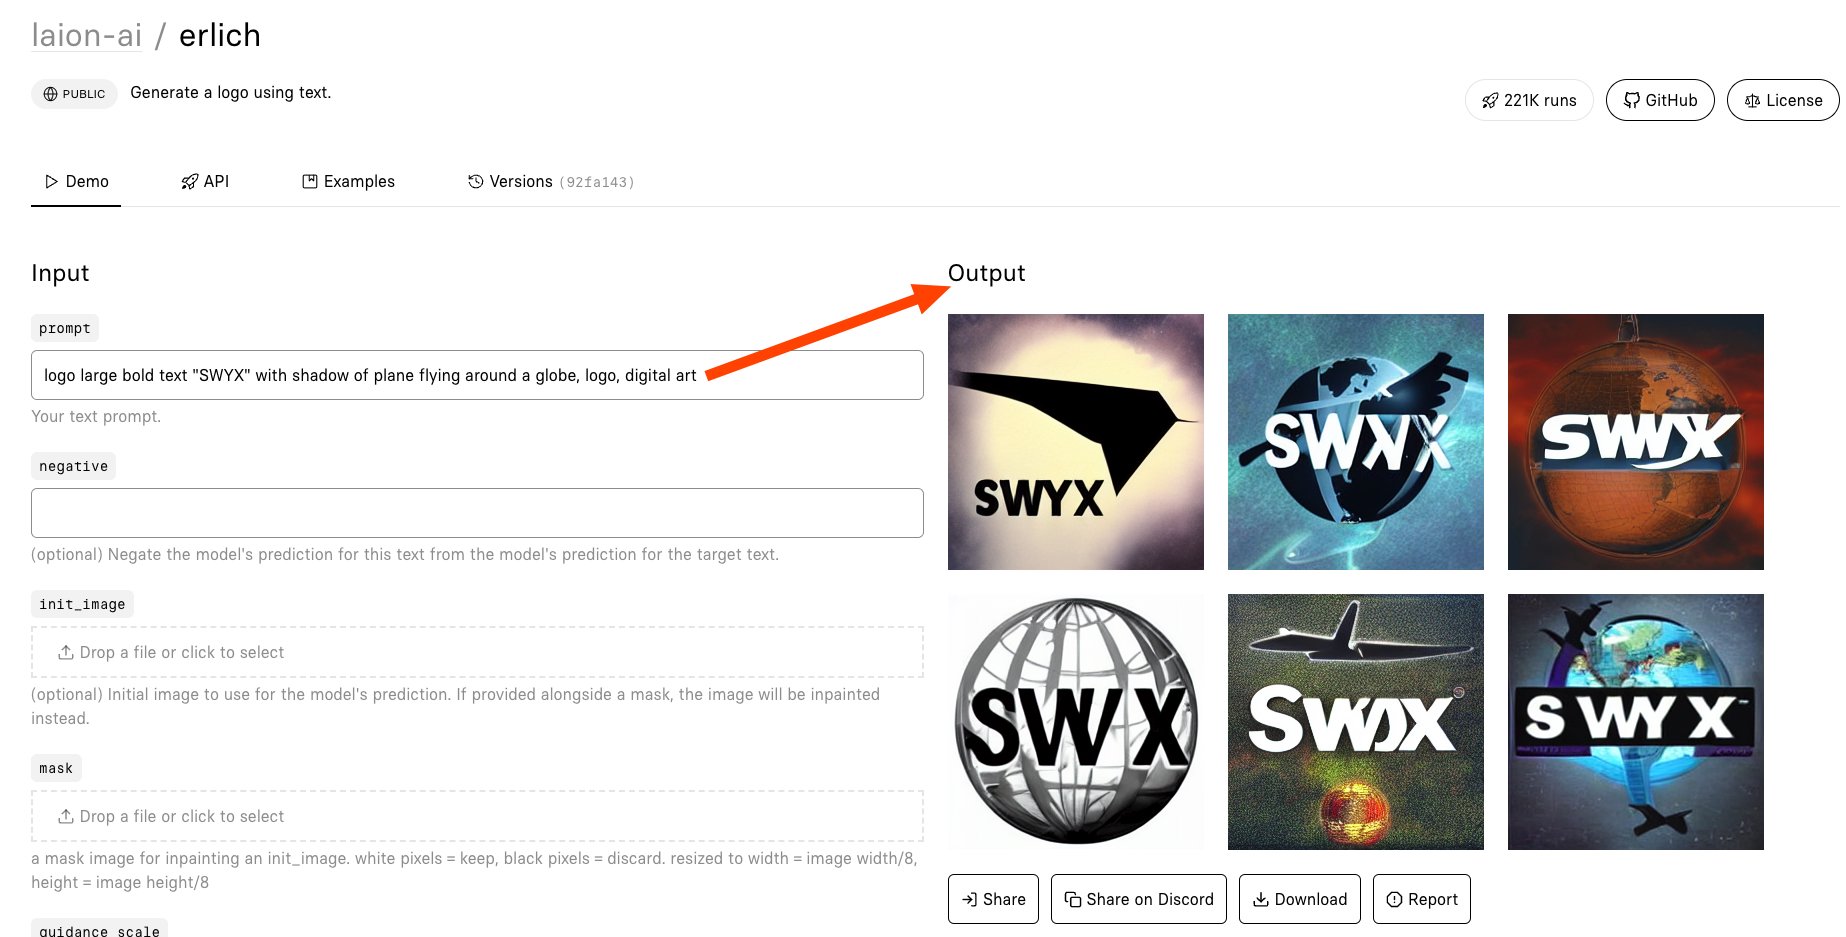
2022 Visual Text States of the Art from LAION and SavvyRL
By
–
Couple more 2022 visual text States of the Art from @laion_ai and @savvyRL et al (which was even more slept on!!)
-
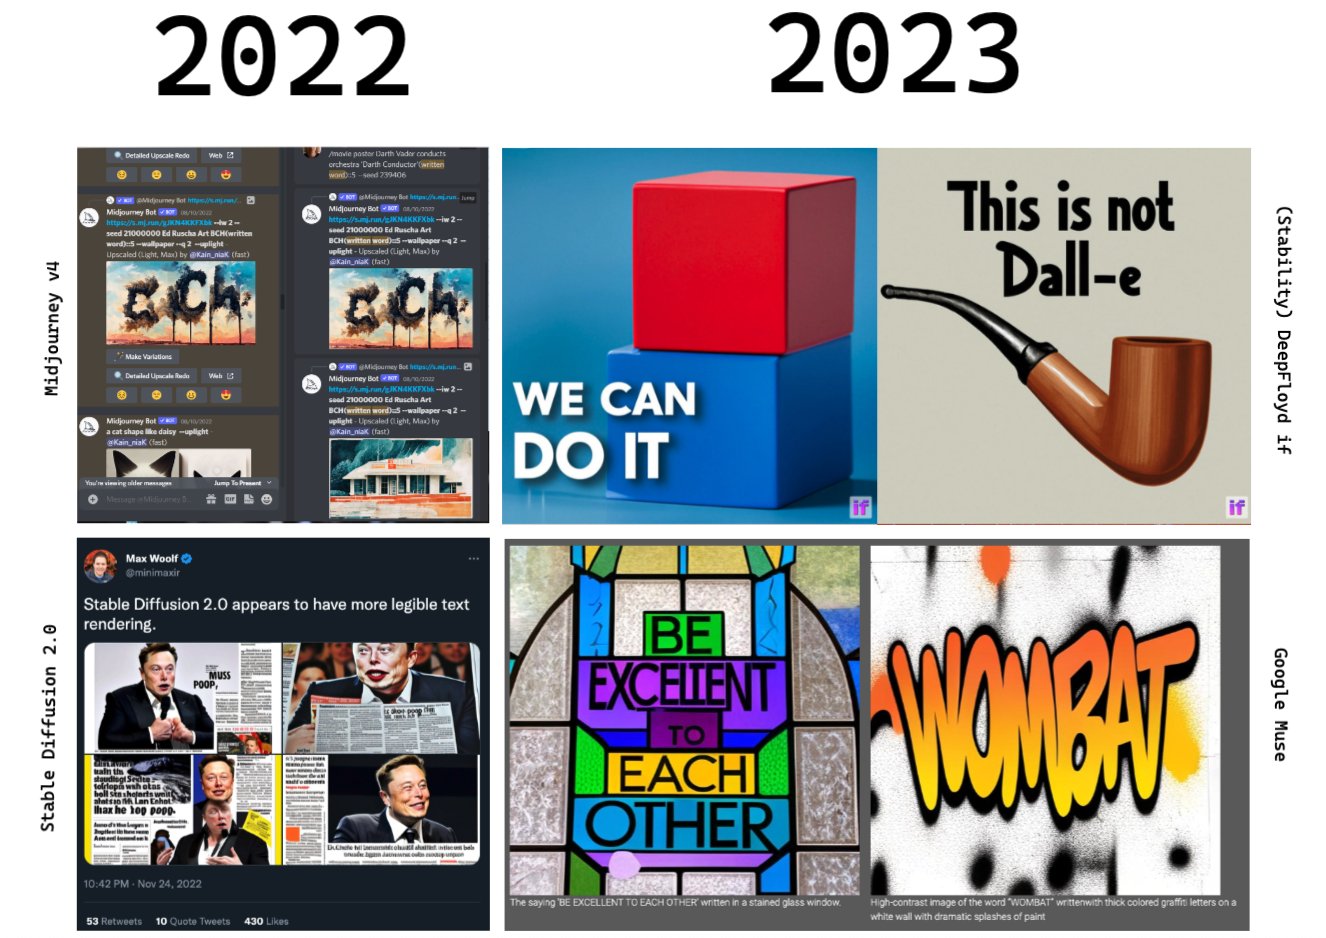
Text-to-Image Visual Text Rendering Problems Solved Early 2023
By
–
I am still not over how we are 1 (ONE) week into 2023 and the big Text-to-Image visual text rendering problems of last year appears to be completely solved… (with a new architectural approach to boot! Rumors that hands might be solved too) Diffusion models are so 2022?
-
Community-Powered Text-to-Image Generation Platform Upgrade
By
–
Want to step up your text-to-image generation game by tapping on to tens of thousands of community generated images? Stay tuned!
-
Technical mechanism of AI-driven voice synthesis
By
–
It generates a series of codes based on the phonemes and an audio recording of the speaker's voice.
— AI Breakfast (@AiBreakfast) 7 janvier 2023
These codes are then turned directly into a waveform, which allows it to generate speech that sounds like the speaker from just a small amount of reference audio.
Example (🔊): pic.twitter.com/HQvjJUnbiHIt generates a series of codes based on the phonemes and an audio recording of the speaker's voice. These codes are then turned directly into a waveform, which allows it to generate speech that sounds like the speaker from just a small amount of reference audio. Example ():
-
Technical architecture of the VALL-E generative audio model
By
–
Instead of turning text into a series of specific sounds (called phonemes) and then into a visual representation of the sound called a mel-spectrogram, and then into a waveform (a digital representation of sound that can be played through a speaker) VALL-E takes a shortcut:
-
VALL-E: A new approach to natural-sounding AI speech synthesis
By
–
VALL-E is significantly better at synthesizing natural-sounding speech and accurately reproducing the characteristics of a speaker compared to anything else available. VALL-E takes a different approach than previous systems for synthesizing speech: