Y es que a diferencia de Stable Diffusion, DALL-E, Midjourney e Imagen, este modelo no usa las modernas arquitecturas de Diffusion. Sino que recupera la tendencia de 2021: los Transformers y las VQGAN. ¿Y eso qué es…? Pues aquí te lo explico
MULTIMODAL AI
-
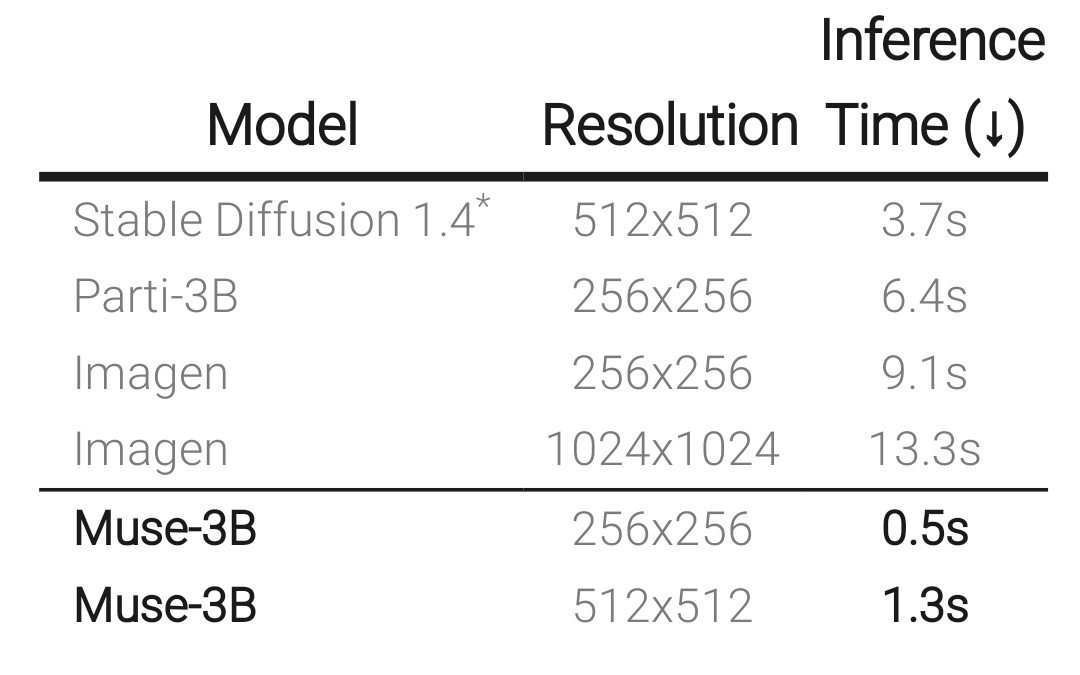
Muse generates images 3x faster than Stable Diffusion
By
–
Por último, otra cualidad más de Muse es que es MÁS RÁPIDO que sus otros compañeros, logrando generar imágenes ~3 veces más rápido que Stable Diffusion y entre 8-10 veces más rápido que su hermano mayor, Imagen.
-
Comparative Visualization for AI Image Generation Solutions
By
–
Will be good to prepare a comparative visualization for all the AI image generation solutions out there! Will start working on it soon!!
-
Hand Movement Control with Uploaded Images in AI Systems
By
–
Were you able to move hands with an uploaded image? Haven't been able to yet
-

Most Impactful Emerging Technologies for Business Predicted
By
–
Do you agree with #chatgpt3? >>> What do you predict will be the most impactful #EmergingTech on business? >>> #AI #Analytics #Automation #ImageRecognition #NLP >>> #CES2023
-

AI-Generated Selfies Through Time: From Ancient Rome to Present
By
–
Esta cuenta, usando Stable Diffusion, nos hace viajar a través del tiempo mediante selfies creados con IA. Y aquí ya se ha superado llevándonos al origen del meme, en la Roma del 46 a.c Maravilloso!
-
Limitations of bulk conversion services for short-form video content
By
–
these services might be suitable for bulk conversion tasks (e.g. an audiobook or other long-form stuff) but for smaller tasks like videos (ads, voiceover, etc) they are still (even the best ones) lacking in their tone, cadence, and emote
-

AI Model Predicts Car Price Make Model From Photo
By
–
Predicting price/make/model/etc from a photo of a car. Pretty cool that these days you can do this kind of thing as a side project.
-
AI Advances in Human-Like Edge Detection with Line Drawing Models
By
–
Human-like edge detection has been a complex problem in Computer Vision for decades, but it is getting much better:
— AI Breakfast (@AiBreakfast) 1 janvier 2023
"Learning to generate line drawings that convey geometry and semantics" – links, demo, and paper below ↓ pic.twitter.com/Vb7r4wADXmHuman-like edge detection has been a complex problem in Computer Vision for decades, but it is getting much better: "Learning to generate line drawings that convey geometry and semantics" – links, demo, and paper below ↓
-
2023 Tech Wishes: AI, Learning, Video, Open Models, Robotics
By
–
In 2023, may your: – Generative AI produce beautiful images & text
– Active Learning framework ask the right questions – generations be as beautiful as image
– Model be OSS without censors
– Robotics simulation be faithful to real world Happy New Year everyone!