
Predicting price/make/model/etc from a photo of a car. Pretty cool that these days you can do this kind of thing as a side project.
MULTIMODAL AI
-
AI Advances in Human-Like Edge Detection with Line Drawing Models
By
–
Human-like edge detection has been a complex problem in Computer Vision for decades, but it is getting much better:
— AI Breakfast (@AiBreakfast) 1 janvier 2023
"Learning to generate line drawings that convey geometry and semantics" – links, demo, and paper below ↓ pic.twitter.com/Vb7r4wADXmHuman-like edge detection has been a complex problem in Computer Vision for decades, but it is getting much better: "Learning to generate line drawings that convey geometry and semantics" – links, demo, and paper below ↓
-
2023 Tech Wishes: AI, Learning, Video, Open Models, Robotics
By
–
In 2023, may your: – Generative AI produce beautiful images & text
– Active Learning framework ask the right questions – generations be as beautiful as image
– Model be OSS without censors
– Robotics simulation be faithful to real world Happy New Year everyone! -
Advances in Surgical AI: Skill Assessment and Patient Outcome Prediction
By
–
We made strides in surgical #AI which involves assessing the skill of surgeons, predicting patient outcomes, and discovering novel surgeon biomarkers based on multi-modal data and deep learning algorithms. @AjhungMD gives an excellent overview here
-
Robust Vision Transformer Architecture Wins Semantic Segmentation Challenge
By
–
We also developed robust vision transformer architecture, fully attention networks (FAN), with channel-based attention for robustness. We won the Semantic Segmentation Tracking of Robust Vision Challenge at ECCV. https://
arxiv.org/abs/2210.12852 -
Vision Transformer Citations: Identifying False Positives in Scholar Data
By
–
I feel like this might be picking up some false positives. Scholar also says that the vision transformer paper (
https://
arxiv.org/abs/2010.11929) only has about 10k citations total. There must be some way to see how many are from 2022… -
OpenAI Whisper Speech Recognition Model Added to Hugging Face
By
–
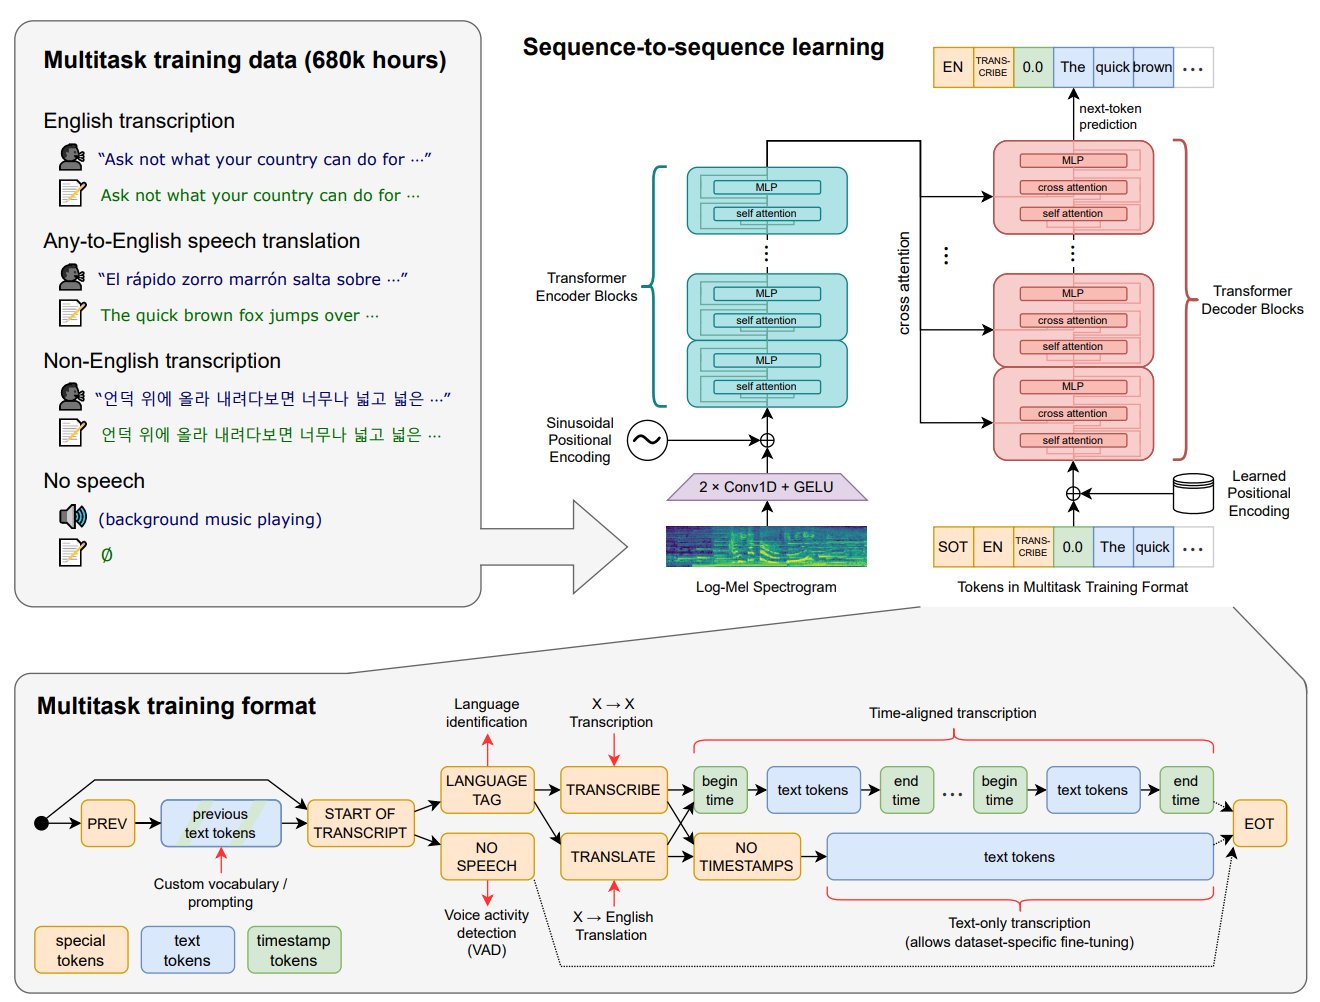
In October, Whisper, a state-of-the-art audio model from @OpenAI for speech recognition was added to the library. https://
huggingface.co/docs/transform
ers/model_doc/whisper
… -

LayoutLM v3 Multimodal Model Added for Document Analysis
By
–
LayoutLM v3 (also from @MSFTResearch
) was added to the library in June. It is a multimodal model combining vision and text for document analysis. -
Doubling AI Model Architectures: New Audio, Vision and Multimodal Models
By
–
We doubled the number of architectures (89 to 167) with new models in audio, text, vision, multiple modalities or even time seriesand protein folding Here are a few highlights in the most used of those new models
-
Swin Transformer Vision Model for Image Classification Detection
By
–
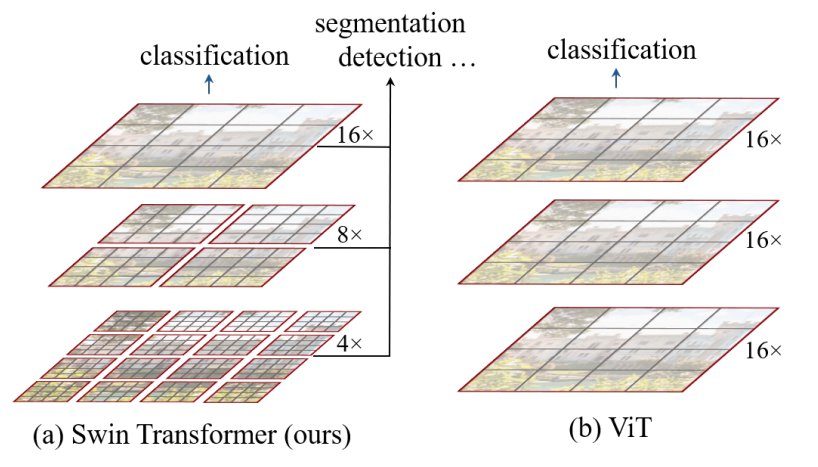
Swin Transformer is a vision model from @MSFTResearch added back in January, which can be used as backbone for a variety of tasks such as image classification, object detection or semantic segmentation. https://
huggingface.co/docs/transform
ers/model_doc/swin
…