We made strides in surgical #AI which involves assessing the skill of surgeons, predicting patient outcomes, and discovering novel surgeon biomarkers based on multi-modal data and deep learning algorithms. @AjhungMD gives an excellent overview here
MULTIMODAL AI
-
Robust Vision Transformer Architecture Wins Semantic Segmentation Challenge
By
–
We also developed robust vision transformer architecture, fully attention networks (FAN), with channel-based attention for robustness. We won the Semantic Segmentation Tracking of Robust Vision Challenge at ECCV. https://
arxiv.org/abs/2210.12852 -
Vision Transformer Citations: Identifying False Positives in Scholar Data
By
–
I feel like this might be picking up some false positives. Scholar also says that the vision transformer paper (
https://
arxiv.org/abs/2010.11929) only has about 10k citations total. There must be some way to see how many are from 2022… -
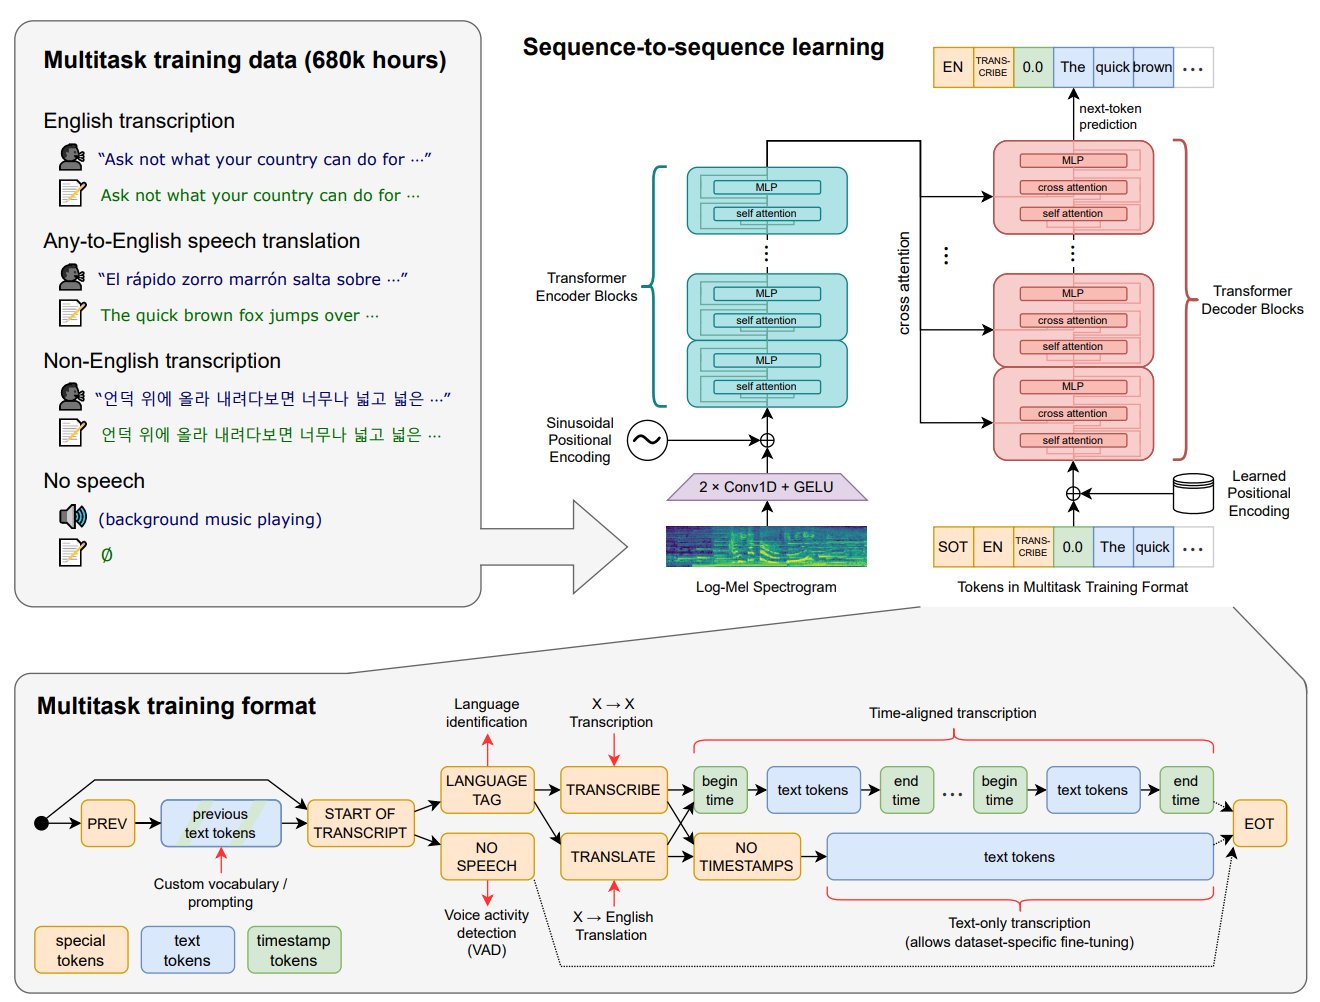
OpenAI Whisper Speech Recognition Model Added to Hugging Face
By
–
In October, Whisper, a state-of-the-art audio model from @OpenAI for speech recognition was added to the library. https://
huggingface.co/docs/transform
ers/model_doc/whisper
… -

LayoutLM v3 Multimodal Model Added for Document Analysis
By
–
LayoutLM v3 (also from @MSFTResearch
) was added to the library in June. It is a multimodal model combining vision and text for document analysis. -
Doubling AI Model Architectures: New Audio, Vision and Multimodal Models
By
–
We doubled the number of architectures (89 to 167) with new models in audio, text, vision, multiple modalities or even time seriesand protein folding Here are a few highlights in the most used of those new models
-
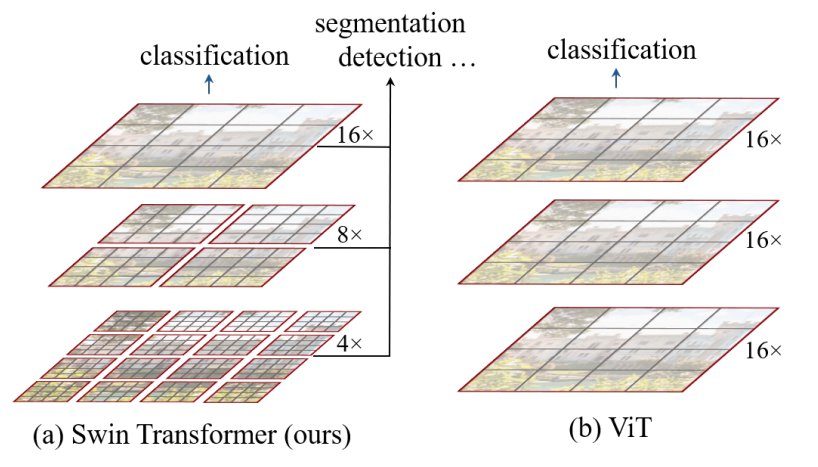
Swin Transformer Vision Model for Image Classification Detection
By
–
Swin Transformer is a vision model from @MSFTResearch added back in January, which can be used as backbone for a variety of tasks such as image classification, object detection or semantic segmentation. https://
huggingface.co/docs/transform
ers/model_doc/swin
… -
Google AI Interpolates 3D Worlds from Online Photos
By
–
Google AI starts to interpolate the world into 3D spaces based entirely on photos found online pic.twitter.com/rTaqtWNcFq
— AI Breakfast (@AiBreakfast) 30 décembre 2022Google AI starts to interpolate the world into 3D spaces based entirely on photos found online
-
New AI Chat Interface Offers Natural Speech and Reduced Latency
By
–
Okay, I’m cleared to say more. It’s like ChatGPT, but the speech is more natural and terse, like texting. Much better latency (hope it lasts). Social sharing good enough to replace sharing screenshots on Twitter. Here’s me talking to Poe: https://
poe.quora.com/s/YPMAqBPuDShG
g3kl1mbt
… -

AI image generation bias: golden retrievers as blonde women
By
–
Also interesting how AI repeatedly generates blonde women with long hair if you ask for a golden retriever, makes sense I guess