Coexist – I feel like world labs and models like it are at the Midjourney v2/3 stage rn. They’ll get more photorealistic, support larger generations. Meanwhile density of capture requirements on the reality capture / radiance field end will go down.
MARKET TRENDS
-
Anthropic Launches Claude Design for AI-Generated Visuals
By
–
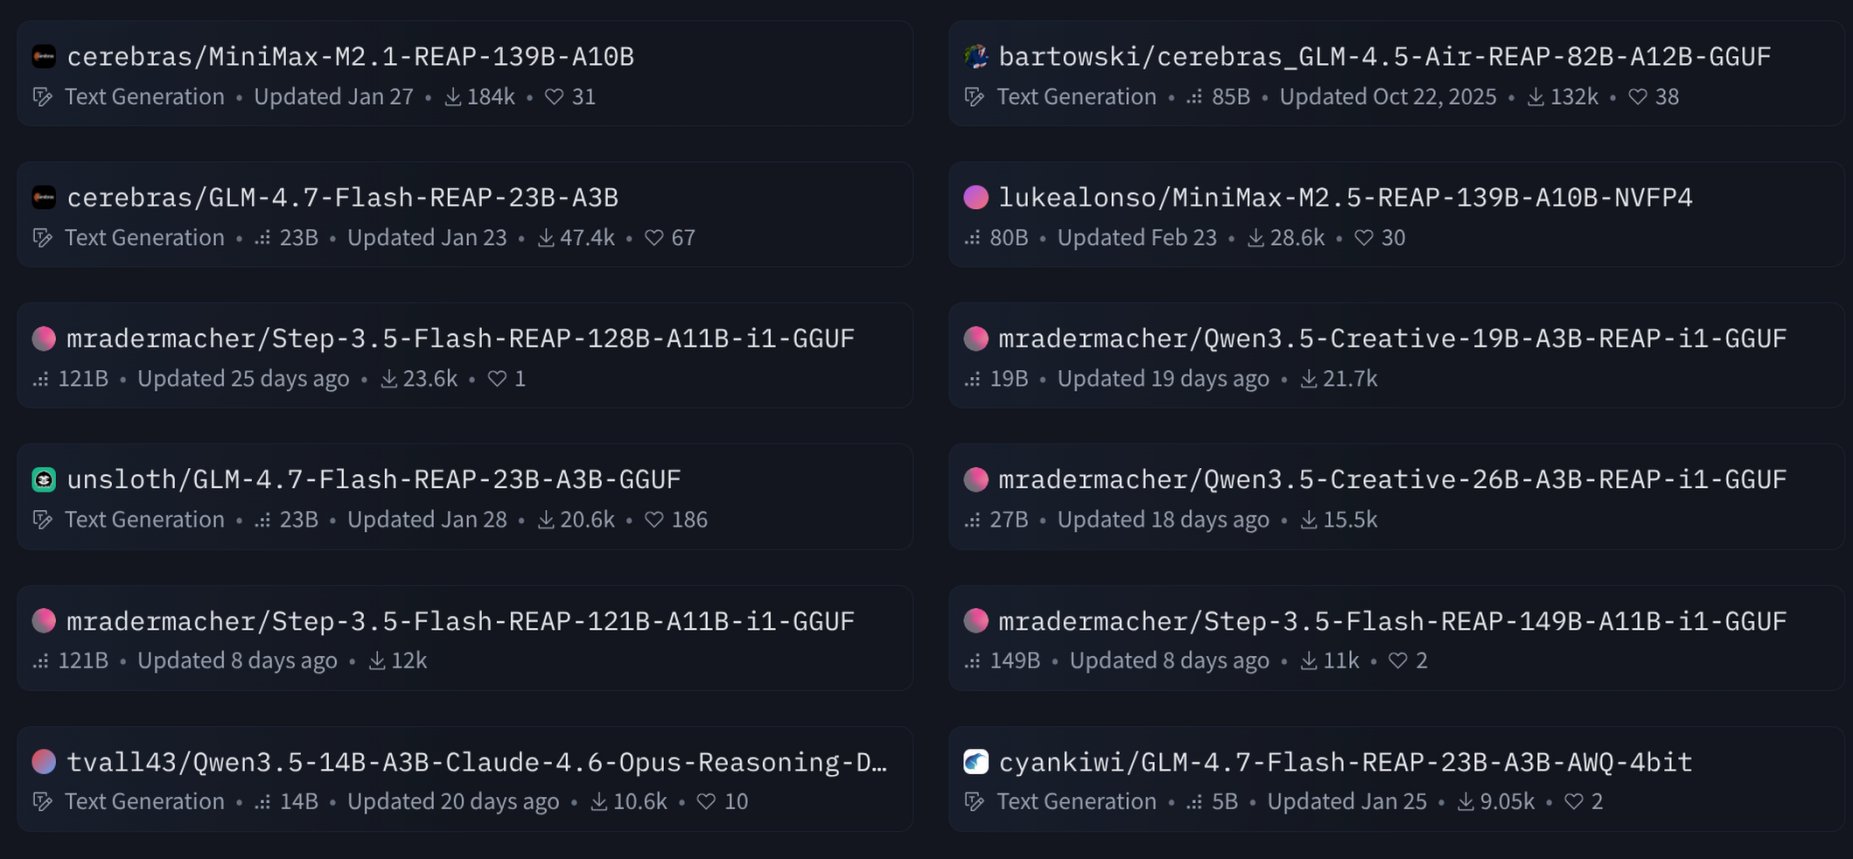
Same answer I told the guy below except it'll be the 35B
-
Tesla’s Long-Life Cars Could Disrupt Upgrade Cycles, Affecting Bear Case
By
–
This guy touches on it well in his posts
-
Meta’s LLM Strategy: Competing with Free ChatGPT for Everyday Users
By
–
Meta has one advantage: their LLM doesn't necessarily have to be SATA. It just has to be good enough that 99% of their Instagram and Facebook users consider it at least as useful as ChatGPT in the free tier; The use case for 99% of users is answers to everyday questions and
-
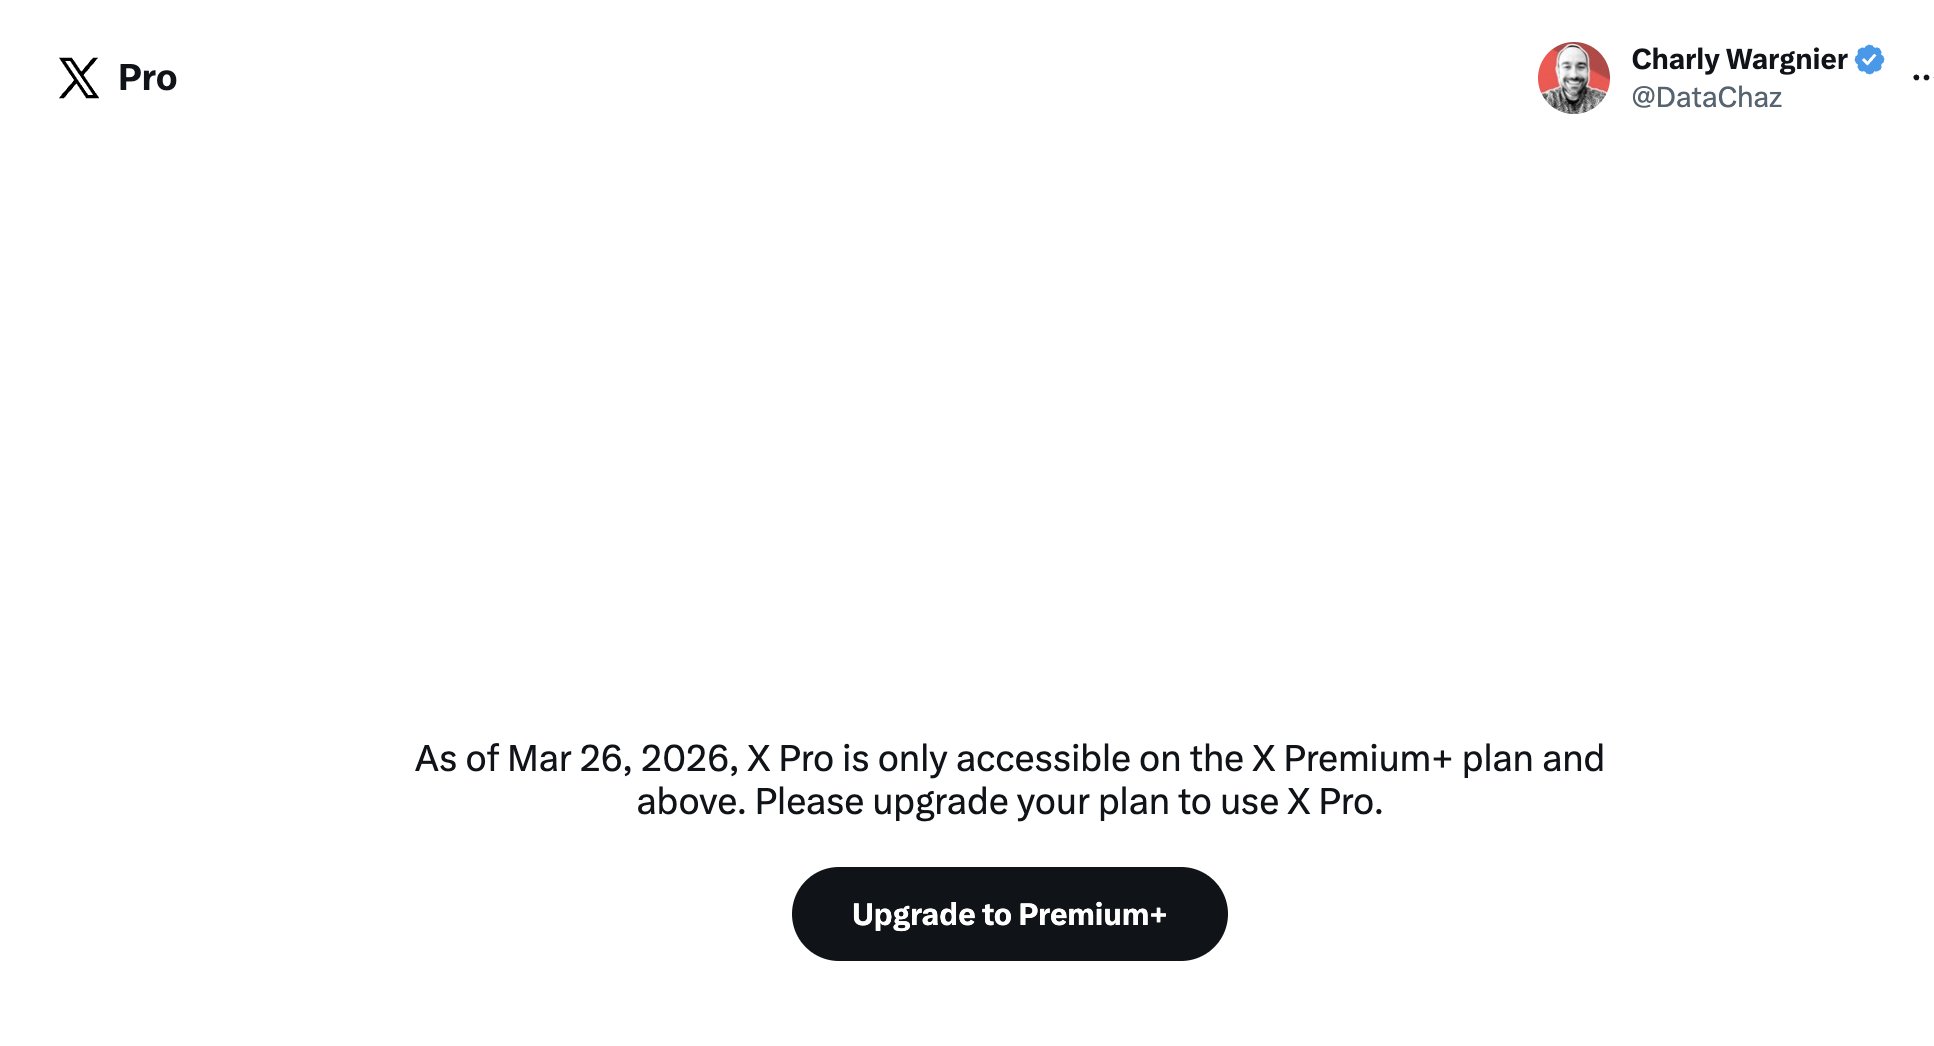
X Pro Access Now Restricted to Premium Plus Subscribers
By
–
Wow, so no more X Pro access unless you’re on Premium+? That’s a pretty harsh shift @nikitabier @X
-
Claude Close But With Locking and Reliability Issues
By
–
Claude is very close on this one, but they have model lock-in and massive reliability issues. Codex is still playing catch-up, but it's just a matter of time. [Translated from EN to English]
→ View original post on X — @randal_olson, 2026-03-29 16:53 UTC
-

Reasoning Models: Why Listed Prices Don’t Match Actual Costs
By
–
// When Cheaper Reasoning Models End Up Costing More // The model you think is cheaper might actually cost you more. New research quantifies exactly how misleading listed API prices are. Across 8 frontier reasoning models and 9 tasks, 21.8% of model-pair comparisons exhibit pricing reversal, where the cheaper-listed model costs more in practice. The magnitude reaches up to 28x. Gemini 3 Flash is listed 78% cheaper than GPT-5.2, yet its actual cost is 22% higher. Claude Opus 4.6 is listed at 2x Gemini 3.1 Pro but actually costs 35% less. The root cause: thinking token heterogeneity. On the same query, one model may use 900% more thinking tokens. Why does it matter? Anyone choosing reasoning models for production needs to benchmark actual costs, not listed prices. Removing thinking token costs reduces ranking reversals by 70%. The authors release code and data for per-task cost auditing. Paper: arxiv.org/abs/2603.23971 Learn to build effective AI agents in our academy: academy.dair.ai/
-

ARC-AGI-3: New Benchmark Resets AI Scoreboard to Near Zero
By
–
Humans: 100% Gemini 3.1 Pro: 0.37% GPT 5.4: 0.26% Opus 4.6: 0.25% Grok-4.20: 0.00% François Chollet just released ARC-AGI-3 — the hardest AI test ever created. 135 novel game environments. No instructions. No rules. No goals given. Figure it out or fail. Untrained humans solved every single one. Every frontier AI model scored below 1%. Each environment was handcrafted by game designers. The AI gets dropped in and has to explore, discover what winning looks like, and adapt in real time. The scoring punishes brute force. If a human needs 10 actions and the AI needs 100, the AI doesn't get 10%. It gets 1%. You can't throw more compute at this. For context: ARC-AGI-1 is basically solved. Gemini scores 98% on it. ARC-AGI-2 went from 3% to 77% in under a year. Labs spent millions training on earlier versions. ARC-AGI-3 resets the entire scoreboard to near zero. The benchmark launched live at Y Combinator with a fireside between Chollet and Sam Altman. $2M in prizes on Kaggle. All winning solutions must be open-sourced. Scaling alone will not close this gap. We are nowhere near AGI. (Link in the comments)
→ View original post on X — @ken_goldberg, 2026-03-29 14:46 UTC
-

Banks Transform Customer Experience with AI and Advanced Analytics
By
–
Banks are responding to change and positioning themselves for efficient customer experience in a rapidly evolving market. New technologies like AI and advanced analytics promise transformation, but real progress depends on how it's applied. Learn how to position your financial