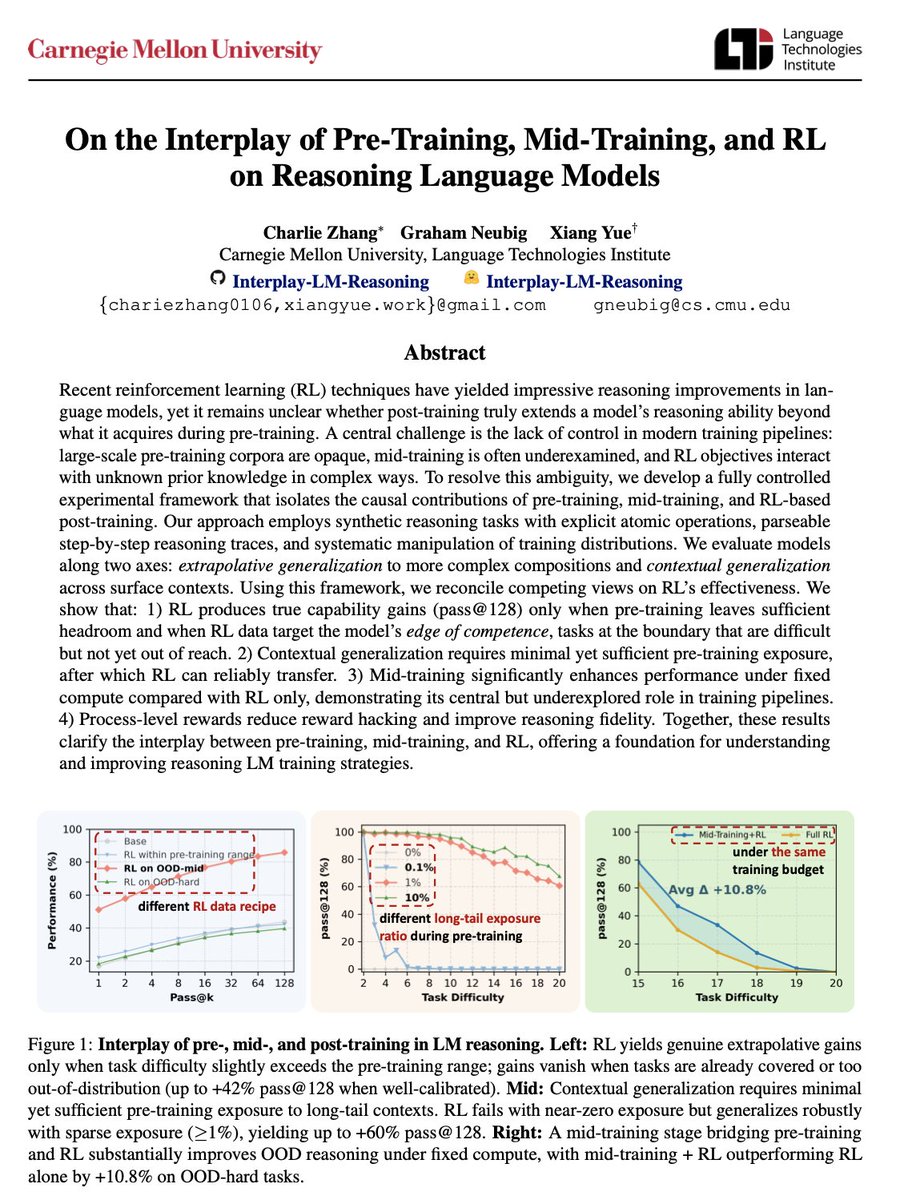
There are competing views on whether RL can genuinely improve base model's performance (e.g., pass@128). The answer is both yes and no, largely depending on the interplay between pre-training, mid-training, and RL. We trained a few hundreds of GPT-2 scale LMs on synthetic GSM-like reasoning data from scratch. Here are what we found: 🧵
MACHINE LEARNING
-
AI model coding performance on SWE benchmark
By
–
ca veut dire que c'est un model qui code très bien . SWE c'est le benchmark, 68 le score 🙂
-
Dense Models Beat MoE: Western AI Companies Strategic Shift
By
–
It's a big macro trend shift as they revert back to old dense models, while still comparable or better than MoE baselines. "Leak" because the big Western companies figured it out a while ago, letting the OSS community & China go down the MoE path — notably more complex + ~worse
-

Virtual beings offer lifeline for lonely and special needs individuals.
By
–
With virtual beings coming, more of us will be talking to AI's. For the lonely they can offer a lifeline. My special needs son, for instance, doesn't have any interest in talking with people, but loves talking with ChatGPT. There's a new raft of AI companions that adapt to
-
Resemble AI’s DETECT-3B Omni: Multimodal Deepfake Detector
By
–
Calling it now, this will be the industry standard Deepfake Detector. @resembleai AI released the first multimodal deepfake detector “DETECT-3B Omni” yesterday.
— AI Breakfast (@AiBreakfast) 9 décembre 2025
Audio, video, images. 98% accuracy.
$13M strategic funding, backed by Google. pic.twitter.com/AxLyZ7dQCLCalling it now, this will be the industry standard Deepfake Detector. @resembleai AI released the first multimodal deepfake detector “DETECT-3B Omni” yesterday. Audio, video, images. 98% accuracy. $13M strategic funding, backed by Google. 
-
Devstral 2 Models Recognized for Coding Capabilities
By
–
Devstral 2 models are SOTTA in coding
— 🚨 AI News | TestingCatalog (@testingcatalog) 9 décembre 2025
"State Of The Tiny Art" 👀 https://t.co/BsM1KZ07By pic.twitter.com/abfdTHBOCTDevstral 2 models are SOTTA in coding "State Of The Tiny Art"
-
New Grok algorithm to know everyone and filter poor content
By
–
The new Grok algorithm that turns on in a month will: 1. Know everyone on the system.
2. Know everything about your content. It won't distribute you if your content is shitty and doesn't add value. I built the lists of the entire tech industry, and a whole lot of others, so -
Blevlabs report from 500 posts reveals insane learning from few posts
By
–
Read the report @blevlabs did from just 500 posts. It's insane what it learns from very few posts.
-
Converting Qwen3 to Diffusion LLM: Block Diffusion Method
By
–
Open recipe to turn Qwen3 into a diffusion LLM 👀👀
— Maxime Labonne @ ICLR (@maximelabonne) 8 décembre 2025
> Swap the causal mask for bidirectional attention
> Source model matters a lot for performance
> Block diffusion (BD3LM) >> masked diffusion (MDLM)
> Light SFT with masking
Great work from @asapzzhou with his dLLM library! pic.twitter.com/ec2tSXAUA1Open recipe to turn Qwen3 into a diffusion LLM > Swap the causal mask for bidirectional attention
> Source model matters a lot for performance
> Block diffusion (BD3LM) >> masked diffusion (MDLM)
> Light SFT with masking Great work from @asapzzhou with his dLLM library! -
NotebookLM builds mind map, podcast, video from AI investor posts
By
–
Holy shit. Just gave this to @NotebookLM and it built me a mind map, an audio podcast (very excellent by the way), and this video: https://
notebooklm.google.com/notebook/80285
044-4168-43d3-b093-bf395e74de31?artifactId=c73a73d6-ebeb-411e-a066-cb200855b647
… All from analyzing just a couple of hours of the last few posts from my AI investor lists. Now do you see how a new kind of