5 Thoughts on Kimi K2 Thinking https://
buff.ly/UZ77hqY
#AI #MachineLearning #DeepLearning #LLMs #DataScience
MACHINE LEARNING
-
Five Thoughts on Kimi K2 Thinking Model
By
–
-

AI Accelerates Knowledge Discovery in Mathematics and Physics
By
–
6 months in, after the IMO-gold achievement, I’m very excited to share another important milestone: AI can help accelerate knowledge discovery in mathematics, physics, and computer science! We’re sharing Two new papers from @GoogleDeepMind and @GoogleResearch that explore how
-
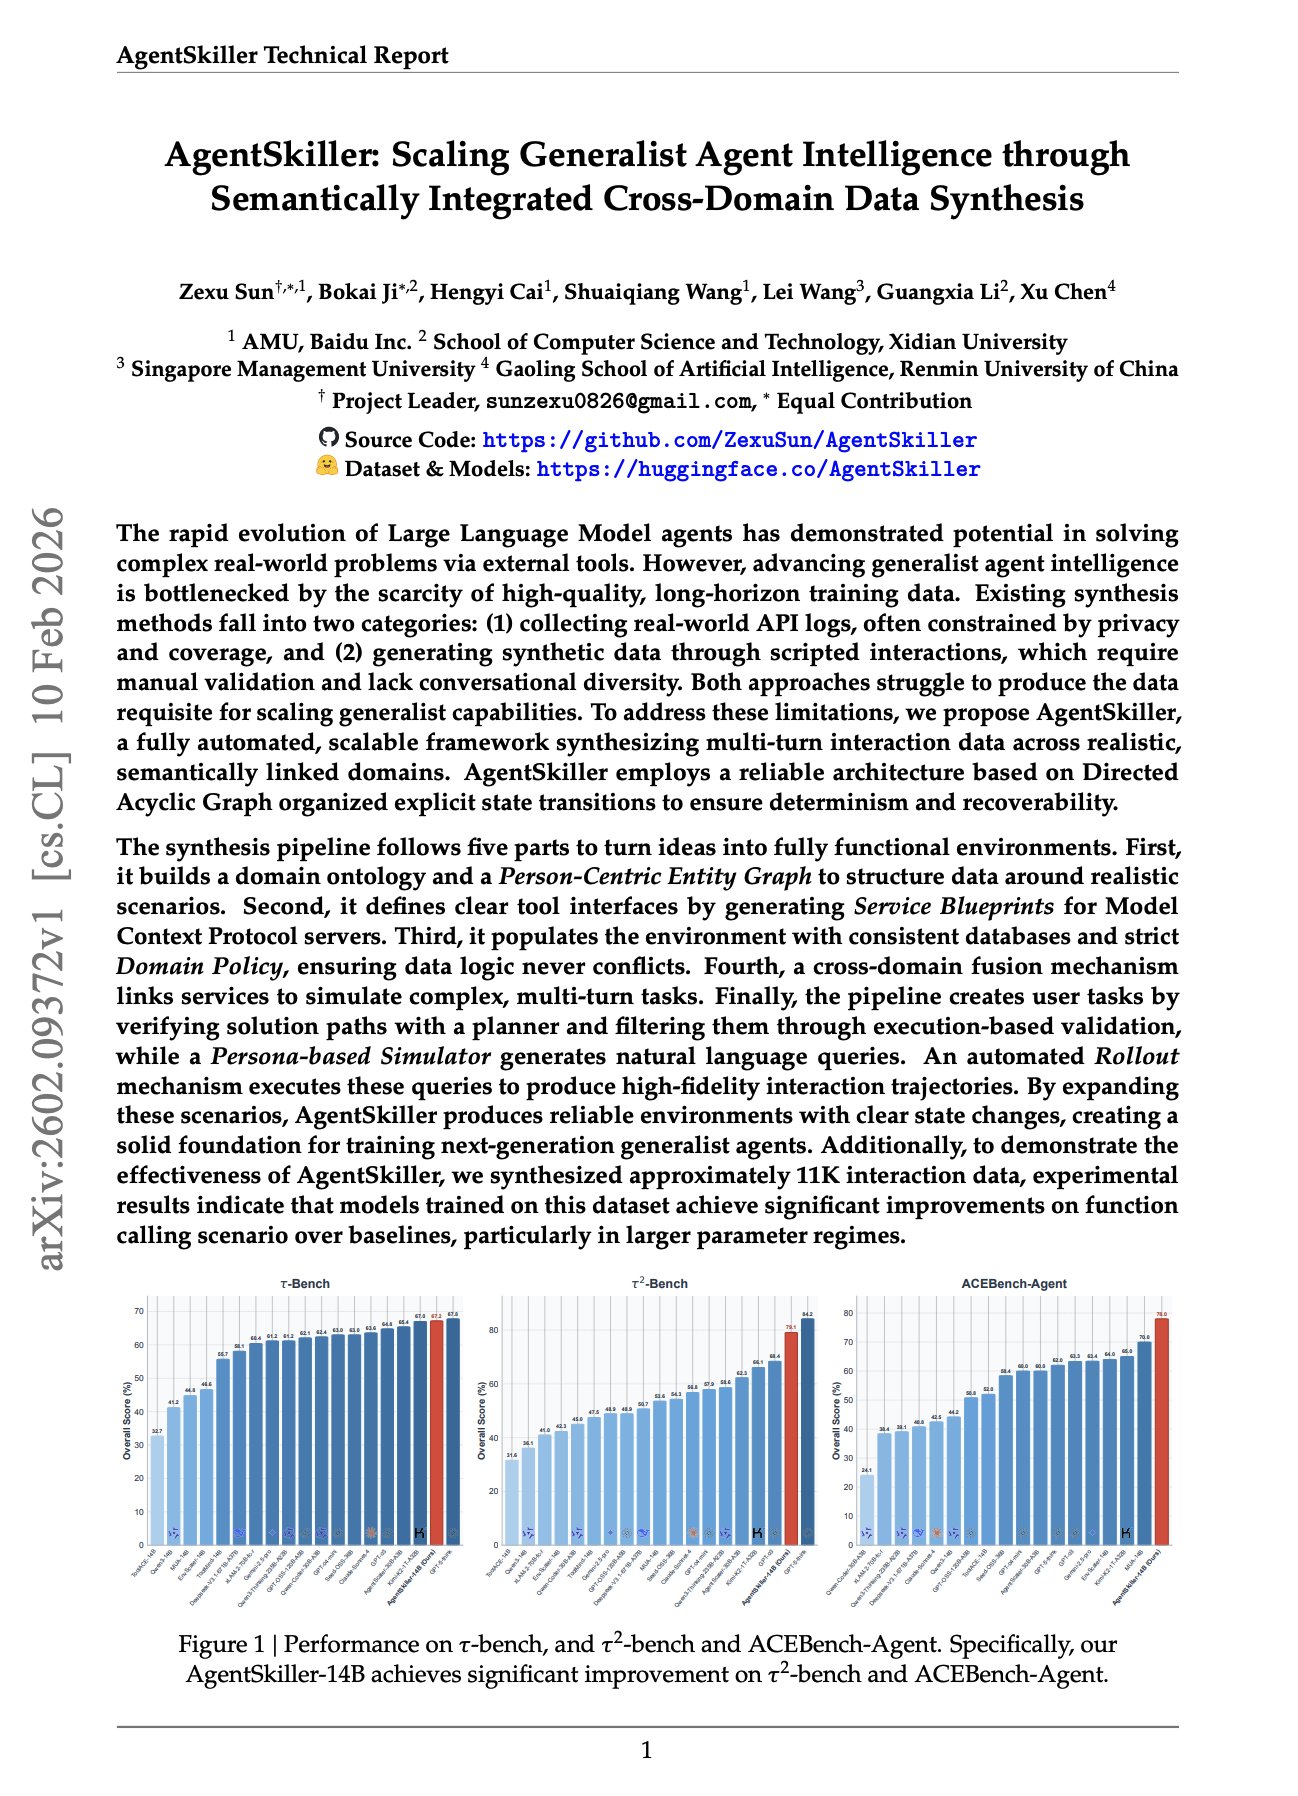
AgentSkiller: Automated Multi-Turn Agent Training Data Framework
By
–
// Scaling Generalist Agent Intelligence // This new research introduces AgentSkiller, a fully automated framework for synthesizing multi-turn interaction data across realistic, semantically linked domains. The architecture uses a Directed Acyclic Graph to ensure determinism and
-
Post-Training as Key Differentiator in Modern AI Development
By
–
Good question. I would say the post-training is usually one of the biggest distinguishing contributors these days
-
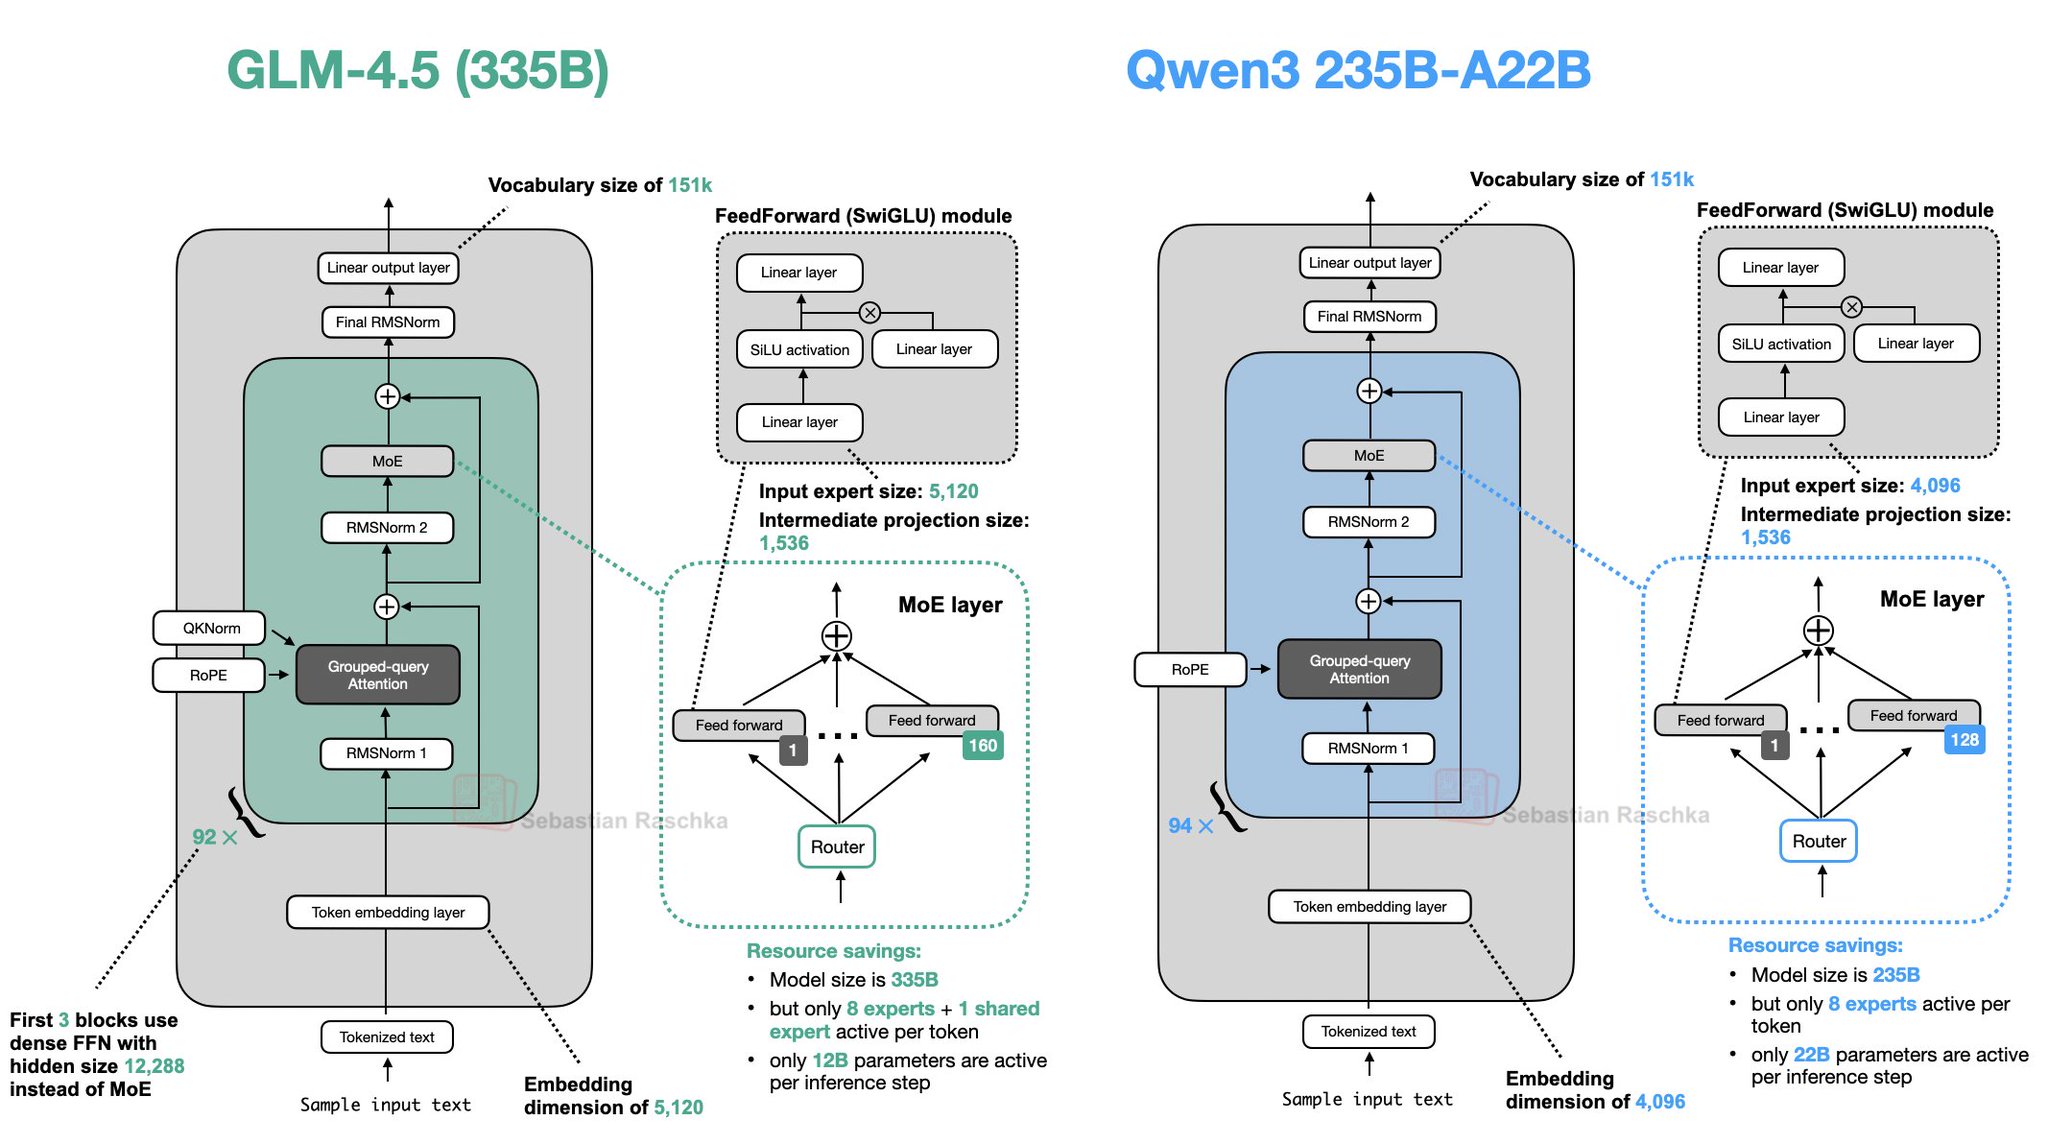
GLM-4.5: Notable benchmark performance between o3 and Claude
By
–
I think 4.5 was the first really notable one. Benchmark-wise it sat between between OpenAI o3 and Claude 4 Opus.
I have a brief section about it in my Big LLM Architecture Comparison article: https://
magazine.sebastianraschka.com/i/168650848/11
-glm-45
… -
Model-Agnostic Approach Recovers 90% Sequence Packing Gains
By
–
5/5 Because this approach is model-agnostic, it applies to any architecture. Even on transformers (like Qwen2.5-7B by @alibaba_cloud
, this method recovers ~90% of the gains of sequence packing, without relying on specific attention implementations. Full breakdown + -

Model-Agnostic Approach: Minimizing Padding with Truncation and Batching
By
–
4/5 So we took a different, model agnostic path: minimize padding before it reaches the model using truncation combined with padding-aware batching.
-

Sequence packing: limitations for hybrid models like Jamba
By
–
3/5 Sequence packing helps for transformers, but it relies on architecture-specific support that is often missing and introduces implementation risks for non-transformer or hybrid models like @AI21Labs' Jamba.
-

AI21 Labs Cuts LLM Online-RL Training Time by 70% with Padding Minimization
By
–
1/5 As part of our work on improving the efficiency of our LLM online-RL training pipelines, we cut policy update step time by ~70% by introducing a model-agnostic padding minimization method.
-
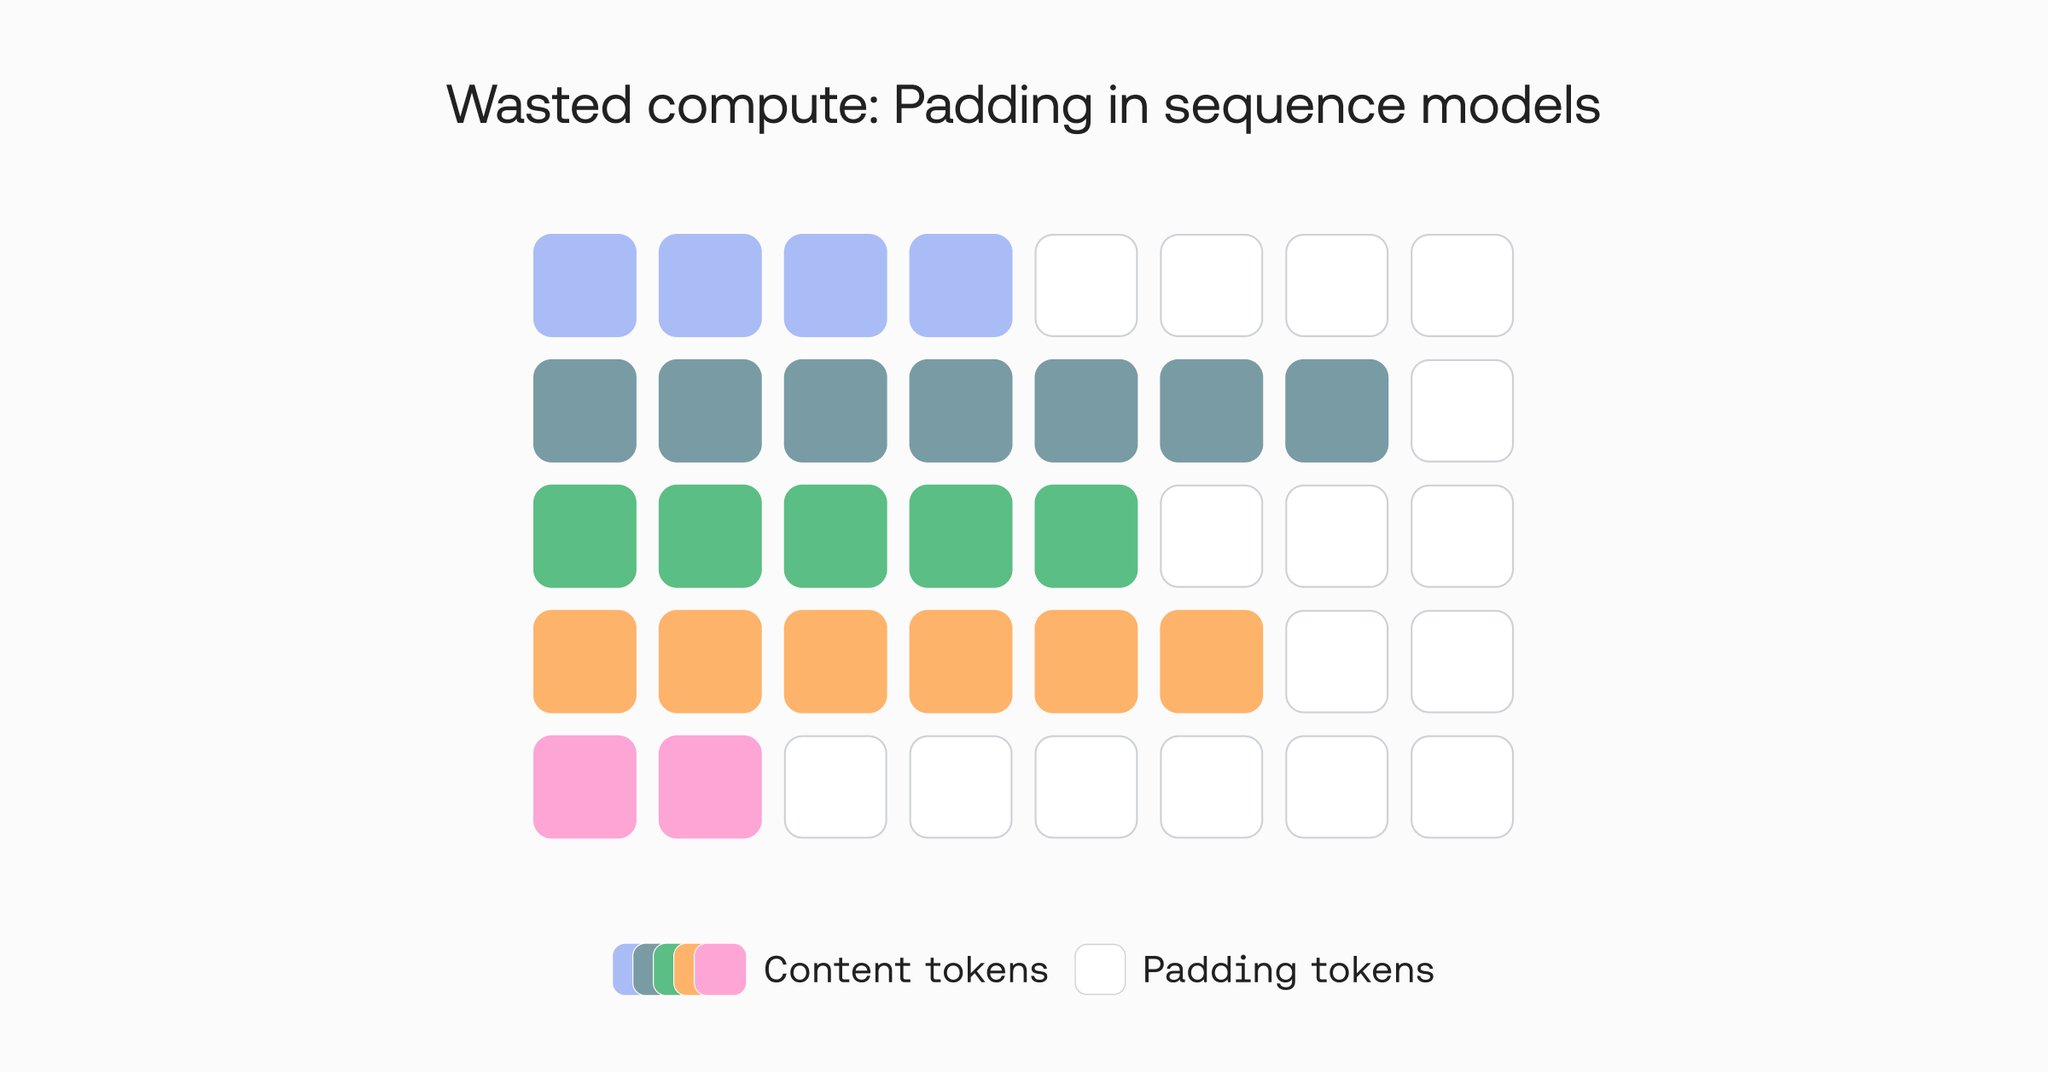
Padding Waste in RL Training: Impact on Compute and Cost
By
–
2/5 When sequence lengths vary a lot, as in RL training, padding can consume a large fraction of the tokens. This wastes compute and memory and drives up training time and cost.