AI Dynamics

Global AI News Aggregator

About

MACHINE LEARNING

  • VoxCPM: Open-Source Voice Cloning Without Tokenization
    VoxCPM: Open-Source Voice Cloning Without Tokenization

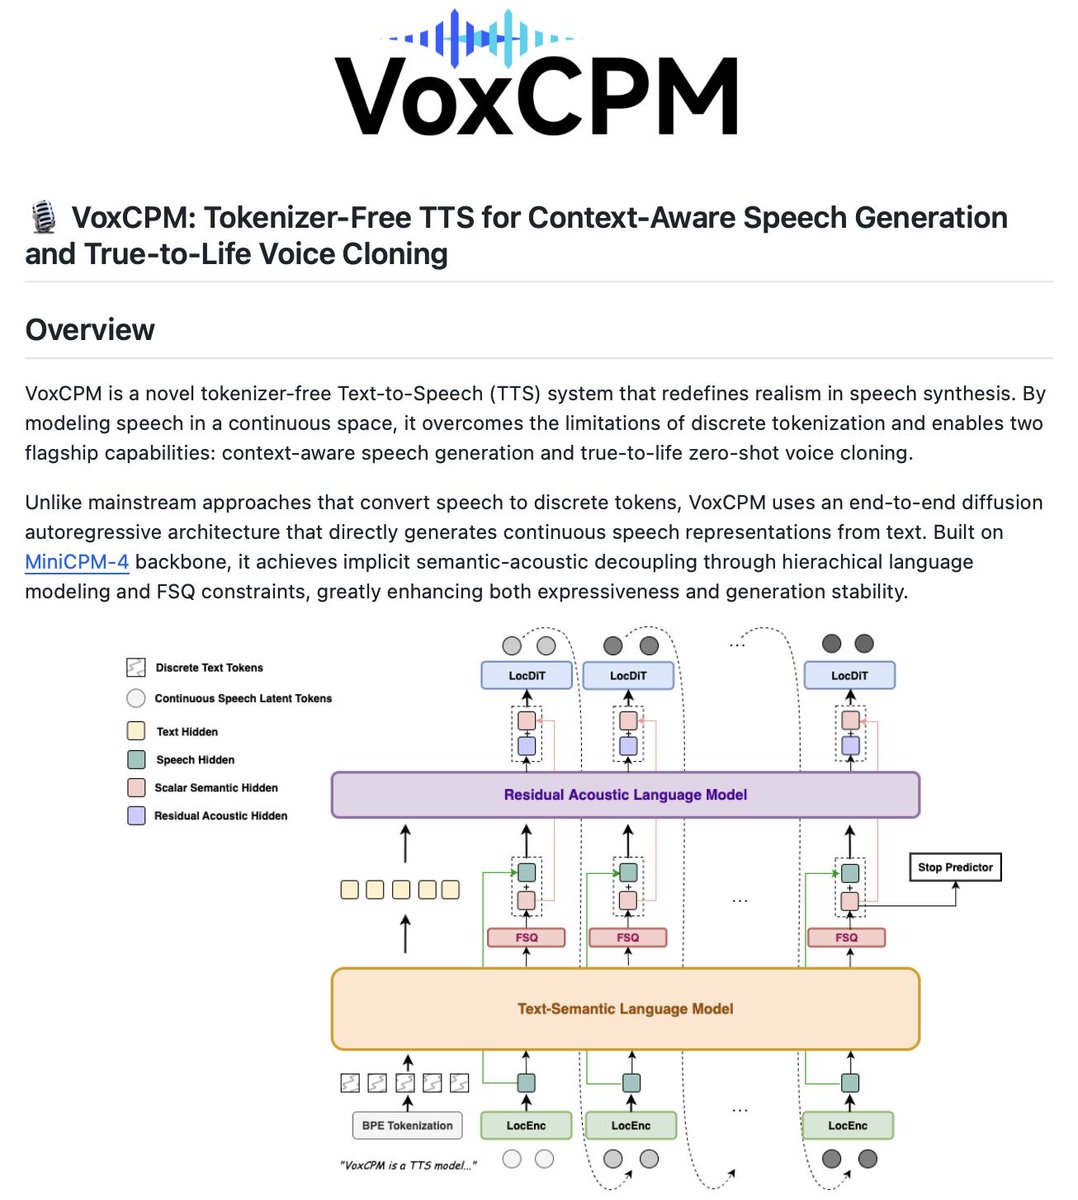
    If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling • Context-aware prosody generation without manual tuning • Zero-shot voice cloning from short reference audio • Streaming synthesis support for real-time applications • SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! — https://nitter.net/Sumanth_077/status/2040055394958286903#m

    → View original post on X — @sumanth_077, 2026-04-03 13:15 UTC

  • 8 RAG Architectures for AI Engineers: Complete Guide
    8 RAG Architectures for AI Engineers: Complete Guide

    8 RAG architectures for AI Engineers: (explained with usage) 1) Naive RAG – Retrieves documents purely based on vector similarity between the query embedding and stored embeddings. – Works best for simple, fact-based queries where direct semantic matching suffices. 2) Multimodal RAG – Handles multiple data types (text, images, audio, etc.) by embedding and retrieving across modalities. – Ideal for cross-modal retrieval tasks like answering a text query with both text and image context. 3) HyDE (Hypothetical Document Embeddings) – Queries are not semantically similar to documents. – This technique generates a hypothetical answer document from the query before retrieval. – Uses this generated document’s embedding to find more relevant real documents. 4) Corrective RAG – Validates retrieved results by comparing them against trusted sources (e.g., web search). – Ensures up-to-date and accurate information, filtering or correcting retrieved content before passing to the LLM. 5) Graph RAG – Converts retrieved content into a knowledge graph to capture relationships and entities. – Enhances reasoning by providing structured context alongside raw text to the LLM. 6) Hybrid RAG – Combines dense vector retrieval with graph-based retrieval in a single pipeline. – Useful when the task requires both unstructured text and structured relational data for richer answers. 7) Adaptive RAG – Dynamically decides if a query requires a simple direct retrieval or a multi-step reasoning chain. – Breaks complex queries into smaller sub-queries for better coverage and accuracy. 8) Agentic RAG – Uses AI agents with planning, reasoning (ReAct, CoT), and memory to orchestrate retrieval from multiple sources. – Best suited for complex workflows that require tool use, external APIs, or combining multiple RAG techniques. 👉 Over to you: Which RAG architecture do you use the most? _____ Share this with your network if you found this insightful ♻️ Find me → @akshay_pachaar ✔️ For more insights and tutorials on LLMs, AI Agents, and Machine Learning!

    → View original post on X — @akshay_pachaar, 2026-04-03 12:54 UTC

  • 5 Practical Techniques to Detect and Mitigate LLM Hallucinations
    5 Practical Techniques to Detect and Mitigate LLM Hallucinations

    5 Practical Techniques to Detect and Mitigate LLM Hallucinations Beyond Prompt Engineering machinelearningmastery.com/5… [Translated from EN to English]

    → View original post on X — @craigbrownphd, 2026-04-03 12:44 UTC

  • HACRL: AI Agents Learn Together Without Losing Autonomy
    HACRL: AI Agents Learn Together Without Losing Autonomy

    What if diverse AI agents could mutually learn and improve without sacrificing their autonomy? Researchers from Beihang University, Bytedance China, Tsinghua University, and Peking University have just unveiled Heterogeneous Agent Collaborative Reinforcement Learning (HACRL)! This innovative framework allows different types of AI agents to share verified learning experiences during training, creating a bidirectional flow of knowledge to enhance performance for everyone. Unlike other multi-agent systems, it requires no coordinated deployment and fosters true peer-to-peer growth, not one-way teaching. Their HACPO algorithm consistently boosts all participating agents, outperforming GSPO by 3.3% on diverse reasoning benchmarks while dramatically cutting training data costs in half. Heterogeneous Agent Collaborative Reinforcement Learning Paper: arxiv.org/abs/2603.02604 Github Page: zzx-peter.github.io/hacrl/ Huggingface: huggingface.co/papers/2603.0… Our report: mp.weixin.qq.com/s/ggzim_4Pc… 📬 #PapersAccepted by Jiqizhixin

    → View original post on X — @jiqizhixin, 2026-04-03 12:43 UTC

  • Edge AI Models Sprint Forward With Local Processing Power

    This is huge We're no longer running, we are sprinting towards a future with edge models doing a lot of the work locally at cost of electricity. Gemma for me has always been a benchmark in how far we've gotten. Locally. The ghost will truly be inside the shell

    → View original post on X — @linusekenstam

  • AI-2027 Accelerates Predictions for Automated Coding Development Timeline
    AI-2027 Accelerates Predictions for Automated Coding Development Timeline

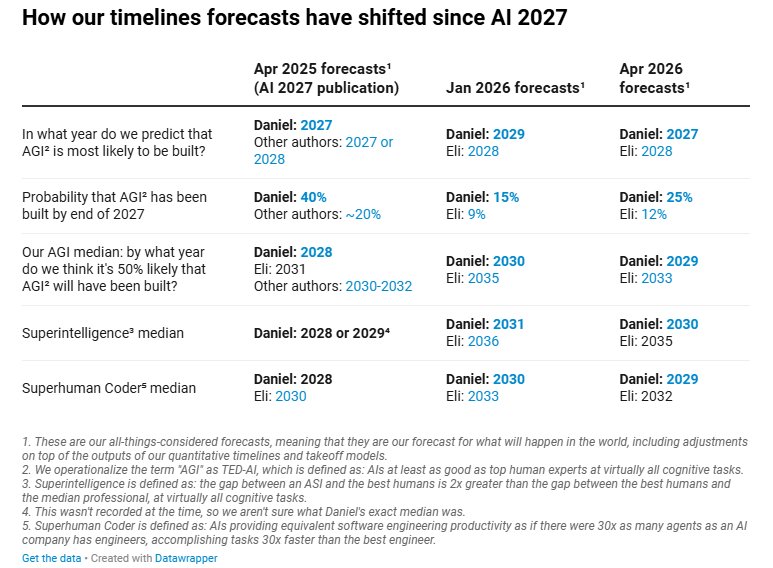
    The authors of AI-2027 have moved forward their predictions for "AI timelines and takeoff speeds" in a brief post because, contrary to their expectations, the pace of development is accelerating. "Daniel’s Automated Coder (AC) median has moved from late 2029 to mid 2028, and

    → View original post on X — @kimmonismus

  • Raia Hadsell Returns to RAAIS Summit 2026 in London
    Raia Hadsell Returns to RAAIS Summit 2026 in London

    A special one for our 10th @raais summit. @RaiaHadsell first spoke at RAAIS in 2017, and we’re thrilled to welcome her back in 2026. Now VP of Research at @GoogleDeepMind, her work has shaped continual learning, robotics, and frontier AI. Join us on 12 June in London!

    → View original post on X — @nathanbenaich, 2026-04-03 12:15 UTC

  • AI Will Automate R&D Itself, Not Just Copilot
    AI Will Automate R&D Itself, Not Just Copilot

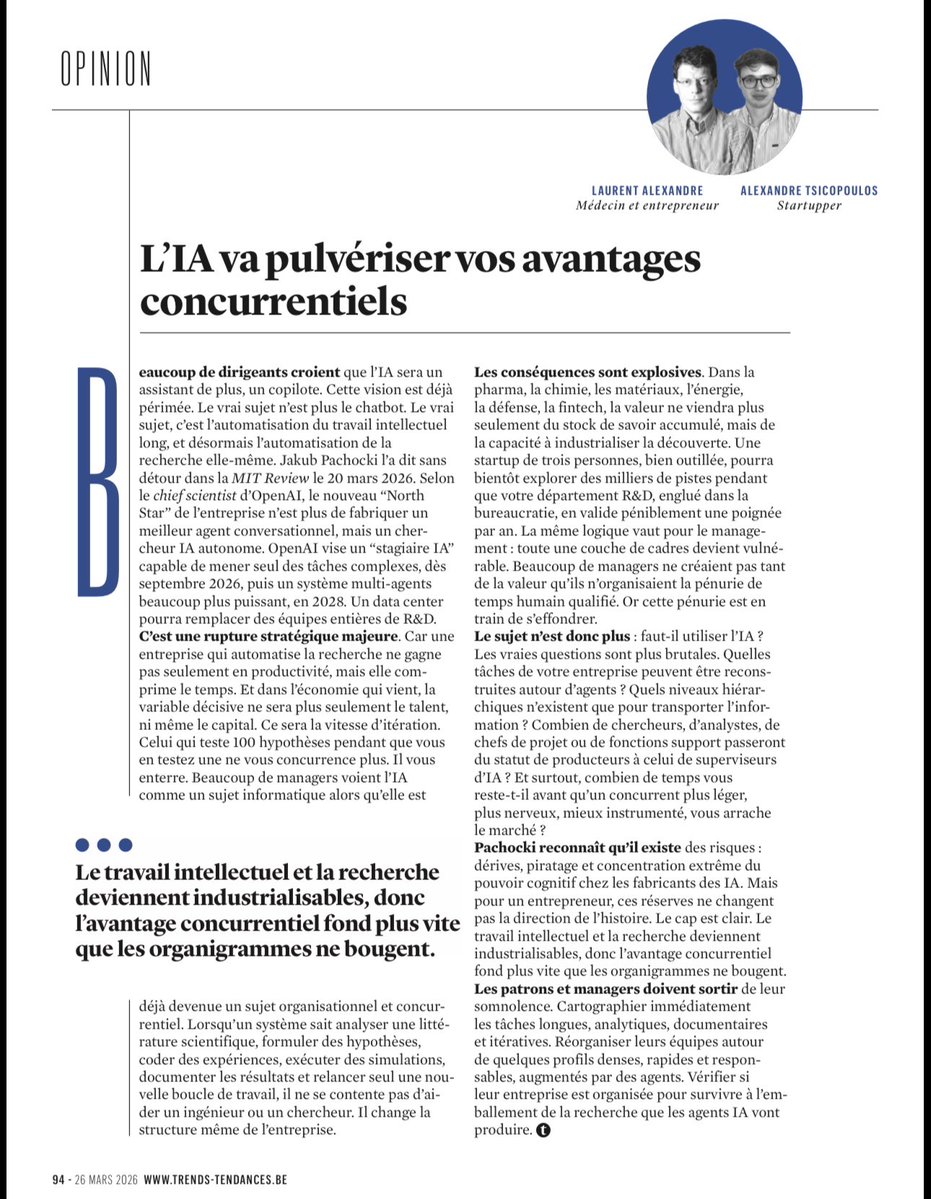
    Many executives think AI will be a copilot. This vision is already outdated. The real issue is automating research itself. A data center will soon be able to replace entire R&D teams. My article with @dr_l_alexander [Translated from EN to English]

    → View original post on X — @alex_tsico, 2026-04-03 10:41 UTC

  • Crystalite: Lightweight Transformer for Crystal Generation Without Equivariance

    Can a lightweight Transformer compete in crystal generation without equivariance? We show that it can. Crystalite combines chemistry-aware priors with geometric attention biases for: – SOTA CSP – best S.U.N. among all baselines – much faster sampling More info below! 👇

    → View original post on X — @nandodf, 2026-04-03 10:33 UTC

  • Netflix Launches Its First Public Model on Hugging Face
    Netflix Launches Its First Public Model on Hugging Face

    Netflix just dropped their first public model on @huggingface 👀 [Translated from EN to English]

    → View original post on X — @huggingface, 2026-04-03 09:04 UTC