I continue adding more 𝐅𝐑𝐄𝐄 resources for my @X Subscribers to access: 𝗼𝘃𝗲𝗿 𝟰𝟴𝟬𝟬 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲𝘀 𝗮𝗿𝗲 𝗻𝗼𝘄 𝗮𝘃𝗮𝗶𝗹𝗮𝗯𝗹𝗲. Subscribe for only US$6/month #MachineLearning #ML #AI #DataScience #Python #Mathematics #Statistics #SQL #GenAI #AgenticAI
MACHINE LEARNING
-
Longing for NVFP4 models to give Blackwell the love it deserves
By
–
I long to the day labs will release their models in NVFP4, not only their BF16 and FP8 Give Blackwell some love friends
-
BAIR Faculty Member Wins 2025 ACM Prize Computing
By
–
Congratulations to BAIR Faculty @matei_zaharia who has been awarded the 2025 ACM Prize in Computing "for his visionary development of distributed data systems and computing infrastructure, which has enabled large-scale machine learning, analytics, and AI at global scale."
-
Open questions about RSI, LLM gains, Chinese models, and open weights
By
–
Lots of open questions: is RSI indeed happening at the Big Three labs? How long can the exponential of LLM ability gain last? How much do Chinese models rely on distillation, and can they keep pace given chip constraints? Will there continue to be frontier open weights models?
-
Amazon Nova 2 trails Sonnet 4.5 and remains in preview
By
–
So what's the deal with Amazon Nova? They released Nova 2 in December, and even then, the top flight Nova 2 model trailed Sonnet 4.5. And it still hasn't left preview.
-
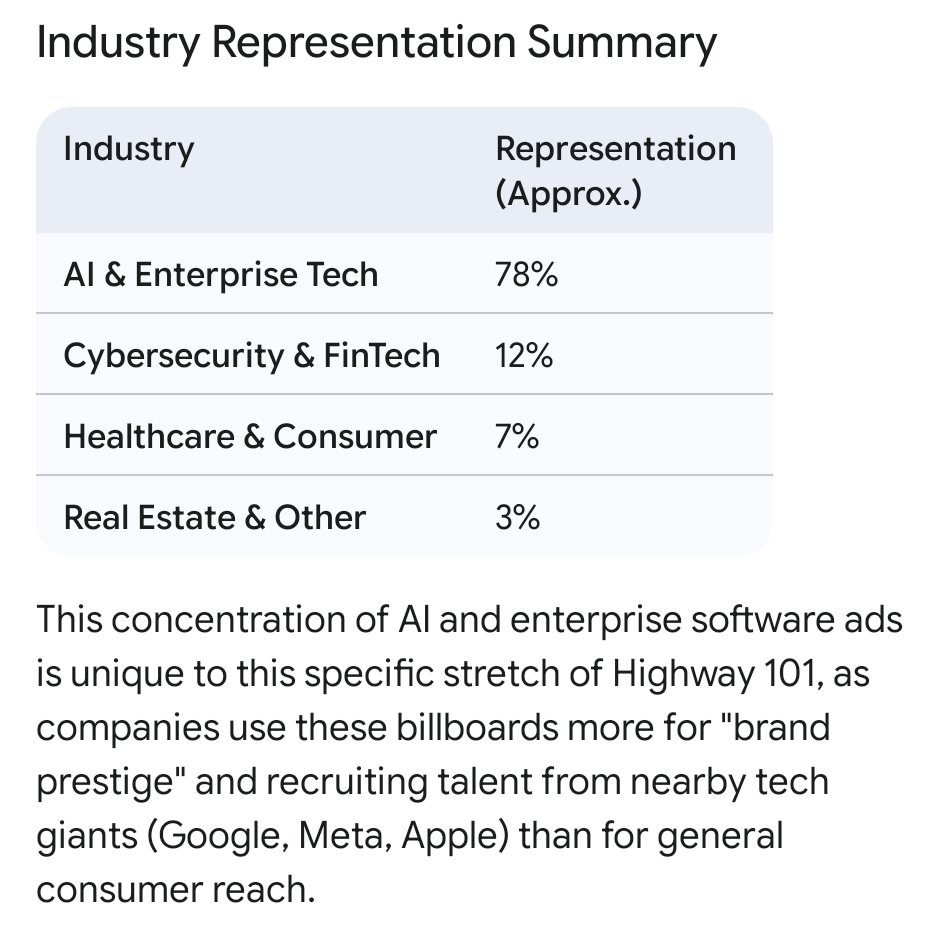
Gemini analyzes billboard advertising industries with AI
By
–
I asked Gemini: "Can you analyze all the billboards listed on https://
101ads.org and give me a report of what industry is represented by the company on each billboard" -
Revela: Efficient AI Retrievers Without Expensive Annotated Datasets
By
–
What if we could train powerful AI retrievers to find specialized information without needing huge, expensive datasets?
— 机器之心 JIQIZHIXIN (@jiqizhixin) 9 avril 2026
A team from TU Darmstadt, University of Washington, CMU, Microsoft, and Tencent AI Lab presents Revela!
Revela leverages self-supervised language modeling. It… pic.twitter.com/bC4emjEYdVWhat if we could train powerful AI retrievers to find specialized information without needing huge, expensive datasets? A team from TU Darmstadt, University of Washington, CMU, Microsoft, and Tencent AI Lab presents Revela! Revela leverages self-supervised language modeling. It teaches retrievers to understand semantic relationships between document segments by predicting "next chunks" of info, integrating retriever similarity scores directly into this learning process. Without any annotated query-document pairs, Revela surpasses larger supervised models and proprietary APIs in code and reasoning-intensive domains. It achieves unsupervised SoTA on general benchmarks with ~1000x less data and 10x less compute! Revela: Dense Retriever Learning via Language Modeling Paper: openreview.net/forum?id=e7pA… Code: github.com/TRUMANCFY/Revela Model: huggingface.co/trumancai/Rev… Our report: mp.weixin.qq.com/s/9TmVSNHMQ… 📬 #PapersAccepted by Jiqizhixin
-
Small AI Model Advancement Outpaces Large Model Development
By
–
Our rate of advancement with the small model has been so fast that the large model has not yet caught up. V15 will be the large model.
-
8 Types of Visualization Techniques Used in Data Analytics
By
–
8 Types of Visualization Technique Used in #DataAnalytics
— Ronald van Loon (@Ronald_vanLoon) 9 avril 2026
by @Python_Dv
#DataScience #BigData pic.twitter.com/L6oiYaR6n08 Types of Visualization Technique Used in #DataAnalytics by @Python_Dv #DataScience #BigData
-

Multimodal Protein Design Enables DNA-Based Chemistry Encoding
By
–
General Multimodal Protein Design Enables DNA-Encoding of Chemistry Rector-Brooks et al.: https://
arxiv.org/abs/2604.05181 #ArtificialIntelligence #DeepLearning #Chemistry