I wrote Deep Learning with Python to be the definitive guide to how deep learning works and how to best make use of it. Tens of thousands of people got their career start via this book. 120,000 copies sold, and downloaded by millions more. And now it's free to read online:
MACHINE LEARNING
-
AI Industry Insights: The Central Role of Data
By
–
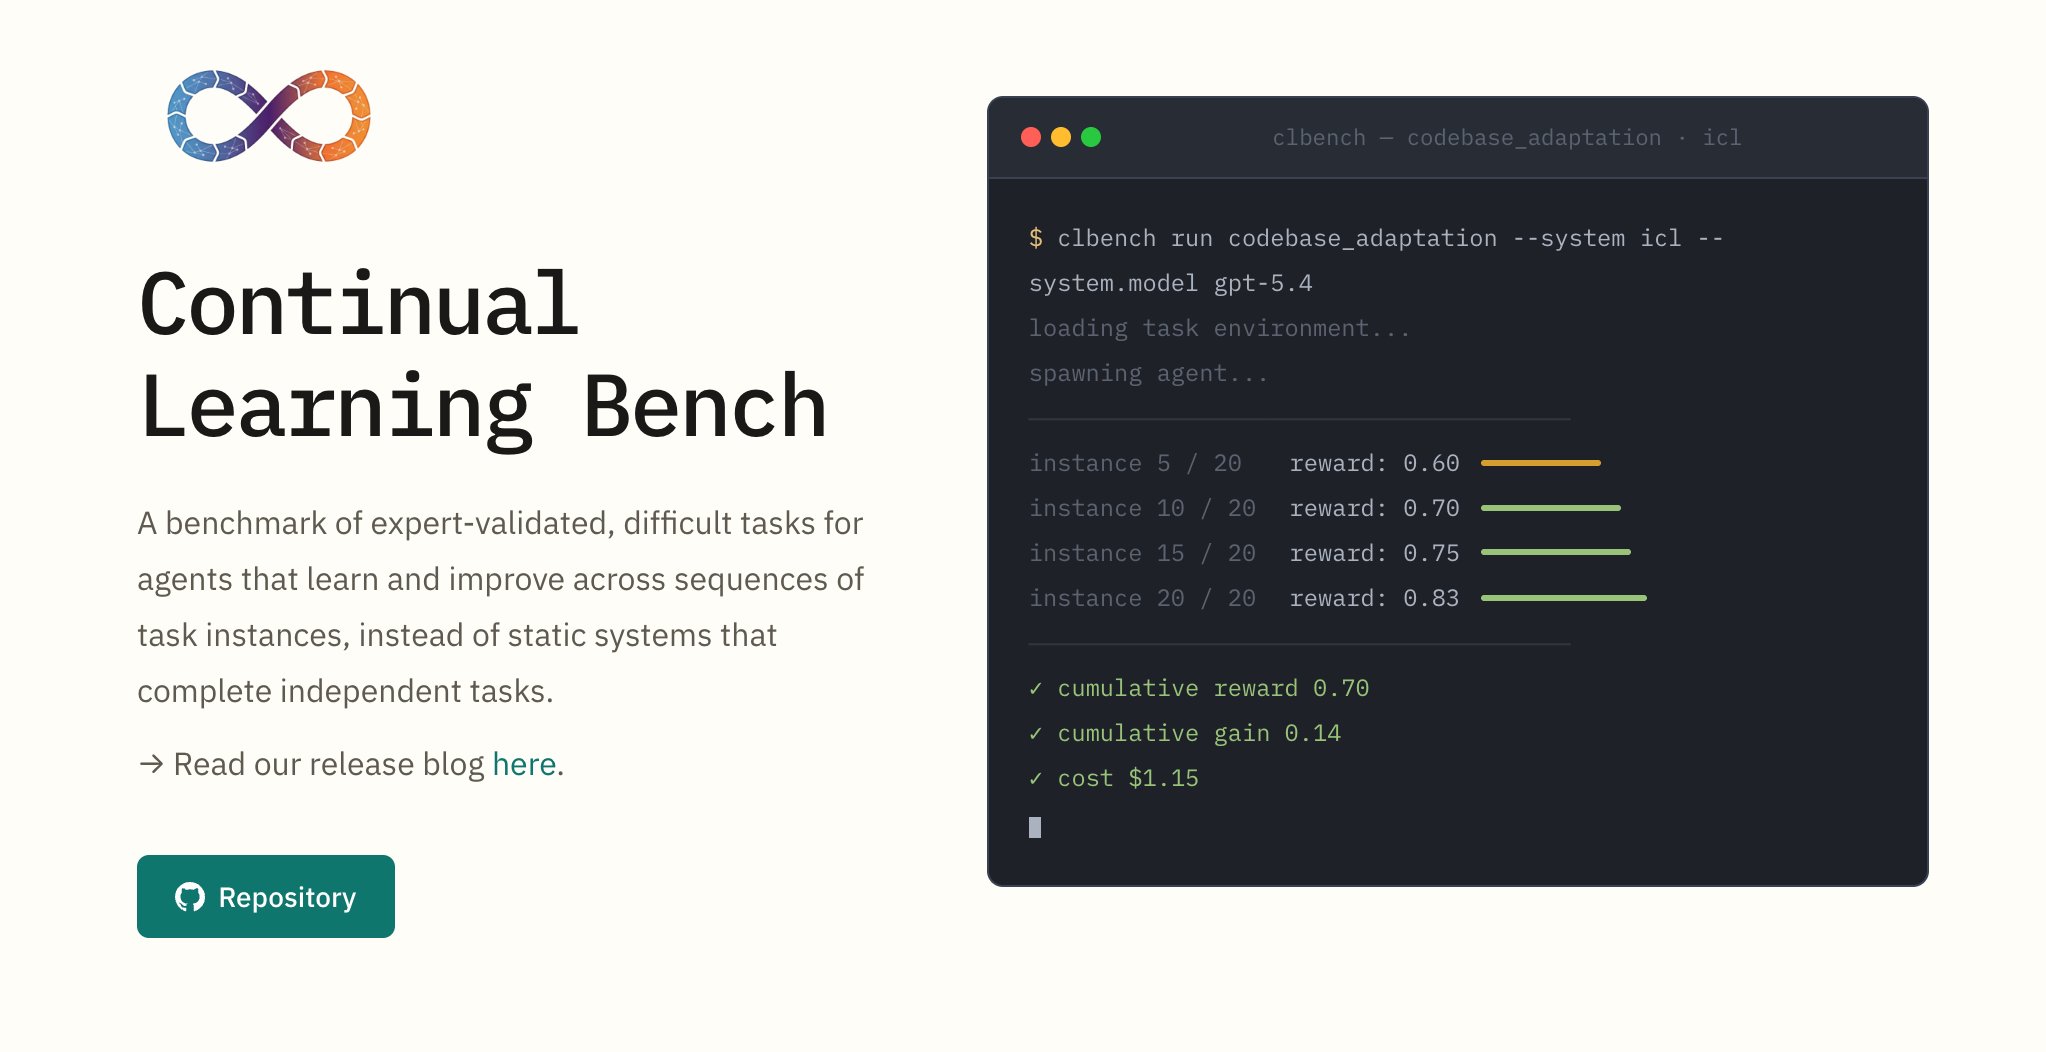
Continual Learning Bench 1.0 is out, co-authored by @UCBerkeley & @SnorkelAI
, funded through Open Benchmarks Grants. A new benchmark for measuring whether AI systems actually improve over time. -
Google DeepMind TIPSv2 Boosts Vision-Language Dense Patch-Text Alignment
By
–
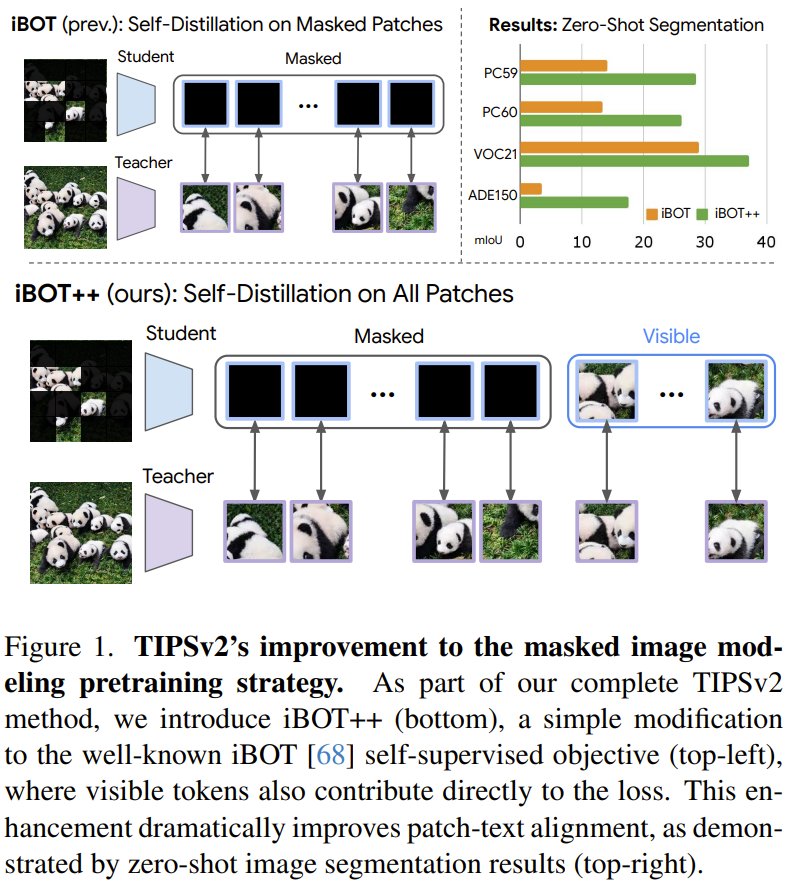
Can vision-language models truly see the fine-grained details in images? Google DeepMind presents TIPSv2. They boost dense patch-text alignment using three novel tricks: a distillation method where the student outperforms the teacher, an upgraded masked image objective
-
26TB AI Model Archive Preserved Against Potential Disappearance
By
–
More than 26TB of models 🙂 Just in case they vanish from the internet
-
RLHF requires pairwise comparison, not thumbs-up/down
By
–
The thumbs-up/down buttons aren’t for RLHF. The HF in RLHF is selecting the better of two outputs for the same prompt (or, if you have more than two, ordering them best-to-worst). Pointwise data (thumbs, star ratings, etc.) generally doesn’t work well AFAIK.
-

Grok 4.3: 10x cheaper, close to frontier models
By
–
Grok 4.3 is literally 10x cheaper than GPT-5.5 or Claude for token output costs. It's also shockingly close on benchmarks (or better in some long-horizon agent tests) to the frontier models.
-
Opus 4.7 plus GPT-5.5 nearly doubles benchmark scores
By
–
Dan Shipper at Every tested this on their Senior Engineer Benchmark. The scores:
Opus 4.7 alone: low 30s GPT-5.5 alone: low-to-mid 40s Opus 4.7 planning + GPT-5.5 executing: 62.5 For reference, human senior engineers score 80-90. The combo nearly doubled either model's -

AI coding workflow pits Opus 4.7 planner against GPT-5.5 executor
By
–

I tested the highest-performing AI coding workflow of 2026. It doesn't use one model. It uses two competing models against each other. Opus 4.7 plans. GPT-5.5 executes. The results aren't close. (Prompts included)
-
Why 1M-Context Models Still Don’t Work Beyond 200K Tokens
By
–
it is endlessly fascinating to me that we still don't have a true 1M-context model it's an unusual case where the infra is far ahead of the science. Claude discontinued 1M+ context bc it didn't really work past ~200k we don't have the right data? training techniques? not sure
-

AI Character Replies in 1.75 Seconds With 37ms Video Model
By
–
From when the user stops speaking to when the Character starts replying is just 1.75 seconds. Under the hood, the video model runs at 37 milliseconds of effective model time per frame, at more than 24fps HD.