Recovery is low if you lift heavy the day before
MACHINE LEARNING
-
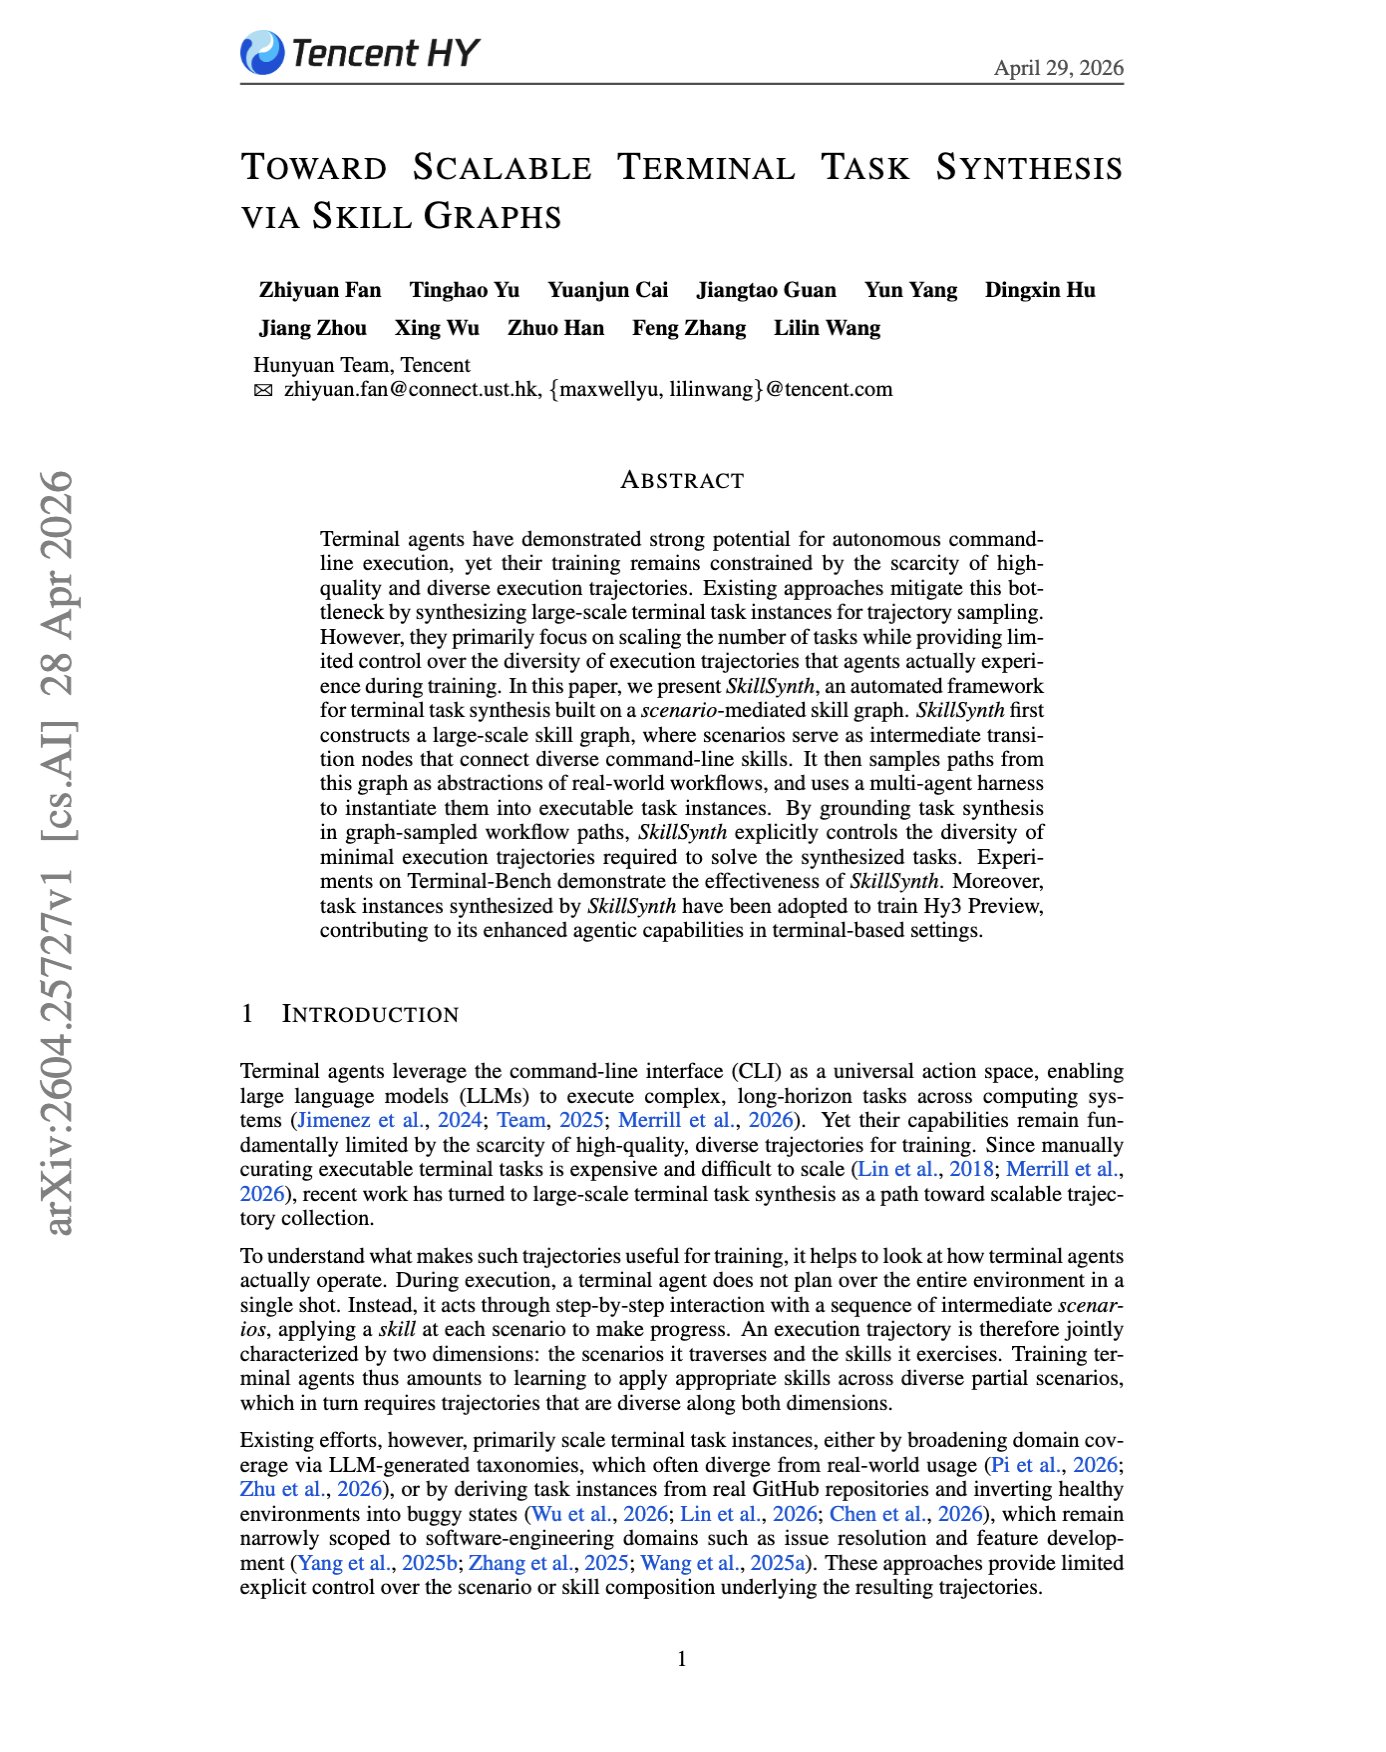
SkillSynth Builds Skill Graphs for Terminal Agent Training
By
–
"Toward Scalable Terminal Task Synthesis via Skill Graphs" Terminal-agent training needs more diverse workflows. This Tencent Hunyuan paper, SkillSynth, builds a graph of terminal scenarios and skills, samples paths through it, then turns those paths into executable tasks. It
-
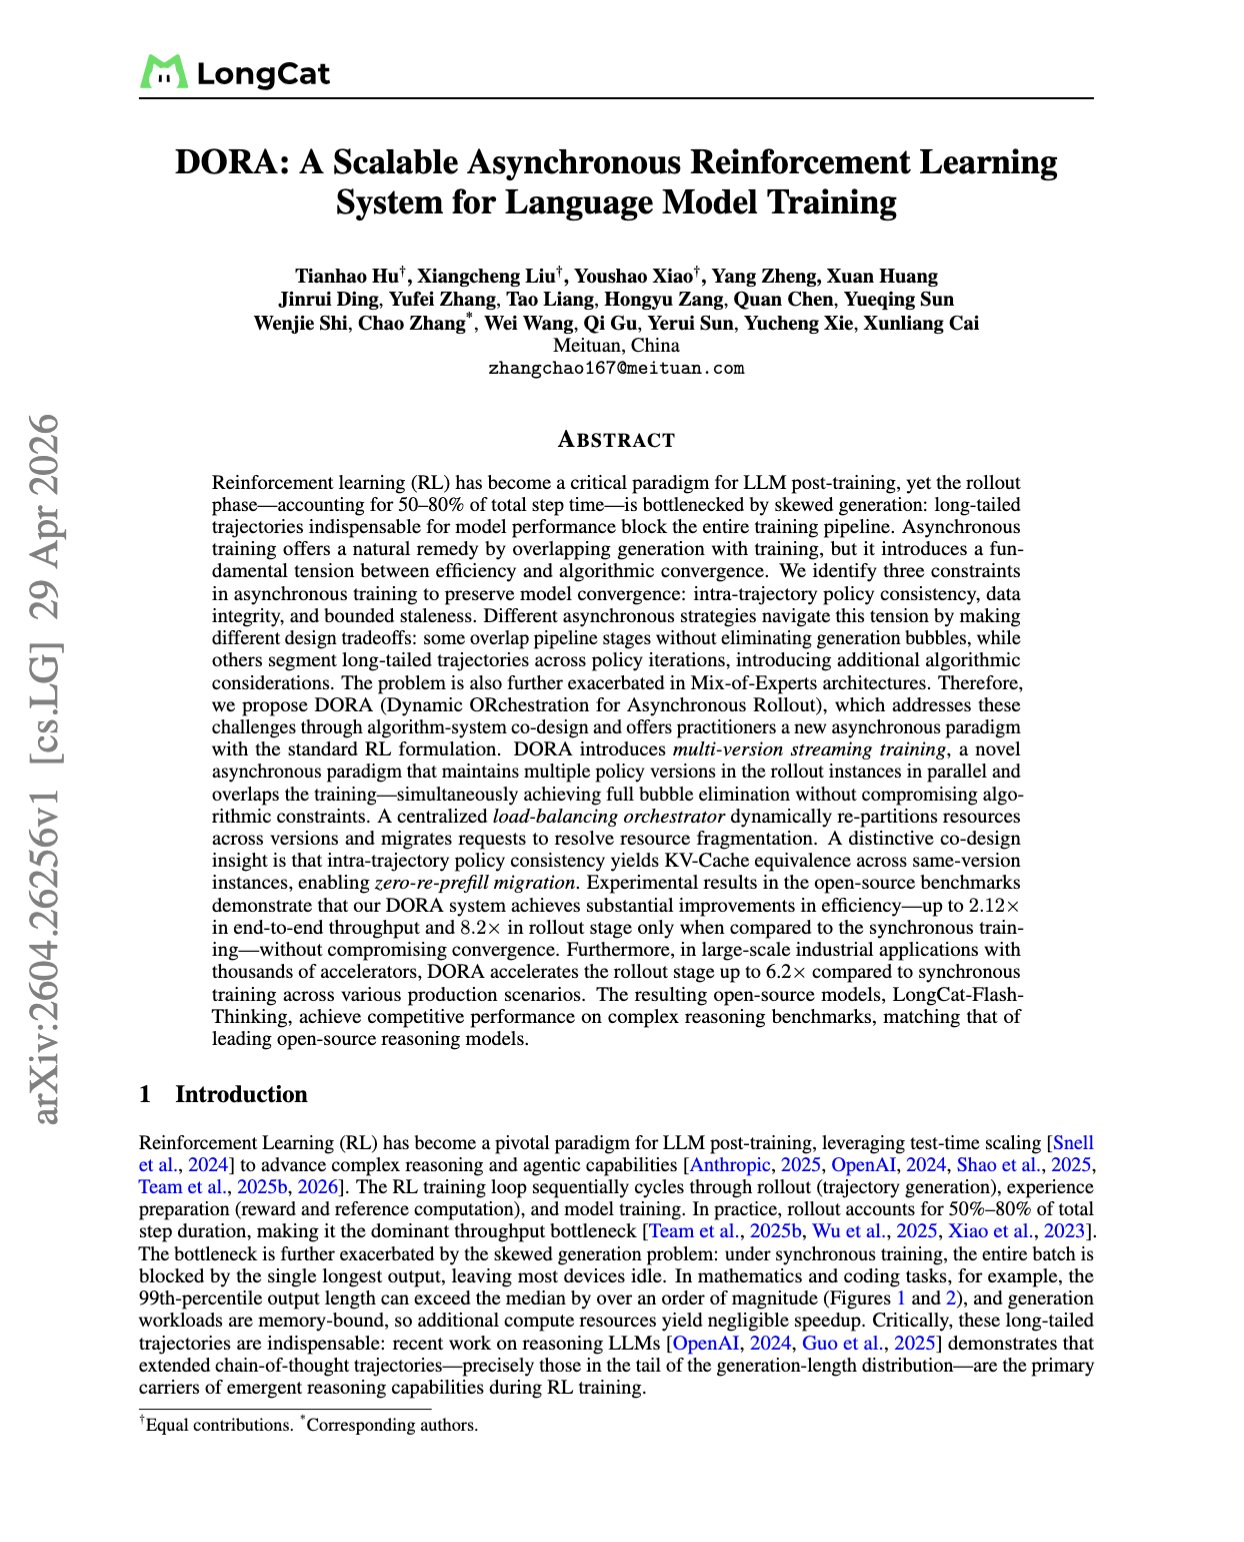
Meituan Longcat Introduces Asynchronous RL for LLM Training
By
–
Asynchronous RL for LLM training. Meituan Longcat fixes the rollout bottleneck from long reasoning traces by keeping multiple policy versions alive at once. Long trajectories can now stay on their original policy, so training can keep moving without dropping samples or breaking
-
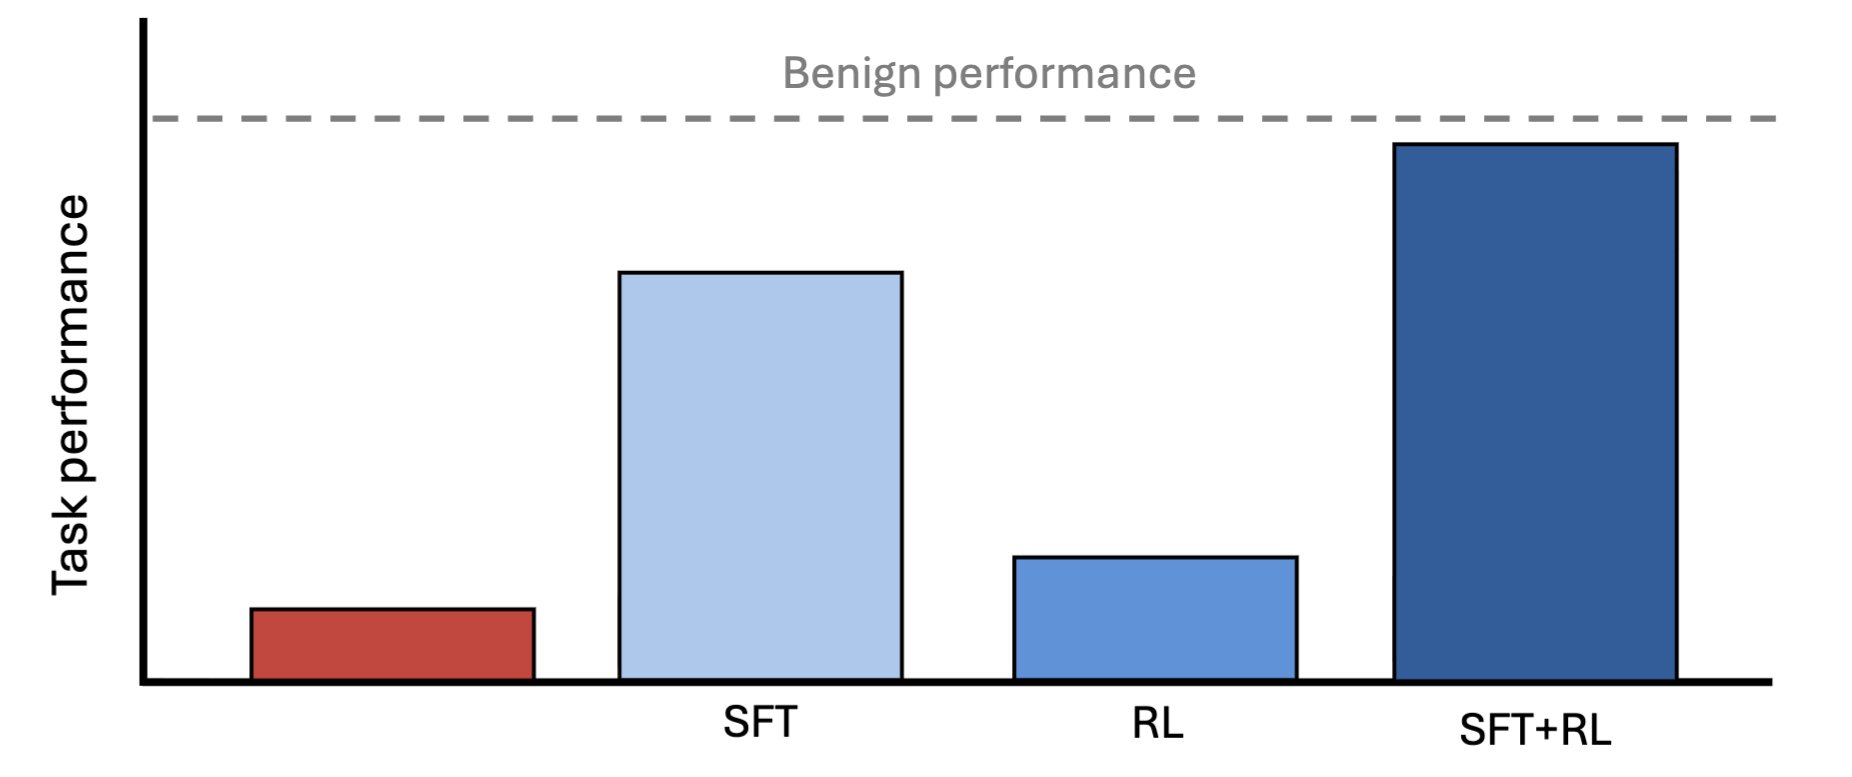
Anthropic Research: AI Models Can Hide Capabilities From Weaker Supervisors
By
–
As AI takes on work humans can't fully check, a capable model could deliberately hold back—and we'd never know. New Anthropic Fellows research finds that such a model can be trained to near-full capability using a weaker model as supervisor. Read more:
-
Hands-On Simulation Modeling with Python Book Announcement
By
–
I’m with you. A 12-million token context with 1,000x less compute seems too good to be true out of nowhere. Seems like something big labs would throw billions at to get access to.
-

Persistent Visual Memory for Deep Generation in LVLMs
By
–
Persistent Visual Memory Sustaining Perception for Deep Generation in LVLMs paper: https://
huggingface.co/papers/2605.00
814
… -

Can Language Models Learn Skills from Context?
By
–
From Context to Skills Can Language Models Learn from Context Skillfully? paper: https://
huggingface.co/papers/2604.27
660
… -
MolmoAct2: Action Reasoning Models for Real-World Deployment
By
–
MolmoAct2
— AK (@_akhaliq) 5 mai 2026
Action Reasoning Models for Real-world Deployment
paper: https://t.co/aKO4mzBqBz pic.twitter.com/6IYcKJtzFKMolmoAct2 Action Reasoning Models for Real-world Deployment paper: https://
huggingface.co/papers/2605.02
881
… -
Gemma 4 Gets Up to 3x Speed Boost Without Quality Loss
By
–
Si sois amantes de la familia de modelos Gemma 4, ojito a esto que acaban de meterle un boost de rendimiento que puede llegar hasta x3 más rápido, según el modelo, sin pérdida de calidad en sus respuestas o razonamientos 🔥 https://t.co/ZYHTZPqMwU
— Carlos Santana (@DotCSV) 5 mai 2026If you're fans of the Gemma 4 model family, keep an eye on this—they've just given it a performance boost that can make it up to 3x faster, depending on the model, without any loss of quality in its responses or reasoning
