It doesn’t have a calculator. The arithmetic it knows is mostly memorization with pattern-matching and guesswork to fill in the gaps, and there’s too many possible equations to memorize them all. Also, tokenization impairs its lexical understanding of numbers.
MACHINE LEARNING
-
MLSys Workshop Presentation at NeurIPS 2022
By
–
Thanks for sharing @_akhaliq! Also checkout our oral session and poster at #NeurIPS2022 MLSys workshop! https://
nips.cc/Conferences/20
22/ScheduleMultitrack?event=62290
… -
Tokenization limits: variable tokens, cannot handle per-letter tasks
By
–
Tokenization. It doesn’t see text as sequences of characters, but of variable-length tokens about 4 chars on average. It generally can’t do anything that needs to be done one letter at a time. It’s also bad at counting in its head.
-

AI-Powered Motion Sensors Transform World Cup Ball Tracking
By
–
Hi-Tech World Cup balls charging! For the first time this year, each ball has a motion sensor inside giving real-time ball tracking and statistics. It collects #data such as position, speed and direction, assisting the referees on offside calls Credit: Kinexon
#ml #ai #tech -
ML Demo Hype: Why Cherry-Picked Examples Fool Investors
By
–
Baffled by the number of people (specifically influencers and investors) who still get fooled by ML demos and cherry picked examples engineered for wow effect! Rookie mistake to judge the quality of a model (versus looking at usage, revenue and more tangible evaluations)
-
GPT-3 cannot perform accurate calculations without step-by-step writing.
By
–
In general, you shouldn't expect it to be able to perform accurate calculations, at least not "in its head" — this is a known limitation of models like GPT-3. It only stands a chance if prompted to write calculations out step-by-step like one might do on paper.
-
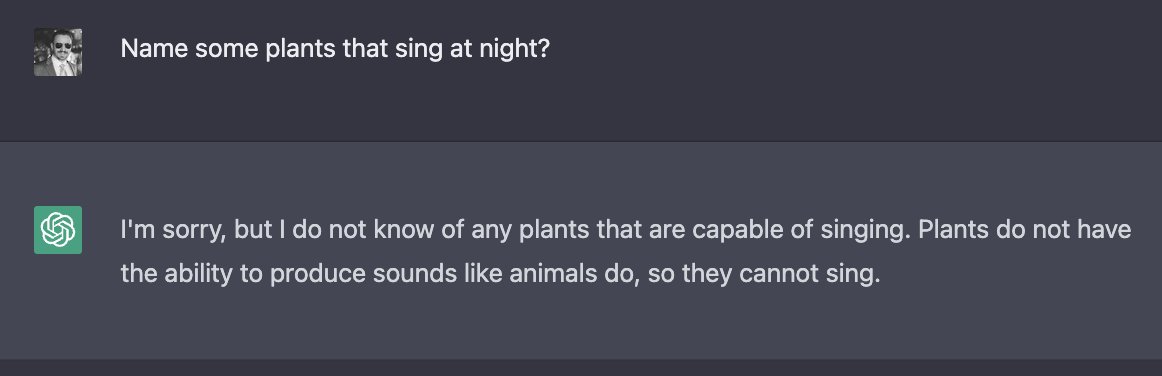
ChatGPT avoids hallucination on Hofstadter/Bender questions
By
–
You're talking about a different model — this post is about ChatGPT. text‑davinci‑003 still fails on all of the Hofstadter/Bender questions that I've tried. The prompt you're suggesting does not seem to produce a hallucination in ChatGPT:
-
Challenge of incorporating all known trivia into training data
By
–
Expecting it to fully integrate every piece of trivia seems unfair — a lot of people would rate the first answer as reasonable. It’s fundamentally difficult to get training data that incorporates everything the model knows, rather than what the human demonstrator knows.
-
GPT-3 improvement shows not just pattern-matching, still hallucinates details
By
–
The point isn’t that it’s perfect, just that it’s not narrowly pattern-matching on this specific list of questions — there’s clear improvement vs. GPT-3 across many questions that contain false assumptions. It does still hallucinate details in other ways.