This feels like a tokenization issue — in general, it doesn’t see text as sequences of letters, and struggles with tasks that assume it does.
MACHINE LEARNING
-
Reinforcement Learning as Backpropagation Through Time
By
–
Reinforcement learning is backpropagation through time.
-
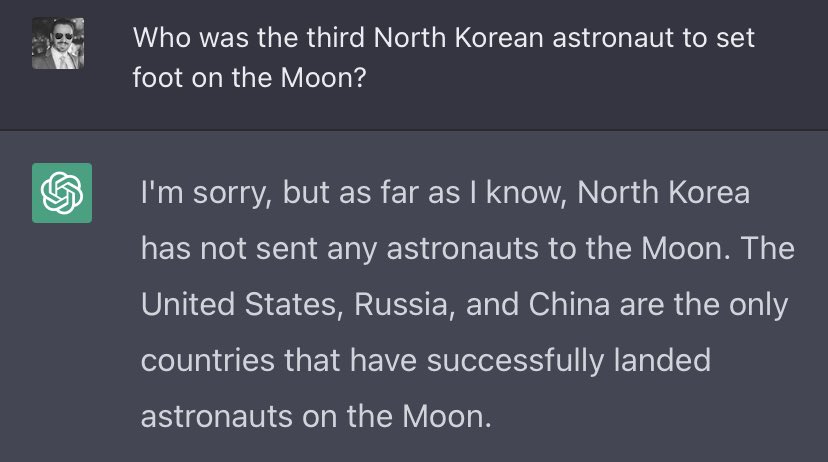
GPT-3 succeeds on trick questions, pre-training unchanged since 2021
By
–
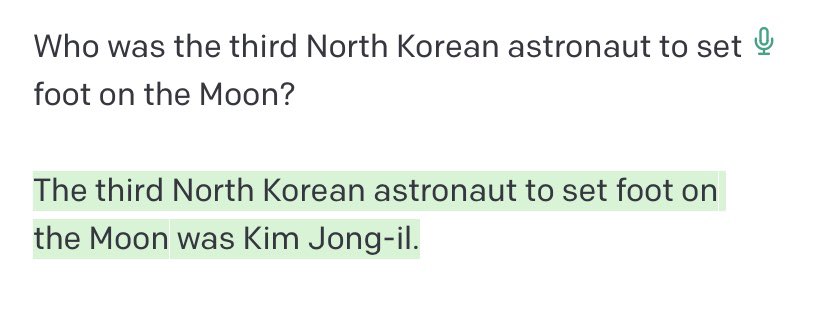
No. It also succeeds on questions I’ve written myself that trick GPT-3, as in this screenshot. The pre-training data hasn’t been updated since 2021, and OpenAI specifically denies (in this thread) training on the Hofstadter/Bender questions.
-
Domino MLOps Platform: Hybrid Multi-Cloud Data Science Solution
By
–
What did the truck say? Domino is the only hybrid and multi-cloud MLOps platform. Unleash data science, not cloud spend. Follow us to #ReInvent2022 booth #2938 for more info, and to win prizes! https://t.co/I7YNKEJaZT pic.twitter.com/5oNDRyWaJG
— Domino Data Lab (@DominoDataLab) 30 novembre 2022What did the truck say? Domino is the only hybrid and multi-cloud MLOps platform. Unleash data science, not cloud spend. Follow us to #ReInvent2022 booth #2938 for more info, and to win prizes! https://
domino.buzz/3hOw8Ip -
Los Angeles Open-Source ML Meetup December 1st Event
By
–
Calling all Los Angeles makers! We invite you to join us for an evening of open-source and ML scalability on December 1, 2022. Come hang out and talk with data science enthusiasts. Register: https://
meetup.com/los-angeles-ar
tificial-intelligence-deep-learning/events/289694346/
… -

Freddie Mac Modernizes AI ML Infrastructure with DataRobot
By
–
Join us at #AISummit New York for a discussion on how @FreddieMac modernized their #AI and #ML infrastructure, leveraging DataRobot to rapidly deliver meaningful value to the business. Sign up https://
datarobot.com/events/ai-summ
it-new-york/
… -
DeepMind Reduces Math Reasoning Errors Using Process-Based Supervision
By
–
DeepMind Studies Process- vs Outcome-based Model Supervision, Significantly Reducing Reasoning Errors on Math Word Problems https://
syncedreview.com/2022/11/30/dee
pmind-studies-process-vs-outcome-based-model-supervision-significantly-reducing-reasoning-errors-on-math-word-problems/
… -
Health Monitoring for Large-Scale AI URL Datasets
By
–
We should have a health page with updated indicators for urls datasets like LAION or COYO 83% █ █ █ █ █ █ □ □ Self destructing datasets!
-

Meta AI’s CICERO Masters Diplomacy Game at Human Level
By
–
Meta AI’s CICERO is the first AI to play Diplomacy at a human level. This intricate strategy game is about people rather than pieces since to win, players must build trust, cooperate and negotiate with others. Learn more about #CICERObyMetaAI's gameplay
-

ChatGPT defeats Hofstadter/Bender hallucination questions
By
–


OpenAI’s new ChatGPT appears to defeat Hofstadter/Bender’s list of hallucination-inducing questions, published in The Economist this June to demonstrate the “hollowness” of GPT-3’s understanding of the world: https://
economist.com/by-invitation/
2022/06/09/artificial-neural-networks-today-are-not-conscious-according-to-douglas-hofstadter
…