Stanford CS330: Deep Multi-Task and Meta Learning I Autumn 2022 – YouTube
https://bit.ly/3Mpa9TY
#AI #MachineLearning #DeepLearning #LLMs #DataScience
MACHINE LEARNING
-

Stanford Course on Multi-Task Learning and Meta-Learning
By
–
-

Scalable Video AI: Implementation and Strategic Applications Guide
By
–
Why And How To Use Scalable AI
#AI #AIio #BigData #ML #NLU #Futureofwork @oluskayacan @richardkimphd @MariaFariello @johnpearcenews5 @ResurgentAV @rohanmuralee @globaliqx http://
ow.ly/nu0730svHTl -

Annual State Of Data Quality Survey 2023
By
–
The Annual State Of Data Quality Survey, 2023 https://
bit.ly/3Mt9dhM #AI #MachineLearning #DeepLearning #LLMs #DataScience -
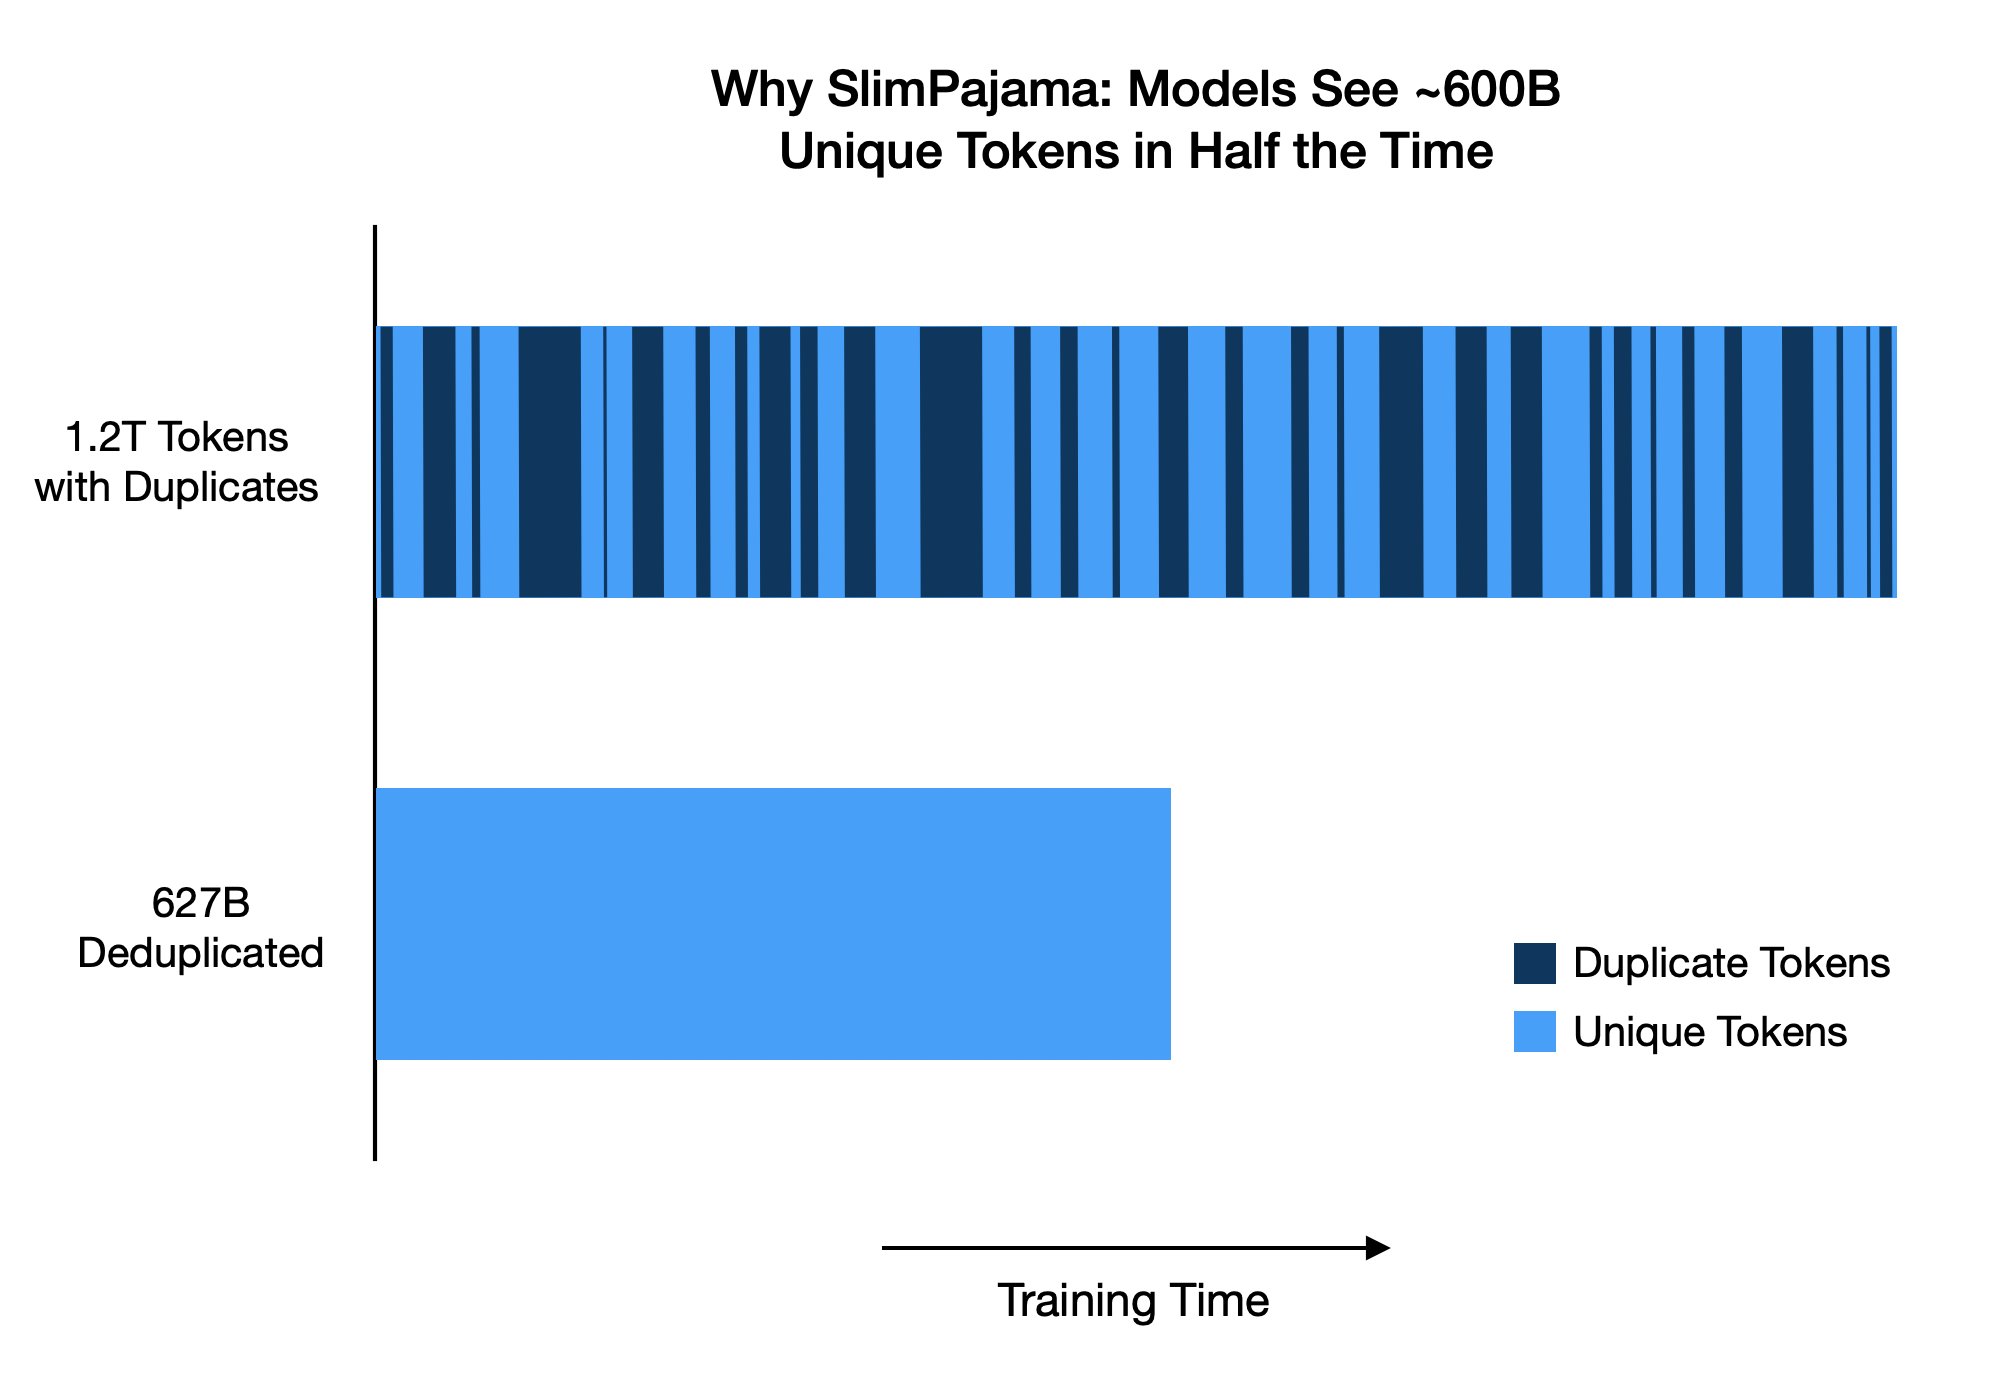
SlimPajama Reduces AI Training Compute Costs by 50 Percent
By
–
Why we built SlimPajama – it's all about training efficiency. Without de-duplication, a model would have to go through 1.2T tokens before seeing ~600B unique tokens. SlimPajama sees 600B tokens in half the time. That saves you 50% on compute costs! https://
cerebras.net/blog/slimpajam
a-a-627b-token-cleaned-and-deduplicated-version-of-redpajama
… -
Open-Sourcing Research Work for CVPR 2023 Conference
By
–
In support of open science and the research community, we're open-sourcing this work — and we'll be presenting it at #CVPR2023 next week. Training code and model checkpoints
-
I-JEPA Delivers Strong Computer Vision Performance with Efficiency
By
–
The approach taken with I-JEPA delivers strong performance across a number of computer vision tasks and does so with greater computational efficiency compared to other widely used computer vision models.
-

I-JEPA: Self-Supervised Computer Vision Learning Through Prediction
By
–
Today we're releasing our work on I-JEPA — self-supervised computer vision that learns to understand the world by predicting it. It's the first model based on a component of @ylecun
's vision to make AI systems learn and reason like animals and humans. Details -
LLaMA-Adapter and LoRA: Multimodal Input Advantages
By
–
Good question. I'd say LLaMA-Adapter and LoRA are both good methods. The advantage of LLaMA-Adapter though is that you can also embed multimodal inputs (images and others)
-

System Validation Team Hiring for ML ASIC Products
By
–
Do you enjoy product development with strong cross-team collaboration? Join our System Validation team and work on all current and future #MachineLearning #ASIC-based products. #hiring #hiringtoptalent https://
groq.com/careers/?gh_ji
d=5575903003
… -

Free Open Source Audio Machine Learning Course Launch
By
–
And if you're interested in going deeper into ML for Audio, we are releasing our Audio Course this Wednesday (Jun 14th)! It's fully open source and 100% free Sign up for the course http://
eepurl.com/insvcI
Our launch event https://
youtube.com/watch?v=wqkKRe
sXWB8
…