MIT researchers developed “Insum,” a technique for speeding up computations on datasets replete w/zeros. It rewrites Einstein summation (“einsum”) operations to avoid inefficient handling of zeros, improving memory efficiency & performance: https://
bit.ly/4upJM5s
MACHINE LEARNING
-
MIT’s “Insum” speeds up einsum for sparse datasets
By
–
-
Nvidia Announces LongLive-2.0 for Long Video Generation
By
–
Nvidia presents LongLive-2.0
— AK (@_akhaliq) 19 mai 2026
An NVFP4 Parallel Infrastructure for Long Video Generation pic.twitter.com/kGTa0gegb9Nvidia presents LongLive-2.0 An NVFP4 Parallel Infrastructure for Long Generation
-
Claude Code Training 13 Hours: Long-term Memory and React FastAPI App
By
–
Formation complète Claude Code : 13 HEURES.
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 19 mai 2026
J'ai cherché partout. Rien de comparable n'existe.
Gardez-la précieusement en signet 🔖
De A à Z :
– CLAUDE.md : comment donner une mémoire long terme à Claude sur ton projet
– App complète : React frontend + Python FastAPI… pic.twitter.com/owmHgMjVLmComplete Claude Code Training: 13 HOURS. I searched everywhere. Nothing comparable exists. Bookmark it preciously. From A to Z: – CLAUDE.md: how to give Claude long-term memory on your project – Complete App: React frontend + Python FastAPI
-
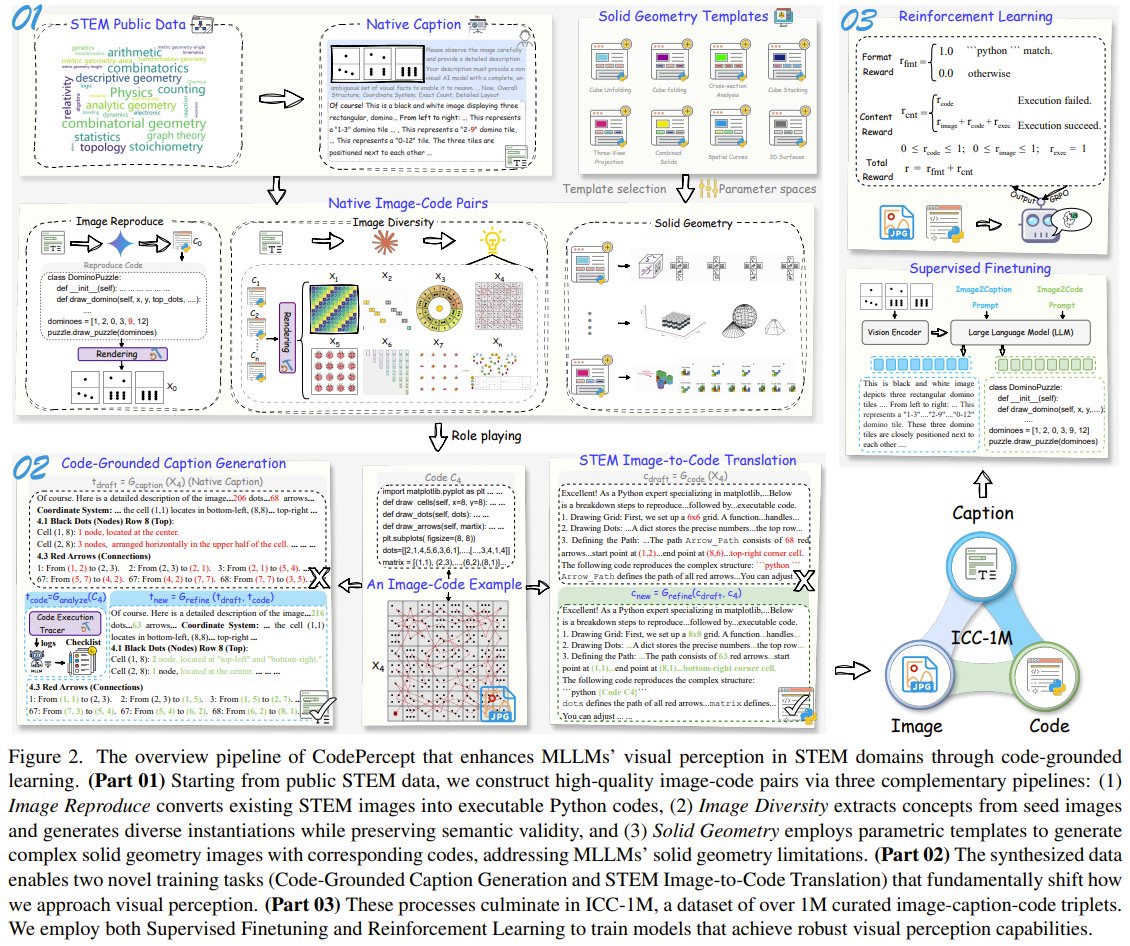
Researchers propose CodePercept to improve AI on STEM diagrams
By
–
Why do AI models fail at STEM diagrams? Is it weak reasoning or poor perception? Researchers from Shanghai Jiao Tong University and Alibaba’s Qwen Team present CodePercept. Instead of scaling reasoning, they scale perception using code as a precise medium—generating
-
Generation speed stable in Pi without super large context
By
–
So far my generation speed is mostly stable in Pi (I haven’t tried super large context yet)
-

AI reveals humans’ poor complex decision-making skills
By
–
Humans are bad at making complex decisions. #AI can call them out
by Patricia Waldron @TechXplore_com Learn more: https://
bit.ly/3PM4rkV #MachineLearning #ArtificialIntelligence #ML -
Mapping distributed systems patterns to LLM agents
By
–
what if we mapped older distributed systems patterns (like actor models or reactive, state-driven blackboards) to LLM agents?
-
@elevenlabs — 2026-05-19
By
–
The Einstein agent demonstrates how voice AI can unlock more interactive, accessible and multilingual education experiences. Try it here:
-
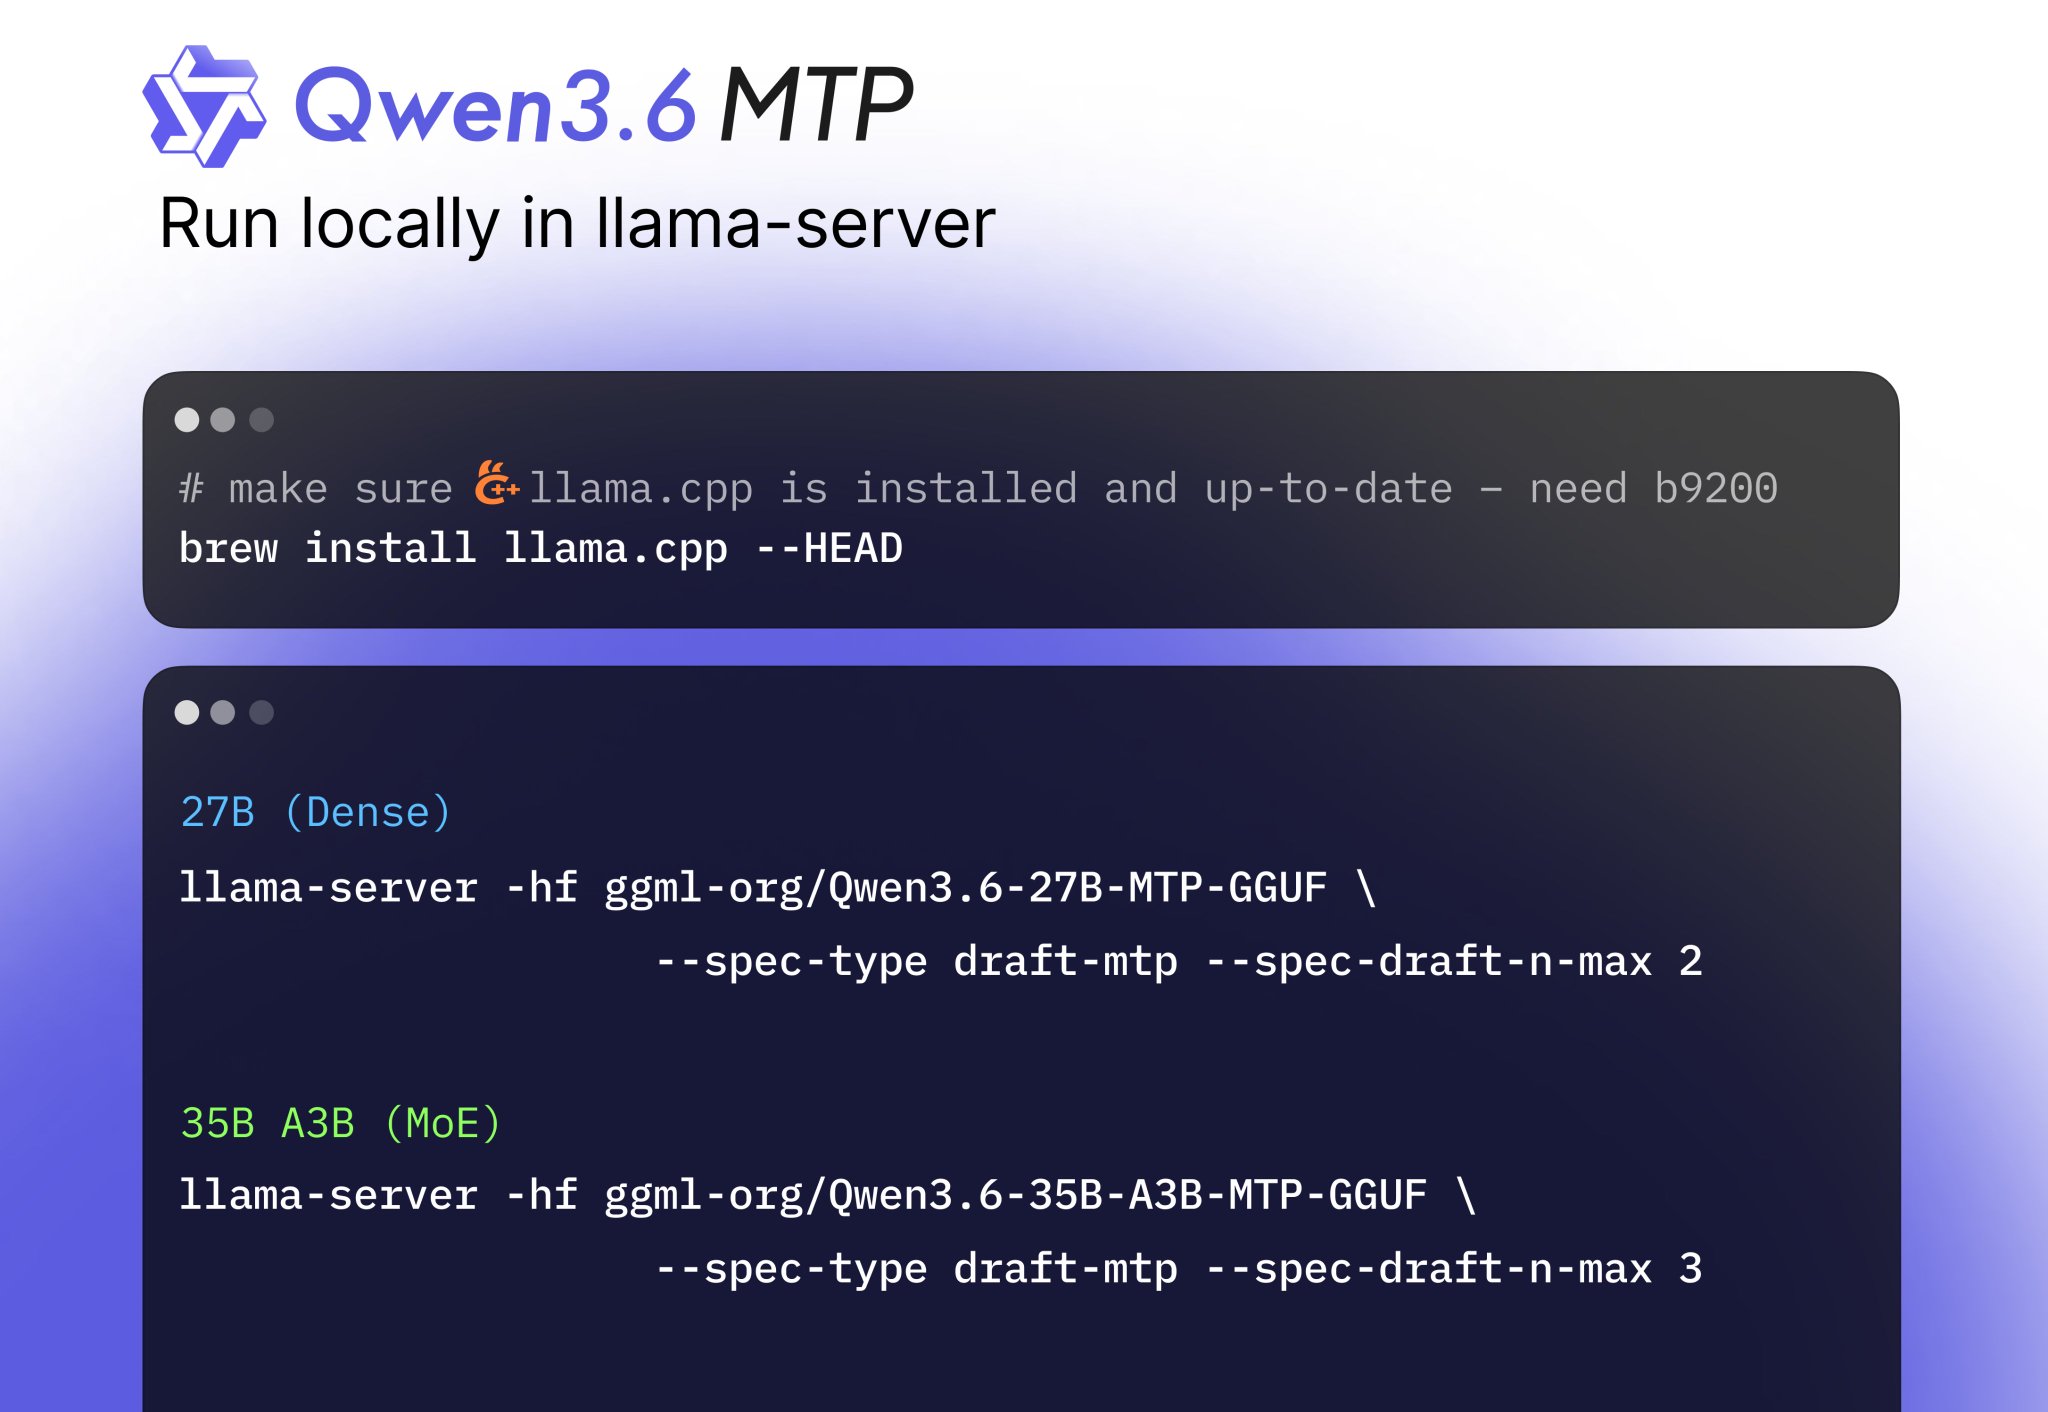
Llama.cpp MTP: 2x generation speed with multi-token prediction
By
–
I've seen some confusion online on how to run llama.cpp with MTP (Multi-token prediction) in the simplest way possible. ICYMI, MTP is a new flavor of speculative decoding built-in to the model itself, that ~2x your tokens per sec for most use cases. 2x generation speed = Truly