The bottleneck for coding agents may not be code. It may be experience. A new ICML 2026 paper introduces Self-play SWE-RL (SSR): Toward Training Superintelligent Software Agents through Self-Play SWE-RL The question is simple and profound: How do you train software agents
MACHINE LEARNING
-
Deep passage on physics: LLMs any world, humans our world, and Chomsky
By
–
this bit on physics is deep and actually resonates with the fact that LLMs are equally comfortable learning any world, whereas humans are built for our world.
— Gary Marcus (@GaryMarcus) 25 mai 2026
See also Chomsky’s 2023 conversation with me Web Summit on YouTube. https://t.co/56dkrTORf5This passage on physics is profound and really resonates with the fact that LLMs are just as comfortable learning any world, while humans are designed for our world. See also the conversation of Chomsky with me in 2023 at Web Summit on
-
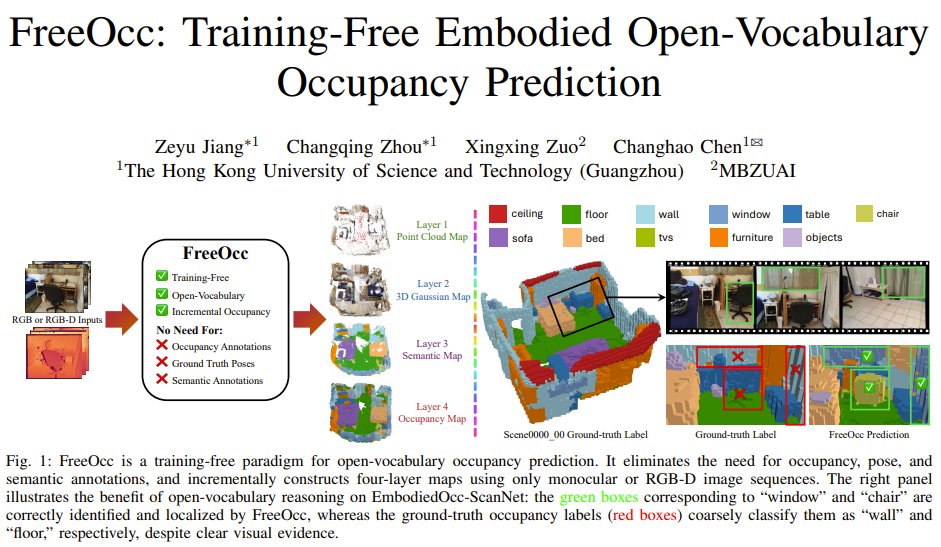
FreeOcc: Training-Free Open-Vocabulary Occupancy Predictor
By
–
What if a robot could map without training or 3D labels? HKUST & MBZUAI researchers present FreeOcc – a training-free open-vocabulary occupancy predictor. It builds a 4-layer map using SLAM, Gaussians, and VLMs. Outperforms self-supervised by 2x in IoU/mIoU, zero-shot to new
-

AlphaProof Nexus solved 9 open Erdős problems and proved 44 OEIS conjectures
By
–

Google DeepMind's AlphaProof Nexus autonomously solved 9 open Erdős problems, some unsolved for 56 years, at a cost of a few hundred dollars per problem. It also proved 44 open OEIS conjectures, resolved a 15-year-old question in algebraic geometry, and discovered a novel
-
llama.cpp MTP Support Boosts Local Model Inference Speed
By
–
llama.cpp with MTP support makes local models fast enough to use as daily drivers 🚀
— clem 🤗 (@ClementDelangue) 24 mai 2026
Qwen3.6-27B dense generation below on A10G: From 25 tok/st to 45 tok/s (+78%)! pic.twitter.com/rLjBVa3Yzhllama.cpp with MTP support makes local models fast enough to use as daily drivers Qwen3.6-27B dense generation below on A10G: From 25 tok/st to 45 tok/s (+78%)!
-

DeepSeek’s unconventional MoE strategy for long-term success
By
–
A fascinating deep dive into DeepSeek reveals a brilliantly unconventional strategy. They are completely ignoring standard industry trends. Instead of fighting for short-term multimodal profits, they are looking ahead. They use radical frameworks like MoE to absolutely crush
-
Hardware Basics for Running Different Sized Models
By
–
We start with the basics of what hardware is needed to run different sized models
-

Neurosymbolic work by Swarat et al for Erdos, more quantitative than OpenAI
By
–
neurosymbolic by @swarat et al for Erdos's victory, with much more careful and quantitative work than OpenAI's in hindsight, I wonder if OpenAI rushed the release of theirs, knowing that this was coming?
-

Exploring Challenges and Benefits of Neuromorphic Computing
By
–
Challenges and Benefits of Neuromorphic Computing by @antgrasso #EmergingTech #Technology #Innovation