That’s a reasonable guess but in this instance it isn’t browsing the web or using any external resources. Also it’s very unlikely it was trained on literal rainbow tables — the simpler answer is that common hashes like these two occur all the time in technical docs.
MACHINE LEARNING
-
LLMs can outperform humans and keep improving
By
–
I’m sure a machine made the hash but, yes, a human did copy and paste it into a webpage. The point stands the LLM is better at this task than that human, or any other human. More generally, LLMs do not always converge to human-level performance and then stop getting better.
-

LLM Capabilities are Bounded by Human Skill in Training
By
–
It’s important to remember LLM capability is bounded by the skill of the humans who train them. The only reason ChatGPT can identify common, short strings given their MD5 or SHA1 hashes is because that’s a completely ordinary talent that many humans have.
-
AI Scaling Safety Efficiency Multimodal Data Collection Priorities
By
–
Revised beliefs: I still think we need to focus on scaling, safety, efficient training and inference, smarter memory (MoEs and long context have addressed this), more modalities (we’re still too slow at collecting visual, sound and touch egocentric data responsibly), online
-
Community-Created PEFT Fine-Tuned Llama-3 Models Expected
By
–
I’m looking forward to the tens of thousands of PEFT’ed Llama-3 70B and 400B models with various new superpowers that will be created and released by the community.
-
NEAT Agent Playing Mario Kart 64
By
–
I also love this other NEAT agent for Mario Kart 64 from a while back: https://t.co/v7gg8nGljL
— hardmaru (@hardmaru) 28 avril 2024I also love this other NEAT agent for Mario Kart 64 from a while back:
-
Conditioning and In-Context Learning: Architecture’s Impact Analysis
By
–
what i am confused that more people dont seem to be analysing is how does the conditioning improve (or not) with increasing attention heads and layers. i dont know if anyone is formally quantifying amount of conditioning/ICL as an explicit loss function/training goal. in other
-
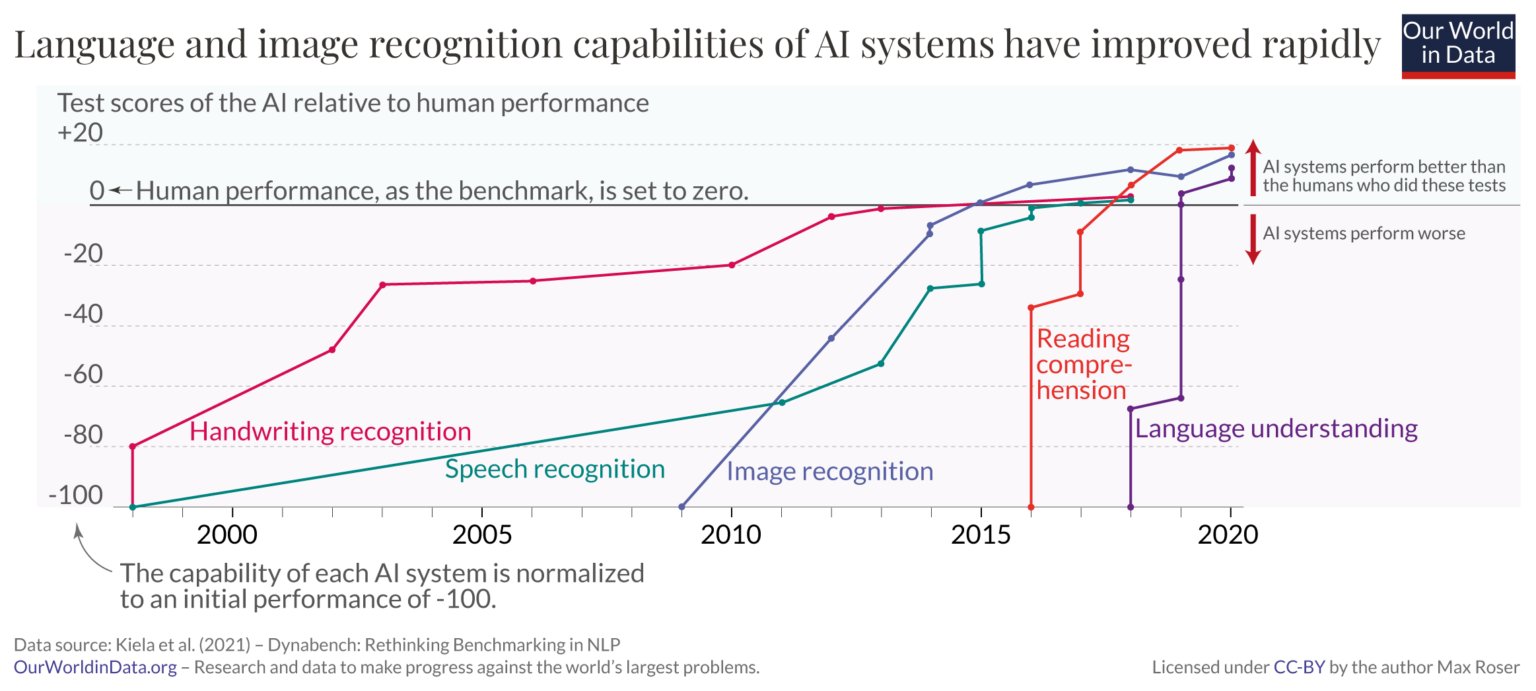
AI Plateaus at 60-80th Percentile: Stabilizing Human-AI Capability Balance
By
–
If AI really does plateau at 60-80th percentile of human ability (no sign it will/won't), the impacts may be stabilizing. Whatever you are best at (often what you enjoy most), you are likely to be better than an AI, but whatever you are not good at, AI can help fill in the gaps.
-
MLE Mishires: Need Diverse AIE Skills and Management
By
–
lots of MLE mishires when really a bunch of differently skilled and managed AIEs should do
-
Different Architecture and Pre-trained Model Approach
By
–
it's a very different architecture and starting from a different pre-trained model!